Our customer service is available all day, and your problems can be solved efficiently at any time. Last but not least, we can guarantee the security of the purchase process of Databricks-Certified-Professional-Data-Engineer test questions and the absolute confidentiality of customer information. You do not have to worry about these issues, because we know that this is a basic condition for us to establish a good business model. At the same time, if you want to continue learning, Databricks-Certified-Professional-Data-Engineer Test Torrent will provide you with the benefits of free updates within one year and a discount of more than one year.
| Section | Weight | Objectives |
|---|---|---|
| Data Modelling | 6% | - Delta Lake table design - Medallion Architecture implementation - Schema design and management |
| Monitoring and Alerting | 10% | - Pipeline observability and logging - Performance and health monitoring - Setting up alerts and notifications |
| Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic - Integration with Databricks APIs and tools - Data transformation and aggregation |
| Debugging and Deploying | 10% | - Deployment using bundles, CLI, and APIs - CI/CD and DevOps practices - Troubleshooting pipelines and errors |
| Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data - Standardization and normalization - Data validation and quality checks |
| Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
| Data Ingestion & Acquisition | 7% | - Connecting to diverse data sources - Auto Loader and streaming ingestion - Schema inference and evolution |
| Data Governance | 7% | - Unity Catalog management - Data lineage and metadata tracking - Policy enforcement |
| Ensuring Data Security and Compliance | 10% | - Data encryption and masking - Access control and permissions - Compliance standards implementation |
| Cost & Performance Optimisation | 13% | - Query optimization and caching - Cluster configuration and scaling - Storage optimization (partitioning, Z-order, indexing) |
>> Reliable Databricks-Certified-Professional-Data-Engineer Guide Files <<
These Databricks Databricks-Certified-Professional-Data-Engineer exam practice questions will greatly help you to prepare well for the final Databricks-Certified-Professional-Data-Engineer certification exam. Databricks Databricks-Certified-Professional-Data-Engineer exam preparation and boost your confidence to pass the Databricks-Certified-Professional-Data-Engineer Exam. All Databricks Databricks-Certified-Professional-Data-Engineer exam practice test questions contain the real and updated Databricks Databricks-Certified-Professional-Data-Engineer exam practice test questions.
NEW QUESTION # 85
A data engineer is creating a data ingestion pipeline to understand where customers are taking their rented bicycles during use. The engineer noticed that, over time, data being transmitted from the bicycle sensors fail to include key details like latitude and longitude. Downstream analysts need both the clean records and the quarantined records available for separate processing.
The data engineer already has this code:
import dlt
from pyspark.sql.functions import expr
rules = {
"valid_lat": "(lat IS NOT NULL)",
"valid_long": "(long IS NOT NULL)"
}
quarantine_rules = "NOT({})".format(" AND ".join(rules.values()))
@dlt.view
def raw_trips_data():
return spark.readStream.table("ride_and_go.telemetry.trips")
How should the data engineer meet the requirements to capture good and bad data?
Answer: C
Explanation:
Comprehensive and Detailed
The requirement is that both valid (good) and invalid (bad) records must be captured and available separately for downstream processing. Invalid records should not simply be dropped; they must be quarantined in a dedicated table.
In Databricks Lakeflow Declarative Pipelines (DLT), this is achieved by creating separate output tables:
One table for valid records (Silver table) that pass the expectations.
Another quarantine table that explicitly captures records failing the expectations.
Option A correctly implements this by:
Declaring a DLT table trips_data_quarantine.
Using .filter(expr(quarantine_rules)) to isolate invalid records (records where latitude or longitude is NULL).
This ensures analysts can query both good records (from the main Silver pipeline table) and bad records (from the quarantine table).
Why not the others?
B: Uses @dlt.expect_or_drop, which drops invalid records instead of quarantining them. This violates the requirement that quarantined data should be available.
C: Same as B, but applies expectations in bulk with expect_all_or_drop. Again, bad data is dropped, not quarantined.
D: Adds an is_quarantined flag in the same table. While it marks bad records, it does not separate them into a distinct quarantine table as required by the business use case.
Therefore, Option A is the only solution aligned with Databricks documentation for quarantining invalid data into a dedicated table while keeping valid data in the main pipeline.
NEW QUESTION # 86
The data engineering team maintains a table of aggregate statistics through batch nightly updates. This includes total sales for the previous day alongside totals and averages for a variety of time periods including the 7 previous days, year-to-date, and quarter-to-date. This table is namedstore_saies_summaryand the schema is as follows:
The tabledaily_store_salescontains all the information needed to updatestore_sales_summary. The schema for this table is:
store_id INT, sales_date DATE, total_sales FLOAT
Ifdaily_store_salesis implemented as a Type 1 table and thetotal_salescolumn might be adjusted after manual data auditing, which approach is the safest to generate accurate reports in thestore_sales_summarytable?
Answer: E
Explanation:
Explanation
The daily_store_sales table contains all the information needed to update store_sales_summary. The schema of the table is:
store_id INT, sales_date DATE, total_sales FLOAT
The daily_store_sales table is implemented as a Type 1 table, which means that old values are overwritten by new values and no history is maintained. The total_sales column might be adjusted after manual data auditing, which means that the data in the table may change over time.
The safest approach to generate accurate reports in the store_sales_summary table is to use Structured Streaming to subscribe to the change data feed for daily_store_sales and apply changes to the aggregates in the store_sales_summary table with each update. Structured Streaming is a scalable and fault-tolerant stream processing engine built on Spark SQL. Structured Streaming allows processing data streams as if they were tables or DataFrames, using familiar operations such as select, filter, groupBy, or join. Structured Streaming also supports output modes that specify how to write the results of a streaming query to a sink, such as append, update, or complete. Structured Streaming can handle both streaming and batch data sources in a unified manner.
The change data feed is a feature of Delta Lake that provides structured streaming sources that can subscribe to changes made to a Delta Lake table. The change data feed captures both data changes and schema changes as ordered events that can be processed by downstream applications or services. The change data feed can be configured with different options, such as starting from a specific version or timestamp, filtering by operation type or partition values, or excluding no-op changes.
By using Structured Streaming to subscribe to the change data feed for daily_store_sales, one can capture and process any changes made to the total_sales column due to manual data auditing. By applying these changes to the aggregates in the store_sales_summary table with each update, one can ensure that the reports are always consistent and accurate with the latest data. Verified References: [Databricks Certified Data Engineer Professional], under "Spark Core" section; Databricks Documentation, under "Structured Streaming" section; Databricks Documentation, under "Delta Change Data Feed" section.
NEW QUESTION # 87
A data engineer wants to reflector the following DLT code, which includes multiple definition with very similar code: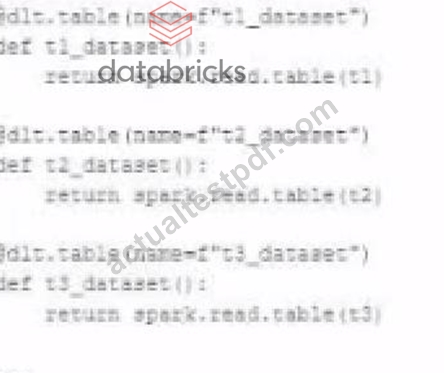
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.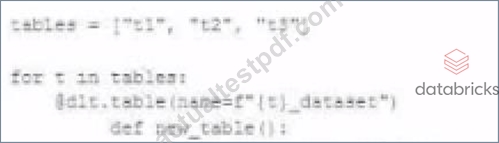
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for tables.
How can the data engineer fix this?
Answer: C
Explanation:
The issue with the refactored code is that it tries to use string interpolation to dynamically create table names within the dlc.table decorator, which will not correctly interpret the table names. Instead, by using a dictionary with table names as keys and their configurations as values, the data engineer can iterate over the dictionary items and use the keys (table names) to properly configure the table settings. This way, the decorator can correctly recognize each table name, and the corresponding configuration settings can be applied appropriately.
NEW QUESTION # 88
A data engineer is configuring a pipeline that will potentially see late-arriving, duplicate records.
In addition to de-duplicating records within the batch, which of the following approaches allows the data engineer to deduplicate data against previously processed records as it is inserted into a Delta table?
Answer: D
NEW QUESTION # 89
A data engineer has created a new cluster using shared access mode with default configurations. The data engineer needs to allow the development team access to view the driver logs if needed.
What are the minimal cluster permissions that allow the development team to accomplish this?
Answer: B
Explanation:
Databricks provides different permission levels to control access to clusters. The correct minimal permission required for viewing driver logs is CAN VIEW.
Databricks Cluster Permission Levels:
* CAN ATTACH TO:
* Allows users to attach notebooks to a cluster but does not allow them to view logs.
* Not sufficient for viewing driver logs.
* CAN MANAGE:
* Grants full control over the cluster, including starting, stopping, and editing configurations.
* Too broad for this requirement.
* CAN VIEW (Correct Answer):
* Allows users to view cluster details, logs, and status but not modify any configurations.
* Minimal required permission for viewing logs.
* CAN RESTART:
* Grants permission to restart the cluster, but does not include log access.
* Not sufficient for viewing logs.
Conclusion:
The minimal permission needed to allow the development team to view driver logs is CAN VIEW.
References:
Databricks Cluster Permissions Documentation
NEW QUESTION # 90
......
In order to have better life, attending certification exams and obtaining certifications will be essential on the path to success. Databricks-Certified-Professional-Data-Engineer latest test cram sheet will help you achieve your goal. Only if you receive the certificate the companies require you can have the opportunities for raising-salary and promotion. Thousands of companies think highly of this certification. You will be popular if you pass exam with Databricks-Certified-Professional-Data-Engineer Latest Test Cram sheet.
Databricks-Certified-Professional-Data-Engineer Reliable Dumps Sheet: https://www.actualtestpdf.com/Databricks/Databricks-Certified-Professional-Data-Engineer-practice-exam-dumps.html