P.S. Free & New ARA-C01 dumps are available on Google Drive shared by Pass4Test: https://drive.google.com/open?id=16pvebNjpR5MkWumHBTuh8MkSIsTKmD7X
In the case of studying with outdated SnowPro Advanced Architect Certification (ARA-C01) practice questions, you will fail and lose your resources. Pass4Test made an ARA-C01 Questions for the students so that they don't get confused to prepare for ARA-C01 Certification Exam successfully in a short time. Pass4Test has designed the real ARA-C01 exam dumps after consulting many professionals and receiving positive feedback.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Engineering | 25% | - Data Loading and Pipelines
|
| Topic 2: Snowflake Architecture | 30% | - Platform Architecture Design
|
| Topic 3: Performance Optimization | 20% | - Cost and Resource Optimization
|
| Topic 4: Accounts and Security | 25% | - Access Control and Authentication
|
Exam ARA-C01 is just a piece of cake if you have prepared for the exam with the helpful of Pass4Test's exceptional study material. If you are a novice, begin from ARA-C01 study guide and revise your learning with the help of testing engine. Exam ARA-C01 Brain Dumps is another superb offer of Pass4Test that is particularly helpful for those who want to the point and the most relevant content to pass exam. With all these products, your success is assured with 100% money back guarantee.
NEW QUESTION # 29
At which object type level can the APPLY MASKING POLICY, APPLY ROW ACCESS POLICY and APPLY SESSION POLICY privileges be granted?
Answer: A
Explanation:
The object type level at which the APPLY MASKING POLICY, APPLY ROW ACCESS POLICY and APPLY SESSION POLICY privileges can be granted is global. These are account-level privileges that control who can apply or unset these policies on objects such as columns, tables, views, accounts, or users. These privileges are granted to the ACCOUNTADMIN role by default, and can be granted to other roles as needed.
The other options are incorrect because they are not the object type level at which these privileges can be granted. Database, schema, and table are lower-level object types that do not support these privileges. References: Access Control Privileges | Snowflake Documentation, Using Dynamic Data Masking | Snowflake Documentation, Using Row Access Policies | Snowflake Documentation, Using Session Policies | Snowflake Documentation
NEW QUESTION # 30
Which system functions does Snowflake provide to monitor clustering information within a table (Choose two.)
Answer: A,E
Explanation:
Explanation
According to the Snowflake documentation, these two system functions are provided by Snowflake to monitor clustering information within a table. A system function is a type of function that allows executing actions or returning information about the system. A clustering key is a feature that allows organizing data across micro-partitions based on one or more columns in the table. Clustering can improve query performance by reducing the number of files to scan.
* SYSTEM$CLUSTERING_INFORMATION is a system function that returns clustering information, including average clustering depth, for a table based on one or more columns in the table. The function takes a table name and an optional column name or expression as arguments, and returns a JSON string with the clustering information. The clustering information includes the cluster by keys, the total partition count, the total constant partition count, the average overlaps, and the average depth1.
* SYSTEM$CLUSTERING_DEPTH is a system function that returns the clustering depth for a table based on one or more columns in the table. The function takes a table name and an optional column name or expression as arguments, and returns an integer value with the clustering depth. The clustering depth is the maximum number of overlapping micro-partitions for any micro-partition in the table. A lower clustering depth indicates a better clustering2.
References:
* SYSTEM$CLUSTERING_INFORMATION | Snowflake Documentation
* SYSTEM$CLUSTERING_DEPTH | Snowflake Documentation
NEW QUESTION # 31
A healthcare company is deploying a Snowflake account that may include Personal Health Information (PHI). The company must ensure compliance with all relevant privacy standards.
Which best practice recommendations will meet data protection and compliance requirements? (Choose three.)
Answer: B,D,F
NEW QUESTION # 32
A table contains five columns and it has millions of records. The cardinality distribution of the columns is shown below: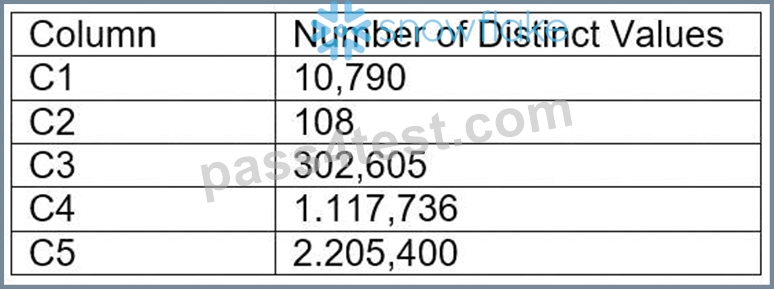
Column C4 and C5 are mostly used by SELECT queries in the GROUP BY and ORDER BY clauses.
Whereas columns C1, C2 and C3 are heavily used in filter and join conditions of SELECT queries.
The Architect must design a clustering key for this table to improve the query performance.
Based on Snowflake recommendations, how should the clustering key columns be ordered while defining the multi-column clustering key?
Answer: B
Explanation:
Explanation
According to the Snowflake documentation, the following are some considerations for choosing clustering for a table1:
* Clustering is optimal when either:
* You require the fastest possible response times, regardless of cost.
* Your improved query performance offsets the credits required to cluster and maintain the table.
* Clustering is most effective when the clustering key is used in the following types of query predicates:
* Filter predicates (e.g. WHERE clauses)
* Join predicates (e.g. ON clauses)
* Grouping predicates (e.g. GROUP BY clauses)
* Sorting predicates (e.g. ORDER BY clauses)
* Clustering is less effective when the clustering key is not used in any of the above query predicates, or when the clustering key is used in a predicate that requires a function or expression to be applied to the key (e.g. DATE_TRUNC, TO_CHAR, etc.).
* For most tables, Snowflake recommends a maximum of 3 or 4 columns (or expressions) per key.
Adding more than 3-4 columns tends to increase costs more than benefits.
Based on these considerations, the best option for the clustering key columns is C. C1, C3, C2, because:
* These columns are heavily used in filter and join conditions of SELECT queries, which are the most effective types of predicates for clustering.
* These columns have high cardinality, which means they have many distinct values and can help reduce the clustering skew and improve the compression ratio.
* These columns are likely to be correlated with each other, which means they can help co-locate similar rows in the same micro-partitions and improve the scan efficiency.
* These columns do not require any functions or expressions to be applied to them, which means they can be directly used in the predicates without affecting the clustering.
References: 1: Considerations for Choosing Clustering for a Table | Snowflake Documentation
NEW QUESTION # 33
One of your colleagues has submitted a long running query in Snowflake. how long the query can run till snowflake automatically cancels the query?
Answer: C
NEW QUESTION # 34
......
We have a variety of versions for your reference: PDF & Software & APP version. All those versions are high efficient and accurate with passing rate up to 98 to 100 percent. So our ARA-C01 Study Guide is efficient, high-quality for you. Such high quality and low price traits of our ARA-C01 guide materials make exam candidates reassured.
Valid ARA-C01 Test Pattern: https://www.pass4test.com/ARA-C01.html
What's more, part of that Pass4Test ARA-C01 dumps now are free: https://drive.google.com/open?id=16pvebNjpR5MkWumHBTuh8MkSIsTKmD7X