P.S. Free 2026 Microsoft AI-103 dumps are available on Google Drive shared by Pass4training: https://drive.google.com/open?id=1TRClfPC9BTcsGYKHoFJkb8sEPtMTNqf2
Our AI-103 study materials are closely linked with the test and the popular trend among the industries and provide all the information about the test. The answers and questions seize the vital points and are verified by the industry experts. Diversified functions can help you get an all-around preparation for the test. Our online customer service replies the clients’ questions about our AI-103 Study Materials at any time. So our AI-103 study materials can be called perfect in all aspects.
| Section | Weight | Objectives |
|---|---|---|
| Plan and manage Azure AI solutions | 25-30% | - Plan Azure AI resources
|
| Implement generative AI solutions | 25-30% | - Optimize and evaluate models
|
| Implement agentic solutions | 20-25% | - Manage agent operations
|
| Implement computer vision solutions | 10-15% | - Analyze visual content
|
| Implement text analysis and information extraction solutions | 10-15% | - Analyze and extract information
|
>> AI-103 Free Sample Questions <<
Our AI-103 training prep was produced by many experts, and the content was very rich. At the same time, the experts constantly updated the contents of the study materials according to the changes in the society. The content of our AI-103 study guide is definitely the most abundant. Before you go to the exam, our AI-103 Exam Questions can provide you with the simulating exam environment. This not only includes the examination process, but more importantly, the specific content of the exam. In previous years' examinations, the hit rate of AI-103 learning quiz was far ahead in the industry.
NEW QUESTION # 99
You have a Microsoft Foundry project that contains an agent.
The knowledge source for the agent is a set of scanned PDF troubleshooting guides stored in Azure Blob Storage. The guide pages contain two-column layouts and tables.
You use Azure Content Understanding in Foundry Tools to process the PDFs.
You plan to ingest the processed content into an index for Retrieval Augmented Generation (RAG) and store extracted fields for downstream automation.
Stakeholders must be able to verify where each extracted field value came from in the original PDF and route low-reliability extractions for manual review.
You need to ensure that the Content Understanding document analyzer output includes a per-field confidence score and source grounding locations within the source document.
What should you do?
Answer: B
Explanation:
The correct answer is A. Enable estimateFieldSourceAndConfidence . Azure Content Understanding document analyzers support an opt-in confidence and grounding capability for field extraction. Microsoft documentation states that to opt in for confidence and grounding, you set estimateFieldSourceAndConfidence
= true in the analyzer configuration, or configure estimateSourceAndConfidence = true for specific fields.
This enables each extracted field to include a confidence score and references back to the original document source location.
This directly satisfies both stakeholder requirements: source grounding allows users to verify where the extracted value came from in the scanned PDF, and the confidence score supports downstream automation rules, such as sending low-confidence fields to manual review. Microsoft's analyzer improvement guidance describes confidence scoring as a value between 0 and 1 and grounding as references or citations for extracted outputs to the original document content.
Generative extraction does not guarantee per-field confidence and source grounding. enableSegment is used for document segmentation, not confidence scoring. Labeled samples can improve extraction quality, but they do not by themselves enable confidence and grounding output. Reference topics: Content Understanding document analyzers, field extraction, confidence scoring, grounding, and RAG ingestion.
NEW QUESTION # 100
Your company is piloting a customer support agent in a Microsoft Foundry project name Project1. Project1 is connected to an existing Application Insights resource, and the company ' s support team reviews runs in the Traces tab.
The Foundry Agent Service is configured to perform the following actions:
* Retrieve the Application Insights connection string by calling
project_client.telemetry.get_application_insights_connection_string().
* Call configure_azure_monitor(connection_string=...) to enable telemetry.
A separate LangChain service configured to use OpenTelemetry and has the following configurations:
* Uses AzureAIOpenTelemetryTracer(connection_string=..., enable_content_recording=False)
* Passes the tracer by using config={ " callbacks " :[azure_tracer]}
Company policy has the following requirements:
* Telemetry from LangChain and OpenTelemetry must be distinguishable within the same Application Insights resource.
* Secrets and credentials must NOT be stored in prompts, tool arguments, or span attributes.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.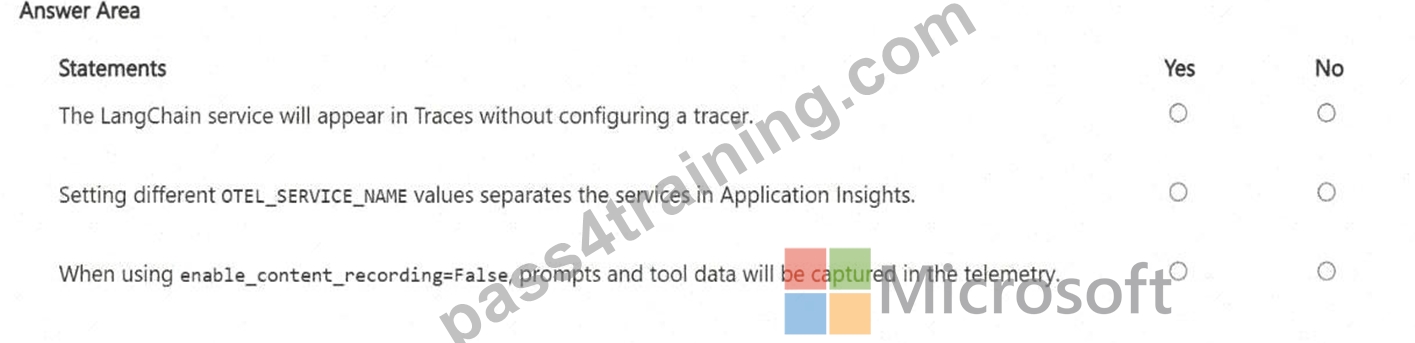
Answer:
Explanation: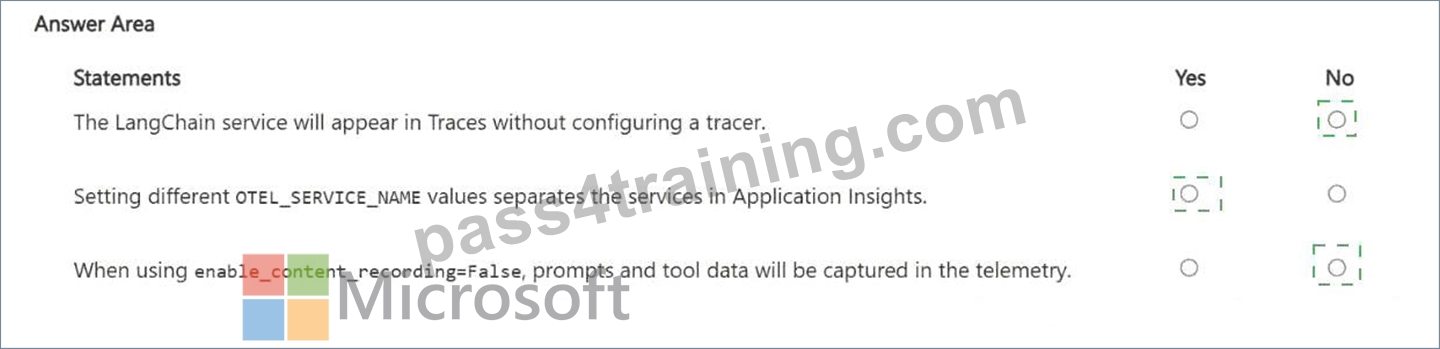
Explanation:
The LangChain service will appear in Traces without configuring a tracer: No Setting different OTEL_SERVICE_NAME values separates the services in Application Insights: Yes When using enable_content_recording=False, prompts and tool data will be captured in the telemetry: No The first statement is No because a separate LangChain or LangGraph application must emit telemetry through the configured tracing integration. Microsoft's LangChain tracing guidance states that you configure AzureAIOpenTelemetryTracer, attach it to the runnable or agent through callbacks, and then inspect the emitted traces in Azure Monitor. The troubleshooting guidance also states that missing LangChain or LangGraph spans are caused by tracing callbacks not being attached to the run.
The second statement is Yes . In OpenTelemetry, OTEL_SERVICE_NAME maps to the service.name resource attribute. Azure Monitor Application Insights uses cloud role names to represent separate services, and Microsoft states that when multiple services emit to the same Application Insights resource, cloud role names must be set so services are represented properly.
The third statement is No . enable_content_recording=False is specifically used to redact message content and tool call arguments from traces. Microsoft also advises disabling content recording in production and not storing secrets, credentials, or tokens in prompts or tool arguments. Reference topics: Microsoft Foundry tracing, LangChain tracing, OpenTelemetry service naming, Application Insights, and secure telemetry configuration.
NEW QUESTION # 101
You have a Microsoft Foundry project that contains an agent used by the financial analysts at your company.
You need to optimize the agent workflow by providing additional data access and processing capabilities. The solution must meet the following requirements:
* Ensure that the agent can perform calculations during conversations
* Ensure that the agent can access up-to-date information from public websites.
* Ensure that the agent can retrieve information from documents uploaded directly to the agent.
What should you use for each requirement? To answer, drag the appropriate tools to the correct requirements.
Each tool may be
used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.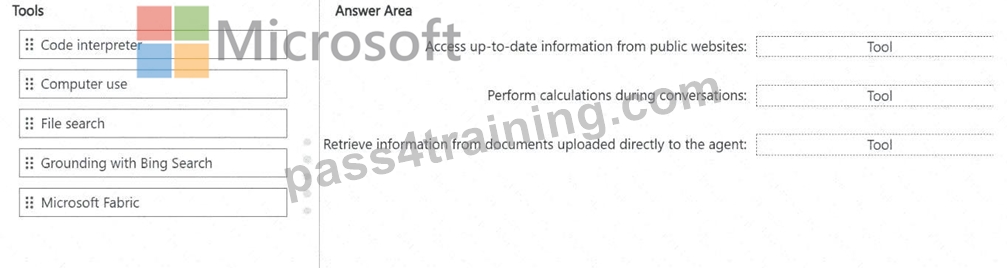
Answer:
Explanation: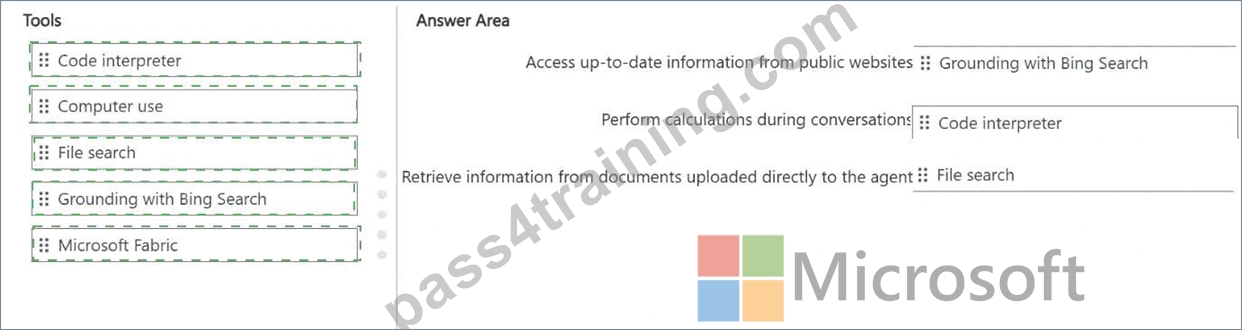
Explanation:
Access up-to-date information from public websites: Grounding with Bing Search Perform calculations during conversations: Code interpreter Retrieve information from documents uploaded directly to the agent: File search The correct tool for public, current web information is Grounding with Bing Search . Microsoft Foundry Agent Service identifies Grounding with Bing Search as the built-in tool that enables an agent to access and return information from the internet, which fits the requirement for up-to-date public website data. ( learn.
microsoft.com )
For calculations during conversations, use Code interpreter . Microsoft's Foundry guidance states that Code Interpreter enables an agent to run Python code in a sandboxed execution environment and solve data analysis and math tasks iteratively. This is the correct fit for financial analysts who need calculations, analysis, and potentially chart generation during the conversation.
For documents uploaded directly to the agent, use File search . Microsoft describes File Search as the tool that enables Foundry agents to search through documents, retrieve relevant information, and augment model responses with knowledge from uploaded files such as PDFs, Word documents, and proprietary content.
Computer use is for interacting with graphical applications, not calculation or document retrieval. Microsoft Fabric is for enterprise data and analytics integration, not direct uploaded document retrieval. Reference topics: Foundry Agent Service tools, Code Interpreter, File Search, and Grounding with Bing Search.
NEW QUESTION # 102
You have a Microsoft Foundry project that contains an agent.
The agent uses a knowledge source built from documents stored in Azure Blob Storage. The documents include digitally scanned PDFs that contain multipage tables.
You have an ingestion job that extracts only plain text, causing loss of table structure, headings, and page-number metadata.
Users frequently ask questions that require the retrieval of specific table rows across the pages.
You need to configure an ingestion job for a Retrieval Augmented Generation (RAG) pipeline that performs optical character recognition (OCR) on scanned PDFs, preserves tables and headings as structure-aware chunks, and stores page-number metadata with each chunk.
How should you configure the ingestion job?
Answer: D
Explanation:
Use OCR and page-level chunking.
Structure Preservation: OCR combined with document layout analysis (such as layout-aware or page-level chunking) detects visual structures like tables, headers, and reading order.
Row-Level Granularity: Page-level chunking retains the boundaries and context of multipage tables, enabling the RAG system to isolate and retrieve specific rows effectively.
Metadata Enrichment: Processing documents page-by-page allows the ingestion pipeline to automatically tag each extracted text chunk with its source page-number metadata.
Incorrect:
[not C]
Use page-level OCR extraction and store each page as a single chunk:
While this captures page numbers, storing an entire page as a single chunk introduces too much noise. It prevents the model from pinpointing specific table rows and often exceeds the optimal context window size for precise RAG retrieval.
[Not D]
Use basic parsing and fixed-size chunking:
Basic parsing cannot read digitally scanned PDFs, resulting in empty or completely garbled text.
Furthermore, fixed-size chunking splits text at arbitrary character limits, which destroys table structures and splits individual rows across different chunks.
Reference:
https://pub.towardsai.net/unlocking-key-technologies-in-document-parsing-81bfe20d741b
NEW QUESTION # 103
You need to ensure that Agent1Dev Team can access Agent1. The solution must meet the security and compliance requirements.
How should you complete the Python code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.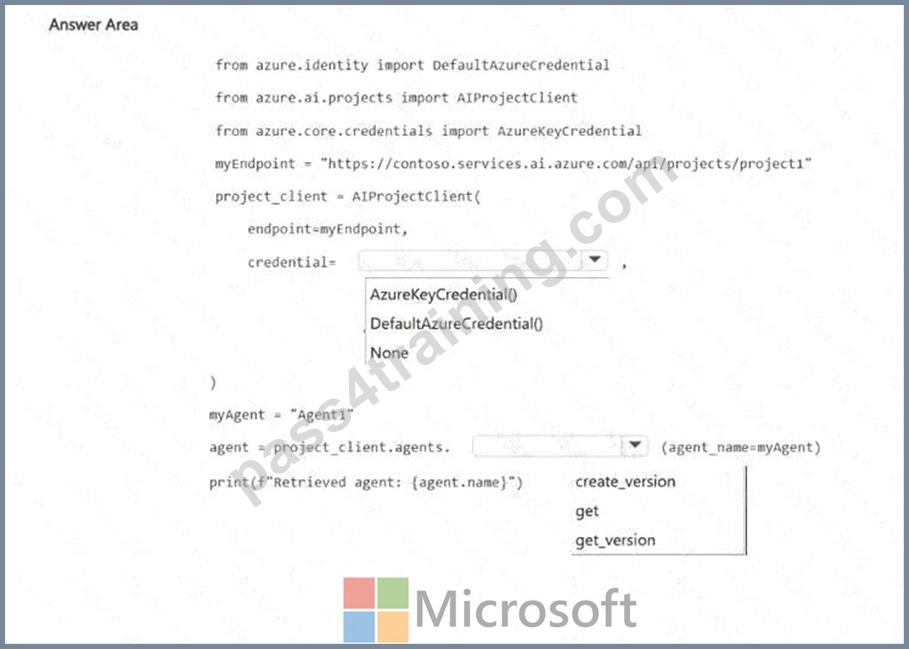
Answer:
Explanation: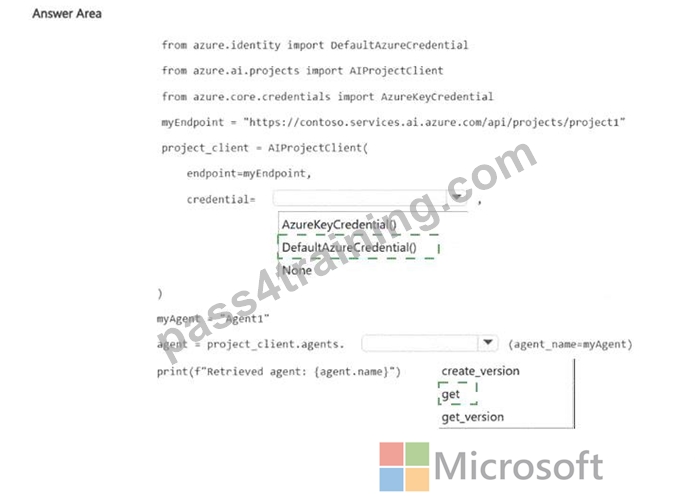
Explanation:
credential = DefaultAzureCredential()
agent = project_client.agents.get(agent_name=myAgent)
The correct authentication option is DefaultAzureCredential() because the case study states that API keys must not be used to access Foundry-deployed models and that Contoso developers must authenticate to Microsoft Foundry resources by using Microsoft Entra authentication. It also states that access to Project1 must be assigned to Agent1Dev Team by using the security group SC_Agent1_Dev . Microsoft Foundry authentication guidance recommends Microsoft Entra ID for production workloads because it supports least- privilege RBAC, per-principal auditing, and keyless authentication. AzureKeyCredential() would violate the no-API-key requirement, and None would not provide a valid credential.
The correct agent operation is get because the task is to access an existing agent named Agent1, not create a new version or retrieve a specific published version. Microsoft Foundry SDK examples show AIProjectClient created with DefaultAzureCredential() and then using project agent operations to create, retrieve, or interact with agents by name. To meet the compliance requirement, the group SC_Agent1_Dev must also be granted the appropriate project-scoped Foundry role, such as Foundry User, for Project1. Reference topics: Microsoft Entra authentication, Foundry RBAC, AIProjectClient, and project agent access.
NEW QUESTION # 104
......
Many people may worry that the AI-103 guide torrent is not enough for them to practice and the update is slowly. We guarantee you that our experts check whether the AI-103 study materials is updated or not every day and if there is the update the system will send the update to the client automatically. So you have no the necessity to worry that you don’t have latest AI-103 Exam Torrent to practice. We provide the best service to you and hope you are satisfied with our product and our service.
AI-103 Latest Test Guide: https://www.pass4training.com/AI-103-pass-exam-training.html
BTW, DOWNLOAD part of Pass4training AI-103 dumps from Cloud Storage: https://drive.google.com/open?id=1TRClfPC9BTcsGYKHoFJkb8sEPtMTNqf2