What's more, part of that It-Tests ACD-301 dumps now are free: https://drive.google.com/open?id=1SvCfNVZhlpSAncvOoSQSBOry6DlVixlS
One of the reason for this popularity is our study material are accompanied by high quality and efficient services so that they can solve all your problems. We guarantee that after purchasing our ACD-301 test prep, we will deliver the product to you as soon as possible about 5-10 minutes. So you don’t need to wait for a long time or worry about the delivery time has any delay. We will transfer our ACD-301 Test Prep to you online immediately, and this service is also the reason why our ACD-301 study torrent can win people’s heart and mind.
| Section | Objectives |
|---|---|
| Topic 1: Data Management | - Data types and CDT structures - Record types and data stores |
| Topic 2: Application Design and Architecture | - Reusable components and design patterns - Solution structuring and application layering |
| Topic 3: Process Modeling | - Advanced process model design - Exception handling and optimization |
| Topic 4: User Interface Design | - User experience best practices - Interface design and dynamic layouts |
| Topic 5: Expression Language and Logic | - Advanced Appian expression functions - Rule design and optimization |
| Topic 6: Security and Deployment | - Security roles and group management - Deployment pipelines and environment management |
When you are preparing ACD-301 practice exam, it is necessary to grasp the overall knowledge points of real exam by using the latest ACD-301 pass guide. Our experts written the accurate ACD-301 test answers for exam preparation and created the study guideline for our candidates. We promise you will get high passing mark with our valid ACD-301 Exam Torrent and your money will be back to your account if you failed exam with our study materials.
NEW QUESTION # 25
You are developing a case management application to manage support cases for a large set of sites. One of the tabs in this application s site Is a record grid of cases, along with Information about the site corresponding to that case. Users must be able to filter cases by priority level and status.
You decide to create a view as the source of your entity-backed record, which joins the separate case/site tables (as depicted in the following Image).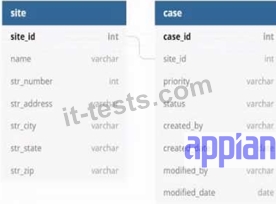
Which three column should be indexed?
Answer: A,E,F
Explanation:
Indexing columns can improve the performance of queries that use those columns in filters, joins, or order by clauses. In this case, the columns that should be indexed are site_id, status, and priority, because they are used for filtering or joining the tables. Site_id is used to join the case and site tables, so indexing it will speed up the join operation. Status and priority are used to filter the cases by the user's input, so indexing them will reduce the number of rows that need to be scanned. Name, modified_date, and case_id do not need to be indexed, because they are not used for filtering or joining. Name and modified_date are only used for displaying information in the record grid, and case_id is only used as a unique identifier for each record. Verified Appian Records Tutorial,Appian Best Practices As an Appian Lead Developer, optimizing a database view for an entity-backed record grid requires indexing columns frequently used in queries, particularly for filtering and joining. The scenario involves a record grid displaying cases with site information, filtered by "priority level" and "status," and joined via the site_id foreign key. The image shows two tables (site and case) with a relationship via site_id. Let's evaluate each column based on Appian's performance best practices and query patterns:
A . site_id:This is a primary key in the site table and a foreign key in the case table, used for joining the tables in the view. Indexing site_id in the case table (and ensuring it's indexed in site as a PK) optimizes JOIN operations, reducing query execution time for the record grid. Appian's documentation recommends indexing foreign keys in large datasets to improve query performance, especially for entity-backed records. This is critical for the join and must be included.
B . status:Users filter cases by "status" (a varchar column in the case table). Indexing status speeds up filtering queries (e.g., WHERE status = 'Open') in the record grid, particularly with large datasets. Appian emphasizes indexing columns used in WHERE clauses or filters to enhance performance, making this a key column for optimization. Since status is a common filter, it's essential.
C . name:This is a varchar column in the site table, likely used for display (e.g., site name in the grid). However, the scenario doesn't mention filtering or sorting by name, and it's not part of the join or required filters. Indexing name could improve searches if used, but it's not a priority given the focus on priority and status filters. Appian advises indexing only frequently queried or filtered columns to avoid unnecessary overhead, so this isn't necessary here.
D . modified_date:This is a date column in the case table, tracking when cases were last updated. While useful for sorting or historical queries, the scenario doesn't specify filtering or sorting by modified_date in the record grid. Indexing it could help if used, but it's not critical for the current requirements. Appian's performance guidelines prioritize indexing columns in active filters, making this lower priority than site_id, status, and priority.
E . priority:Users filter cases by "priority level" (a varchar column in the case table). Indexing priority optimizes filtering queries (e.g., WHERE priority = 'High') in the record grid, similar to status. Appian's documentation highlights indexing columns used in WHERE clauses for entity-backed records, especially with large datasets. Since priority is a specified filter, it's essential to include.
F . case_id:This is the primary key in the case table, already indexed by default (as PKs are automatically indexed in most databases). Indexing it again is redundant and unnecessary, as Appian's Data Store configuration relies on PKs for unique identification but doesn't require additional indexing for performance in this context. The focus is on join and filter columns, not the PK itself.
Conclusion: The three columns to index are A (site_id), B (status), and E (priority). These optimize the JOIN (site_id) and filter performance (status, priority) for the record grid, aligning with Appian's recommendations for entity-backed records and large datasets. Indexing these columns ensures efficient querying for user filters, critical for the application's performance.
Appian Documentation: "Performance Best Practices for Data Stores" (Indexing Strategies).
Appian Lead Developer Certification: Data Management Module (Optimizing Entity-Backed Records).
Appian Best Practices: "Working with Large Data Volumes" (Indexing for Query Performance).
NEW QUESTION # 26
For each requirement, match the most appropriate approach to creating or utilizing plug-ins Each approach will be used once.
Note: To change your responses, you may deselect your response by clicking the blank space at the top of the selection list.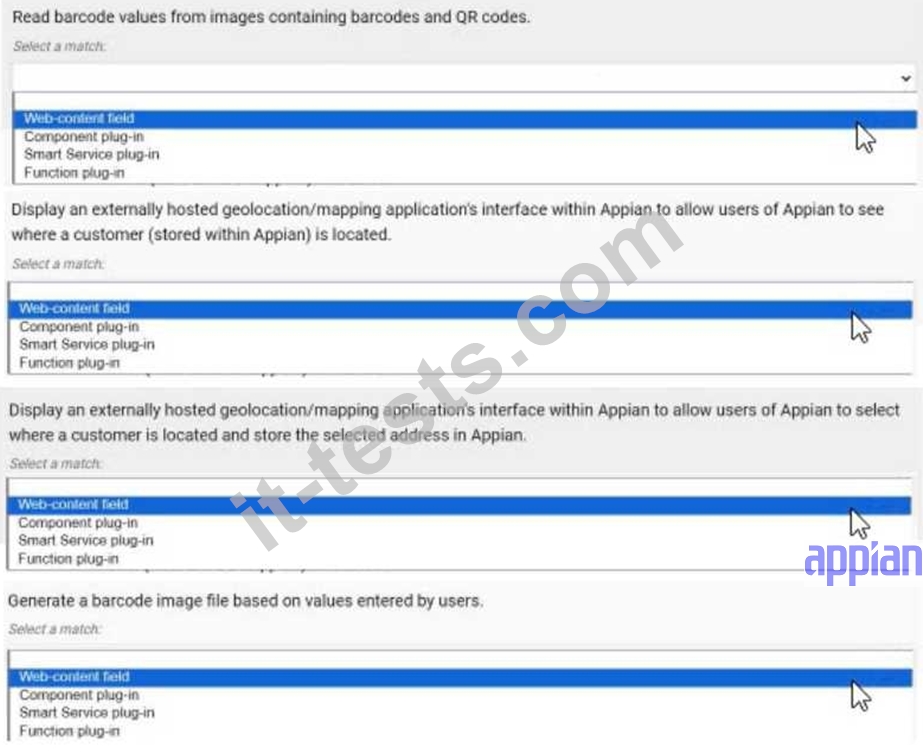
Answer:
Explanation: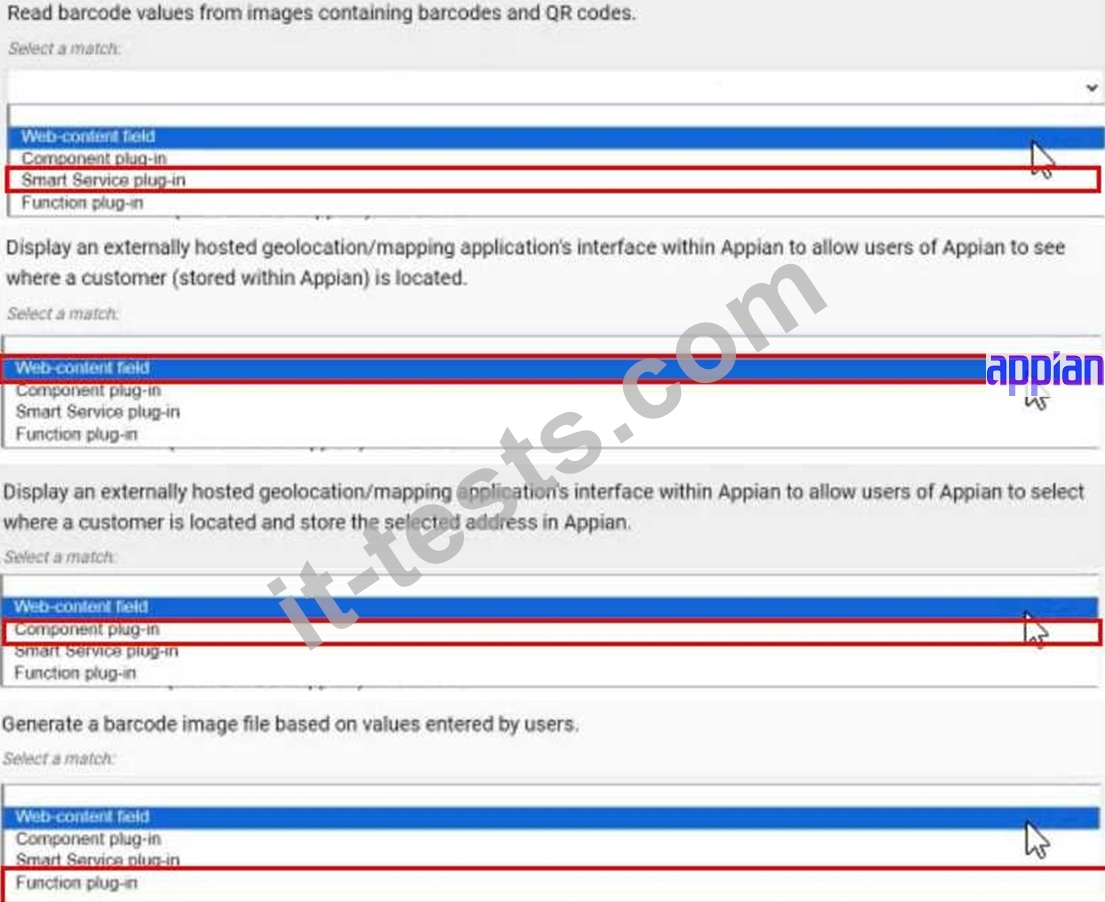
NEW QUESTION # 27
You are tasked to build a large-scale acquisition application for a prominent customer. The acquisition process tracks the time it takes to fulfill a purchase request with an award.
The customer has structured the contract so that there are multiple application development teams.
How should you design for multiple processes and forms, while minimizing repeated code?
Answer: B
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, designing a large-scale acquisition application with multiple development teams requires a strategy to manage processes, forms, and code reuse effectively. The goal is to minimize repeated code (e.g., duplicate interfaces, process models) while ensuring scalability and maintainability across teams. Let's evaluate each option:
A . Create a Center of Excellence (CoE):
A Center of Excellence is an organizational structure or team focused on standardizing practices, training, and governance across projects. While beneficial for long-term consistency, it doesn't directly address the technical design of minimizing repeated code for processes and forms. It's a strategic initiative, not a design solution, and doesn't solve the immediate need for code reuse. Appian's documentation mentions CoEs for governance but not as a primary design approach, making this less relevant here.
B . Create a common objects application:
This is the best recommendation. In Appian, a "common objects application" (or shared application) is used to store reusable components like expression rules, interfaces, process models, constants, and data types (e.g., CDTs). For a large-scale acquisition application with multiple teams, centralizing shared objects (e.g., rule!CommonForm, pm!CommonProcess) ensures consistency, reduces duplication, and simplifies maintenance. Teams can reference these objects in their applications, adhering to Appian's design best practices for scalability. This approach minimizes repeated code while allowing team-specific customizations, aligning with Lead Developer standards for large projects.
C . Create a Scrum of Scrums sprint meeting for the team leads:
A Scrum of Scrums meeting is a coordination mechanism for Agile teams, focusing on aligning sprint goals and resolving cross-team dependencies. While useful for collaboration, it doesn't address the technical design of minimizing repeated code-it's a process, not a solution for code reuse. Appian's Agile methodologies support such meetings, but they don't directly reduce duplication in processes and forms, making this less applicable.
D . Create duplicate processes and forms as needed:
Duplicating processes and forms (e.g., copying interface!PurchaseForm for each team) leads to redundancy, increased maintenance effort, and potential inconsistencies (e.g., divergent logic). This contradicts the goal of minimizing repeated code and violates Appian's design principles for reusability and efficiency. Appian's documentation strongly discourages duplication, favoring shared objects instead, making this the least effective option.
Conclusion: Creating a common objects application (B) is the recommended design. It centralizes reusable processes, forms, and other components, minimizing code duplication across teams while ensuring consistency and scalability for the large-scale acquisition application. This leverages Appian's application architecture for shared resources, aligning with Lead Developer best practices for multi-team projects.
Appian Documentation: "Designing Large-Scale Applications" (Common Application for Reusable Objects).
Appian Lead Developer Certification: Application Design Module (Minimizing Code Duplication).
Appian Best Practices: "Managing Multi-Team Development" (Shared Objects Strategy).
To build a large scale acquisition application for a prominent customer, you should design for multiple processes and forms, while minimizing repeated code. One way to do this is to create a common objects application, which is a shared application that contains reusable components, such as rules, constants, interfaces, integrations, or data types, that can be used by multiple applications. This way, you can avoid duplication and inconsistency of code, and make it easier to maintain and update your applications. You can also use the common objects application to define common standards and best practices for your application development teams, such as naming conventions, coding styles, or documentation guidelines. Verified [Appian Best Practices], [Appian Design Guidance]
NEW QUESTION # 28
Your application contains a process model that is scheduled to run daily at a certain time, which kicks off a user input task to a specified user on the 1st time zone for morning data collection. The time zone is set to the (default) pm!timezone. In this situation, what does the pm!timezone reflect?
Answer: C
Explanation:
Comprehensive and Detailed In-Depth Explanation:
In Appian, the pm!timezone variable is a process variable automatically available in process models, reflecting the time zone context for scheduled or time-based operations. Understanding its behavior is critical for scheduling tasks accurately, especially in scenarios like this where a process runs daily and assigns a user input task.
Option C (The default time zone for the environment as specified in the Administration Console):
This is the correct answer. Per Appian's Process Model documentation, when a process model uses pm!timezone and no custom time zone is explicitly set, it defaults to the environment's time zone configured in the Administration Console (under System > Time Zone settings). For scheduled processes, such as one running "daily at a certain time," Appian uses this default time zone to determine when the process triggers. In this case, the task assignment occurs based on the schedule, and pm!timezone reflects the environment's setting, not the user's location.
Option A (The time zone of the server where Appian is installed): This is incorrect. While the server's time zone might influence underlying system operations, Appian abstracts this through the Administration Console's time zone setting. The pm!timezone variable aligns with the configured environment time zone, not the raw server setting.
Option B (The time zone of the user who most recently published the process model): This is irrelevant. Publishing a process model does not tie pm!timezone to the publisher's time zone. Appian's scheduling is system-driven, not user-driven in this context.
Option D (The time zone of the user who is completing the input task): This is also incorrect. While Appian can adjust task display times in the user interface to the assigned user's time zone (based on their profile settings), the pm!timezone in the process model reflects the environment's default time zone for scheduling purposes, not the assignee's.
For example, if the Administration Console is set to EST (Eastern Standard Time), the process will trigger daily at the specified time in EST, regardless of the assigned user's location. The "1st time zone" phrasing in the question appears to be a typo or miscommunication, but it doesn't change the fact that pm!timezone defaults to the environment setting.
NEW QUESTION # 29
As part of an upcoming release of an application, a new nullable field is added to a table that contains customer dat a. The new field is used by a report in the upcoming release and is calculated using data from another table.
Which two actions should you consider when creating the script to add the new field?
Answer: B,E
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, adding a new nullable field to a database table for an upcoming release requires careful planning to ensure data integrity, report functionality, and rollback capability. The field is used in a report and calculated from another table, so the script must handle both deployment and potential reversibility. Let's evaluate each option:
A . Create a script that adds the field and leaves it null:
Adding a nullable field and leaving it null is technically feasible (e.g., using ALTER TABLE ADD COLUMN in SQL), but it doesn't address the report's need for calculated data. Since the field is used in a report and calculated from another table, leaving it null risks incomplete or incorrect reporting until populated, delaying functionality. Appian's data management best practices recommend populating data during deployment for immediate usability, making this insufficient as a standalone action.
B . Create a rollback script that removes the field:
This is a critical action. In Appian, database changes (e.g., adding a field) must be reversible in case of deployment failure or rollback needs (e.g., during testing or PROD issues). A rollback script that removes the field (e.g., ALTER TABLE DROP COLUMN) ensures the database can return to its original state, minimizing risk. Appian's deployment guidelines emphasize rollback scripts for schema changes, making this essential for safe releases.
C . Create a script that adds the field and then populates it:
This is also essential. Since the field is nullable, calculated from another table, and used in a report, populating it during deployment ensures immediate functionality. The script can use SQL (e.g., UPDATE table SET new_field = (SELECT calculated_value FROM other_table WHERE condition)) to populate data, aligning with Appian's data fabric principles for maintaining data consistency. Appian's documentation recommends populating new fields during deployment for reporting accuracy, making this a key action.
D . Create a rollback script that clears the data from the field:
Clearing data (e.g., UPDATE table SET new_field = NULL) is less effective than removing the field entirely. If the deployment fails, the field's existence with null values could confuse reports or processes, requiring additional cleanup. Appian's rollback strategies favor reverting schema changes completely (removing the field) rather than leaving it with nulls, making this less reliable and unnecessary compared to B.
E . Add a view that joins the customer data to the data used in calculation:
Creating a view (e.g., CREATE VIEW customer_report AS SELECT ... FROM customer_table JOIN other_table ON ...) is useful for reporting but isn't a prerequisite for adding the field. The scenario focuses on the field addition and population, not reporting structure. While a view could optimize queries, it's a secondary step, not a primary action for the script itself. Appian's data modeling best practices suggest views as post-deployment optimizations, not script requirements.
Conclusion: The two actions to consider are B (create a rollback script that removes the field) and C (create a script that adds the field and then populates it). These ensure the field is added with data for immediate report usability and provide a safe rollback option, aligning with Appian's deployment and data management standards for schema changes.
Appian Documentation: "Database Schema Changes" (Adding Fields and Rollback Scripts).
Appian Lead Developer Certification: Data Management Module (Schema Deployment Strategies).
Appian Best Practices: "Managing Data Changes in Production" (Populating and Rolling Back Fields).
NEW QUESTION # 30
......
If you are preparing for the practice exam, we can make sure that the ACD-301 study materials from our company will be the best choice for you, and you cannot find the better study materials than our company’. There are a lot of advantages of our ACD-301 Study Materials, and then, I am going to introduce the special functions of our ACD-301 study materials in detail to you. We are hopeful that you will like our products.
ACD-301 Actual Braindumps: https://www.it-tests.com/ACD-301.html
What's more, part of that It-Tests ACD-301 dumps now are free: https://drive.google.com/open?id=1SvCfNVZhlpSAncvOoSQSBOry6DlVixlS