BTW, DOWNLOAD part of PrepAwayPDF DP-750 dumps from Cloud Storage: https://drive.google.com/open?id=1VONeEiOjxElfxTWi8GbZFh1swjSFyM84
Cease to struggle and you cease to live. Only by continuous learning can we not be surpassed by others. Many people do not like to study and think that learning is a very vexing thing. This kind of cognition makes their careers stagnate. DP-750 test question will change your perception. DP-750 learning dumps aim to help students learn easily and effectively that has been developed over many years by many industry experts. For the online version, unlike other materials that limit one person online, DP-750 learning dumps does not limit the number of concurrent users and the number of online users. You can practice anytime, anywhere, practice repeatedly, practice with others, and even purchase together with othersDP-750 learning dumps make every effort to help you save money and effort, so that you can pass the exam with the least cost.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Topic 2: Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
| Topic 3: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Topic 4: Prepare and process data | 30-35% | - Data quality and validation
|
When asked about the opinion about the exam, most people may think that it’s not a quite easy thing, and some people even may think that it’s a difficult thing. DP-750 learning materials of us include the questions and answers, which will show you the right answers after you finish practicing. DP-750 Online Test engine can record the test history and have a performance review, with this function you can have a review of what you have learned.
NEW QUESTION # 44
You have an Azure Databricks workspace that contains a Git folder and uses Azure Repos as the Git provider.
From the main branch, you create a branch named Branch1. You commit changes to Branch1.
You need to incorporate the changes from Branch1 into main The solution must preserve the commit history in the repository. Which command should you run?
Answer: C
Explanation:
The correct answer is A - merge.
A Git merge combines the histories of two branches by creating a merge commit that joins them. Every individual commit from Branch1 remains visible in the repository log - the full development history is preserved. This is the requirement: 'the solution must preserve the commit history in the repository.' Option C (rebase) moves Branch1's commits on top of main by replaying them as new commits with new hashes. The end result looks like a linear history, but the original commit hashes are rewritten - the prior history is not preserved in its original form. For a shared repository, rebase rewrites public history, which is considered problematic.
Option B (pull) fetches remote changes and merges or rebases them into the current branch - it's used to sync with a remote, not to incorporate a feature branch. Option D (push) sends local commits to the remote but doesn't incorporate any branch into another.
Reference: https://learn.microsoft.com/en-us/azure/databricks/repos/git-operations-with-repos
NEW QUESTION # 45
Which tool is best for continuous ingestion of files landing in Azure Data Lake?
Answer: B
Explanation:
Auto Loader is optimized for incremental and continuous ingestion from cloud storage. It detects new files automatically and scales efficiently. Databricks Jobs schedule tasks but do not handle file detection. Logic Apps are workflow tools. ADF is batch-oriented.
NEW QUESTION # 46
Which ingestion option should you recommend for each data source? To answer, drag the appropriate options to the correct data sources. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.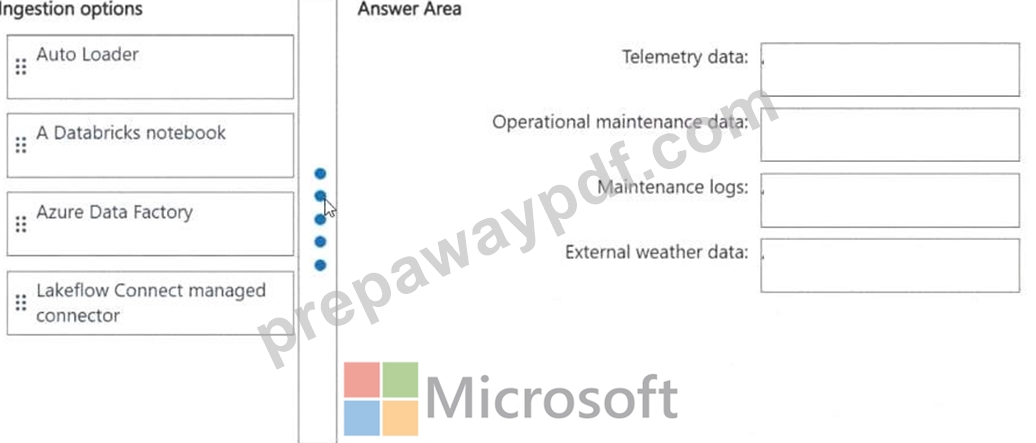
Answer:
Explanation: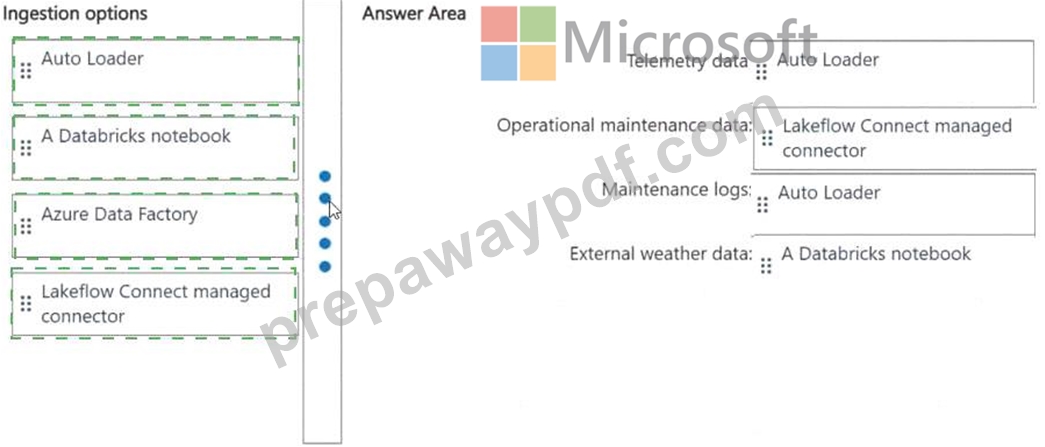
Explanation:
The right ingestion tool depends on the source characteristics:
File-based telemetry and maintenance data # Auto Loader (cloudFiles). It monitors ADLS Gen2 for new arrivals, handles schema inference and evolution for the frequent schema drift, and requires minimal operational effort.
Real-time telemetry from Event Hubs # Spark Structured Streaming with the azure-eventhubs-spark connector. This provides exactly-once semantics and checkpoint-based recovery, satisfying 'resume processing after failures without reprocessing.' Structured maintenance data from PostgreSQL # JDBC connector. Databricks supports direct JDBC reads from relational databases with pushdown predicates.
Daily CSV ERP extracts (50-100 GB) # COPY INTO or Auto Loader. Both support idempotent incremental batch loading into Delta tables with minimal code.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/auto-loader/
NEW QUESTION # 47
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 processes raw data files stored in Azure Storage.
New files arrive at unpredictable intervals.
You need to ensure that Job1 starts automatically when new files arrive and does NOT consume compute resources when no data is available.
Which type of job trigger should you use?
Answer: A
Explanation:
A file arrival trigger starts Job1 when new files are detected in the monitored Azure Storage location. Because the job is launched only after a qualifying arrival, compute does not remain active while the source is idle.
This is well suited to unpredictable file-delivery patterns and avoids the unnecessary executions produced by a fixed schedule. A continuous trigger keeps the workload running and therefore consumes compute even when no files are available. A scheduled trigger starts the job at predetermined times whether or not new data exists. A manual trigger cannot provide automatic processing. File arrival triggers consequently provide the required event-driven behavior while improving resource utilization and controlling cost during inactive periods. Microsoft Learn
NEW QUESTION # 48
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You need to configure Cluster1 to meet the following requirements:
- The cluster must scale up automatically when workloads increase.
- The cluster must scale down automatically when workloads decrease.
The solution must minimize costs.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,B
Explanation:
Enabling autoscaling and setting a 30-minute auto-termination timeout is the correct configuration to meet the goals.
Autoscaling handles fluctuating workloads, while auto-termination prevents you from paying for idle compute resources.
Dynamic Scaling: Autoscaling automatically adds workers during high loads and removes them when demand drops.
Cost Control: The 30-minute termination window ensures the cluster shuts down completely if no jobs are running, stopping all compute charges.
Reference:
https://community.databricks.com/t5/get-started-discussions/cluster-auto-termination-best- practices/td-p/75826
NEW QUESTION # 49
......
The pass rate is 98.65%, and we can ensure you pass the exam if you choose DP-750 training materials from us. In addition, we have professional experts to compile and verify DP-750 questions and answers, therefore you can just use them at ease. We also pass guarantee and money back guarantee if you fail to pass the exam. Free update for DP-750 Training Materials is available, namely, in the following year, you don’t need to spend a cent, but you can get the latest information of the exam. And the latest version for DP-750 exam briandumps will send to your email automatically.
Valid DP-750 Exam Camp Pdf: https://www.prepawaypdf.com/Microsoft/DP-750-practice-exam-dumps.html
BONUS!!! Download part of PrepAwayPDF DP-750 dumps for free: https://drive.google.com/open?id=1VONeEiOjxElfxTWi8GbZFh1swjSFyM84