ちなみに、PassTest AIF-C01の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1_f-f_SGeS2OoonJ1xR03RN8IF0LQyjEE
これらの問題を解決するための基本的な方法は、社会の発展よりも速いスピードで成長することです。現場では、Amazon認定を取得して、自分自身を改善し、より良いあなたとより良い未来を目指してください。それにより、あなたはあなたの職業で認められます。 AIF-C01試験トレントは、より大企業に注意を向けさせる能力を証明できます。その後、より良い仕事を取得し、適切な職場に行くための選択肢があります。そして、AIF-C01試験問題は、98%以上の高い品質と高い合格率で有名です。 AIF-C01学習ガイドをお試しください。
| Section | Weight | Objectives |
|---|---|---|
| Guidelines for Responsible AI | 14% | - Define responsible AI principles: fairness, transparency, privacy, safety - Explain bias detection and reduction - Identify risks and mitigation strategies for AI systems - Describe ethical and societal impacts of AI |
| Fundamentals of AI and ML | 20% | - Identify types of ML: supervised, unsupervised, reinforcement learning - Define artificial intelligence (AI), machine learning (ML), and deep learning - Recognize key concepts: data, models, training, inference, evaluation - Describe common ML workflows and lifecycle |
| Applications of Foundation Models | 28% | - Describe use cases for text, image, video, and code generation - Recognize tools for building and deploying generative AI solutions - Identify AWS services for generative AI: Amazon Bedrock, Amazon Titan - Explain integration of foundation models into applications |
| Fundamentals of Generative AI | 24% | - Describe concepts: prompts, embeddings, fine-tuning, retrieval-augmented generation (RAG) - Explain capabilities and use cases of generative AI - Define generative AI and foundation models - Differentiate between generative AI and traditional ML |
| Security, Compliance, and Governance for AI Solutions | 14% | - Governance frameworks for AI lifecycle - Security controls for AI data and models - Data protection and privacy in AI workflows - Compliance requirements and regulations |
弊社PassTestのAIF-C01試験準備では、学習習慣を身に付けるのに役立ちます。 AIF-C01学習教材を購入して使用すると、学習の良い習慣を身に付けることができます。さらに重要なことは、良い習慣は科学的な小道具の学習方法を見つけ、学習効率を高めるのに役立ちます。そして、短時間でAIF-C01試験に合格するのに役立ちます。弊社からAIF-C01テストガイドを急いで購入すると、多くのメリットが得られます。
質問 # 369
A company is implementing the Amazon Titan foundation model (FM) by using Amazon Bedrock. The company needs to supplement the model by using relevant data from the company's private data sources.
Which solution will meet this requirement?
正解:C
解説:
Creating an Amazon Bedrock knowledge base allows the integration of external or private data sources with a foundation model (FM) like Amazon Titan. This integration helps supplement the model with relevant data from the company's private data sources to enhance its responses.
* Option C (Correct): "Create an Amazon Bedrock knowledge base": This is the correct answer as it enables the company to incorporate private data into the FM to improve its effectiveness.
* Option A: "Use a different FM" is incorrect because it does not address the need to supplement the current model with private data.
* Option B: "Choose a lower temperature value" is incorrect as it affects output randomness, not the integration of private data.
* Option D: "Enable model invocation logging" is incorrect because logging does not help in supplementing the model with additional data.
AWS AI Practitioner References:
* Amazon Bedrock and Knowledge Integration: AWS explains how creating a knowledge base allows Amazon Bedrock to use external data sources to improve the FM's relevance and accuracy.
質問 # 370
A company is building an AI application to summarize books of varying lengths. During testing, the application fails to summarize some books. Why does the application fail to summarize some books?
正解:C
解説:
Comprehensive and Detailed
Foundation models have a context window (max tokens), which limits the size of the input text (prompt + instructions).
If the input (e.g., a very long book) exceeds this limit, the model cannot process it, causing failure.
Temperature (A) and Top P (C) control randomness, not input size.
Fine-tuning (B) is irrelevant to input truncation failures.
Reference:
AWS Documentation - Amazon Bedrock Model Parameters (context size limits)
質問 # 371
A company wants to make a trained model available to production applications through an API endpoint for runtime queries.
Which ML lifecycle phase does this activity represent?
正解:A
解説:
The verified answer is D. Model deployment and inference. The question describes a trained model being made available to production applications through an API endpoint. That is deployment, and the runtime use of the model to answer queries is inference. AWS SageMaker documentation states that after training, you can get predictions, or inferences, from trained machine learning models, and SageMaker provides model deployment options to support ML inference needs. This directly matches the phrase "available to production applications through an API endpoint for runtime queries." Data preparation is incorrect because that phase happens before training. It includes collecting, cleaning, transforming, labeling, and preparing datasets so the model can learn from them. The question already says the model is trained, so the workflow has moved beyond data preparation.
Model training and tuning is incorrect because training and tuning are where the model learns patterns from data and hyperparameters may be adjusted to improve performance. The question is not describing learning, optimization, or retraining. It describes exposing the trained model to applications.
Model evaluation and validation is incorrect because evaluation checks whether the model meets quality, accuracy, fairness, safety, or business criteria before or during production use. The scenario does not describe testing the model; it describes making the model callable by production applications.
In the ML lifecycle, deploying a model means placing it into an environment where applications can send requests and receive predictions. Inference is the process of using the deployed model to generate outputs from new inputs. Because the company is exposing the trained model through an API endpoint for runtime queries, the activity is model deployment and inference.
質問 # 372
A company has a large amount of unlabeled data. The company wants to group the data based on feature similarities.
Which algorithm will meet this requirement?
正解:A
解説:
Comprehensive and Detailed Explanation (AWS AI documents):
AWS machine learning fundamentals classify K-means as an unsupervised learning algorithm used to group unlabeled data into clusters based on feature similarity and distance metrics. Because the data is unlabeled and the goal is grouping rather than prediction, K-means is the most appropriate choice.
Why the other options are incorrect:
* XGBoost is a supervised learning algorithm that requires labeled data.
* DeepAR forecasting is designed for time series forecasting.
* Linear learner is typically used for supervised regression or classification tasks.
AWS AI Study Guide References:
* AWS unsupervised learning concepts
* AWS clustering algorithms overview
質問 # 373
Which THREE of the following principles of responsible AI are most critical to this scenario? (Choose 3)
* Explainability
* Fairness
* Privacy and security
* Robustness
* Safety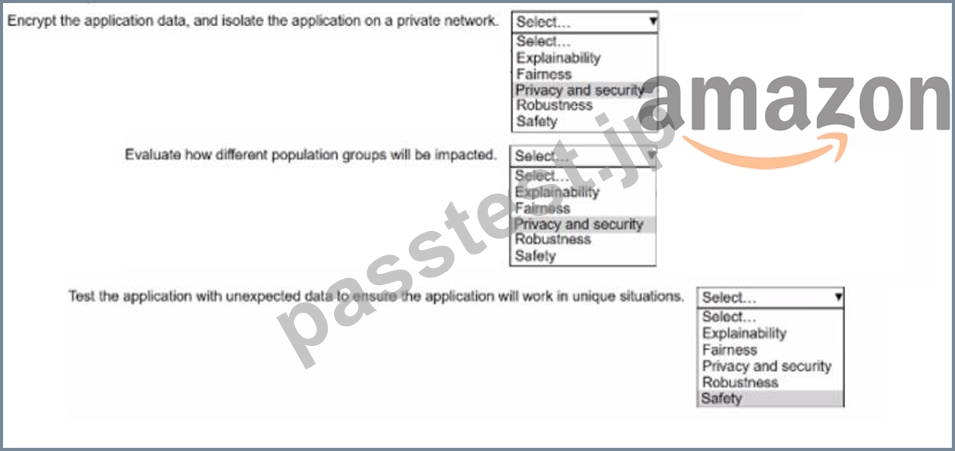
正解:
解説: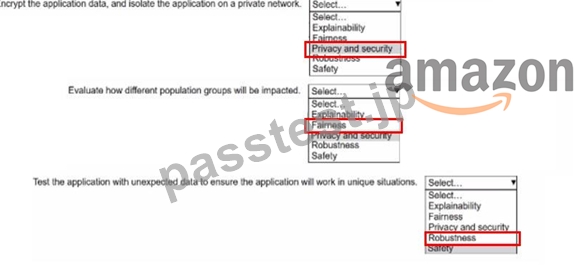
質問 # 374
......
今の社会の中で、ネット上で訓練は普及して、弊社は試験問題集を提供する多くのネットの一つでございます。PassTestが提供したのオンラインAIF-C01商品がAmazon業界では品質の高い学習資料、受験生の必要が満足できるサイトでございます。
AIF-C01最速合格: https://www.passtest.jp/Amazon/AIF-C01-shiken.html
P.S.PassTestがGoogle Driveで共有している無料の2026 Amazon AIF-C01ダンプ:https://drive.google.com/open?id=1_f-f_SGeS2OoonJ1xR03RN8IF0LQyjEE