The content of our AI-500 practice engine is based on real exam by whittling down superfluous knowledge without delinquent mistakes rather than dropping out of reality. Being subjected to harsh tests of market, our AI-500 exam questions are highly the manifestation of responsibility carrying out the tenets of customer oriented. And our AI-500 Study Materials are warmly praised and welcomed by the customers all over the world.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure, govern, and deploy multi-agent solutions | 20–25% | - Apply security and compliance
|
| Topic 2: Develop multi-agent solutions in Azure | 30–35% | - Implement agents using Azure AI services
|
| Topic 3: Architect multi-agent solutions | 15–20% | - Design logical architecture for multi-agent systems
|
| Topic 4: Evaluate, optimize, and monitor multi-agent solutions | 20–25% | - Assess performance and reliability
|
>> AI-500 Latest Learning Material <<
Time is flying and the exam date is coming along, which is sort of intimidating considering your status of review process. The more efficient the materials you get, the higher standard you will be among competitors. So, high quality and high accuracy rate AI-500 practice materials are your ideal choice this time. By adding all important points into AI-500 practice materials with attached services supporting your access of the newest and trendiest knowledge, our AI-500 practice materials are quite suitable for you right now.
NEW QUESTION # 56
You need to implement an advanced prompt engineering strategy to resolve the Patient Intake agent issues.
The solution must prevent hardcoding new logic into the agent ' s core prompt.
What should you do?
Answer: A
Explanation:
The intake problem involves verbose, variable patient narratives and a requirement to avoid hardcoding new logic into the core prompt. Injecting dynamic context with curated few-shot examples gives the model representative demonstrations of how to identify clinically relevant symptoms while ignoring irrelevant narrative details. Microsoft AI-500 objectives explicitly include examples and dynamic context injection as advanced prompt-engineering techniques. Removing defensive guidance would weaken safety. Reducing the context window would not teach the model what information matters and could simply discard useful details.
Frequent full-model fine-tuning is operationally heavier and unnecessary for a behavior that can be demonstrated through curated examples. Dynamic few-shot context also allows the examples to be versioned and updated without rewriting the agent ' s base persona or application logic. Therefore C best addresses the extraction problem while preserving prompt lifecycle flexibility. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: AI-500 Study Guide - advanced prompt engineering
NEW QUESTION # 57
You have a Microsoft Foundry multi-agent solution. The solution includes an orchestrator that uses Azure Al Search as a semantic cache to shortlist agents and invokes the top match.
You have a version-controlled repository that contains a curated dataset, expected routing, and expected responses. A pull request adds an agent named Agent 1, new sample utterances, and a changed selector prompt.
You need to configure an automated prerelease evaluation gate for the pull request. The solution must meet the following requirements:
* Validate the integrated system response after the new agent is available to orchestration.
* Validate the semantic cache retrieval quality against the expected results.
* Keep regression tests aligned with the pull request changes.
How should you configure the evaluation gate? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Semantic cache metric: Candidate-set recall and precision; Integrated system check: An end-to-end evaluation against the curated dataset; Regression dataset: Add cases for the new capability to the curated dataset.
The semantic cache is acting as a retrieval/shortlisting component, so recall and precision are the appropriate measures of whether expected agent candidates are surfaced and whether irrelevant candidates are avoided.
The pull request also changes the selector prompt and adds an agent, so component-only tests are insufficient; an end-to-end evaluation must exercise retrieval, routing, the new agent, and final response generation together. Finally, the version-controlled regression dataset should evolve with the capability. Adding representative cases for the new agent keeps expected routing and responses aligned with the code and prompt changes in the pull request. Microsoft Foundry evaluation guidance treats curated datasets as reusable regression assets for CI/CD quality gates. Together, these three selections test retrieval quality, integrated behavior, and regression coverage at the correct layers. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - evaluation datasets and CI/CD evaluation
NEW QUESTION # 58
You are designing Microsoft Foundry multi-agent solution. The agents will use Agent-to-Agent (A2A) delegation and access separate Azure Storage containers within a lesource group named RG1.
You need to recommend identity components for the design. The solution must meet the following requirements:
* Eliminate stored application secrets.
* Limit the impact of a compromised agent or deployment.
Solution: Use a shared single-tenant application registration for the agents Assign Azure roles at the subscription scope. Does this meet the goal?
Answer: B
Explanation:
A shared single-tenant application registration combined with subscription-wide role assignments creates an excessively broad trust and authorization boundary. It also does not, by itself, guarantee elimination of stored credentials because an app registration can still authenticate with a client secret or certificate unless federation is configured. More importantly, compromise of any agent using the shared identity could expose resources well beyond that agent ' s assigned Storage container. Microsoft guidance favors distinct workload/agent identities and the narrowest practical Azure RBAC scope, ideally at the resource or data-resource level required by each agent. Because the proposed design uses both a shared identity and subscription-level access, it fails the blast-radius requirement and least-privilege principle. Therefore B, No, is correct. Least privilege remains the governing principle: grant only the identity, data, tool, or deployment access required for the specific operation. The selected answer preserves that boundary while still allowing the workflow to satisfy its functional requirement.
Official Microsoft reference: Microsoft Foundry agent identity
NEW QUESTION # 59
You have a multi-agent Retrieval-Augmented Generation (RAG) solution that uses a Foundry IQ knowledge base. The solution includes a support agent and a policy agent.
You have an evaluation dataset that contains the following for each user query
* The expected source IDs
* Retrieved chunks in rank order
* The final agent response
You discover that an embedding model change and a custom analyzer change cause the failed traces shown in the following table.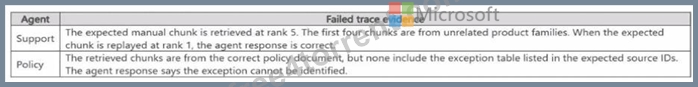
You need to isolate the failing parts of the RAG pipeline.
Which evaluator should you use for each agent? To answer, drag the appropriate evaluators to the correct agents. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.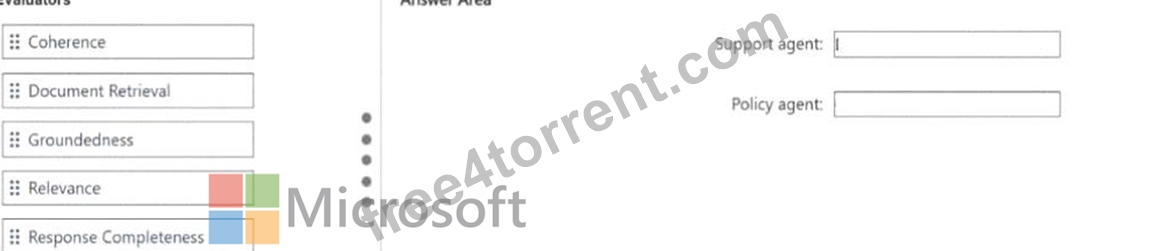
Answer:
Explanation: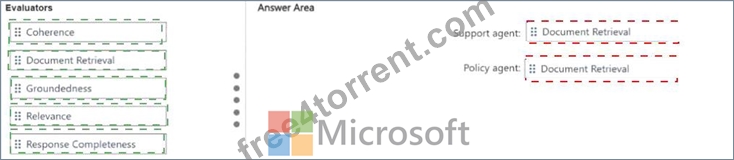
Explanation:
Support agent: Document Retrieval; Policy agent: Document Retrieval.
Both failures are retrieval failures and should therefore be diagnosed with the Document Retrieval evaluator.
The dataset includes expected source IDs and ranked retrieved chunks, which provides the retrieval ground truth required by that evaluator. For the support agent, the expected source appears too low in the ranking after unrelated chunks. For the policy agent, the required exception-table source is missing entirely.
Groundedness would evaluate whether the final response is supported by the context it actually received; it could therefore pass even when the retrieval stage failed to fetch a required source. Microsoft Foundry ' s Document Retrieval evaluator compares retrieved documents against labeled ground truth and reports ranking
/search metrics such as NDCG and Fidelity. The corrected answer is Document Retrieval for both agents. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
NEW QUESTION # 60
You need to recommend changes to decrease the Claim Approval duration without breaking any existing functionality.
What should you recommend?
Answer: A
Explanation:
Fraud-check, Policy-eligibility, and Document-summary are independent specialist activities, so running them concurrently reduces wall-clock time without changing their outputs. The Decision agent is different because the case study states that it depends on the results of those three agents. It therefore must execute only after the independent work completes. Microsoft Agent Framework ' s concurrent orchestration pattern is designed for independent participants whose results can be fanned in later, while dependency-driven work should remain ordered. Running all four agents concurrently would violate the Decision agent ' s data dependency.
Running all four sequentially would preserve correctness but add unnecessary latency. Disabling memory would also change functionality unrelated to the performance bottleneck. The optimal graph is therefore a parallel fan-out of the three independent specialists followed by a fan-in and Decision step, which preserves behavior while minimizing end-to-end claim-approval duration. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Microsoft Agent Framework - Concurrent orchestration
NEW QUESTION # 61
......
There are some prominent features that are making the Microsoft AI-500 exam dumps the first choice of AI-500 certification exam candidates. The prominent features are real and verified AI-500 exam questions, availability of Microsoft AI-500 exam dumps in three different formats, affordable price, 1 year free updated AI-500 Exam Questions download facility, and 100 percent Microsoft AI-500 exam passing money back guarantee. We are quite confident that all these AI-500 exam dumps feature you will not find anywhere.
AI-500 Latest Test Simulator: https://www.free4torrent.com/AI-500-braindumps-torrent.html