P.S. Free & New DP-600 dumps are available on Google Drive shared by ActualVCE: https://drive.google.com/open?id=1Re-FlTJNTwtN-phG7kWHU2dUqizdW7Zs
With our DP-600 exam materials, you will find that the difficult topics have been given special attention by our professional experts and explained with the help of examples, simulations and graphs. Our DP-600 study braindumps will certainly help candidates to enrich their knowledge in their daily work and be ready to answer all questions in the real exam. The benefits of studying our DP-600 learning guide is doubled to your expectation.
| Section | Objectives |
|---|---|
| Topic 1: Manage and secure Microsoft Fabric | - Governance and administration
|
| Topic 2: Get data into Microsoft Fabric | - Data ingestion and integration
|
| Topic 3: Real-time analytics | - Streaming and event processing
|
| Topic 4: Implement analytics solutions | - Data warehousing and modeling
|
| Topic 5: Implement data engineering solutions | - Lakehouse architecture
|
Now rest assured that with the Microsoft DP-600 exam questions you will get the updated version of DP-600 exam real questions all the time. You have the option to download updated Microsoft DP-600 Exam Questions up to 12 months from the date of Microsoft DP-600 exam questions purchase.
NEW QUESTION # 129
You ne ed to recommend a solution to prepare the tenant for the PoC.
Which two actions should you recommend performing from the Fabric Admin portal? Each correct answer presents part of the solution.
NOTE: Each correct answer is worth one point.
Answer: A,B
Explanation:
The PoC is planned to be completed using a Fabric trial capacity, which implies that users involved in the PoC should be able to try paid features. However, this should be limited to specific security groups involved in the PoC to prevent the entire organization from accessing the se features before the trial is proven successful (A). The ability for users to create Fabric items should also be enabled for specific security groups to ensure that only the relevant team members participating in the PoC can create items in the Fabric en vironment (E).
Topic 1, Litware. Inc. Case Study
Overview
Litware. Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
litware has been using a Microsoft Power Bl tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Fabric En vironment
Litware has data that must be analyzed as shown in the following table.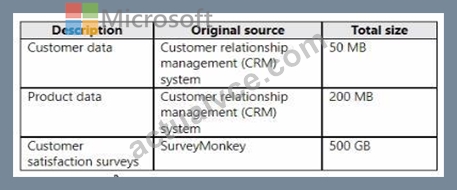
The Product data contains a single table and the following columns.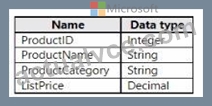
The customer satisfaction data contains the following tables:
* Survey
* Question
* Response
For each survey submitted, the following occurs:
* One row is added to the Survey table.
* One row is added to the Response table for each question in the survey.
The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Litware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity.
The following three workspaces will be created:
* AnalyticsPOC: Will contain the data store, semantic models, reports, pipelines, dataflows, and notebooks used to populate the data store
* DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate Onelake
* DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
* A data store (type to be decided)
* A custom semantic model
* A default semantic model
* Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers ' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
* Read access by using T-SQL or Python
* Semi-structured and unstructured data
* Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model.
The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model.
The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SQL queries and in the default semantic model. The following logic must be used:
* List prices that are less than or equal to 50 are in the low pricing group.
* List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
* List pnces that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC. Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
* Fabric administrators will be the workspace administrators.
* The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
* The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
* The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook.
* The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power Bl reports by using the semantic models created by the analytics engineers.
* The date dimension must be available to all users of the data store.
* The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
* FabricAdmins: Fabric administrators
* AnalyticsTeam: All the members of the analytics team
* DataAnalysts: The data analysts on the analytics team
* DataScientists: The data scientists on the analytics team
* Data Engineers: The data engineers on the analytics team
* Analytics Engineers: The analytics engineers on the analytics team
Report Requirements
The data analysis must create a customer satisfaction report that meets the following requirements:
* Enables a user to select a product to filter customer survey responses to only those who have purchased that product
* Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected date
* Shows data as soon as the data is updated in the data store
* Ensures that the report and the semantic model only contain data from the current and previous year
* Ensures that the report respects any table-level security specified in the source data store
* Minimizes the execution time of report queries
NEW QUESTION # 130
You have a Microsoft Power Bl project that contains a file named definition.pbir. definition.pbir contains the following JSON.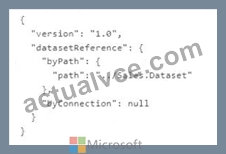
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.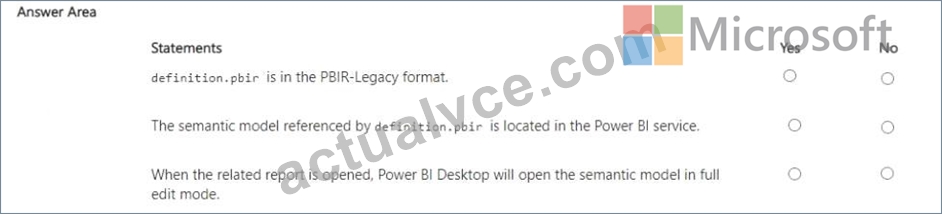
Answer:
Explanation:
Explanation: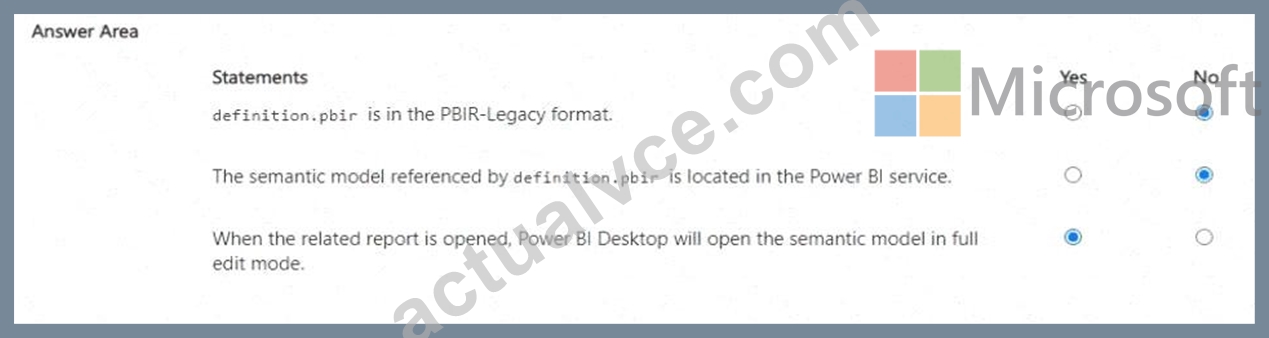
We are analyzing the JSON for definition.pbir in a Power BI Project:
{
" version " : " 1.0 " ,
" datasetReference " : {
" byPath " : {
" path " : " ../Sales.Dataset "
},
" byConnection " : null
}
}
Statement 1:
" definition.pbir is in the PBIR-Legacy format. "
No # The legacy PBIR format references datasets by byConnection (pointing to the Power BI service).
Here, it uses byPath, which is the new project format, not legacy.
Statement 2:
" The semantic model referenced by definition.pbir is located in the Power BI service. " No # The JSON shows byPath: " ../Sales.Dataset " , meaning the semantic model is referenced locally within the project folder (Sales.Dataset), not in the Power BI service.
Statement 3:
" When the related report is opened, Power BI Desktop will open the semantic model in full edit mode. " Yes # Since the semantic model is referenced by path (local PBIP project files), Power BI Desktop will open the model in full edit mode. If it had been byConnection, it would open in live connect mode to the service instead.
Final Answer:
PBIR-Legacy format # No
Semantic model in Power BI service # No
Opens in full edit mode # Yes
References:
Power BI Project (PBIP) structure
PBIR formats: byPath vs byConnection
NEW QUESTION # 131
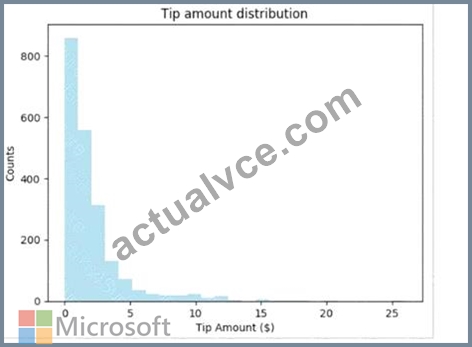
You have a Fabric notebook that has the Python code and output shown in the following exhibit.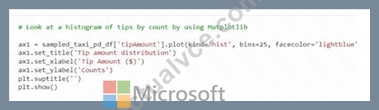
Which type of analytics are you performing?
Answer: A
Explanation:
The Python code and output shown in the exhibit display a histogram, which is a representation of the distribution of data. This kind of analysis is descriptive analytics, which is used to describe or summarize the features of a dataset. Descriptive analytics answers the question of "what has happened" by providing insight into past data through tools such as mean, median, mode, standard deviation, and graphical representations like histograms.
References: Descriptive analytics and the use of histograms as a way to visualize data distribution are basic concepts in data analysis, often covered in introductory analytics and Python programming resources.
NEW QUESTION # 132
You have a Fabric tenant that contains a semantic model. The model contains data about retail stores.
You need to write a DAX query that will be executed by using the XMLA endpoint The query must return a table of stores that have opened since December 1,2023.
How should you complete the DAX expression? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.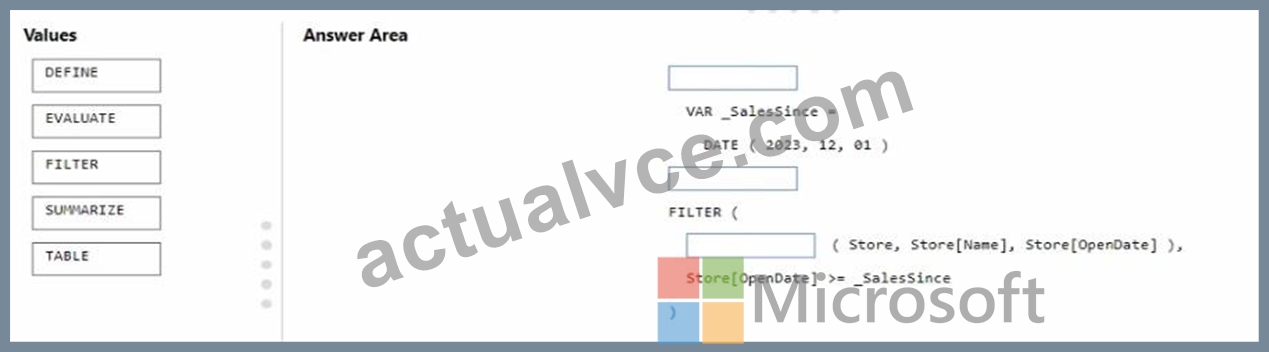
Answer:
Explanation: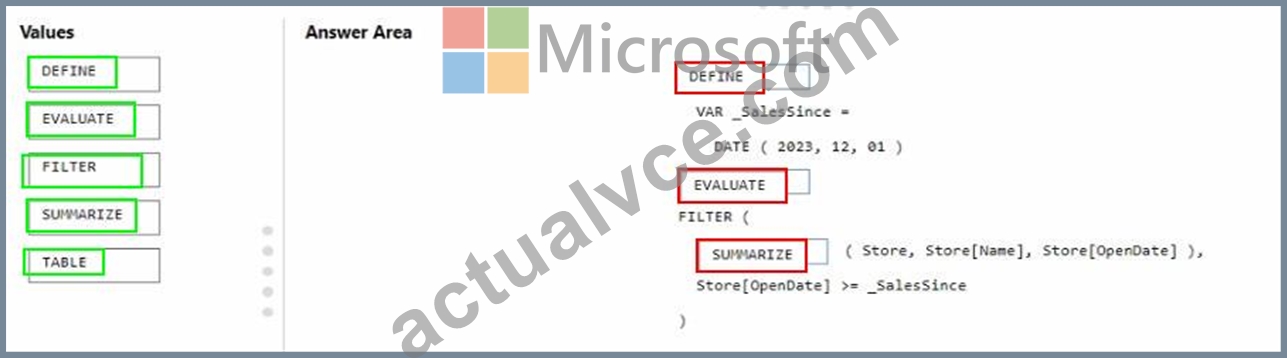
.
Reference:
DAX FILTER Function
DAX SUMMARIZE Function
NEW QUESTION # 133
You need to refresh the Orders table of the Online Sales department. The solution must meet the semantic model requirements. What should you include in the solution?
Answer: B
Explanation:
Requirement: "The number of rows added to the Orders table during refreshes must be minimized." The Orders table has a sequential OrderID.
To minimize refresh size, you must only import new rows, not the entire table.
This requires retrieving the maximum OrderID currently loaded, then only loading rows with a greater OrderID.
So, the correct solution is to use a pipeline (ADF) with a dataflow to retrieve the maximum OrderID.
The answer: C. an Azure Data Factory pipeline that executes a dataflow to retrieve the maximum value of
the OrderID column in the destination lakehouse
NEW QUESTION # 134
......
We are a certification exam dumps website that meets the needs of many IT workers who are going to participate in the Microsoft DP-600 real exam. Our colleagues will always check the updating of DP-600 practice questions and the similarity of real question is almost 100%. It will be not difficult for candidates to clear DP-600 Exam Braindumps if they are good at considering and conclude except practicing DP-600 dumps pdf.
Test DP-600 Testking: https://www.actualvce.com/Microsoft/DP-600-valid-vce-dumps.html
BTW, DOWNLOAD part of ActualVCE DP-600 dumps from Cloud Storage: https://drive.google.com/open?id=1Re-FlTJNTwtN-phG7kWHU2dUqizdW7Zs