As we always want to do better in this career, our research center has formed a group of professional experts responsible for researching new technology of the DP-750 study materials. The technology of the DP-750 practice prep will be innovated every once in a while. As you can see, we never stop innovating new version of the DP-750 Exam Questions. We really need your strong support. We always adopt the kind and useful advices of our loyal customers who wrote to us and gave us their opinions on their study.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Topic 2: Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Topic 3: Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Topic 4: Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
>> New DP-750 Test Question <<
All kinds of exams are changing with dynamic society because the requirements are changing all the time. To keep up with the newest regulations of the DP-750 exam, our experts keep their eyes focusing on it. And the DP-750 study tool can provide a good learning platform for users who want to get the test DP-750 Certification in a short time. If you can choose to trust us, I believe you will have a good experience when you use the Microsoft Certified: Fabric Data Engineer Associate study guide, and you can pass the exam and get a good grade in the test DP-750 certification.
NEW QUESTION # 89
You have an Azure Databricks workspace named Workspace1 that is attached to a Unity Catalog metastore named metastore1 You need to register an Azure Storage account named account1 that has a hierarchical namespace enabled as an external location The external location must use a managed identity to authenticate to account1 and the solution must follow the principle of least privilege.
Which three actions should you perform in sequence' To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.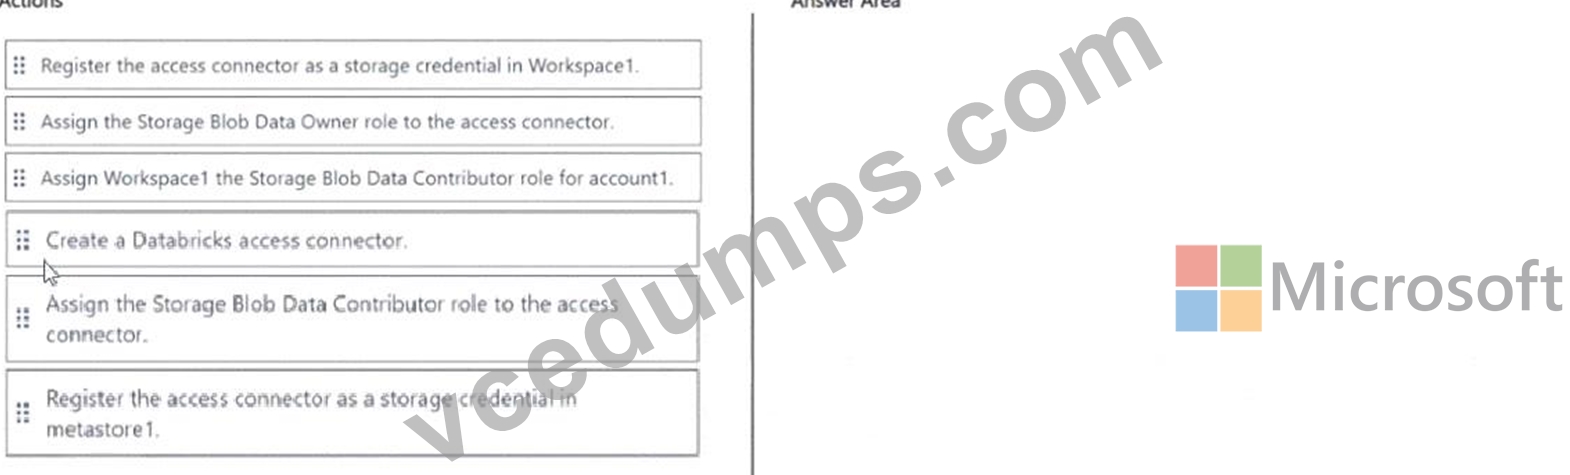
Answer:
Explanation: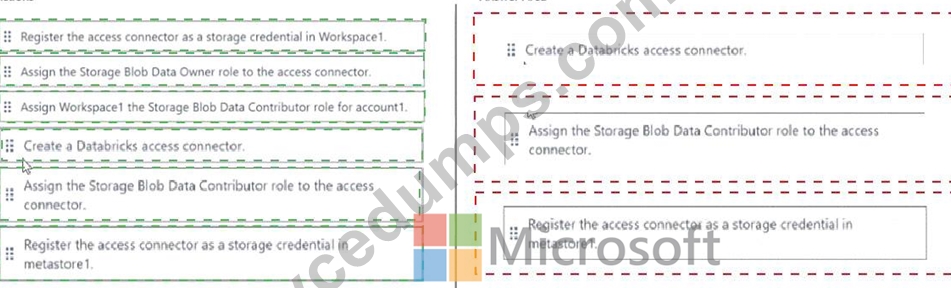
Explanation:
Registering an ADLS Gen2 account as an external location in Unity Catalog requires three steps in a specific order:
Step 1: Create a Databricks Access Connector. This Azure resource wraps a system-assigned or user-assigned managed identity. It is the credential-less authentication bridge between Databricks and Azure Storage - no SAS tokens or access keys are stored anywhere in the workspace.
Step 2: Create a Storage Credential in Unity Catalog that references the Access Connector. This object tells Unity Catalog 'use this identity when accessing storage.' The Storage Credential is the reusable authentication object.
Step 3: Create an External Location that maps a Unity Catalog path to the specific ADLS Gen2 container using the Storage Credential. This is the object that grants Databricks users access to files under that path, and it respects the principle of least privilege by scoping access to a specific container.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/storage-credentials
NEW QUESTION # 90
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named Catalog1. Catalog1 contains a table named Transactions. Transactions contains the following columns:
- transaction_id
- customer_name
- email_address
- credit_card_number
- transaction_amount
You need to ensure that business analysts can query all the rows in the Transactions table. The solution must meet the following requirements:
- Prevent the analysts from seeing the full values in the email_address and credit_card_number columns.
- Ensure that the analysts can see only the values after the @
character in each email address.
- Ensure that the analysts can see only the last four digits of each
credit card number.
- Enable the analysts to query the table without errors.
- Follow the principle of least privilege.
What should you do?
Answer: C
Explanation:
To protect sensitive customer information while allowing a specific group to run queries, use Unity Catalog's Dynamic Column Masking. This grants the group table access while applying User- Defined Functions (UDFs) to redact the email addresses and credit card numbers dynamically.
Here is the exact SQL implementation to apply:
1. Create the masking SQL UDFs
Define functions to apply the exact partial masking rules requested.
2. Apply the column masks to the tableAlter the transaction table to attach these UDFs to the respective columns.
3. Grant least privilege permissionsGrant the group the SELECT permission on the table, along with the foundational permissions to access the catalog and schema.
Reference:
https://docs.databricks.com/aws/en/data-governance/unity-catalog/filters-and-masks
NEW QUESTION # 91
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a table named Table1 by using a data quality validation rule named rule1.
You need to modify rule1 to meet the following requirements:
- Ensure that amount is always greater than 0.
- Prevent an update to Table1 from being committed when data that
violates rule1 is detected.
Which statement should you execute?
Answer: A
Explanation:
To ensure the data validation rule forces the pipeline update to abort and roll back transactions when data violates the condition, you must use a "fail" expectation operator. In Databricks Lakeflow Spark Declarative Pipelines (SDP), the command/syntax depends on whether your pipeline is written in Python or SQL.
Python Implementation
If your pipeline uses Python, apply the @dp.expect_or_fail decorator above your table definition (note: dp is the standard alias for the databricks.pipelines module in Lakeflow SDP):
dp.expect_or_fail("amount_greater_than_zero", "amount > 0")
Reference:
https://docs.databricks.com/aws/en/ldp/expectations
NEW QUESTION # 92
You have an Azure Databricks account that contains workspaces enabled for Unity Catalog.
You need to implement audit logging to meet the following requirements:
* Capture audit logs for all the workspaces in the account.
* Retain the audit logs for 90 days.
* Minimize storage and ingestion costs.
The logs will be reviewed only during security investigations and will NOT be queried regularly.
To where should you send the audit logs?
Answer: C
Explanation:
An Azure Storage account provides durable, comparatively low-cost retention for diagnostic and audit logs that are accessed infrequently. A lifecycle or retention policy can preserve the logs for 90 days and then remove them automatically. This matches an investigation-only access pattern without paying the ingestion and indexing charges associated with Log Analytics. Azure Monitor metrics stores numerical monitoring measurements, not the complete audit-event records required here. Azure Event Hubs is a streaming transport intended to forward events to consumers and is not the final long-term retention destination. Log Analytics is appropriate when teams need frequent querying, dashboards, and alerting, but those capabilities introduce unnecessary cost for logs reviewed only during occasional investigations. Storage therefore best satisfies centralized retention and cost requirements.
NEW QUESTION # 93
You have an Azure Databricks workspace that uses Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that ingests data into a managed Delta table named Table1. Table1 is used for analytics.
New columns are added to the source data, causing pipeline failures during writes to Table1.
You need to prevent the pipeline failures. The solution must ensure that schema changes are detected and handled.
What should you do?
Answer: D
Explanation:
You should enable schema evolution to resolve this problem. In Lakeflow Spark Declarative Pipelines (SDP)-formerly known as Delta Live Tables (DLT)-schema evolution automatically updates the schema of your managed Delta tables when new columns are detected in the source data.
Prevents Pipeline Failures: By default, Delta Lake applies strict schema enforcement to prevent bad or mismatched data from corrupting your tables. When the source data layout changes (e.g., column creep), the pipeline will throw a runtime error and fail the write operation.
Automates Ingestion Flexibility: Activating schema evolution allows Delta Lake to automatically adapt by adding the new columns to the target managed table layout dynamically, eliminating manual intervention or explicit ALTER TABLE operations.
Reference:
https://learn.microsoft.com/en-us/azure/databricks/ldp/unity-catalog
NEW QUESTION # 94
......
Once you have practiced and experienced the quality of our DP-750 exam preparation, you will remember the serviceability and usefulness of them. For the excellent quality of our DP-750 training questions explains why our DP-750 practice materials helped over 98 percent of exam candidates get the certificate you dream of successfully. Believe me with our DP-750 Guide quiz, you will be more confident to pass the exam in the shortest time with ease.
DP-750 Valid Test Preparation: https://www.vcedumps.com/DP-750-examcollection.html