BONUS!!! Download part of Prep4sureExam Professional-Machine-Learning-Engineer dumps for free: https://drive.google.com/open?id=1v60T1vJzYE15UQSnjCCQWHoTtZU9ywxA
The product Prep4sureExam provide with you is compiled by professionals elaborately and boosts varied versions which aimed to help you pass the Professional-Machine-Learning-Engineer exam by the method which is convenient for you. It is not only cheaper than other dumps but also more effective. The high pass rate of our Professional-Machine-Learning-Engineer Study Materials has been approved by thousands of candidates, they recognized our website as only study tool to pass Professional-Machine-Learning-Engineer exam.
Google Professional Machine Learning Engineer Exam is a certification exam offered by Google Cloud for professionals who demonstrate mastery in designing, building, and deploying scalable machine learning models. Professional-Machine-Learning-Engineer exam is designed to assess the candidate's ability to use Google Cloud's machine learning technologies to develop and deploy production-grade ML models, as well as to optimize and maintain them to ensure their reliability, accuracy, and scalability.
The Google Professional-Machine-Learning-Engineer Exam is designed to test the candidate's skills in various areas such as data preparation, feature engineering, model development, training, and deployment. Professional-Machine-Learning-Engineer exam also evaluates the candidate's ability to optimize and tune machine learning models for improved performance and scalability.
>> Professional-Machine-Learning-Engineer Dumps PDF <<
Professional-Machine-Learning-Engineer Exam is a Google certification exam and IT professionals who have passed some Google certification exams are popular in IT industry. So more and more people participate in Professional-Machine-Learning-Engineer certification exam, but Professional-Machine-Learning-Engineer certification exam is not very simple. If you do not have participated in a professional specialized training course, you need to spend a lot of time and effort to prepare for the exam. But now Prep4sureExam can help you save a lot of your precious time and energy.
Google Professional Machine Learning Engineer certification exam requires candidates to have a strong understanding of machine learning concepts such as supervised and unsupervised learning, deep learning, natural language processing, and computer vision. Professional-Machine-Learning-Engineer Exam also tests the candidate's ability to work with big data technologies such as Apache Spark, Apache Hadoop, and Google BigQuery.
NEW QUESTION # 89
You work on the data science team at a manufacturing company. You are reviewing the company's historical sales data, which has hundreds of millions of records. For your exploratory data analysis, you need to calculate descriptive statistics such as mean, median, and mode; conduct complex statistical tests for hypothesis testing; and plot variations of the features over time You want to use as much of the sales data as possible in your analyses while minimizing computational resources. What should you do?
Answer: A
Explanation:
D Use BigQuery to calculate the descriptive statistics, and use Google Data Studio to visualize the time plots. Use Vertex Al Workbench user-managed notebooks to run the statistical analyses.
Explanation:
The best option for analyzing large and complex datasets while minimizing computational resources is to use a combination of BigQuery and Vertex AI Workbench. BigQuery is a serverless, scalable, and cost-effective data warehouse that can perform fast and interactive queries on petabytes of data. BigQuery can calculate descriptive statistics such as mean, median, and mode by using SQL functions such as AVG, PERCENTILE_CONT, and MODE. Vertex AI Workbench is a managed service that provides an integrated development environment for data science and machine learning. Vertex AI Workbench allows users to create and run Jupyter notebooks on Google Cloud, and access various tools and libraries for data visualization and statistical analysis. Vertex AI Workbench can connect to BigQuery and use the results of the queries to create time plots and run statistical tests for hypothesis testing. By using BigQuery and Vertex AI Workbench, users can leverage the power and flexibility of Google Cloud to perform exploratory data analysis on large and complex datasets. Reference:
Preparing for Google Cloud Certification: Machine Learning Engineer, Course 2: Data Engineering for ML on Google Cloud, Week 1: Introduction to Data Engineering for ML Google Cloud Professional Machine Learning Engineer Exam Guide, Section 1: Architecting low-code ML solutions, 1.1 Developing ML models by using BigQuery ML Official Google Cloud Certified Professional Machine Learning Engineer Study Guide, Chapter 3: Data Engineering for ML, Section 3.2: BigQuery for ML
NEW QUESTION # 90
You recently joined a machine learning team that will soon release a new project. As a lead on the project, you are asked to determine the production readiness of the ML components. The team has already tested features and data, model development, and infrastructure. Which additional readiness check should you recommend to the team?
Answer: B
Explanation:
https://static.googleusercontent.com/media/research.google.com/en//pubs/archive/aad9f93b86b7addfea4c419b9100c6cdd26cacea.pdf
NEW QUESTION # 91
You are an ML engineer responsible for designing and implementing training pipelines for ML models. You need to create an end-to-end training pipeline for a TensorFlow model. The TensorFlow model will be trained on several terabytes of structured data. You need the pipeline to include data quality checks before training and model quality checks after training but prior to deployment. You want to minimize development time and the need for infrastructure maintenance. How should you build and orchestrate your training pipeline?
Answer: B
Explanation:
The best option for creating and orchestrating an end-to-end training pipeline for a TensorFlow model is to use TensorFlow Extended (TFX) and standard TFX components, and deploy the pipeline to Vertex AI Pipelines. TFX is an end-to-end platform for deploying production ML pipelines, which consists of several built-in components that cover the entire ML lifecycle, from data ingestion and validation, to model training and evaluation, to model deployment and monitoring. TFX also supports custom components and integrations with other Google Cloud services, such as BigQuery, Dataflow, and Cloud Storage. Vertex AI Pipelines is a fully managed service that allows you to run TFX pipelines on Google Cloud, without having to worry about infrastructure provisioning, scaling, or maintenance. Vertex AI Pipelines also provides a user-friendly interface to monitor and manage your pipelines, as well as tools to track and compare experiments. The other options are not as suitable for creating and orchestrating an end-to-end training pipeline for a TensorFlow model, because:
* Creating the pipeline using Kubeflow Pipelines domain-specific language (DSL) and predefined Google Cloud components would require more development time and effort, as Kubeflow Pipelines DSL is not as expressive or compatible with TensorFlow as TFX. Predefined Google Cloud components might not cover all the stages of the ML lifecycle, and might not be optimized for TensorFlow models.
* Orchestrating the pipeline using Kubeflow Pipelines deployed on Google Kubernetes Engine would require more infrastructure maintenance, as Kubeflow Pipelines is not a fully managed service, and you would have to provision and manage your own Kubernetes cluster. This would also incur more costs, as
* you would have to pay for the cluster resources, regardless of the pipeline usage. References:
* TFX | ML Production Pipelines | TensorFlow
* Vertex AI Pipelines | Google Cloud
* Kubeflow Pipelines | Google Cloud
* Google Cloud launches machine learning engineer certification
* Google Professional Machine Learning Engineer Certification
* Professional ML Engineer Exam Guide
NEW QUESTION # 92
You are going to train a DNN regression model with Keras APIs using this code: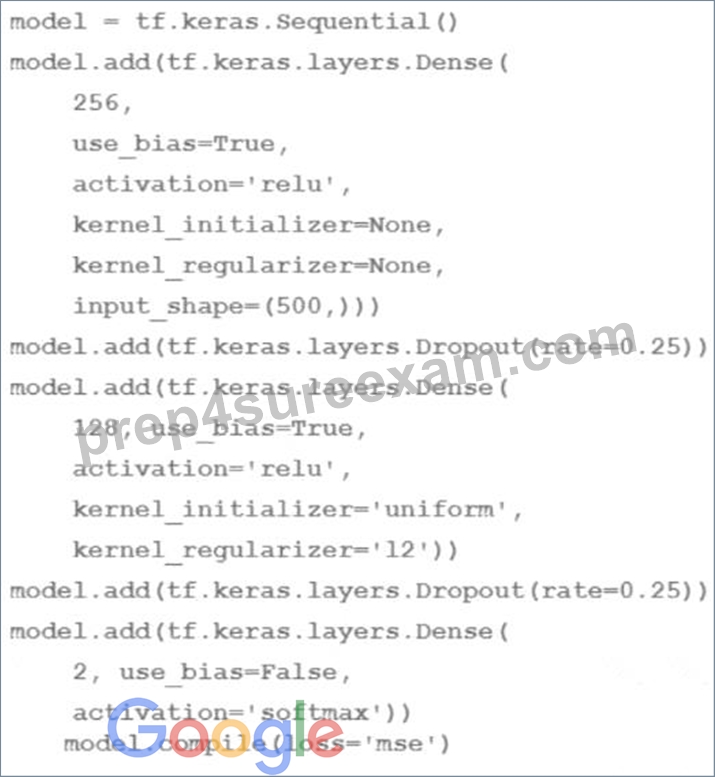
How many trainable weights does your model have? (The arithmetic below is correct.)
Answer: D
Explanation:
The number of trainable weights in a DNN regression model with Keras APIs can be calculated by multiplying the number of input units by the number of output units for each layer, and adding the number of bias units for each layer. The bias units are usually equal to the number of output units,except for the last layer, which does not have bias units if the activation function is softmax1. In this code, the model has three layers: a dense layer with 256 units and relu activation, a dropout layer with 0.25 rate, and a dense layer with 2 units and softmax activation. The input shape is 500. Therefore, the number of trainable weights is:
* For the first layer: 500 input units * 256 output units + 256 bias units = 128256
* For the second layer: The dropout layer does not have any trainable weights, as it only randomly sets some of the input units to zero to prevent overfitting2.
* For the third layer: 256 input units * 2 output units + 0 bias units = 512 The total number of trainable weights is 128256 + 512 = 161024. Therefore, the correct answer is B.
References:
* How to calculate the number of parameters for a Convolutional Neural Network?
* Dropout (keras.io)
NEW QUESTION # 93
You developed a custom model by using Vertex Al to forecast the sales of your company s products based on historical transactional data You anticipate changes in the feature distributions and the correlations between the features in the near future You also expect to receive a large volume of prediction requests You plan to use Vertex Al Model Monitoring for drift detection and you want to minimize the cost. What should you do?
Answer: B
Explanation:
The best option for using Vertex AI Model Monitoring for drift detection and minimizing the cost is to use the features and the feature attributions for monitoring, and set a prediction-sampling-rate value that is closer to 0 than 1. This option allows you to leverage the power and flexibility of Google Cloud to detect feature drift in the input predict requests for custom models, and reduce the storage and computation costs of the model monitoring job. Vertex AI Model Monitoring is a service that can track and compare the results of multiple machine learning runs. Vertex AI Model Monitoring can monitor the model's prediction input data for feature skew and drift. Feature drift occurs when the feature data distribution in production changes over time. If the original training data is not available, you can enable drift detection to monitor your models for feature drift. Vertex AI Model Monitoring uses TensorFlow Data Validation (TFDV) to calculate the distributions and distance scores for each feature, and compares them with a baseline distribution. The baseline distribution is the statistical distribution of the feature's values in the training data. If the training data is not available, the baseline distribution is calculated from the first 1000 prediction requests that the model receives. If the distance score for a feature exceeds an alerting threshold that you set, Vertex AI Model Monitoring sends you an email alert. However, if you use a custom model, you can also enable feature attribution monitoring, which can provide more insights into the feature drift. Feature attribution monitoring analyzes the feature attributions, which are the contributions of each feature to the prediction output. Feature attribution monitoring can help you identify the features that have the most impact on the model performance, and the features that have the most significant drift over time. Feature attribution monitoring can also help you understand the relationship between the features and the prediction output, and the correlation between the features1. The prediction-sampling-rate is a parameter that determines the percentage of prediction requests that are logged and analyzed by the model monitoring job. Using a lower prediction-sampling-rate can reduce the storage and computation costs of the model monitoring job, but also the quality and validity of the data. Using a lower prediction-sampling-rate can introduce sampling bias and noise into the data, and make the model monitoring job miss some important features or patterns of the data. However, using a higher prediction-sampling-rate can increase the storage and computation costs of the model monitoring job, and also the amount of data that needs to be processed and analyzed. Therefore, there is a trade-off between the prediction-sampling-rate and the cost and accuracy of the model monitoring job, and the optimal prediction-sampling-rate depends on the business objective and the data characteristics2. By using the features and the feature attributions for monitoring, and setting a prediction-sampling-rate value that is closer to 0 than 1, you can use Vertex AI Model Monitoring for drift detection and minimize the cost.
The other options are not as good as option D, for the following reasons:
Option A: Using the features for monitoring and setting a monitoring-frequency value that is higher than the default would not enable feature attribution monitoring, and could increase the cost of the model monitoring job. The monitoring-frequency is a parameter that determines how often the model monitoring job analyzes the logged prediction requests and calculates the distributions and distance scores for each feature. Using a higher monitoring-frequency can increase the frequency and timeliness of the model monitoring job, but also the computation costs of the model monitoring job. Moreover, using the features for monitoring would not enable feature attribution monitoring, which can provide more insights into the feature drift and the model performance1.
Option B: Using the features for monitoring and setting a prediction-sampling-rate value that is closer to 1 than 0 would not enable feature attribution monitoring, and could increase the cost of the model monitoring job. The prediction-sampling-rate is a parameter that determines the percentage of prediction requests that are logged and analyzed by the model monitoring job. Using a higher prediction-sampling-rate can increase the quality and validity of the data, but also the storage and computation costs of the model monitoring job. Moreover, using the features for monitoring would not enable feature attribution monitoring, which can provide more insights into the feature drift and the model performance12.
Option C: Using the features and the feature attributions for monitoring and setting a monitoring-frequency value that is lower than the default would enable feature attribution monitoring, but could reduce the frequency and timeliness of the model monitoring job. The monitoring-frequency is a parameter that determines how often the model monitoring job analyzes the logged prediction requests and calculates the distributions and distance scores for each feature. Using a lower monitoring-frequency can reduce the computation costs of the model monitoring job, but also the frequency and timeliness of the model monitoring job. This can make the model monitoring job less responsive and effective in detecting and alerting the feature drift1.
Reference:
Preparing for Google Cloud Certification: Machine Learning Engineer, Course 3: Production ML Systems, Week 4: Evaluation Google Cloud Professional Machine Learning Engineer Exam Guide, Section 3: Scaling ML models in production, 3.3 Monitoring ML models in production Official Google Cloud Certified Professional Machine Learning Engineer Study Guide, Chapter 6: Production ML Systems, Section 6.3: Monitoring ML Models Using Model Monitoring Understanding the score threshold slider
NEW QUESTION # 94
......
Testking Professional-Machine-Learning-Engineer Exam Questions: https://www.prep4sureexam.com/Professional-Machine-Learning-Engineer-dumps-torrent.html
BTW, DOWNLOAD part of Prep4sureExam Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1v60T1vJzYE15UQSnjCCQWHoTtZU9ywxA