Seeing The Exam Dumps Databricks-Certified-Data-Engineer-Professional Collection, Passed Half of Databricks Certified Data Engineer Professional Exam

2026 Latest Dumpleader Databricks-Certified-Data-Engineer-Professional PDF Dumps and Databricks-Certified-Data-Engineer-Professional Exam Engine Free Share: https://drive.google.com/open?id=1YHkOOZ-xZATcfuKsphCU-lAKSjiIeurE
Our Databricks-Certified-Data-Engineer-Professional learning materials can help you dream come true. A surprising percentage of exam candidates are competing for the certificate of the Databricks-Certified-Data-Engineer-Professional exam in recent years. Each man is the architect of his own fate. So you need speed up your pace with the help of our Databricks-Certified-Data-Engineer-Professional Guide prep which owns the high pass rate as 98% to 100% to give you success guarantee and considered the most effective Databricks-Certified-Data-Engineer-Professional exam braindumps in the market.
| Section | Objectives |
|---|
| Delta Lake and Data Management | - Schema evolution and enforcement
- Delta Lake transactions and ACID properties
- Time travel and versioning
|
| Databricks Lakehouse Platform Architecture | - Workspace and cluster architecture
- Data governance concepts (Unity Catalog basics)
- Medallion architecture (Bronze, Silver, Gold)
|
| Production Pipelines and Orchestration | - Error handling and recovery strategies
- Databricks Workflows
- Job scheduling and monitoring
|
| Data Modeling and Transformation | - Performance optimization techniques
- Spark SQL transformations
- Dimensional modeling concepts
|
| Data Ingestion and Processing | - Structured Streaming fundamentals
- ETL pipeline design patterns
- Batch and streaming ingestion with Auto Loader
|
>> Exam Dumps Databricks-Certified-Data-Engineer-Professional Collection <<
New Databricks-Certified-Data-Engineer-Professional Test Syllabus & Databricks-Certified-Data-Engineer-Professional Valid Test Pdf
First and foremost, our company has prepared Databricks-Certified-Data-Engineer-Professional free demo in this website for our customers. Second, it is convenient for you to read and make notes with our PDF version. Last but not least, we will provide considerate on line after sale service for you in twenty four hours a day, seven days a week. So let our Databricks-Certified-Data-Engineer-Professional practice materials to be your learning partner in the course of preparing for the exam, especially the PDF version is really a wise choice for you.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q62-Q67):
NEW QUESTION # 62
A Structured Streaming job deployed to production has been experiencing delays during peak hours of the day. At present, during normal execution, each microbatch of data is processed in less than 3 seconds. During peak hours of the day, execution time for each microbatch becomes very inconsistent, sometimes exceeding 30 seconds. The streaming write is currently configured with a trigger interval of 10 seconds.
Holding all other variables constant and assuming records need to be processed in less than 10 seconds, which adjustment will meet the requirement?
- A. Decrease the trigger interval to 5 seconds; triggering batches more frequently may prevent records from backing up and large batches from causing spill.
- B. The trigger interval cannot be modified without modifying the checkpoint directory; to maintain the current stream state, increase the number of shuffle partitions to maximize parallelism.
- C. Increase the trigger interval to 30 seconds; setting the trigger interval near the maximum execution time observed for each batch is always best practice to ensure no records are dropped.
- D. Use the trigger once option and configure a Databricks job to execute the query every 10 seconds; this ensures all backlogged records are processed with each batch.
- E. Decrease the trigger interval to 5 seconds; triggering batches more frequently allows idle executors to begin processing the next batch while longer running tasks from previous batches finish.
Answer: A
Explanation:
The adjustment that will meet the requirement of processing records in less than 10 seconds is to decrease the trigger interval to 5 seconds. This is because triggering batches more frequently may prevent records from backing up and large batches from causing spill. Spill is a phenomenon where the data in memory exceeds the available capacity and has to be written to disk, which can slow down the processing and increase the execution time. By reducing the trigger interval, the streaming query can process smaller batches of data more quickly and avoid spill. This can also improve the latency and throughput of the streaming job.
NEW QUESTION # 63
A data engineer is configuring a Lakeflow Declarative Pipeline to process CDC (Change Data Capture) data from a source. The source events sometimes arrive out of order, and multiple updates may occur with the same update_timestamp but with different update_sequence_id.
What should the data engineer do to ensure events are sequenced correctly?
- A. Set track_history_column_list to [event_timestamp, event_id] in AUTO CDC APIs.
- B. Use dropDuplicates() to remove out-of-order and duplicate records in LDP.
- C. Use SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) in AUTO CDC APIs.
- D. Use a window function to sort update_sequence_id within the same partition, i.e., update_timestamp in the LDP pipeline.
Answer: C
Explanation:
When handling CDC data, sequencing is critical because updates may arrive out of order or multiple changes may occur for the same record at the same timestamp. Databricks' AUTO CDC APIs provide built-in constructs to handle ordering logic.
The correct mechanism is to use the SEQUENCE BY clause in the CDC configuration.
Specifically, when both update_timestamp and update_sequence_id exist, the recommended approach is:
SEQUENCE BY STRUCT(event_timestamp, update_sequence_id)
This ensures that within the same record key, the engine applies updates in the exact sequence they occurred, resolving conflicts where multiple updates share the same timestamp but differ in sequence ID.
Option A (track_history_column_list) is used for historical tracking and auditing changes, not for sequencing logic. It ensures lineage but does not enforce correct event order.
Option B (dropDuplicates()) only removes exact duplicates; it cannot guarantee sequencing correctness when multiple updates exist.
Option C is correct: SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) explicitly enforces ordering, as recommended by the CDC pipeline guidelines.
Option D (window function) would be a manual approach in Spark Structured Streaming, but Lakeflow Declarative Pipelines already provide native CDC sequencing support, making this unnecessary.
Thus, the best practice per Databricks CDC documentation is to use Option C with SEQUENCE BY STRUCT.
NEW QUESTION # 64
A data engineer is designing a secure data sharing strategy for their organization. The company needs to share sensitive customer analytics data with two different partners. Partner A uses Databricks with Unity Catalog enabled, while Partner B uses Apache Spark on AWS without Databricks. How should the company implement secure data sharing for these scenarios?
- A. Databricks-to-Databricks sharing (D2D) can only be used within the same cloud provider, so you must use open sharing (D2O) for any cross-cloud scenarios. Unit Catalog governance is not available when sharing with external platforms.
- B. For Partner A, implement Databricks-to-Databricks sharing (D2D) with Unit Catalog integration and no-token exchange system. For Partner B, use open sharing protocol (D2O) with either bearer tokens or OIDC federation for authentication, ensuring both approaches maintain robust security and governance.
- C. Open sharing protocol (D2O) should be used for both partners because it provides better security than D2D sharing. The bearer token approach is always more secure than Unity Catalog's native authentication.
- D. Both partners should use the same Delta Sharing approach since security requirements are identical. You should create bearer tokens for both partners and use the open sharing protocol (D2O) for maximum compatibility.
Answer: B
Explanation:
Databricks-to-Databricks sharing with Unity Catalog provides the most seamless and secure option for Partner A by enabling native governance, fine-grained access controls, and a no-token exchange model. For Partner B, which does not use Databricks, the open sharing protocol enables secure access from external Spark environments using standard authentication mechanisms such as bearer tokens or OIDC federation, while still enforcing sharing policies and protecting sensitive data.
NEW QUESTION # 65
A nightly job ingests data into a Delta Lake table using the following code:
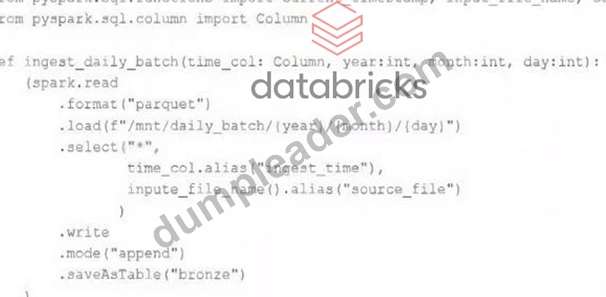
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
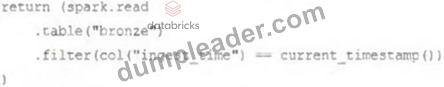
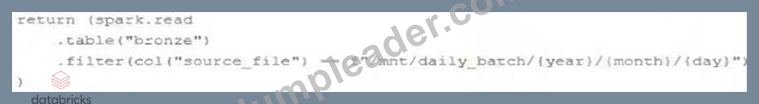
Which code snippet completes this function definition?
def new_records():
- A.
- B. return spark.readStream.load("bronze")
- C.
- D. return spark.readStream.table("bronze")
- E. return spark.read.option("readChangeFeed", "true").table ("bronze")
Answer: C
Explanation:
https://docs.databricks.com/en/delta/delta-change-data-feed.html
NEW QUESTION # 66
An upstream source writes Parquet data as hourly batches to directories named with the current date. A nightly batch job runs the following code to ingest all data from the previous day as indicated by the date variable:
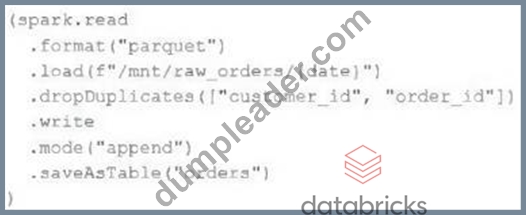
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order.
If the upstream system is known to occasionally produce duplicate entries for a single order hours apart, which statement is correct?
- A. Each write to the orders table will only contain unique records, but newly written records may have duplicates already present in the target table.
- B. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, these records will be overwritten.
- C. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, the operation will tail.
- D. Each write to the orders table will run deduplication over the union of new and existing records, ensuring no duplicate records are present.
- E. Each write to the orders table will only contain unique records, and only those records without duplicates in the target table will be written.
Answer: A
Explanation:
This is the correct answer because the code uses the dropDuplicates method to remove any duplicate records within each batch of data before writing to the orders table. However, this method does not check for duplicates across different batches or in the target table, so it is possible that newly written records may have duplicates already present in the target table. To avoid this, a better approach would be to use Delta Lake and perform an upsert operation using mergeInto.
NEW QUESTION # 67
......
Challenge is omnipresent like everywhere. By eliciting all necessary and important points into our Databricks-Certified-Data-Engineer-Professional practice materials, their quality and accuracy have been improved increasingly, so their quality is trustworthy and unquestionable. There is a bunch of considerate help we are willing to offer. Besides, according to various predispositions of exam candidates, we made three versions for your reference. Untenable materials may waste your time and energy during preparation process.
New Databricks-Certified-Data-Engineer-Professional Test Syllabus: https://www.dumpleader.com/Databricks-Certified-Data-Engineer-Professional_exam.html
- Realistic Databricks Exam Dumps Databricks-Certified-Data-Engineer-Professional Collection 🌴 The page for free download of “ Databricks-Certified-Data-Engineer-Professional ” on ☀ www.troytecdumps.com ️☀️ will open immediately 🥛Databricks-Certified-Data-Engineer-Professional Practice Online
- Valid Databricks-Certified-Data-Engineer-Professional - Exam Dumps Databricks Certified Data Engineer Professional Exam Collection 🦄 「 www.pdfvce.com 」 is best website to obtain ▶ Databricks-Certified-Data-Engineer-Professional ◀ for free download 😩Databricks-Certified-Data-Engineer-Professional Practice Online
- Databricks-Certified-Data-Engineer-Professional Guide 🍱 Study Databricks-Certified-Data-Engineer-Professional Dumps 👈 Databricks-Certified-Data-Engineer-Professional Practice Online 🎰 The page for free download of ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ on [ www.easy4engine.com ] will open immediately 🤜Databricks-Certified-Data-Engineer-Professional Reliable Dumps Files
- Pdfvce Dumps Save Your Money with Up to one year of Free Updates 🌿 Easily obtain free download of ➽ Databricks-Certified-Data-Engineer-Professional 🢪 by searching on ➥ www.pdfvce.com 🡄 🛩Authentic Databricks-Certified-Data-Engineer-Professional Exam Questions
- Databricks-Certified-Data-Engineer-Professional Latest Learning Material 🚟 Valid Databricks-Certified-Data-Engineer-Professional Real Test 🍪 Databricks-Certified-Data-Engineer-Professional Practice Online 👣 Open ➡ www.dumpsmaterials.com ️⬅️ and search for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ to download exam materials for free 📸Databricks-Certified-Data-Engineer-Professional Latest Learning Material
- Databricks-Certified-Data-Engineer-Professional examkiller valid study dumps - Databricks-Certified-Data-Engineer-Professional exam review torrents 🥗 The page for free download of ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ on ➠ www.pdfvce.com 🠰 will open immediately 🔷Online Databricks-Certified-Data-Engineer-Professional Bootcamps
- Valid Databricks-Certified-Data-Engineer-Professional Real Test 🖖 Exam Databricks-Certified-Data-Engineer-Professional Dump 👋 Latest Braindumps Databricks-Certified-Data-Engineer-Professional Ppt 🧑 Simply search for ▛ Databricks-Certified-Data-Engineer-Professional ▟ for free download on ➽ www.exam4labs.com 🢪 🥺Databricks-Certified-Data-Engineer-Professional Latest Learning Material
- Databricks-Certified-Data-Engineer-Professional Exam Demo 🍰 Databricks-Certified-Data-Engineer-Professional Reliable Dumps Files 🦑 Exam Databricks-Certified-Data-Engineer-Professional Dump 🌲 Open website “ www.pdfvce.com ” and search for ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ for free download 🥄Authentic Databricks-Certified-Data-Engineer-Professional Exam Questions
- Realistic Databricks Exam Dumps Databricks-Certified-Data-Engineer-Professional Collection 😱 Open ➽ www.prepawaypdf.com 🢪 enter 「 Databricks-Certified-Data-Engineer-Professional 」 and obtain a free download 🚵Databricks-Certified-Data-Engineer-Professional Practice Online
- 100% Pass 2026 Databricks Accurate Databricks-Certified-Data-Engineer-Professional: Exam Dumps Databricks Certified Data Engineer Professional Exam Collection 🥖 Search for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ on ✔ www.pdfvce.com ️✔️ immediately to obtain a free download 🤜Study Databricks-Certified-Data-Engineer-Professional Dumps
- Databricks-Certified-Data-Engineer-Professional Dumps Materials - Databricks-Certified-Data-Engineer-Professional Exam Braindumps - Databricks-Certified-Data-Engineer-Professional Real Questions 🆑 Search for ▛ Databricks-Certified-Data-Engineer-Professional ▟ and obtain a free download on { www.torrentvce.com } ✉Databricks-Certified-Data-Engineer-Professional Accurate Answers
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
What's more, part of that Dumpleader Databricks-Certified-Data-Engineer-Professional dumps now are free: https://drive.google.com/open?id=1YHkOOZ-xZATcfuKsphCU-lAKSjiIeurE