DOWNLOAD the newest DumpStillValid DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1NiPKL6BuvuF8wTma_FUbDhteNq2f4Ry9
Our system will accurately help you analyze the exercises of the DP-100 study materials. So you need not to summarize by yourself. Then you will clearly know where you are good at and where your do badly. Flexible adjustment to your revision of the DP-100 Real Exam is essential to pass the exam. You can make decisions after careful consideration. It is up to you to make a decision. And after you finish the DP-100 exam questions, the scores will show out right away.
Microsoft DP-100 (Designing and Implementing a Data Science Solution on Azure) Certification Exam is a popular certification exam designed to test the skills and knowledge of data professionals in designing and implementing data science solutions on the Microsoft Azure platform. DP-100 exam is ideal for data scientists, data analysts, and other professionals who want to demonstrate their expertise in working with data on the Azure platform.
| Topic | Details |
|---|---|
Manage Azure resources for machine learning (25-30%) | |
| Create an Azure Machine Learning workspace | - create an Azure Machine Learning workspace - configure workspace settings - manage a workspace by using Azure Machine Learning studio |
| Manage data in an Azure Machine Learning workspace | - select Azure storage resources - register and maintain datastores - create and manage datasets |
| Manage compute for experiments in Azure Machine Learning | - determine the appropriate compute specifications for a training workload - create compute targets for experiments and training - configure Attached Compute resources including Azure Databricks - monitor compute utilization |
| Implement security and access control in Azure Machine Learning | - determine access requirements and map requirements to built-in roles - create custom roles - manage role membership - manage credentials by using Azure Key Vault |
| Set up an Azure Machine Learning development environment | - create compute instances - share compute instances - access Azure Machine Learning workspaces from other development environments |
| Set up an Azure Databricks workspace | - create an Azure Databricks workspace - create an Azure Databricks cluster - create and run notebooks in Azure Databricks - link and Azure Databricks workspace to an Azure Machine Learning workspace |
Run Experiments and Train Models (20-25%) | |
| Create models by using the Azure Machine Learning Designer | - create a training pipeline by using Azure Machine Learning designer - ingest data in a designer pipeline - use designer modules to define a pipeline data flow - use custom code modules in designer |
| Run model training scripts | - create and run an experiment by using the Azure Machine Learning SDK - configure run settings for a script - consume data from a dataset in an experiment by using the Azure Machine Learning SDK - run a training script on Azure Databricks compute - run code to train a model in an Azure Databricks notebook |
| Generate metrics from an experiment run | - log metrics from an experiment run - retrieve and view experiment outputs - use logs to troubleshoot experiment run errors - use MLflow to track experiments - track experiments running in Azure Databricks |
| Use Automated Machine Learning to create optimal models | - use the Automated ML interface in Azure Machine Learning studio - use Automated ML from the Azure Machine Learning SDK - select pre-processing options - select the algorithms to be searched - define a primary metric - get data for an Automated ML run - retrieve the best model |
| Tune hyperparameters with Azure Machine Learning | - select a sampling method - define the search space - define the primary metric - define early termination options - find the model that has optimal hyperparameter values |
Deploy and operationalize machine learning solutions (35-40%) | |
| Select compute for model deployment | - consider security for deployed services - evaluate compute options for deployment |
| Deploy a model as a service | - configure deployment settings - deploy a registered model - deploy a model trained in Azure Databricks to an Azure Machine Learning endpoint - consume a deployed service - troubleshoot deployment container issues |
| Manage models in Azure Machine Learning | - register a trained model - monitor model usage - monitor data drift |
| Create an Azure Machine Learning pipeline for batch inferencing | - configure a ParallelRunStep - configure compute for a batch inferencing pipeline - publish a batch inferencing pipeline - run a batch inferencing pipeline and obtain outputs - obtain outputs from a ParallelRunStep |
| Publish an Azure Machine Learning designer pipeline as a web service | - create a target compute resource - configure an Inference pipeline - consume a deployed endpoint |
| Implement pipelines by using the Azure Machine Learning SDK | - create a pipeline - pass data between steps in a pipeline - run a pipeline - monitor pipeline runs |
>> DP-100 Practice Test Engine <<
Download the free DP-100 pdf demo file of DumpStillValid brain dumps. Checking the worth of the DP-100 exam questions and learns the format of questions and answers. A few moments are enough to introduce you to the excellent of the DP-100 Brain Dumps and the authenticity and relevance of the information contained in them.
Microsoft DP-100 certification exam is designed to test the skills of data professionals who want to design and implement data science solutions on the Azure platform. DP-100 exam is intended for individuals who have experience working with Azure data services and are familiar with data science concepts and techniques. DP-100 Exam covers a wide range of topics, including data exploration and preparation, modeling, deployment, and monitoring.
NEW QUESTION # 146
You create a multi-class image classification deep learning model.
The model must be retrained monthly with the new image data fetched from a public web portal. You create an Azure Machine Learning pipeline to fetch new data, standardize the size of images and retrain the model.
You need to use the Azure Machine Learning Python SEX v2 to configure the schedule for the pipeline. The schedule should be defined by using the frequency and interval properties with frequency set to month' and interval set to "1:
Which three classes should you instantiate in sequence"' To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.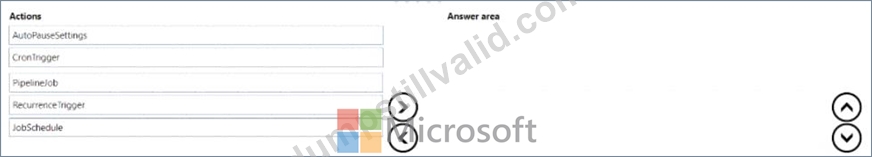
Answer:
Explanation: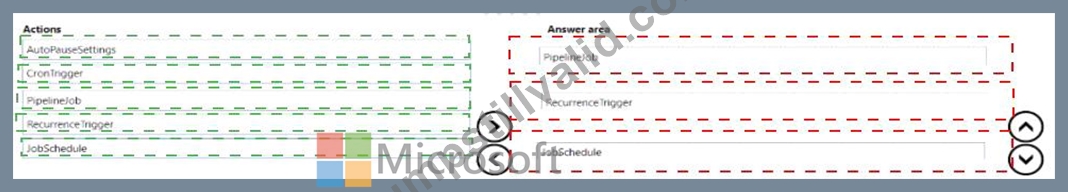
Explanation: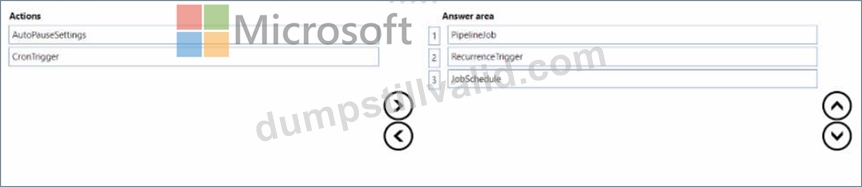
NEW QUESTION # 147
You use Azure Machine Learning to implement hyperparameter tuning with a Bandit early termination policy.
The policy uses a slack_factor set to 01. an evaluation interval set to 1, and an evaluation delay set to b.
You need to evaluate the outcome of the early termination policy
What should you evaluate? To answer, select the appropriate options m the answer area.
NOTE: Each correct selection is worth one point.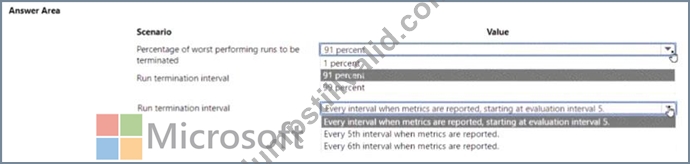
Answer:
Explanation: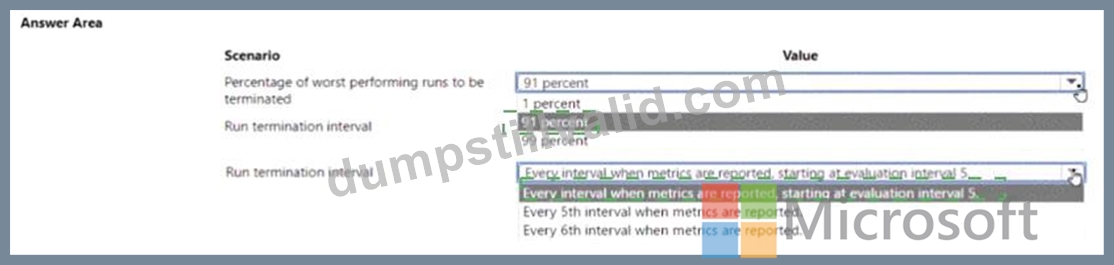
Explanation: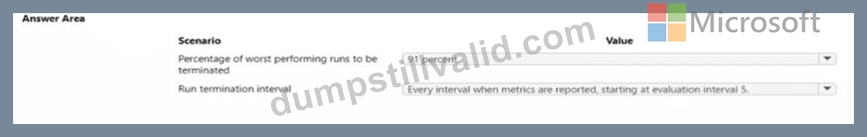
NEW QUESTION # 148
You manage are Azure Machine Learning workspace by using the Python SDK v2.
You must create an automated machine learning job to generate a classification model by using data files stored in Parquet format. You must configure an auto scaling compute target and a data asset for the job.
You need to configure the resources for the job.
Which resource configuration should you use? to answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.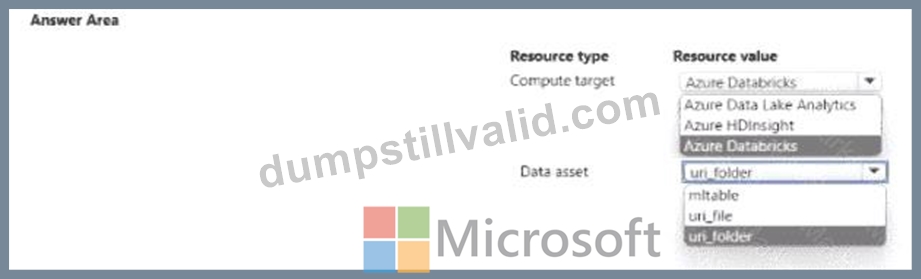
Answer:
Explanation: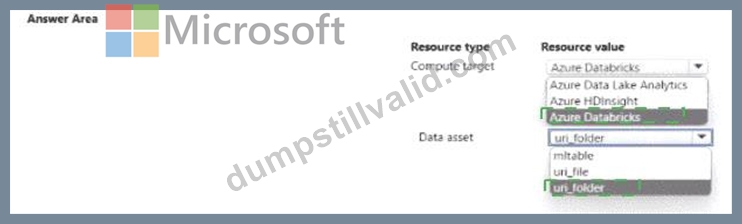
Explanation: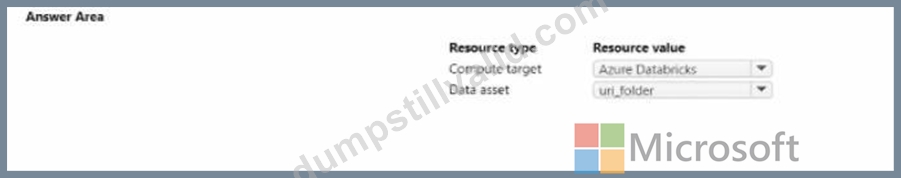
NEW QUESTION # 149
You plan to implement a two-step pipeline by using the Azure Machine Learning SDK for Python.
The pipeline will pass temporary data from the first step to the second step.
You need to identify the class and the corresponding method that should be used in the second step to access temporary data generated by the first step in the pipeline.
Which class and method should you identify? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point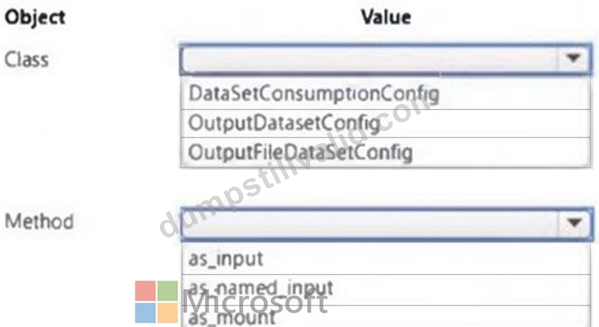
Answer:
Explanation: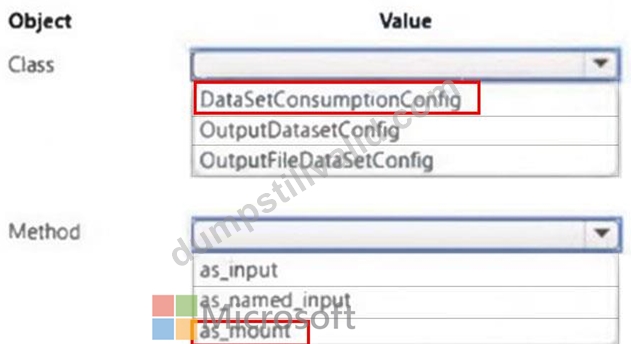
NEW QUESTION # 150
You create a training pipeline using the Azure Machine Learning designer. You upload a CSV file that contains the data from which you want to train your model.
You need to use the designer to create a pipeline that includes steps to perform the following tasks:
* Select the training features using the pandas filter method.
* Train a model based on the naive_bayes.GaussianNB algorithm.
* Return only the Scored Labels column by using the query SELECT [Scored Labels] FROM t1; Which modules should you use? To answer, drag the appropriate modules to the appropriate locations. Each module name may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.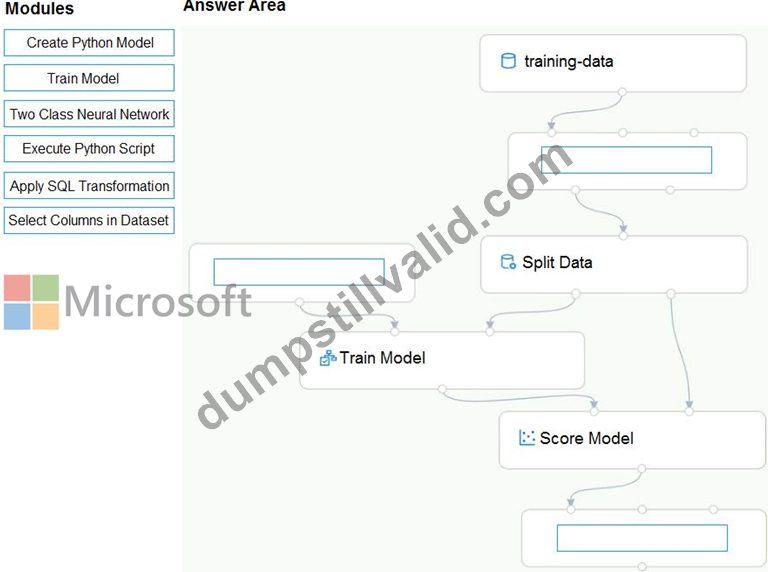
Answer:
Explanation: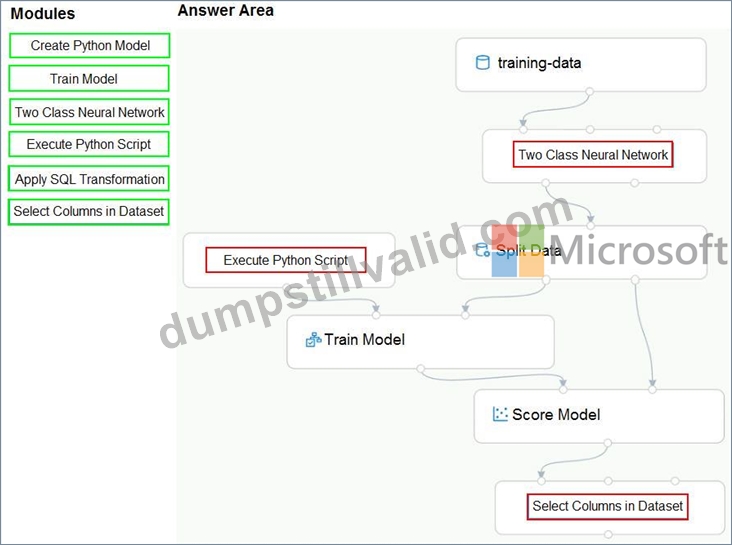
NEW QUESTION # 151
......
DP-100 Valid Test Review: https://www.dumpstillvalid.com/DP-100-prep4sure-review.html
BTW, DOWNLOAD part of DumpStillValid DP-100 dumps from Cloud Storage: https://drive.google.com/open?id=1NiPKL6BuvuF8wTma_FUbDhteNq2f4Ry9