Databricks training pdf material is the valid tools which can help you prepare for the Databricks-Certified-Professional-Data-Engineer actual test. Databricks-Certified-Professional-Data-Engineer vce demo gives you the prep hints and important tips, helping you identify areas of weakness and improve both your conceptual knowledge and hands-on skills. With the help of Databricks-Certified-Professional-Data-Engineer study material, you will master the concepts and techniques that ensure you exam success. What’s more, you can receive Databricks-Certified-Professional-Data-Engineer updated study material within one year after purchase. Besides, you can rest assured to enjoy the secure shopping for Databricks exam dumps on our site, and your personal information will be protected by our policy.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Transformation, Cleansing, and Quality | 10% | - Standardization and normalization - Data validation and quality checks - Handling missing or inconsistent data |
| Topic 2: Data Ingestion & Acquisition | 7% | - Schema inference and evolution - Connecting to diverse data sources - Auto Loader and streaming ingestion |
| Topic 3: Debugging and Deploying | 10% | - Deployment using bundles, CLI, and APIs - Troubleshooting pipelines and errors - CI/CD and DevOps practices |
| Topic 4: Data Modelling | 6% | - Medallion Architecture implementation - Delta Lake table design - Schema design and management |
| Topic 5: Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
| Topic 6: Data Governance | 7% | - Policy enforcement - Data lineage and metadata tracking - Unity Catalog management |
| Topic 7: Ensuring Data Security and Compliance | 10% | - Compliance standards implementation - Data encryption and masking - Access control and permissions |
| Topic 8: Monitoring and Alerting | 10% | - Setting up alerts and notifications - Performance and health monitoring - Pipeline observability and logging |
| Topic 9: Developing Code for Data Processing using Python and SQL | 22% | - Data transformation and aggregation - Batch and incremental processing logic - Integration with Databricks APIs and tools |
| Topic 10: Cost & Performance Optimisation | 13% | - Query optimization and caching - Storage optimization (partitioning, Z-order, indexing) - Cluster configuration and scaling |
>> Databricks-Certified-Professional-Data-Engineer Latest Dumps Book <<
We have compiled the Databricks-Certified-Professional-Data-Engineer test guide for these candidates who are trouble in this exam, in order help they pass it easily, and we deeply believe that our Databricks-Certified-Professional-Data-Engineer exam questions can help you solve your problem. Believe it or not, if you buy our study materials and take it seriously consideration, we can promise that you will easily get the certification that you have always dreamed of. We believe that you will never regret to buy and practice our Databricks-Certified-Professional-Data-Engineer latest question.
NEW QUESTION # 185
Which of the following tool provides Data Access control, Access Audit, Data Lineage, and Data discovery?
Answer: B
NEW QUESTION # 186
Review the following error traceback:
Which statement describes the error being raised?
Answer: D
Explanation:
The error being raised is an AnalysisException, which is a type of exception that occurs when Spark SQL cannot analyze or execute a query due to some logical or semantic error1. In this case, the error message indicates that the query cannot resolve the column name 'heartrateheartrateheartrate' given the input columns
'heartrate' and 'age'. This means that there is no column in the table named 'heartrateheartrateheartrate', and the query is invalid. A possible cause of this error is a typo or a copy-paste mistake in the query. To fix this error, the query should use a valid column name that exists in the table, such as
'heartrate'. References: AnalysisException
NEW QUESTION # 187
Assuming that the Databricks CLI has been installed and configured correctly, which Databricks CLI command can be used to upload a custom Python Wheel to object storage mounted with the DBFS for use with a production job?
Answer: A
Explanation:
The libraries command group allows you to install, uninstall, and list libraries on Databricks clusters. You can use the libraries install command to install a custom Python Wheel on a cluster by specifying the --whl option and the path to the wheel file. For example, you can use the following command to install a custom Python Wheel named mylib-0.1-py3-none-any.whl on a cluster with the id 1234-567890-abcde123:
databricks libraries install --cluster-id 1234-567890-abcde123 --whl dbfs:/mnt/mylib/mylib-0.1-py3-none-any.
whl
This will upload the custom Python Wheel to the cluster and make it available for use with a production job.
You can also use the libraries uninstall command to uninstall a library from a cluster, and the libraries list command to list the libraries installed on a cluster.
References:
Libraries CLI (legacy): https://docs.databricks.com/en/archive/dev-tools/cli/libraries-cli.html Library operations: https://docs.databricks.com/en/dev-tools/cli/commands.html#library-operations Install or update the Databricks CLI: https://docs.databricks.com/en/dev-tools/cli/install.html
NEW QUESTION # 188
A table is registered with the following code: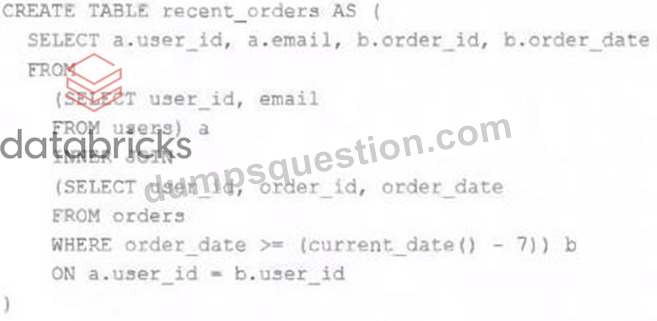
Bothusersandordersare Delta Lake tables. Which statement describes the results of queryingrecent_orders?
Answer: B
Explanation:
Explanation
This is the correct answer because Delta Lake supports time travel, which allows users to query data as of a specific version or timestamp. The code uses the VERSION AS OF syntax to specify the version of each source table to be used in the join. The result of querying recent_orders will be the same as joining those versions of the source tables at query time. The query will use snapshot isolation, which means it will use a consistent snapshot of the table at the time the query began, regardless of any concurrent updates or deletes.
Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Query an older snapshot of a table (time travel)" section.
NEW QUESTION # 189
What is the main difference between the silver layer and gold layer in medallion architecture?
Answer: A
Explanation:
Explanation
Medallion Architecture - Databricks
Gold Layer:
1. Powers Ml applications, reporting, dashboards, ad hoc analytics
2. Refined views of data, typically with aggregations
3. Reduces strain on production systems
4. Optimizes query performance for business-critical data
Exam focus: Please review the below image and understand the role of each layer(bronze, silver, gold) in medallion architecture, you will see varying questions targeting each layer and its purpose.
Sorry I had to add the watermark some people in Udemy are copying my content.
A diagram of a house Description automatically generated with low confidence
NEW QUESTION # 190
......
Practice tests (desktop and web-based) are simulations of actual Databricks Databricks-Certified-Professional-Data-Engineer PDF Questions designed to help individuals prepare and improve their performance for the Databricks Databricks-Certified-Professional-Data-Engineer certification test. DumpsQuestion facilitates the customers with customizable practice tests which means they can adjust the number of questions and set the time of the test according to themselves which will help them in order to feel the real-based exam pressure and control it.
Databricks-Certified-Professional-Data-Engineer New Dumps Ppt: https://www.dumpsquestion.com/Databricks-Certified-Professional-Data-Engineer-exam-dumps-collection.html