2026 Latest Easy4Engine SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1G6_OpHdrAI8S4BQ3ba4REOvZvYK4TrYL
Our SPS-C01 exam braindumps can lead you the best and the fastest way to reach for the certification and achieve your desired higher salary by getting a more important position in the company. Because we hold the tenet that low quality exam materials may bring discredit on the company. So we only creat the best quality of our SPS-C01 Study Materials to help our worthy customers pass the exam by the first attempt. Tens of thousands of our customers have passed their exam. And you will be the next one if you buy our SPS-C01 practice engine.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Performance Optimization and Best Practices | 20% | - Minimizing data transfer - Query pushdown and optimization - Warehouse sizing for Snowpark - Debugging and explain plans - Vectorized UDFs - Caching strategies |
| Topic 2: Snowpark Concepts | 15% | - Snowpark Sessions and connection management - Stored procedures and conditional logic - Snowpark architecture and core concepts - Snowpark DataFrames and query plans - Client-side vs. Server-side execution - Transformations vs. Actions |
| Topic 3: Data Transformations and DataFrame Operations | 35% | - Complex data pipelines - Window functions - Filtering, Aggregating, and Joining DataFrames - Persisting transformed data - Using built-in functions |
| Topic 4: Snowpark API for Python | 30% | - User-Defined Functions (UDFs) and Stored Procedures - Reading and writing data - Working with Semi-structured data - DataFrame creation and manipulation - Establishing connections and session management |
>> SPS-C01 Latest Exam Question <<
Easy4Engine provides you with a free demo of Snowflake SPS-C01 Questions so you do not have any doubts about the quality of our exam prep material. Similarly, We also provide free updates up to 365 days after purchasing Snowflake Certified SnowPro Specialty - Snowpark dumps questions, so that you always get the latest Snowflake dumps.
NEW QUESTION # 197
You have a Snowflake table named 'RAW EVENTS with a large number of events data, containing columns like 'EVENT ID', 'TIMESTAMP, 'USER ID, and 'EVENT_TYPE. The 'EVENT TYPE column contains string values representing different event categories. You want to create a Snowpark DataFrame, but due to the table's size, you only want to sample a small portion of the data for initial exploration and testing. Which of the following code snippets MOST accurately and efficiently creates a sampled Snowpark DataFrame named 'sampled_df containing approximately 1% of the rows from the 'RAW EVENTS table?





Answer: B
Explanation:
Explanation:Option A provides the MOST accurate and efficient way to sample 1% of the data using , seed-42)'. The 'frae parameter directly specifies the fraction of rows to sample. 'seed' ensures consistent sampling across multiple runs. Option B is inefficient because it calculates the total count of rows before limiting, which scans the entire table. Option C, uses 'randomSplit' , but it splits the data into two new dataframes. Option D, utilizes Snowflake's SQL sampling feature via 'session.sqr , is a valid alternative, but less idiomatic when using Snowpark API directly. Option E, the parameter 'n' is deprecated and has been removed. 'sample' requires 'frae parameter.
NEW QUESTION # 198
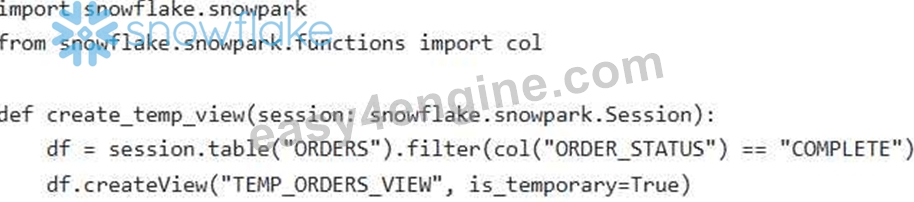
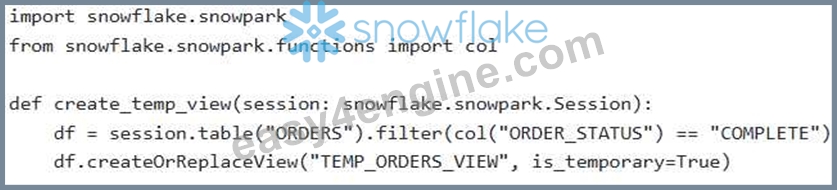
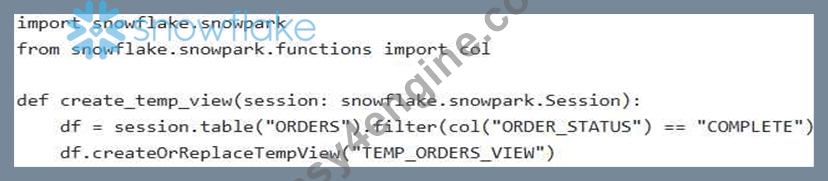
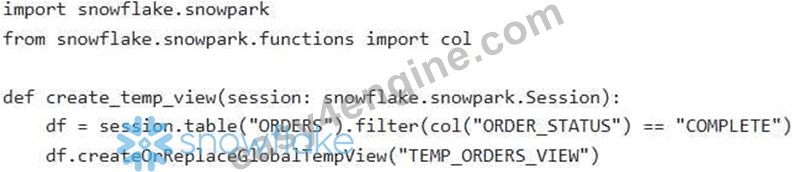
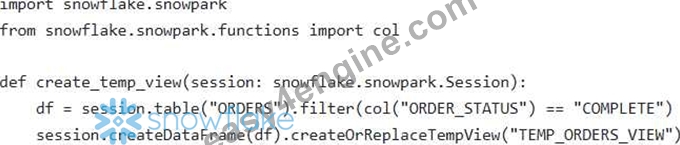
A Snowpark application is designed to process data residing in a Snowflake table called 'ORDERS'. The application needs to create a temporary view named 'TEMP ORDERS VIEW based on a filtered subset of this table. The view should only be accessible within the current Snowpark session and should be automatically dropped when the session ends. What is the MOST efficient and correct Python code snippet using Snowpark to achieve this?
Answer: C
Explanation:
Option A, , is the most efficient and directly creates a temporary view scoped to the session. The 'createOrRepIaceTempView' method is the correct Snowpark API call for creating such views. Options B and D, 'createOrReplaceView' with or 'createView' with , are not valid Snowpark API calls. Option C, createOrReplaceGlobalTempViews , creates a global temporary view, accessible across sessions, which is not the requirement. Option E is adding a redundant step by creating a dataframe from another dataframe.
NEW QUESTION # 199
A Snowpark Python application is experiencing significant performance degradation when processing a large dataset (100GB+) stored in Snowflake. The application performs a complex series of transformations, including window functions and joins with smaller lookup tables. You suspect data skew is contributing to the issue. Which of the following strategies would be MOST effective in mitigating the impact of data skew and improving performance?
Answer: E
Explanation:
Salting or pre-partitioning addresses data skew directly by distributing the skewed values more evenly across partitions. Increasing warehouse size (A) might help to some extent but doesn't solve the underlying skew issue. Broadcasting small tables (C) is a good optimization, but it's less effective if the larger dataset is skewed. Disabling query result caching (D) is irrelevant to data skew. Converting to Pandas (E) will likely make performance worse for large datasets due to data transfer overhead and limitations of single-node processing.
NEW QUESTION # 200
You are developing a Snowpark application that involves creating a set of stored procedures and UDFs to process data'. To ensure proper version control and dependency management, you decide to package your Python code into a single Python Wheel file and deploy it to Snowflake. Which of the following methods are valid for deploying and utilizing this Python Wheel file within Snowflake, considering best practices for maintainability and security? (Select TWO)
Answer: A,D
Explanation:
Options D and E are the correct answers. Creating a Conda environment file and deploying it to Snowflake (Option D) allows for explicit version control and dependency management, ensuring consistent execution across environments. You need to upload the environment.yml which contains the packages and custom wheel you need to add. Using 'snowflake-cli' to push wheel as a package (Option E) is the approach for using custom packages. These are the recommended approaches. Uploading wheel files to internal or external stages and referencing them using the 'USING' clause (Options A and B) might work, but it lacks the structured dependency management provided by Conda environments. Snowsight cannot be used to directly upload wheels for environment setup (Option C).
NEW QUESTION # 201
You are developing a Snowpark application that processes high-volume event data stored in a Snowflake table named 'raw events'. The application aggregates data by session ID. You observe significant performance degradation during peak hours. Analyzing Snowflake query history reveals that the 'session_id' column has high cardinality and data skew. Which of the following strategies, or combination of strategies, would be MOST effective in optimizing the aggregation performance?
Answer: B,D
Explanation:
Using BUCKET_ID hint improves parallel processing and mitigates data skew in Snowpark. Pre-aggregation reduces the amount of data processed by the Snowpark application, thus improving performance. Increasing the warehouse size (A) might help but doesn't address data skew. UDFs (D) can introduce overhead if not optimized. GROUP BY alone (B) will not address the data skew problem
NEW QUESTION # 202
......
In informative level, we should be more efficient. In order to take the initiative, we need to have a strong ability to support the job search. And how to get the test SPS-C01 certification in a short time, which determines enough SPS-C01 qualification certificates to test our learning ability and application level. Our SPS-C01 Exam Questions are specially designed to meet this demand for our worthy customers. As long as you study with our SPS-C01 learning guide, you will pass the exam and get the certification for sure.
SPS-C01 Test Guide Online: https://www.easy4engine.com/SPS-C01-test-engine.html
DOWNLOAD the newest Easy4Engine SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1G6_OpHdrAI8S4BQ3ba4REOvZvYK4TrYL