従来の見解では、練習資料は、実際の試験に現れる有用な知識を蓄積するために、それらに多くの時間を割く必要があります。 Pass4Testただし、Developing AI Apps and Agents on Azureの学習に関する質問はMicrosoftその方法ではありません。 以前のAI-103試験受験者のデータによると、合格率は最大98〜100%です。 最小限の時間と費用で試験に合格するのに役立つ十分なコンテンツがあります。Developing AI Apps and Agents on Azure AI-103準備資料の最新コンテンツで学習できるように、当社の専門家が毎日更新状況を確認し、彼らの勤勉な仕事と専門的な態度が練習資料に高品質をもたらします。 Developing AI Apps and Agents on Azureトレーニングエンジンの初心者である場合は、疑わしいかもしれませんが、参照用に無料のデモが提供されています。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Plan and manage Azure AI solutions | 25–30% | - Design Azure AI infrastructure
|
| Topic 2: Implement information extraction and knowledge mining | 10–15% | - Extract structured data from documents
|
| Topic 3: Implement generative AI and agentic solutions | 30–35% | - Build generative AI applications
|
| Topic 4: Implement computer vision solutions | 10–15% | - Build multimodal solutions
|
| Topic 5: Implement text and speech analysis solutions | 10–15% | - Implement natural language processing
|
クライアントにAI-103学習準備で一流のサービスを提供します。これには、販売の前後のサービス、24時間のオンラインカスタマーサービスと長距離支援、返金サービス、更新サービスが含まれます。クライアントは、私たちの試してみると、クライアントは、彼らはいつでも私たちの顧客サービスに連絡することができ、販売後の私たちの製品について問題がある場合は、販売前に自由にAI-103ガイド素材をダウンロードすることができます。私たちMicrosoftは、Developing AI Apps and Agents on Azureトレーニングクイズについて、クライアントの質問や疑問を返信し、その問題を解決するため、24時間オンライン顧客サービスを提供しています。
質問 # 64
You have a Microsoft Foundry project.
You plan to build a customer support solution that contains an agent. The solution must meet the following requirements:
* Provide accurate, context-aware responses grounded in internal product documentation stored in Azure AI Search.
* Require deep, multi-step reasoning across long contexts.
* Generate detailed natural language responses.
Which type of model should you use to power the agent?
正解:A
解説:
The correct model type is a large language model (LLM) . The scenario requires an agent that can reason over retrieved documentation, synthesize context-aware answers, and generate detailed natural language responses. Microsoft Foundry RAG guidance defines Retrieval Augmented Generation as a pattern that combines search with large language models so responses are grounded in organizational data, which directly matches the use of Azure AI Search for internal product documentation.
An LLM is also the correct fit for deep, multi-step reasoning across long contexts. Azure AI Search agentic retrieval guidance states that complex chat and agent scenarios use an LLM to break a user query into smaller focused subqueries for better coverage over indexed content. Microsoft also describes Azure AI Search as a way to ground agents and chatbots in proprietary enterprise data for accurate, context-aware responses.
A multimodal model is unnecessary because the requirements are text-focused, not image, audio, or video based. A key phrase extraction model performs narrow text analytics and cannot generate detailed answers.
An SLM may reduce cost and latency, but the stated need for deep reasoning and long-context synthesis favors an LLM. Reference topics: Microsoft Foundry RAG, Azure AI Search grounding, agentic retrieval, and model selection for generative AI agents.
質問 # 65
You have a Microsoft Foundry project that contains a deployed chat model.
You have a Python service that sends API requests to the model. The service is integrated with an automated validation system that compares generated outputs against approved response patterns.
Stakeholders report that small wording differences are causing validation mismatches.
You need to update the request parameters to improve output stability. The solution must maximize reasoning quality.
How should you complete the Python code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.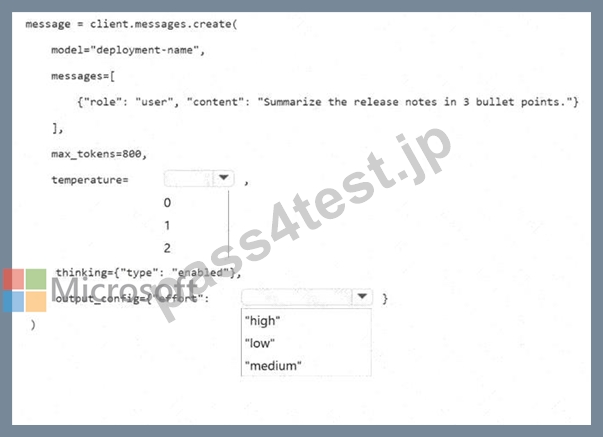
正解:
解説: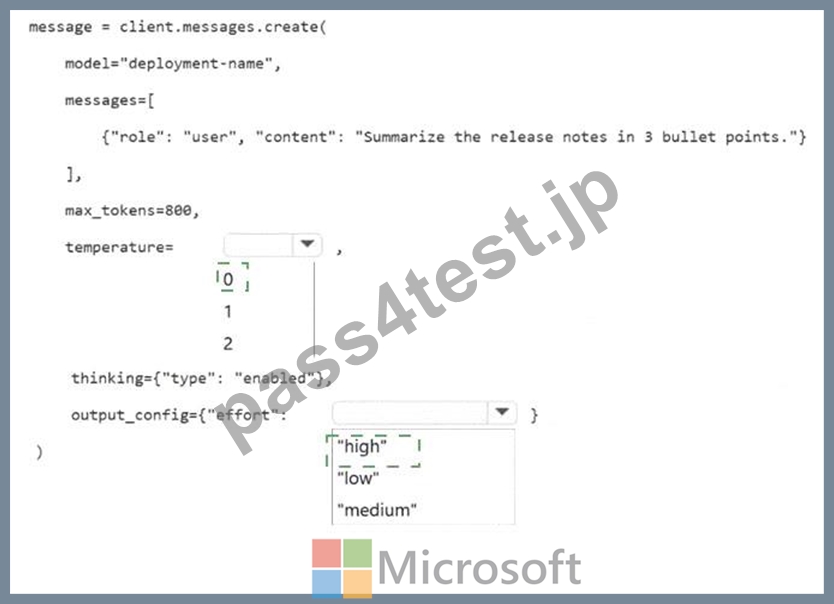
Explanation:
temperature = 0
output_config = { " effort " : " high " }
The correct configuration is temperature = 0 and output_config = { " effort " : " high " }. The requirement is to reduce small wording variations that are breaking automated validation. In chat completion requests, temperature controls sampling randomness. Microsoft's Azure OpenAI reference states that temperature ranges between 0 and 2, and that higher values make output more random while lower values make output more focused and deterministic. Therefore, the most stable setting from the available choices is 0, because it minimizes randomness and improves repeatability for validation-sensitive response patterns.
The solution must also maximize reasoning quality. The code already enables thinking with thinking={ " type
" : " enabled " }, so the remaining reasoning-quality control is the effort setting. Microsoft Foundry model guidance states that the effort parameter controls the quality/cost tradeoff and supports low, medium, and high effort levels. Selecting " high " maximizes reasoning quality among the available options.
Using temperature values of 1 or 2 would increase variability and make validation mismatches more likely.
Selecting low or medium effort would not meet the requirement to maximize reasoning quality. Reference topics: Microsoft Foundry model inference, chat model parameters, temperature, thinking, effort, and output stability.
質問 # 66
You are building an app that will share user images. You need to configure the app to:
* Categorize each image as a photograph or drawing.
* Generate a caption for the image.
* Minimize development effort.
Which two services should you include?
正解:A、C
解説:
Use image type detection to distinguish drawings from ordinary photographic content. Azure Vision's ImageType visual feature returns information including lineDrawingType, which indicates whether the submitted image is a line drawing, and clipArtType, which estimates whether it is clip art. The application can use these pretrained results to implement the required photograph-versus-drawing categorization without collecting labeled images or training a custom classifier.
Use image descriptions to generate the caption. Azure Vision Image Analysis provides the Caption visual feature, which generates a concise, one-sentence description of the overall image. Dense Captions can additionally describe individual regions, but the standard Caption feature directly satisfies the stated requirement.
Object detection identifies and locates individual objects by using bounding boxes; it does not determine whether the entire image is a photograph or drawing. Content tags produce descriptive keywords rather than a natural-language caption. Azure Custom Vision classification could be trained for the image-type distinction, but it would require image collection, labeling, training, evaluation, and deployment, increasing development effort unnecessarily.
Study Guide alignment: configure applications to produce captions and implement solutions that identify visual characteristics within images .
質問 # 67
You are planning a Microsoft Foundry project named Project1 that will contain multiple agents. Each agent will access the same Azure Al Search resource.
You need to recommend a solution to centrally manage the Azure Al Search credentials within Project1. The solution must be implemented across all the agents.
What should you recommend?
正解:A
解説:
The correct recommendation is B. Add a connection to the Azure AI Search resource . Microsoft Foundry project connections are used to centrally define access from a project to external resources, including Azure AI Search. The official connection guidance states that you can add a connection by selecting an external service such as Azure AI Search , choosing the resource, and selecting the authentication method for that resource. This creates a reusable project-level configuration rather than requiring each agent to store or duplicate search credentials independently.
For Foundry agents that use Azure AI Search, the Azure AI Search tool requires a project_connection_id, which is the resource ID of the project connection to Azure AI Search. This allows multiple agents to reference the same managed connection while using the configured endpoint and authentication settings consistently. RBAC may be part of a keyless authentication design, but it does not by itself create a centrally managed Foundry credential configuration. Disabling key-based access improves security posture but does not connect the agents. A managed private endpoint addresses network isolation, not credential centralization.
Reference topics: Microsoft Foundry project connections, Azure AI Search tool, project connection IDs, authentication, and agent grounding.
質問 # 68
Hotspot Question
You have a Microsoft Foundry project.
- You need to create a customer support agent that meets the following
requirements:
- Grounds responses only in company policy documents stored in curated
repositories
- Retains customer preferences across separate chat sessions
How should you configure the agent? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.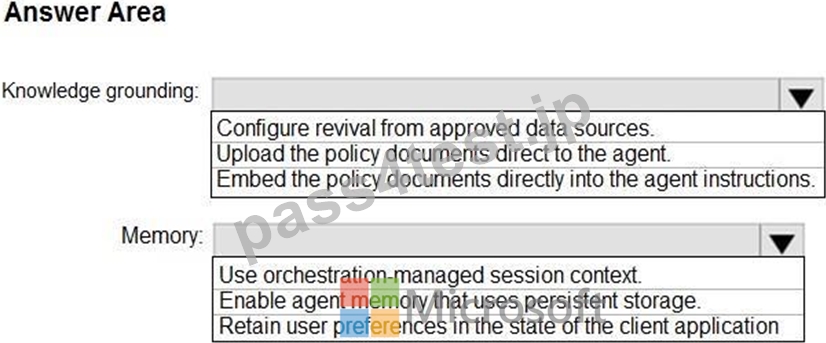
正解:
解説: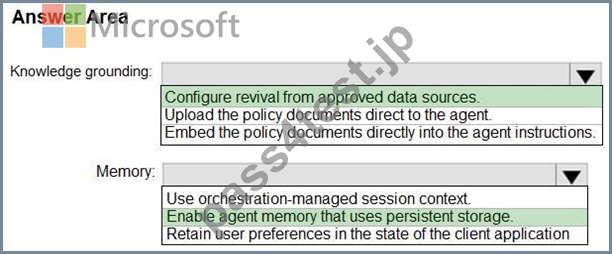
Explanation:
Box 1: Configure retrieval from approved data sources
You should configure retrieval from approved data sources to meet this requirement.
In Microsoft Foundry (and broader Azure AI Foundry / Azure OpenAI architectures), grounding an agent exclusively in company policy documents requires implementing a Retrieval-Augmented Generation (RAG) pattern. This ensures the AI model only answers using the provided context and does not hallucinate or rely on its public training data.
Box 2: Enable agent memory that uses persistent storage
To retain user preferences across completely separate chat sessions or conversations, you must use persistent agent memory. Traditional chat history only tracks messages within a single active thread or session. By contrast, the Memory Store feature provides a managed, long-term memory system that structurally indexes user preferences and facts across different devices and separate sessions.
Reference:
https://techcommunity.microsoft.com/blog/azure-ai-foundry-blog/announcing-new-capabilities-for-azure-openai-on-your-data/4144636
質問 # 69
......
Pass4TestのMicrosoftのAI-103試験トレーニング資料は高度に認証されたIT領域の専門家の経験と創造を含めているものです。私たちのIT専門家は受験生のために、最新的なMicrosoftのAI-103問題集を提供します。うちの学習教材の高い正確性は言うまでもありません。受験生が最も早い時間で、一回だけでMicrosoftのAI-103認定試験に合格できるために、Pass4Testはずっとがんばります。
AI-103合格問題: https://www.pass4test.jp/AI-103.html