Nowadays, online learning is very popular among students. Most candidates have chosen our Databricks-Certified-Data-Engineer-Professional learning engine to help them pass the exam. Our company has accumulated many experiences after ten years’ development. We never stop researching and developing the new version of the Databricks-Certified-Data-Engineer-Professional practice materials. With our Databricks-Certified-Data-Engineer-Professional study questions, you can easily get your expected certification as well as a brighter future.
| Section | Weight | Objectives |
|---|---|---|
| Data Modeling and Storage | 20% | - Data Modeling - File Formats - Storage Optimization |
| Data Quality and Governance | 12% | - Governance - Data Quality - Data Lineage |
| Monitoring and Troubleshooting | 16% | - Performance Optimization - Troubleshooting - Monitoring |
| Databricks Lakehouse Platform | 24% | - Delta Lake - Unity Catalog - Data Management - Lakehouse Architecture |
| Data Processing | 28% | - Structured Streaming - Data Transformation - ETL Pipelines - Spark SQL |
>> Databricks-Certified-Data-Engineer-Professional Paper <<
By gathering, analyzing, filing essential contents into our Databricks-Certified-Data-Engineer-Professional training quiz, they have helped more than 98 percent of exam candidates pass the Databricks-Certified-Data-Engineer-Professional exam effortlessly and efficiently. You can find all messages you want to learn related with the exam in our Databricks-Certified-Data-Engineer-Professional Practice Engine. Any changes taking place in the environment and forecasting in the next Databricks-Certified-Data-Engineer-Professional exam will be compiled earlier by them. About necessary or difficult questions, they left relevant information for you.
NEW QUESTION # 115
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
Answer: A
Explanation:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. These statistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.
NEW QUESTION # 116
A data company uses Databricks Unity Catalog and has multiple enterprise data sources, including PostgreSQL, Snowflake, and SQL Server. The central data platform team wants to configure Lakehouse Federation so analysts can query external tables directly in Databricks using Databricks SQL, without duplicating data. Which steps are necessary to configure Lakehouse Federation in a secure and governed manner?
Answer: C
Explanation:
Lakehouse Federation is configured by defining secure connections to external data sources and registering them as foreign catalogs in Unity Catalog. Access is then governed using Unity Catalog permissions at the catalog, schema, and table levels, enabling analysts to query external tables securely without data duplication.
NEW QUESTION # 117
A data engineer manages a production Lakeflow Declarative Pipeline that processes customer transaction data. The pipeline includes several data quality expectations such as transaction_amount > 0 and customer_id IS NOT NULL. These expectations are defined using the EXPECT clause in SQL.
The engineer aims to monitor the pipeline's data quality by analyzing the number of records that passed or failed each expectation during the latest pipeline update. The Lakeflow Declarative Pipelines event logs are stored in a Delta table named event_log_table.
For the most recent pipeline update, determine a programmatically appropriate approach to extract information like the name of each expectation, associated dataset, count of records that passed the expectation, and count of records that failed the expectation.
Which method retrieves the desired data quality metrics from the Lakeflow Declarative Pipelines event log?
Answer: C
Explanation:
The Databricks documentation specifies that for Lakeflow Declarative Pipelines, detailed data quality metrics are logged as events of type expectation_result within the event log. Each record of this type contains fields including expectation_name, dataset_name, passed_records, and failed_records. Filtering on event_type = 'expectation_result' and expanding the details field allows retrieving metrics for each expectation from the most recent pipeline update. While flow_progress provides summary statistics and data_quality events aggregate results, only expectation_result events provide granular, per-expectation metrics required for audit and monitoring automation.
NEW QUESTION # 118
A data engineer is reviewing the PySpark code to copy a part of the production dataset to the sandbox environment, and needs to be sure that no PII(Personally Identifiable Information) data is being copied. After checking the sales table, the data engineer notices that it has user emails as the only PII data included as well as being the only column to identify the user.
from pyspark.sql import functions as F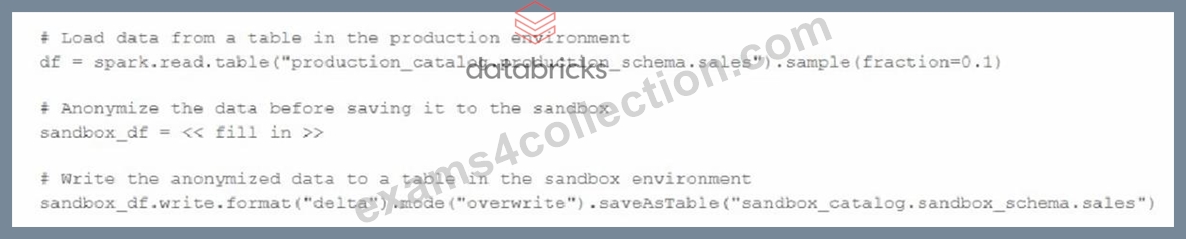
Which anonymised code should be used to achieve the required outcome?
Answer: B
Explanation:
Hashing the email column replaces the original PII with a deterministic, irreversible value while preserving its role as a unique identifier. This ensures no actual email addresses are copied to the sandbox environment, while still allowing consistent joins or user-level analysis if needed.
NEW QUESTION # 119
A data engineer is evaluating tools to build a production-grade data pipeline. The team must process change data from cloud object storage, filter out or isolate invalid records, and ensure the timely delivery of clean data to downstream consumers. The team is small, under tight deadlines, and wants to minimize operational overhead while keeping pipelines auditable and maintainable.
Which approach should the data engineer implement?
Answer: C
Explanation:
LDP provides a declarative framework for building production-grade pipelines with minimal operational overhead. Streaming Tables and Materialized Views handle incremental processing automatically, while built-in data expectations allow invalid records to be filtered or isolated in a consistent and auditable way. This approach is well suited for small teams under tight deadlines, as it simplifies maintenance, improves reliability, and ensures timely delivery of clean data to downstream consumers.
NEW QUESTION # 120
......
The one badge of Databricks-Certified-Data-Engineer-Professional certificate will increase your earnings and push you forward to achieve your career objectives. Are you ready to accept this challenge? Looking for the simple and easiest way to pass the Databricks-Certified-Data-Engineer-Professional certification exam? If your answer is yes then you do not need to get worried. Just visit the Databricks Databricks-Certified-Data-Engineer-Professional Pdf Dumps and explore the top features of Databricks-Certified-Data-Engineer-Professional test questions. If you feel that Databricks Certified Data Engineer Professional Exam Databricks-Certified-Data-Engineer-Professional exam questions can be helpful in exam preparation then download Databricks Certified Data Engineer Professional Exam Databricks-Certified-Data-Engineer-Professional updated questions and start preparation right now.
Databricks-Certified-Data-Engineer-Professional Valid Test Tips: https://www.exams4collection.com/Databricks-Certified-Data-Engineer-Professional-latest-braindumps.html