우리는 고객이 첫 번째 시도에서Microsoft DP-750 자격증시험을 합격할수있다는 것을 약속드립니다. Microsoft DP-750 시험을 합격하여 자격증을 손에 넣는다면 취직 혹은 연봉인상 혹은 승진이나 이직에 확실한 가산점이 될것입니다. Microsoft DP-750시험 어려운 시험이지만 저희Microsoft DP-750덤프로 조금이나마 쉽게 따봅시다.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Topic 2: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Topic 3: Prepare and process data | 30-35% | - Data ingestion
|
| Topic 4: Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
Microsoft인증 DP-750시험을 통과하여 자격증을 취득하여 IT 업계에서의 자신의 자리를 지키려면 많은 노력이 필요합니다. 회사일도 바쁜데 시험공부까지 스트레스가 장난아니게 싸이고 몸도 많이 상하겠죠. ITDumpsKR는 여러분을 위해 최신Microsoft인증 DP-750시험에 대비한Microsoft인증 DP-750덤프를 발췌하였습니다. Microsoft인증 DP-750덤프는Microsoft인증 DP-750시험의 기출문제와 예상문제가 묶어져 있어 시험적중율이 굉장히 높습니다. 쉽게 시험을 통과하려면ITDumpsKR의 Microsoft인증 DP-750덤프를 추천합니다.
질문 # 86
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
- The schemas and tables can be queried in Databricks.
- The schemas and tables appear alongside other Unity Catalog objects.
- The data is NOT copied into Databricks-managed storage.
Solution: You create a new native catalog in Unity Catalog.
Does this meet the goal?
정답:B
설명:
Correct:
* You create a foreign catalog in Catalog Explorer.
You should create a Foreign Catalog using Lakehouse Federation.
Data Copying: Lakehouse Federation queries data directly in the source SQL Server without moving or copying it.
Seamless Integration: The database schemas and tables appear right inside Unity Catalog alongside your other data objects.Real-time Access: It provides immediate access to live SQL Server data.
Incorrect:
* You create a Databricks access connector.
* You create a Lakeflow Connect pipeline and connect it to DB1.
Data Copying: Lakeflow Connect is an ingestion tool that physically replicates and copies data into Databricks-managed storage (Delta tables).
Storage Costs: It violates your requirement to keep data out of Databricks storage.
* You create a new native catalog in Unity Catalog.
Note:
To expose the external SQL Server database in Unity Catalog without copying the data, you must use Lakehouse Federation.
Here are the step-by-step actions you need to take:
1. Create a Connection
Create a securable object in Unity Catalog that specifies the path and credentials to access the SQL Server database.
Go to Catalog Explorer or use SQL.
Select External Data > Connections.
Create a connection using the SQL Server connection details (URL, host, port, and database credentials).
*-> 2. Create a Foreign Catalog
Create a specific type of catalog in Unity Catalog that mirrors the external database.
Use the CREATE FOREIGN CATALOG SQL command or the Catalog Explorer UI.
Link this foreign catalog directly to the connection you created in step 1.
3. Query the DataOnce the foreign catalog is created, Unity Catalog automatically syncs the schemas and tables from SQL Server.
Reference:
https://docs.databricks.com/gcp/en/database-objects/
질문 # 87
You use Databricks Asset Bundles to manage two jobs and an app.
You need to deploy the bundle to development and production environments. The solution must meet the following requirements
* Deploy the app to both environments.
* Deploy only one job to development.
* Minimize administrative effort.
What should you use?
정답:D
설명:
The correct answer is D - a targets node in databricks.yml.
Databricks Asset Bundles use a single databricks.yml to define all resources (jobs, apps, pipelines) once, and a targets node to define per-environment overrides. Within the development target, you can use the include
/exclude mechanism or resource-level overrides to deploy only one of the two jobs. The app and the second job are deployed to both environments through the shared resource definition.
Option B (separate databricks.yml files per environment) works technically but means duplicating the shared resource definitions across files - any change to a shared resource requires edits in multiple places, which is exactly the administrative overhead the question wants to avoid.
Option A (resources node) defines resources globally across all targets - it doesn't provide environment- specific filtering. Option C (variables node) parameterises values like cluster sizes or paths but doesn't control which resources are deployed to which environment.
Reference: https://learn.microsoft.com/en-us/azure/databricks/dev-tools/bundles/deployment-modes
질문 # 88
What improves join performance for small lookup tables?
정답:D
질문 # 89
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2. You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.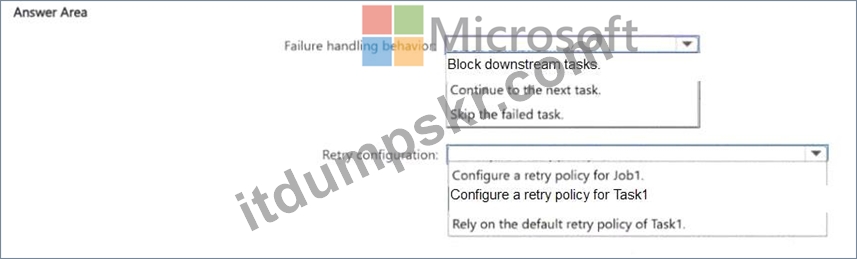
정답:
설명: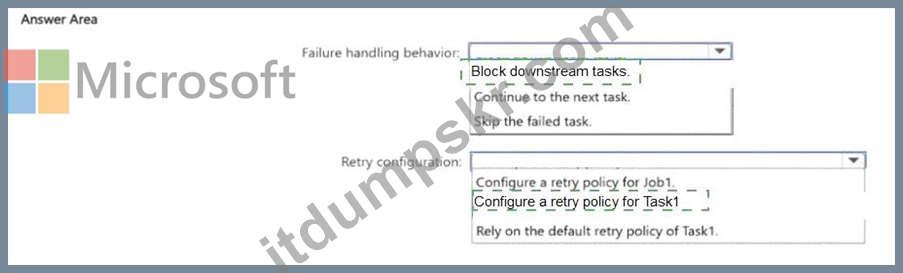
Explanation:
Two task-level settings solve this:
Task1 retry policy: configure Task1 with a maximum number of retries and a retry interval. When Task1 fails, Lakeflow Jobs automatically re-runs it up to the retry limit without any manual intervention. This handles transient infrastructure failures transparently.
Task2 run condition set to ' All succeeded ' with Task1 as its dependency: this means Task2 only starts when Task1 has succeeded. If Task1 fails and exhausts all retries, Task2 remains blocked - it never runs on data from a failed upstream ingestion. The dependency is declared in Task2 ' s ' Depends on ' setting in the job configuration.
These two settings are independent and composable. Task1 ' s retry policy gives it multiple chances to recover. Task2 ' s dependency and run condition ensure the downstream transformation only runs on clean, successfully ingested data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#task-retries
질문 # 90
Hotspot Question
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 contains three tasks named Task1, Task2, and Task3.
If Task1 fails, Task2 and Task3 must be prevented from running. Successfully completed tasks must NOT rerun during recovery.
You need to configure Job1 to support controlled failure handling and recovery.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.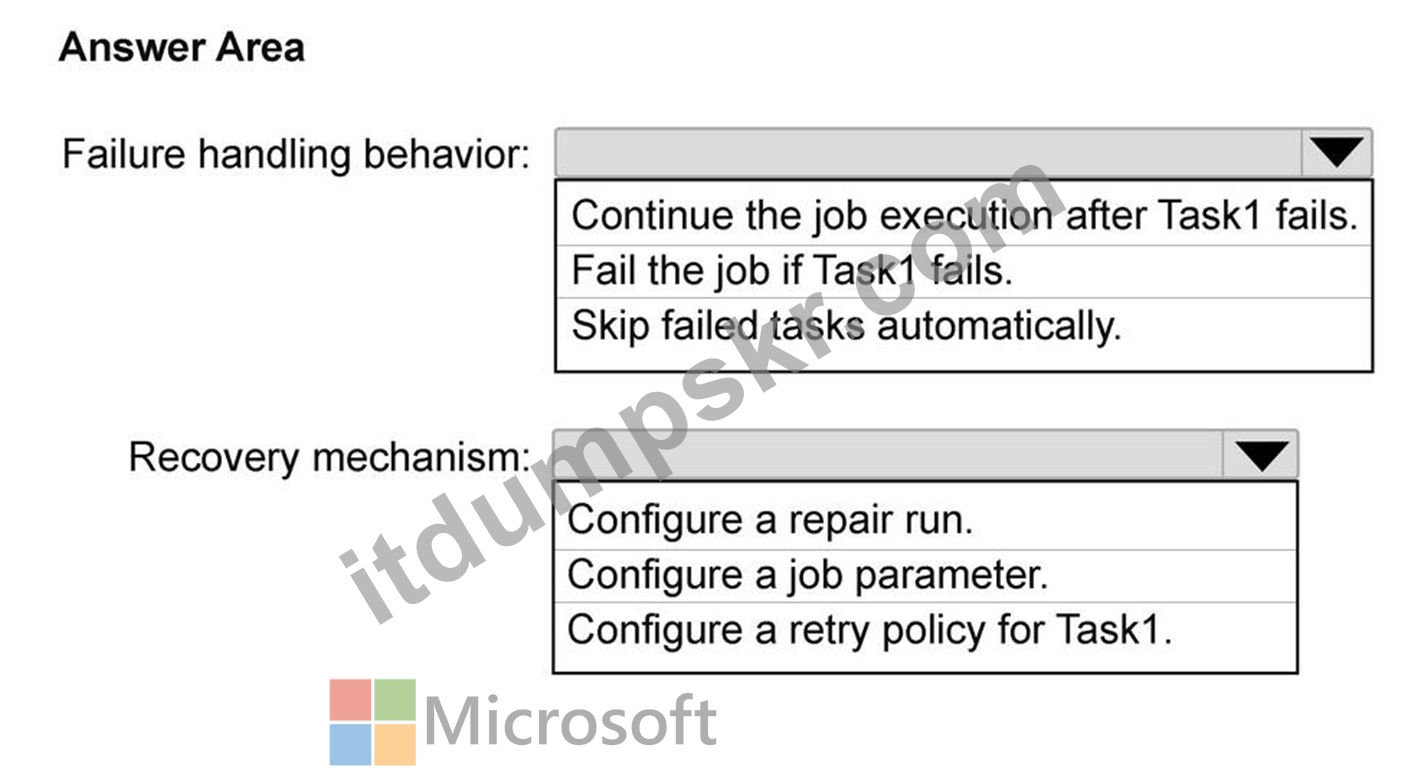
정답:
설명: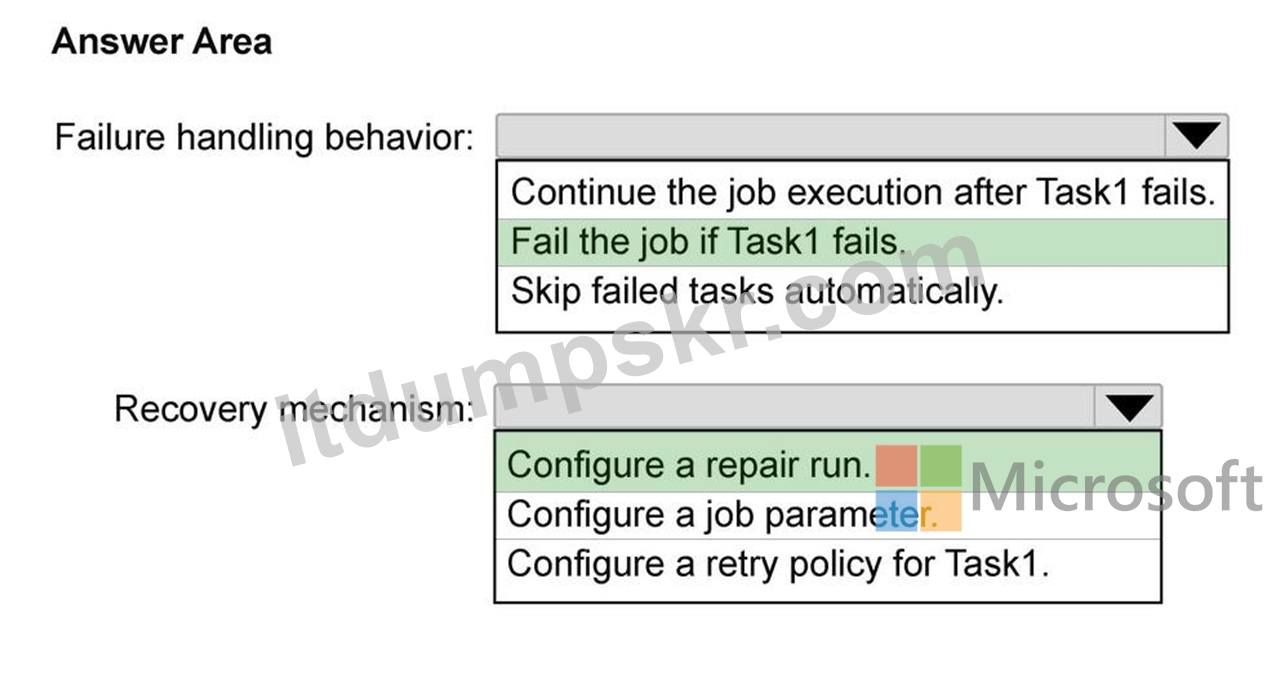
질문 # 91
......
ITDumpsKR에는 전문적인 업계인사들이Microsoft DP-750시험문제와 답에 대하여 연구하여, 시험준비중인 여러분들한테 유용하고 필요한 시험가이드를 제공합니다. 만약ITDumpsKR의 제품을 구매하려면, 우리ITDumpsKR에서는 아주 디테일 한 설명과 최신버전 최고품질의자료를 즉적중율이 높은 문제와 답을제공합니다.Microsoft DP-750자료는 충분한 시험대비자료가 될 것입니다. 안심하시고 ITDumpsKR가 제공하는 상품을 사용하시고, 100%통과 율을 확신합니다.
DP-750완벽한 인증자료: https://www.itdumpskr.com/DP-750-exam.html