2026 Latest itPass4sure DP-800 PDF Dumps and DP-800 Exam Engine Free Share: https://drive.google.com/open?id=1s3XRYCyVXFs0raycqm9JbqOKAF3SkCqT
There are so many features to show that our DP-800 study guide surpasses others. You can have a free try for downloading our DP-800 exam demo before you buy our products. What’s more, you can acquire the latest version of DP-800 training materials checked and revised by our exam professionals after your purchase constantly for a year. Besides, the pass rate of our DP-800 Exam Questions are unparalled high as 98% to 100%, you will get success easily with our help.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
Competition appear everywhere in modern society. There are many way to improve ourselves and learning methods of DP-800 exams come in different forms. Economy rejuvenation and social development carry out the blossom of technology; some DP-800 practice materials are announced which have a good quality. Certification qualification DP-800 Exam Materials are a big industry and many companies are set up for furnish a variety of services for it. And our DP-800 study guide has three different versions: PDF, Soft and APP versions to let you study in varied and comfortable ways.
NEW QUESTION # 58
You have an Azure SQL database that has Query Store enabled
Query Performance Insight shows that one stored procedure has the longest runtime. The procedure runs the following parameterized query.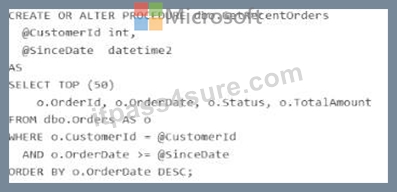
The dbo.orders table has approximately 120 million rows. Customer-id is highly selective, and orderOate is used for range filtering and sorting.
Vou have the following indexes:
* Clustered index: PK_Orders on (Orderld)
* Nonclustered index: lx_0rders_order-Date on (OrderDate) with no included columns An actual execution plan captured from Query Store for slow runs shows the following:
* An index seek on ixordersorderDate followed by a Key Lookup (Clustered) on PKOrders for customerid, status, and TotalAnount
* A sort operator before top (50), because the results are ordered by orderDate DESC For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.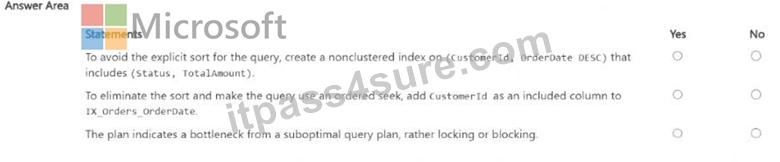
Answer:
Explanation: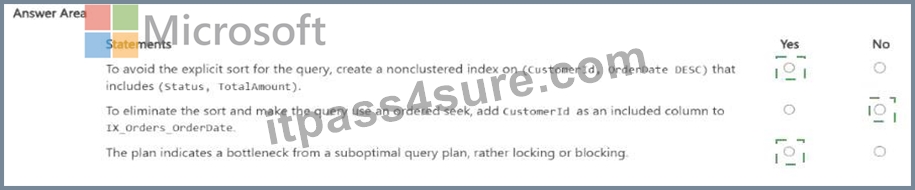
Explanation: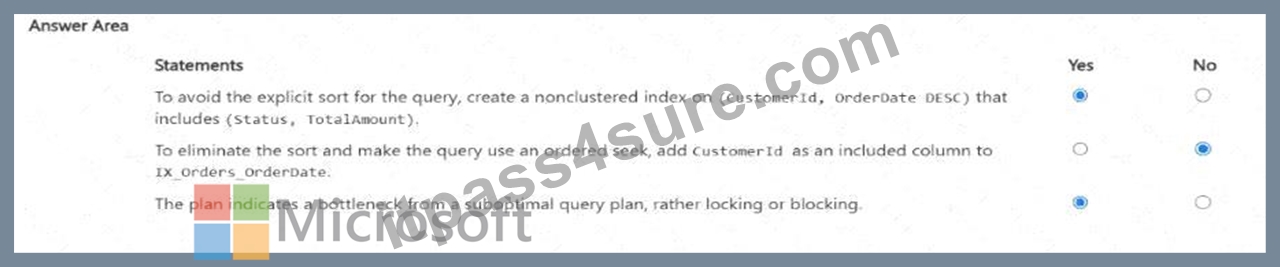
The first statement is Yes . The query filters on CustomerId, applies a range predicate on OrderDate, and sorts by OrderDate DESC. Microsoft's index design guidance recommends putting equality predicates first in the key, followed by columns used for ordering/range access, because the order of key columns determines seek and sort support. A nonclustered index on (CustomerId, OrderDate DESC) can support an ordered seek for this query and avoid the explicit sort. Including Status and TotalAmount helps cover the query, and OrderId is already available because the clustered key is stored with nonclustered index rows.
The second statement is No . Adding CustomerId as an included column to IX_Orders_OrderDate does not make it part of the index's navigational structure. Microsoft states that included columns are nonkey columns used to cover queries; they do not provide the seek and ordering characteristics that key columns do. So an index keyed only on OrderDate still is not the right ordered access path for WHERE CustomerId =
@CustomerId ... ORDER BY OrderDate DESC.
The third statement is Yes . The described actual plan shows an index seek on the wrong access path for the workload, followed by clustered key lookups and an explicit sort before TOP (50). That is characteristic of a suboptimal query/index plan . Query Store and Query Performance Insight are designed to surface plan- related performance regressions, while locking/blocking problems are typically identified through waits
/DMVs and blocking-session indicators, not from a plan shape like seek + lookup + sort alone.
NEW QUESTION # 59
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.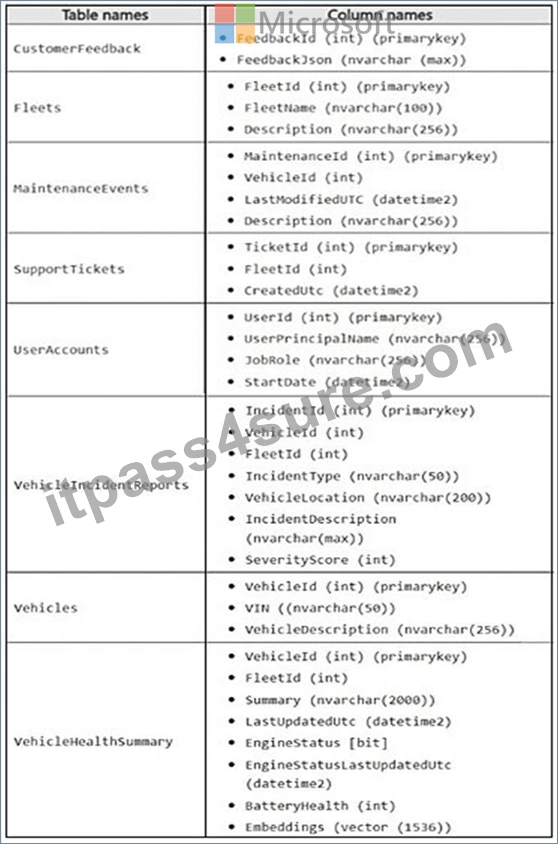
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.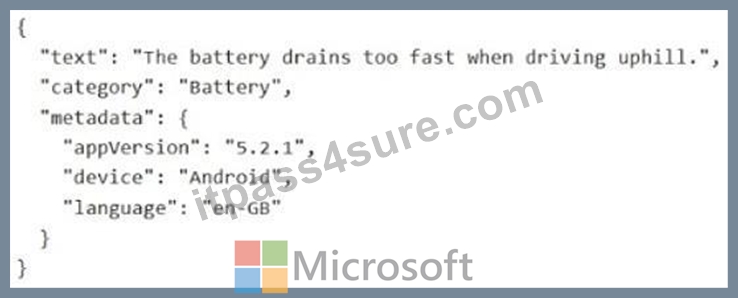
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.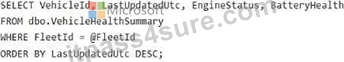
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
You need to generate embeddings to resolve the issues identified by the analysts. Which column should you use?
Answer: B
Explanation:
Scenario: VehicleIncidentReports often contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
The column you should use to generate embeddings is IncidentDescription.
Why this is the correct choice:
Semantic Meaning: Embeddings are designed to capture the semantic meaning of rich, unstructured text. The IncidentDescription column likely contains the detailed natural language notes about weather, traffic, and location that the analysts are struggling to search effectively using standard methods.
Vector Search: By converting the text in IncidentDescription into mathematical vectors (embeddings), you can perform a semantic vector search. This allows the database to find
"similar" incidents based on the context of the description rather than just matching exact keywords or categories.
Incorrect:
[Not A]
VehicleLocation: Typically contains specific coordinates or addresses which are better handled by spatial data types or exact matching.
[Not C]
IncidentType: Is likely a categorical label (e.g., "Fender Bender", "Multi-car pileup") and too simple for meaningful embedding generation.
[Not D]
SeverityScore: Is a numeric value that represents a magnitude, not a semantic concept.
Reference:
https://learn.microsoft.com/en-us/sql/t-sql/spatial-geography/spatial-types-geography
NEW QUESTION # 60
You have an Azure Al Search service and an index named hotels that includes a vector Held named DescriptionVector.
You query hotels by using the Search Documents REST API.
You add semantic ranking to the hybrid search query and discover that some queries return fewer results than expected, and captions and answers are missing.
You need to complete the hybrid search request to meet the following requirements:
* Include more documents when ranking.
* Always include captions and answers.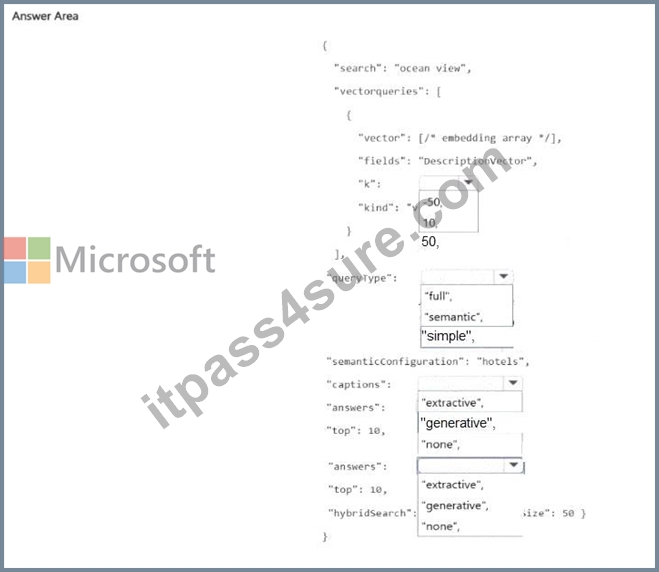
Answer:
Explanation: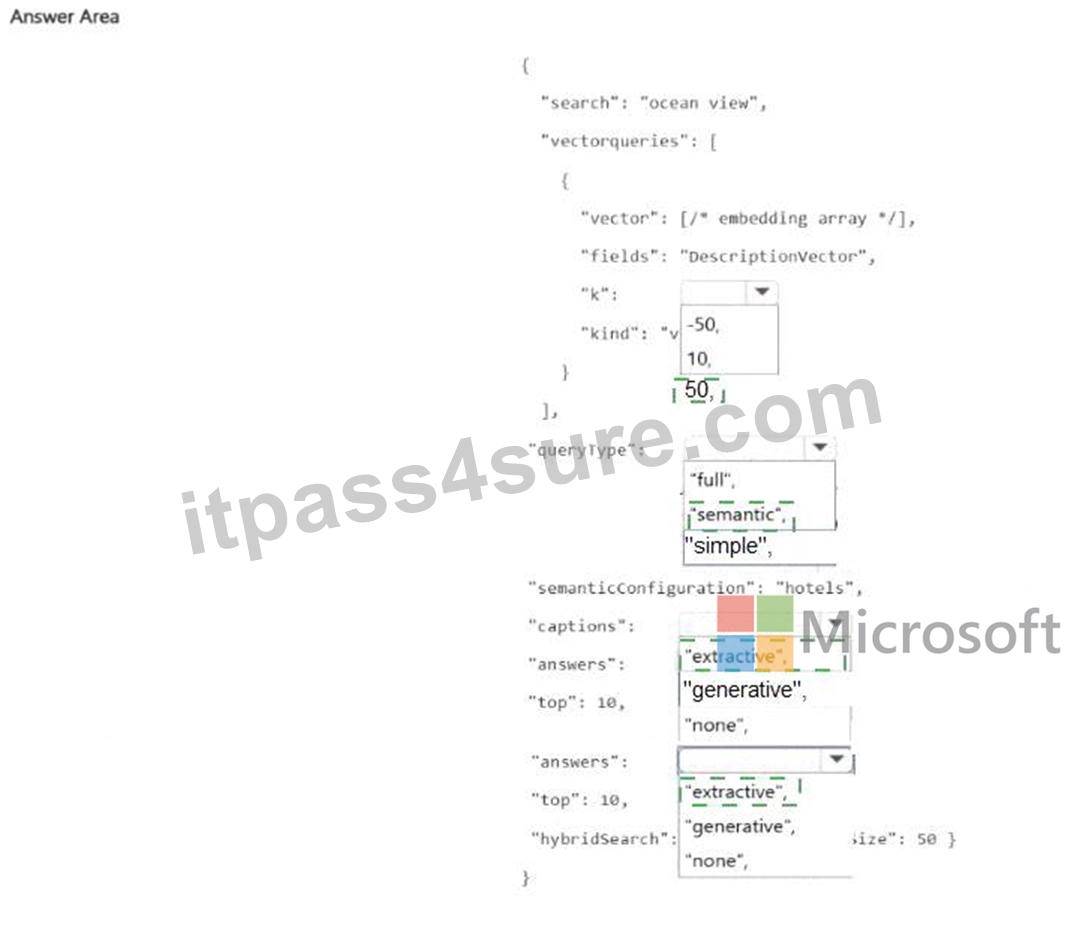
Explanation: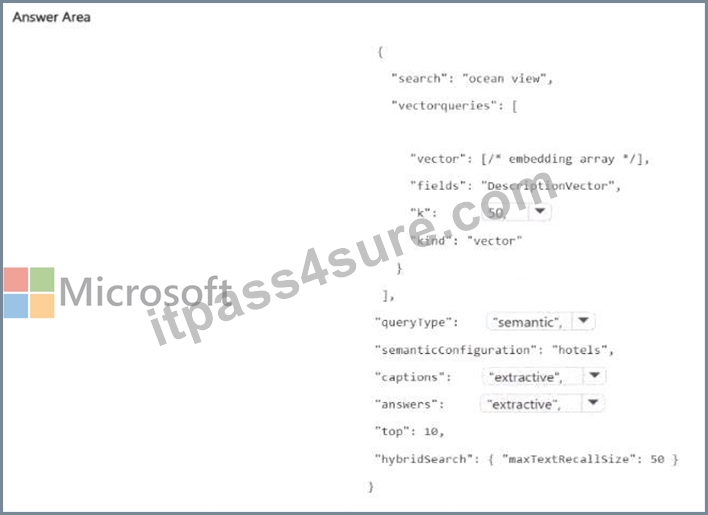
These are the correct selections for a hybrid query that uses semantic ranking in Azure AI Search.
Use k = 50 because Microsoft explicitly recommends that when you combine semantic ranking with vector queries , you should set k to 50 so the semantic ranker has enough candidates to rerank. If you use a smaller value such as 10, semantic ranking can receive too few inputs, which is exactly why some queries return fewer results than expected.
Use queryType = " semantic " because captions and answers are only available on semantic queries.
Microsoft documents that captions is valid only when the query type is semantic, and semantic answers are returned only for semantic queries.
Use captions = " extractive " because semantic captions are extractive passages pulled from the top-ranked documents. Microsoft's REST documentation states that the valid captions option here is extractive and that it defaults to none if not specified.
Use answers = " extractive " because semantic answers in Azure AI Search are extractive, not generated.
Microsoft documents that semantic answers are verbatim passages recognized as answers and the REST API lists extractive as the answer-return option.
NEW QUESTION # 61
You have an Azure SQL database that contains a table named Tickets_Embeddings. Tickets_Embeddings contains a VECTOR(1536) column.
Embeddings are generated by using text-embedding-ada-002 and the /openai/v1/embeddings endpoint.
After a review of the current environment, the following changes are requested:
The AI architect has recommended switching to text-embedding-3-small.
The security team requires authentication by using Microsoft Entra managed identities only. Storing API keys in an application is prohibited.
Which two actions should you include in the solution? Each correct answer presents a part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,E
NEW QUESTION # 62
Vou have a Microsoft Fabric workspace named Workspace1 that contains a SQL database named SalesDB and an API for GraphQL tern named SalesApi.
You have a Microsoft Entra group named SqlUsers.
From Workspace1, you assign permission to SalesApi as shown in the following exhibit.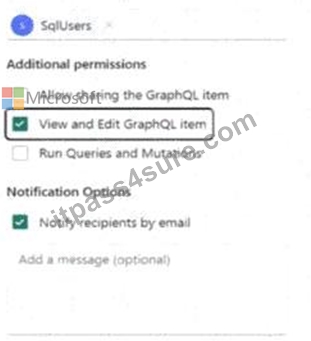
The connection to SalesDB has the connectivity option configured as shown in the following exhibit.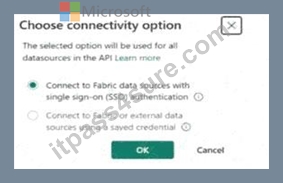
SqlUsers has the Viewer role for Workspace1.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.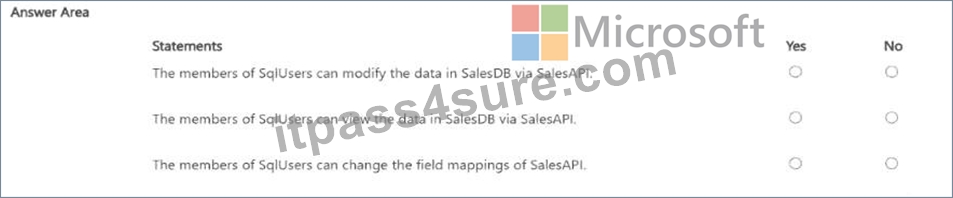
Answer:
Explanation: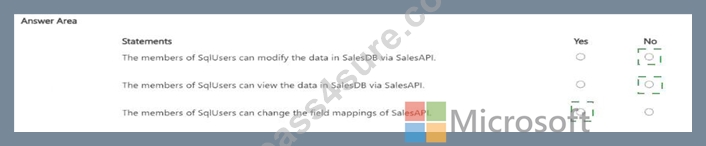
Explanation:
* The members of SqlUsers can modify the data in SalesDB via SalesApi. # No
* The members of SqlUsers can view the data in SalesDB via SalesApi. # No
* The members of SqlUsers can change the field mappings of SalesApi. # Yes For both viewing and modifying data through SalesApi, the key missing permission is Run Queries and Mutations . Microsoft's Fabric GraphQL documentation states that callers need Execute permissions for the GraphQL API , which correspond to the Run Queries and Mutations option, and with SSO connectivity they also need appropriate permissions on the underlying data source. In the exhibit, SqlUsers has View and Edit GraphQL item selected, but Run Queries and Mutations is not selected, so members cannot query or mutate data through the API.
The third statement is Yes because the group was explicitly granted View and Edit GraphQL item . That permission is the one that allows users to open and modify the GraphQL item itself, including schema-related configuration such as field mappings in the API item. The workspace Viewer role does not by itself grant query execution through the API, but the direct GraphQL item permission shown does allow editing the item.
NEW QUESTION # 63
......
Our DP-800 real exam dumps are specially prepared for you. Try our DP-800 study tool and absorb new knowledge. After a period of learning, you will find that you are making progress. The knowledge you have studied on our DP-800 exam question will enrich your life and make you wise. Do not reject challenging yourself. Your life will finally benefit from your positive changes. Let us struggle together and become better. Then you will do not need to admire others’ life. Our DP-800 Real Exam dumps will fully change your life.
Reliable DP-800 Exam Tips: https://www.itpass4sure.com/DP-800-practice-exam.html
DOWNLOAD the newest itPass4sure DP-800 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1s3XRYCyVXFs0raycqm9JbqOKAF3SkCqT