참고: PassTIP에서 Google Drive로 공유하는 무료, 최신 SPS-C01 시험 문제집이 있습니다: https://drive.google.com/open?id=1xhMDGwotUdqSXnvnmHe5Ef70XHVo0G_X
PassTIP는 응시자에게 있어서 시간이 정말 소중하다는 것을 잘 알고 있으므로 Snowflake SPS-C01덤프를 자주 업데이트 하고, 오래 되고 더 이상 사용 하지 않는 문제들은 바로 삭제해버리며 새로운 최신 문제들을 추가 합니다. 이는 응시자가 확실하고도 빠르게Snowflake SPS-C01덤프를 마스터하고Snowflake SPS-C01시험을 패스할수 있도록 하는 또 하나의 보장입니다.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark API and Development | 30% | - Multi-language support
|
| Topic 2: Performance and Best Practices | 10% | - Optimization techniques
|
| Topic 3: Data Transformations and Operations | 35% | - Advanced operations
|
| Topic 4: Snowpark Concepts and Architecture | 25% | - Session management and connection
|
PassTIP의 Snowflake인증 SPS-C01덤프는 다른 덤프판매 사이트보다 저렴한 가격으로 여러분들께 가볍게 다가갑니다. Snowflake인증 SPS-C01덤프는 기출문제와 예상문제로 되어있어 시험패스는 시간문제뿐입니다.
질문 # 57
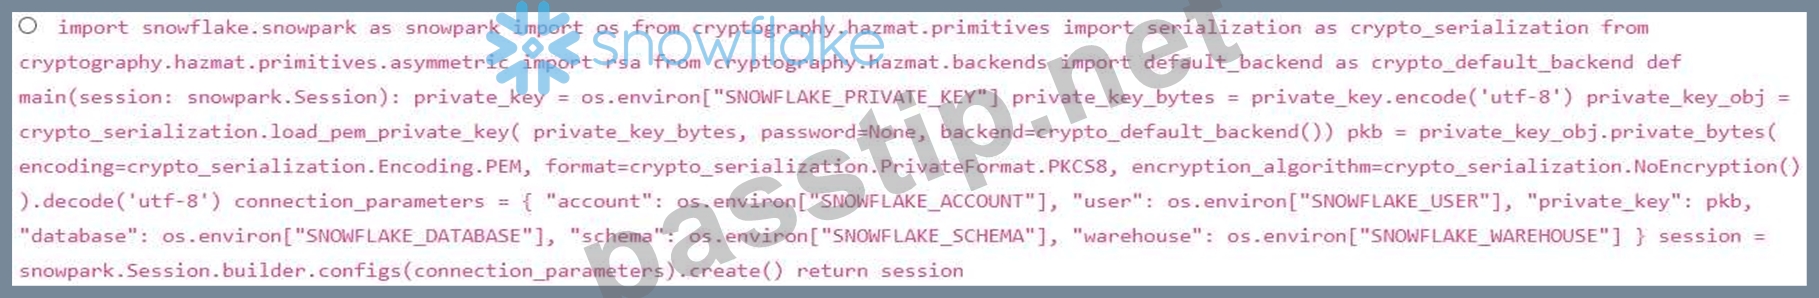
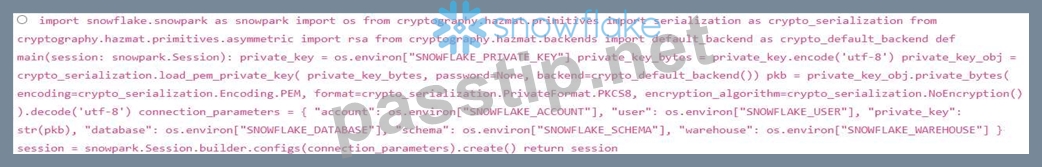
You are developing a Snowpark Python application that connects to Snowflake using key pair authentication. You have the private key stored securely in an environment variable named 'SNOWFLAKE PRIVATE KEY. Which of the following code snippets correctly establishes a Snowpark session using this method, assuming all other necessary connection parameters (account, user, database, schema, warehouse) are also set as environment variables?



정답:B
설명:
Option D is correct because it properly retrieves the private key from the environment variable, decodes the PEM format, and passes it to the connection parameters after converting the key object to a string. It uses the cryptography library to handle the private key securely, which is required for key pair authentication. The code snippet decodes the private key using cryptography library and creates a string, which then is passed to the connection parameters to create a session. Option A fails to use the cryptography library and just passes the private key directly. Option B is incorrect because it doesn't use the 'configs' method, which is the correct way to pass all connection parameters at once. Option C doesn't encode the private key properly, and does not convert to string after decoding using cryptography. Option E does convert to string, but is not secure as the private key is directly passed without decoding it using the cryptography library.
질문 # 58
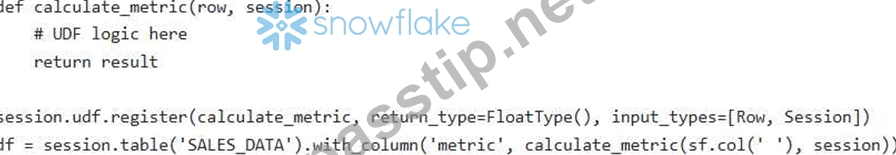
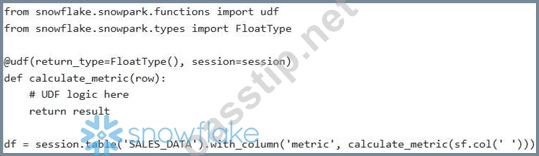
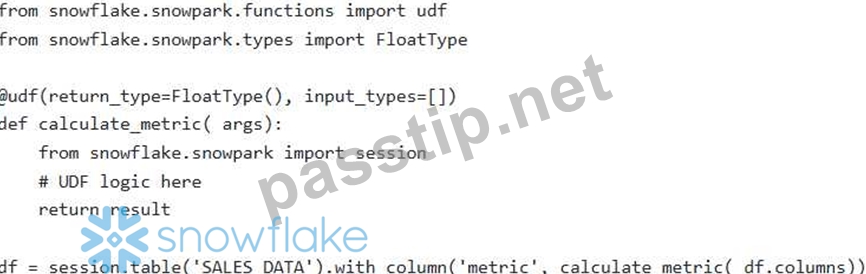
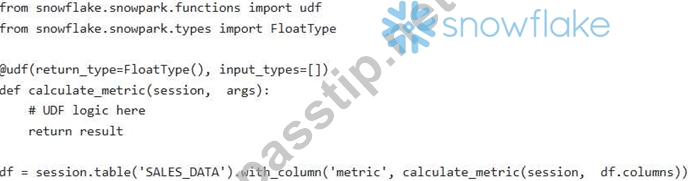
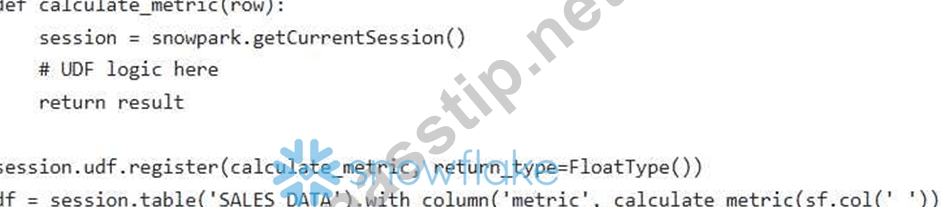
You are using Snowpark Python to create a DataFrame from an existing Snowflake table "SALES DATA'. You want to apply a user- defined function (UDF) to each row of the DataFrame to calculate a custom sales metric. The UDF requires access to the 'session' object. Which of the following approaches is correct for defining and applying the UDF in Snowpark?
정답:C
설명:
Option E is the correct approach. To access the session object from within the UDF, you can import it when registering the UDF with the session. It should be imported inside the function and use the decorator. The input_types parameter should be set to 0, since this allows for session access.
질문 # 59
You are tasked with processing a Snowpark DataFrame named 'orders df that contains order information. The DataFrame includes the following columns: 'order _ id' (INTEGER), 'customer_id' (INTEGER), 'order_date' (DATE), 'order_total' (STRING), and 'discount_code' (STRING). The 'order_total' column contains values with leading dollar signs and commas (e.g., '$1 ,234.56'). The column can contain codes like 'SAVEIO', 'SAVE20', or be NULL. Your goal is to create a new DataFrame 'transformed_df that includes the following transformations: 1 . Convert the 'order_total' column to a numeric value (DOUBLE) after removing the dollar signs and commas. 2. Apply a discount based on the 'discount_code'. If the 'discount_code' is 'SAVEIO', apply a 10% discount; if it's 'SAVE20', apply a 20% discount. If the 'discount_code' is NULL or any other value, apply no discount (0%). 3. Calculate the 'final_total' after applying the discount. Which of the following code snippets correctly and efficiently implements these transformations using Snowpark?





정답:E
설명:
Option A correctly implements all transformations efficiently using Snowpark functions. It converts 'order_totar to a numeric value, applies the discount based on the using 'when' , and calculates the 'final_totar. It avoids using IJDFs or 'collect' operations, which can be less efficient. Using 'lit' with numeric values isn't necessary or best practice, so option B is less preferable. Option C attempts to use a IJDF, which is less efficient than using built-in Snowpark functions. Also 'to_number' and for IJDF is not required. Option D calculates the discount amount directly instead of the discount rate. Option E attempts to use 'rdd.map' which is not available and it's generally advised against as it removes parallelism.
질문 # 60
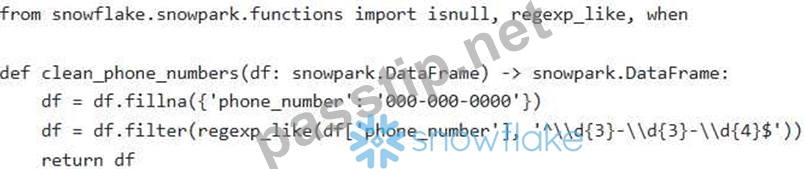
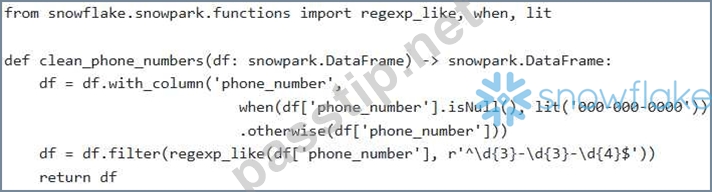
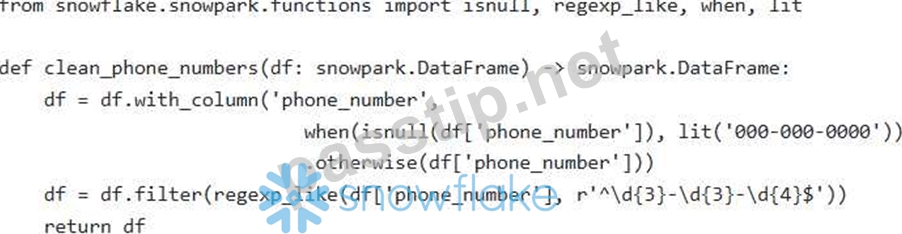
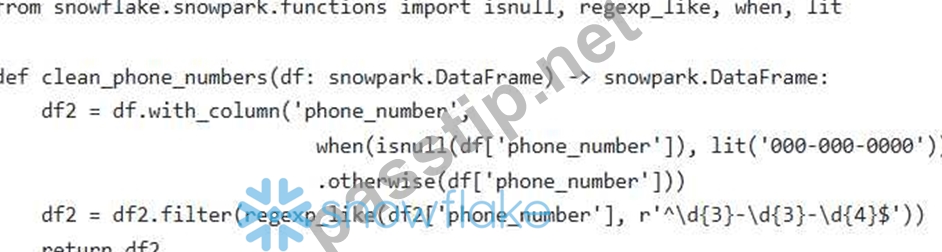
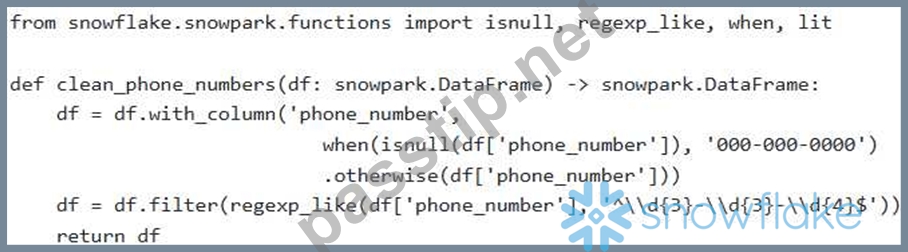
You are working with a Snowpark DataFrame containing customer data, including a 'phone_number' column. Some phone numbers are missing or have incorrect formats. You want to impute missing values with a default phone number '000-000-0000' and remove any phone numbers that do not match the pattern 'XXX-XXX-XXXX' using Snowpark Python. Which of the following code snippets achieves this most efficiently?
정답:C
설명:
Option E is correct. It uses 'when' with 'isnull' to impute missing phone numbers and 'regexp_like' to filter out invalid formats. Options A and B are similar but less explicit. Option C omits 'lit', which makes the code incorrect as it won't work with Snowpark. Option D does not use 'lit' and also 'fillna' will give an exception if datatypes doesnt match
질문 # 61
You are tasked with deploying a set of Python UDFs and UDTFs to a Snowflake environment using Snowpark. These functions rely on several external Python packages and need to be versioned and managed effectively. Which of the following strategies provides the MOST robust and scalable solution for managing dependencies and deploying these functions in a reproducible manner?
정답:A,D
설명:
Options B and C provide the most robust and scalable solution. Creating a conda environment specification file (environment.yml) allows for precise control over dependencies and their versions. Both allow other devs to work with the same environment. Uploading the yml allows to include it as a part of snowflake's udfs and udtfs. The difference is whether it can be done directly in snowpark (B) or through the CLI (C). Option A is less manageable as dependencies grow and is prone to manual errors. Option D is not the correct way to handle dependencies for UDFs/UDTFs; the 'imports' parameter is used for data files and other resources, not for installing Python packages.
질문 # 62
......
PassTIP에서 제공되는Snowflake SPS-C01인증시험덤프의 문제와 답은 실제시험의 문제와 답과 아주 유사합니다. 아니 거이 같습니다. 우리PassTIP의 덤프를 사용한다면 우리는 일년무료 업뎃서비스를 제공하고 또 100%통과 율을 장담합니다. 만약 여러분이 시험에서 떨어졌다면 우리는 덤프비용전액을 환불해드립니다.
SPS-C01시험자료: https://www.passtip.net/SPS-C01-pass-exam.html
참고: PassTIP에서 Google Drive로 공유하는 무료 2026 Snowflake SPS-C01 시험 문제집이 있습니다: https://drive.google.com/open?id=1xhMDGwotUdqSXnvnmHe5Ef70XHVo0G_X