Databricks Databricks-Certified-Data-Engineer-Associate Online Prüfung & Databricks-Certified-Data-Engineer-Associate Online Prüfungen

Außerdem sind jetzt einige Teile dieser Fast2test Databricks-Certified-Data-Engineer-Associate Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1e0sBJECmXM1vek81rbGYBNDSzkremlDH
Gehen Sie einen entscheidenden Schritt weiter. Mit der Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierung erhalten Sie einen Nachweis Ihrer besonderen Qualifikationen und eine Anerkennung für Ihr technisches Fachwissen. Databricks bietet eine Reihe verschiedener Databricks-Certified-Data-Engineer-Associate Zertifizierungsprogramme für professionelle Benutzer an. Untersuchungen haben gezeigt, dass zertifizierte Fachleute häufig mehr verdienen als ihre Kollegen ohne Zertifizierung.
Die GAQM Databricks-Certified-Data-Engineer-Associate (Databricks Certified Data Engineer Associate) Certification Exam ist eine hochbegehrte Zertifizierung im Bereich der Datenengineering. Diese Zertifizierung soll die Fähigkeiten und Kenntnisse validieren, die erforderlich sind, um Datenpipelines und Datensolutions auf der Databricks-Plattform zu entwerfen, zu erstellen und zu warten. Die Prüfung richtet sich an Fachleute, die ein starkes Verständnis für Datenengineering-Konzepte haben und Erfahrung mit Databricks haben.
>> Databricks Databricks-Certified-Data-Engineer-Associate Online Prüfung <<
Databricks Databricks-Certified-Data-Engineer-Associate Online Prüfungen - Databricks-Certified-Data-Engineer-Associate Fragenkatalog
Die Schulungsunterlagen zur Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung von Fast2test sind unvergleichbar. Das hat nicht nur mit der Qualität zu tun. Am wichitgsten ist es, dass Die Schulungsunterlagen zur Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung von Fast2test mit allen IT-Zertifizierungen im Einklang sind. So kümmern sich viele Kandidaten um uns. Sie glauben in uns und sind von uns abhängig. Das hat genau unsere Stärke reflektiert. Sie werden sicher Ihren Freuden nach dem Kauf unserer Produkte Fast2test empfehlen. Denn es kann Ihnen wirklich sehr helfen.
Die Associate -Zertifizierung von Databricks Certified Data Engineer ist für Personen, die mit Big Data arbeiten und skalierbare Datenpipelines erstellen möchten. Die Zertifizierungsprüfung deckt eine Reihe von Themen ab, einschließlich Datenmodellierung, Datenaufnahme, Datenumwandlung, Datenspeicherung und Datenverarbeitung. Die Kandidaten werden auch auf ihr Wissen über Apache Spark, eine beliebte Open-Source-Datenverarbeitungs-Engine und Datenbanken Unified Analytics-Plattform getestet.
Databricks Certified Data Engineer Associate Exam Databricks-Certified-Data-Engineer-Associate Prüfungsfragen mit Lösungen (Q186-Q191):
186. Frage
Which type of workloads are compatible with Auto Loader?
- A. Streaming workloads
- B. Machine learning workloads
- C. Serverless workloads
- D. Batch workloads
Antwort: A
187. Frage
A data engineer has developed a data pipeline to ingest data from a JSON source using Auto Loader, but the engineer has not provided any type inference or schema hints in their pipeline. Upon reviewing the data, the data engineer has noticed that all of the columns in the target table are of the string type despite some of the fields only including float or boolean values.
Which of the following describes why Auto Loader inferred all of the columns to be of the string type?
- A. JSON data is a text-based format
- B. There was a type mismatch between the specific schema and the inferred schema
- C. Auto Loader cannot infer the schema of ingested data
- D. Auto Loader only works with string data
- E. All of the fields had at least one null value
Antwort: A
Begründung:
JSON data is a text-based format that represents data as a collection of name-value pairs. By default, when Auto Loader infers the schema of JSON data, it treats all columns as strings. This is because JSON data can have varying data types for the same column across different files or records, and Auto Loader does not attempt to reconcile these differences. For example, a column named "age" may have integer values in some files, but string values in others. To avoid data loss or errors, Auto Loader infers the column as a string type.
However, Auto Loader also provides an option to infer more precise column types based on the sample data.
This option is called cloudFiles.inferColumnTypes and it can be set to true or false. When set to true, Auto Loader tries to infer the exact data types of the columns, such as integers, floats, booleans, or nested structures. When set to false, Auto Loader infers all columns as strings. The default value of this option is false. References: Configure schema inference and evolution in Auto Loader, Schema inference with auto loader (non-DLT and DLT), Using and Abusing Auto Loader's Inferred Schema, Explicit path to data or a defined schema required for Auto loader.
188. Frage
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.
The code block used by the data engineer is below:
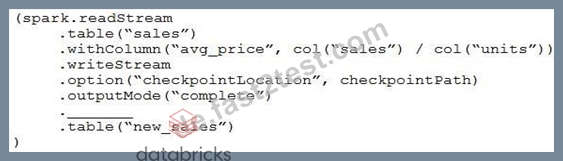
The data engineer only wants the query to process all of the available data in as many batches as required.
Which line of code should the data engineer use to fill in the blank?
- A. trigger(once=True)
- B. trigger(availableNow=True)
- C. trigger(processingTime="once")
- D. trigger(continuous="once")
Antwort: B
189. Frage
A Lakeflow Jobs workflow fails at the last task because of an error in a notebook task. This workflow is scheduled to run daily. The data engineer fixes the notebook and wants to rerun the pipeline. This workflow is very compute-intensive and expensive to run. Which action should the data engineer take in order to minimize downtime and compute cost?
- A. Restart the cluster
- B. Re-run the entire workflow
- C. Switch to another cluster
- D. Repair run
Antwort: D
Begründung:
Repair run allows rerunning only the failed task and any dependent tasks instead of executing the entire workflow again, minimizing compute cost and downtime while preserving the original run context.
190. Frage
A data engineering team has two tables. The first table march_transactions is a collection of all retail transactions in the month of March. The second table april_transactions is a collection of all retail transactions in the month of April. There are no duplicate records between the tables.
Which of the following commands should be run to create a new table all_transactions that contains all records from march_transactions and april_transactions without duplicate records?
- A. CREATE TABLE all_transactions AS
SELECT * FROM march_transactions
OUTER JOIN SELECT * FROM april_transactions; - B. CREATE TABLE all_transactions AS
SELECT * FROM march_transactions
UNION SELECT * FROM april_transactions; - C. CREATE TABLE all_transactions AS
SELECT * FROM march_transactions
MERGE SELECT * FROM april_transactions; - D. CREATE TABLE all_transactions AS
SELECT * FROM march_transactions
INNER JOIN SELECT * FROM april_transactions; - E. CREATE TABLE all_transactions AS
SELECT * FROM march_transactions
INTERSECT SELECT * from april_transactions;
Antwort: B
Begründung:
Explanation
To create a new table all_transactions that contains all records from march_transactions and april_transactions without duplicate records, you should use the UNION operator, as shown in option B. This operator combines the result sets of the two tables while automatically removing duplicate records.
191. Frage
......
Databricks-Certified-Data-Engineer-Associate Online Prüfungen: https://de.fast2test.com/Databricks-Certified-Data-Engineer-Associate-premium-file.html
- Databricks-Certified-Data-Engineer-Associate Prüfungsfragen, Databricks-Certified-Data-Engineer-Associate Fragen und Antworten, Databricks Certified Data Engineer Associate Exam 🙉 ➤ www.zertfragen.com ⮘ ist die beste Webseite um den kostenlosen Download von ➥ Databricks-Certified-Data-Engineer-Associate 🡄 zu erhalten 🎩Databricks-Certified-Data-Engineer-Associate Prüfungs
- Databricks-Certified-Data-Engineer-Associate Prüfungsunterlagen 👪 Databricks-Certified-Data-Engineer-Associate Prüfungs 🏖 Databricks-Certified-Data-Engineer-Associate Musterprüfungsfragen 🥖 Geben Sie ➠ www.itzert.com 🠰 ein und suchen Sie nach kostenloser Download von [ Databricks-Certified-Data-Engineer-Associate ] 🛀Databricks-Certified-Data-Engineer-Associate Testantworten
- Databricks-Certified-Data-Engineer-Associate Prüfungsfragen, Databricks-Certified-Data-Engineer-Associate Fragen und Antworten, Databricks Certified Data Engineer Associate Exam ⬜ Erhalten Sie den kostenlosen Download von 「 Databricks-Certified-Data-Engineer-Associate 」 mühelos über ☀ www.itzert.com ️☀️ 🥿Databricks-Certified-Data-Engineer-Associate Prüfungsfrage
- Databricks-Certified-Data-Engineer-Associate aktueller Test, Test VCE-Dumps für Databricks Certified Data Engineer Associate Exam 🧽 Suchen Sie jetzt auf ▛ www.itzert.com ▟ nach 「 Databricks-Certified-Data-Engineer-Associate 」 um den kostenlosen Download zu erhalten 🤟Databricks-Certified-Data-Engineer-Associate PDF Demo
- 100% Garantie Databricks-Certified-Data-Engineer-Associate Prüfungserfolg 🌇 Suchen Sie auf ➽ www.zertpruefung.ch 🢪 nach kostenlosem Download von [ Databricks-Certified-Data-Engineer-Associate ] 😾Databricks-Certified-Data-Engineer-Associate Prüfungs
- Databricks-Certified-Data-Engineer-Associate aktueller Test, Test VCE-Dumps für Databricks Certified Data Engineer Associate Exam 📌 URL kopieren [ www.itzert.com ] Öffnen und suchen Sie ☀ Databricks-Certified-Data-Engineer-Associate ️☀️ Kostenloser Download 🎊Databricks-Certified-Data-Engineer-Associate Kostenlos Downloden
- Databricks-Certified-Data-Engineer-Associate Übungsfragen: Databricks Certified Data Engineer Associate Exam - Databricks-Certified-Data-Engineer-Associate Dateien Prüfungsunterlagen ⛅ Öffnen Sie die Webseite ⇛ www.pruefungfrage.de ⇚ und suchen Sie nach kostenloser Download von ⇛ Databricks-Certified-Data-Engineer-Associate ⇚ 👭Databricks-Certified-Data-Engineer-Associate Testfagen
- 100% Garantie Databricks-Certified-Data-Engineer-Associate Prüfungserfolg 🌱 Suchen Sie jetzt auf ( www.itzert.com ) nach ⏩ Databricks-Certified-Data-Engineer-Associate ⏪ und laden Sie es kostenlos herunter 🚎Databricks-Certified-Data-Engineer-Associate Musterprüfungsfragen
- Databricks-Certified-Data-Engineer-Associate Online Test 📰 Databricks-Certified-Data-Engineer-Associate Prüfungsfrage 😃 Databricks-Certified-Data-Engineer-Associate Kostenlos Downloden ⚛ Suchen Sie jetzt auf ➡ www.deutschpruefung.com ️⬅️ nach ⮆ Databricks-Certified-Data-Engineer-Associate ⮄ und laden Sie es kostenlos herunter 🍇Databricks-Certified-Data-Engineer-Associate Lerntipps
- Databricks-Certified-Data-Engineer-Associate Prüfungsfrage 📝 Databricks-Certified-Data-Engineer-Associate Deutsch 🌑 Databricks-Certified-Data-Engineer-Associate Unterlage 📻 Suchen Sie auf der Webseite ( www.itzert.com ) nach ▶ Databricks-Certified-Data-Engineer-Associate ◀ und laden Sie es kostenlos herunter 💰Databricks-Certified-Data-Engineer-Associate PDF Demo
- Databricks-Certified-Data-Engineer-Associate Fragen - Antworten - Databricks-Certified-Data-Engineer-Associate Studienführer - Databricks-Certified-Data-Engineer-Associate Prüfungsvorbereitung 🌄 Geben Sie ⏩ www.echtefrage.top ⏪ ein und suchen Sie nach kostenloser Download von ⮆ Databricks-Certified-Data-Engineer-Associate ⮄ 🕋Databricks-Certified-Data-Engineer-Associate Testantworten
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! Laden Sie die vollständige Version der Fast2test Databricks-Certified-Data-Engineer-Associate Prüfungsfragen kostenlos herunter: https://drive.google.com/open?id=1e0sBJECmXM1vek81rbGYBNDSzkremlDH