BTW, DOWNLOAD part of FreePdfDump SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1wIGKf9iXSlX487IR1EMKcQV5syRHkGtd
If you don't have enough time to study for your Snowflake Snowflake Certified SnowPro Specialty - Snowpark exam, FreePdfDump provides Snowflake SPS-C01 Pdf questions. You may quickly download Snowflake SPS-C01 exam questions in PDF format on your smartphone, tablet, or desktop. You can Print Snowflake SPS-C01 pdf questions and answers on paper and make them portable so you can study on your own time and carry them wherever you go. Snowflake evolves swiftly, and a practice test may become obsolete within weeks of its publication. We provide free updates for Snowflake SPS-C01 Exam Questions for three months after the purchase to ensure you are studying the most recent Snowflake solutions.
| Section | Objectives |
|---|---|
| Topic 1: DataFrame Operations and Data Processing | - Data transformation workflows
|
| Topic 2: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 3: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 4: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 5: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Topic 6: Data Engineering with Snowpark | - Pipeline development
|
>> Latest SPS-C01 Exam Online <<
Our SPS-C01 exam cram is famous for instant access to download, and you can receive the downloading link and password within ten minutes, and if you don’t receive, you can contact us. Moreover, SPS-C01 exam materials contain both questions and answers, and it’s convenient for you to check the answers after practicing. We offer you free demo to have a try before buying, so that you can know what the complete version is like. We offer you free update for 365 days for SPS-C01 Exam Dumps, so that you can obtain the latest information for the exam, and the latest version for SPS-C01 exam dumps will be sent to your email automatically.
NEW QUESTION # 22
You have a Snowpark DataFrame containing product information, and you want to persist it into a Snowflake table named PRODUCTS. You need to handle the following scenarios: 1. If the table 'PRODUCTS does not exist, create it. 2. If the table PRODUCTS' exists, append the data from 'df_products' to it. Which of the following methods can achieve this?





Answer: B
Explanation:
Option B is the correct solution. The 'mode('append')' ensures that the data from 'df_products' is appended to the 'PRODUCTS' table if it exists. If the table does not exist, Snowflake will create it automatically. Option A will create the table if it doesn't exist, but will throw an error if it does. Option C will overwrite the table. Option D is unnecessarily complex and inefficient, first collecting the data to the driver then creating a new DataFrame. Option E doesn't exist in Snowpark API.
NEW QUESTION # 23
You have two Snowflake tables, 'customers' and 'orders'. The 'customers' table contains customer information, including a 'customer id' and 'region'. The 'orders' table contains order information, including 'order id', 'customer id', and 'order amount'. You need to create a Snowpark DataFrame that joins these two tables on 'customer id' and calculates the total order amount per region. However, some customers may not have any orders, and you want to include all customers in the result, with a total order amount of 0 for those without orders. Which of the following Snowpark code snippets will achieve this goal MOST efficiently, assuming 'customers_df and 'orders_ff are pre-existing Snowpark DataFrames representing the respective tables?





Answer: C
Explanation:
Option B is the most efficient because it uses 'coalesce' directly within the 'agg' function, avoiding a separate .na.fill' operation which could be less optimized in Snowpark. It handles the null values resulting from the left outer join correctly, ensuring that customers without orders have a 0 total order amount. Options A and C might work in some contexts, but are less idiomatic and potentially less efficient. Options D and E are less concise and may not be the most optimal way to express the desired logic in Snowpark.
NEW QUESTION # 24
You are profiling a Snowpark application that uses a combination of SQL queries and Python UDFs. You observe that a particular stage involving a UDF is taking significantly longer than expected. You suspect that the UDF's performance is the bottleneck. Which of the following steps would be the MOST comprehensive approach to diagnose and address the performance issue?
Answer: A
Explanation:
Option B offers the most structured and informed approach. The query profile provides detailed insights into execution times for each stage, including UDF execution. Analyzing the UDF code then allows for targeted optimization. While A, C, and D are potentially helpful, they are less systematic. E is premature without proper diagnosis. The query profile in Snowflake is the most comprehensive and targeted approach to the performance troubleshooting. Also it is important to understand the code inside UDF.
NEW QUESTION # 25
A data engineering team is migrating a series of complex SQL queries into Snowpark Python to leverage vectorized UDFs and optimize performance. They currently use several Common Table Expressions (CTEs) within their SQL queries. What is the most efficient and Pythonic approach to create a Snowpark DataFrame representing the result of a complex SQL query with multiple CTEs, minimizing code redundancy and maintaining readability?
Answer: C
Explanation:
Option D is the most efficient. Using with the complete SQL query, including CTEs, leverages Snowflake's query optimizer to handle the CTEs efficiently. While rewriting in Snowpark DataFrame API (Option E) might eventually be desirable for full Snowpark utilization, it's a more significant undertaking. Options A and B introduce inefficiencies (string manipulation, temporary tables) or unnecessary complexity (separate DataFrames and joins). Option C is also less performant than submitting the whole query in one go.
NEW QUESTION # 26
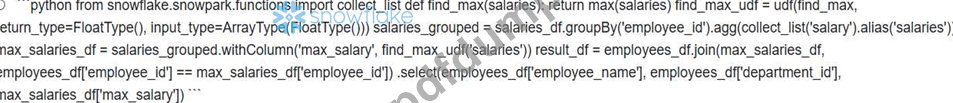
You have two Snowpark DataFrames: 'employees_df with columns 'employee_id' (INTEGER), 'employee_name' (STRING), 'department_id' (INTEGER), and 'salaries_df' with columns 'employee_id' (INTEGER), "salary' (FLOAT), 'effective_date' (DATE). You need to create a new DataFrame that contains the employee's name, department, and the highest salary they have ever received. Assuming there can be multiple salary entries for the same employee with different 'effective date' values, which of the following Snowpark code snippets would correctly and efficiently solve this problem?




Answer: B
Explanation:
Option B is the most efficient solution. It first calculates the maximum salary for each employee in the DataFrame using 'groupBy' and 'max' , then joins this aggregated result with the 'employees_df to retrieve the employee's name and department. This approach avoids unnecessary data shuffling and minimizes the amount of data processed in the join. Option A performs the join before the aggregation, which can be less efficient. Options C and E use window functions, which are more complex and may not be as efficient for this simple aggregation. Option D uses a UDF and 'collect_list' , which can be very inefficient due to data transfer and UDF overhead.
NEW QUESTION # 27
......
Getting Snowflake certification is a good way for you to access to IT field. But you may find that real test questions are difficult and professional and you have no time to prepare the SPS-C01 valid test. So it is time that our latest dumps torrent and training materials help you get high passing score in the process of SPS-C01 practice test at your first attempt.
SPS-C01 Dumps Torrent: https://www.freepdfdump.top/SPS-C01-valid-torrent.html
What's more, part of that FreePdfDump SPS-C01 dumps now are free: https://drive.google.com/open?id=1wIGKf9iXSlX487IR1EMKcQV5syRHkGtd