BONUS!!! Download part of DumpsQuestion AI-300 dumps for free: https://drive.google.com/open?id=1gHQtpFiy1wlRZO-jJELmwPxnZdJ53lml
The software version is one of the three versions of our AI-300 actual exam, which is designed by the experts from our company. The functions of the software version are very special. For example, the software version can simulate the real exam environment. If you buy our AI-300 study questions, you can enjoy the similar real exam environment. In addition, the software version of our study materials is not limited to the number of the computer. So do not hesitate and buy our AI-300 Preparation exam, you will benefit a lot from it and pass the AI-300 exam for sure.
| Section | Objectives |
|---|---|
| Topic 1: Design and implement an MLOps infrastructure | - Manage environments, data stores, and model registries - Configure source control, CI/CD pipelines, and automation for ML workflows - Set up Azure Machine Learning workspace and compute targets - Implement security, governance, and compliance for MLOps |
| Topic 2: Implement machine learning model lifecycle and operations | - Train, register, and version models using Azure Machine Learning - Retrain, update, and manage model versions in production - Deploy models to real-time and batch endpoints - Monitor model performance, data drift, and operational health |
| Topic 3: Optimize generative AI systems and model performance | - Fine-tune and distill models for specific use cases - Tune prompts, system messages, and grounding strategies - Implement cost management and scaling strategies for GenAI workloads - Optimize inference performance, caching, and throughput |
| Topic 4: Design and implement a GenAIOps infrastructure | - Manage API keys, rate limits, and responsible AI guardrails - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Configure prompt orchestration, prompt flows, and agent frameworks - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search |
| Topic 5: Implement generative AI quality assurance and observability | - Evaluate generative AI outputs for quality, safety, and grounding - Monitor latency, token usage, cost, and error rates - Conduct red teaming, adversarial testing, and content filtering - Implement logging, tracing, and telemetry for GenAI applications |
You can also be a part of this wonderful community. To do this you just need to pass the Microsoft AI-300 certification exam. Are you ready to accept this challenge? Looking for the proven and easiest way to crack the Microsoft AI-300 Certification Exam? If your answer is yes then you do not need to go anywhere. Just download DumpsQuestion AI-300 exam practice questions and start Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam preparation without wasting further time.
NEW QUESTION # 53
Drag and Drop Question
You are fine-tuning an LLM base model by using Microsoft Foundry. You have a labeled dataset of customer emails.
You need to improve task-specific prediction accuracy so that the model can be tested and deployed later.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.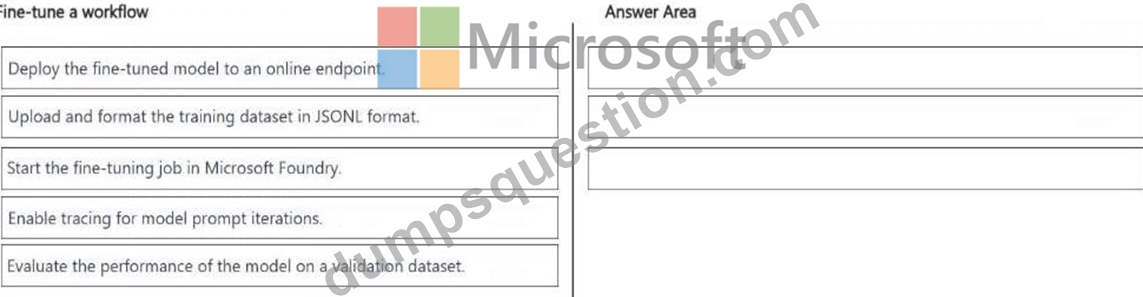
Answer:
Explanation: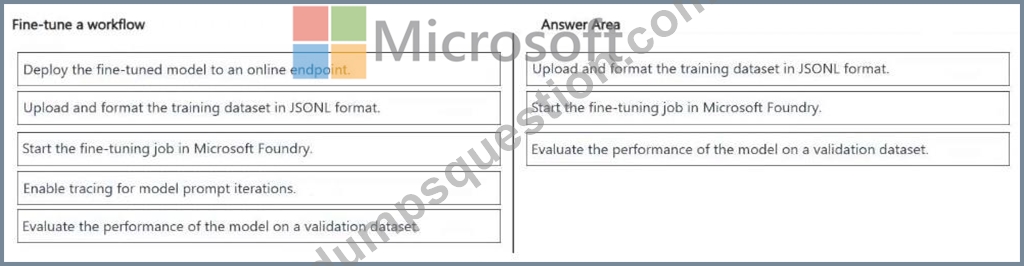
Explanation:
Step 1: Upload and format the training dataset in JSON format.
Upload and Format Training Data (JSONL)
You need to format your labeled emails so the model can learn from them.
Format Requirements: In Microsoft Foundry, training and validation files must be prepared in a JSONL (JSON Lines) format.
Structure: Each line should represent a single conversation or input-output pair. For email tasks (like classification, summarization, or routing), this usually consists of a messages array.
Step 2: Start the fine-tuning jobs in Microsoft Foundry.
Start Supervised Fine-Tuning (SFT) Jobs
Once your data is uploaded to a private Azure storage account or directly through the UI, you will initiate the training process.
Technique: Choose Supervised Fine-Tuning (SFT). SFT is designed for teaching models specific tasks (like specific tone alignment or labeling) on labeled data.
Execution: Through the Azure AI Foundry Model Catalog, select your base model (e.g., GPT-4o- mini or Llama Scout), upload your train/validation JSONL files, and submit the job.
Experimentation: Foundry also supports hyperparameter settings (like learning rates and batch sizes) which you can tweak if needed.
Step 3: Evaluate the performance of the model on a validation dataset.
Evaluate and Deploy
Fine-tuning is an iterative process. Before deploying to a production environment, you must evaluate the model to ensure it meets your specific task accuracy goals.
Evaluation: Use Foundry's built-in evaluation tools and your validation dataset to benchmark the fine-tuned student model against the baseline base model.
Deployment: Once task-specific prediction accuracy is confirmed using validation metrics, you can host and deploy the model directly on Azure AI Foundry for your applications to consume.
Reference:
https://devblogs.microsoft.com/foundry/beyond-the-prompt-why-and-how-to-fine-tune-your-own-models/
NEW QUESTION # 54
You manage an Azure Machine Learning workspace. You have a folder that contains a CSV file. The folder is registered as a folder data asset.
You plan to use the folder data asset for data wrangling during interactive development.
You need to access and load the folder data asset into a Pandas data frame.
Which method should you use to achieve this goal?
Answer: B
Explanation:
Azure Machine Learning distinguishes between uri_folder, uri_file, and mltable data assets. Because the registered asset in this scenario is a folder data asset containing CSV data , the appropriate MLTable API is mltable.from_delimited_files(). Microsoft documents that a registered uri_folder containing CSV files can be retrieved through MLClient, its storage path supplied as a folder path, and then passed to mltable.
from_delimited_files(). The resulting MLTable object can subsequently be materialized into a Pandas DataFrame by calling to_pandas_dataframe().
A representative workflow is conceptually:
tbl = mltable.from_delimited_files(paths=[{ " folder " : data_asset.path}]) followed by:
df = tbl.to_pandas_dataframe()
mltable.load() is primarily appropriate when loading an existing MLTable definition , such as a registered table data asset containing an MLTable file. from_parquet_files() is intended for Parquet-formatted data, while from_delta_lake() targets Delta Lake data sources. Neither matches the CSV-based folder described here. Microsoft also identifies uri_folder as the appropriate asset type for folders containing CSV or Parquet files used with Pandas or Spark.
Study Guide Reference: Design and implement an MLOps infrastructure - Azure Machine Learning data assets, MLTable APIs, interactive data access, and Pandas-based data wrangling.
Continue with Azure ML data access
NEW QUESTION # 55
Drag and Drop Question
A customer-facing web application uses a foundational model deployed through Microsoft Foundry.
A new model version must be introduced and validated without disrupting production traffic.
You need to deploy the new version by using a safe promotion strategy.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.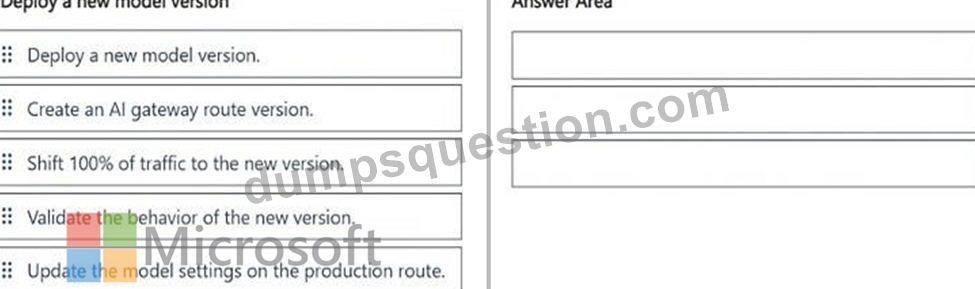
Answer:
Explanation: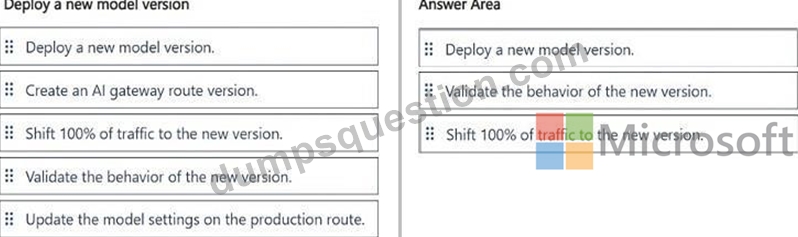
NEW QUESTION # 56
An organization maintains separate Azure Machine Learning workspaces for development and production.
Both environments must use the same validated assets without duplicating them.
Assets must be shared across workspaces while maintaining centralized governance and version control.
You need to enable reuse of assets across workspaces without copying them.
What should you do?
Answer: A
Explanation:
Microsoft ' s Azure Machine Learning documentation on registries describes them as organization-level repositories that sit above individual workspaces. When you publish an asset such as a model, environment, or component to an Azure ML registry, it becomes accessible to any workspace in any subscription within the same Azure tenant, all without physical duplication. The registry maintains a single source of truth with full version history. Option A (Git integration) synchronizes code, not compiled ML artifacts. Option B (pipeline component) packages a reusable pipeline step but does not solve cross-workspace sharing. Option C (shared environment) addresses runtime dependencies, not the full range of ML assets. The registry is the purpose- built solution for centralized governance, version control, and cross-workspace asset sharing - the Microsoft- recommended pattern for mature MLOps organizations.
Microsoft Learn Reference Topic: Share assets across workspaces with Azure Machine Learning registries
NEW QUESTION # 57
A team manages prompts that are used by a generative AI application built on Microsoft Foundry. Multiple developers contribute prompt updates, and changes must be reviewed and tracked over time.
The team requires that:
Prompt changes are reviewed before being applied to the version in production.
Previous prompt versions can be restored if issues occur.
Prompt updates follow the same governance practices as the application code.
You need to implement a controlled process for managing and updating prompts in production.
How should you manage prompt updates to meet the requirements? To answer, move the appropriate actions to the correct requirements. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content. NOTE: Each correct selection is worth one point.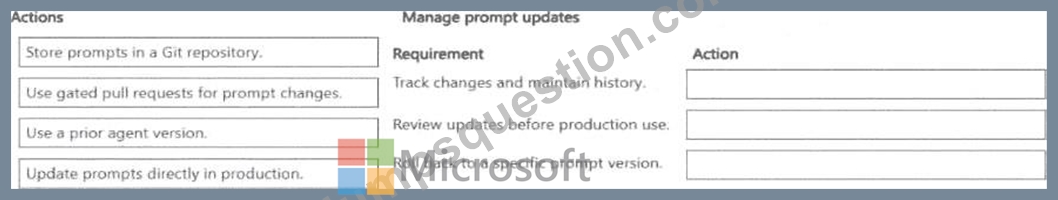
Answer:
Explanation: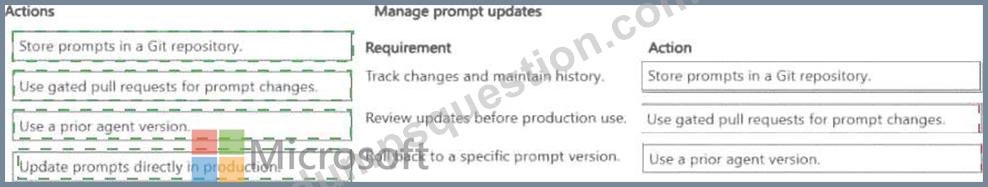
Explanation:
All three requirements point to Git as the underlying mechanism, but each uses a different Git capability. For reviewing changes before production: a branch-based workflow where prompt changes are made on feature branches and merged to the main branch only after pull request approval enforces the review gate. For restoring previous versions: Git ' s commit history and tag system provide a precise, immutable record of every prompt state, and a git revert or checkout to a specific commit SHA restores any prior version instantly.
For governance parity with application code: by storing prompts in the same Git repository as application code, all the same CI/CD, branch protection, code review, and audit trail policies apply automatically. The alternatives such as Blob Storage or embedded configuration files lack native review workflows, branch protection, and full audit history.
Microsoft Learn Reference Topic: Prompt management and versioning with Git integration in Microsoft Foundry
NEW QUESTION # 58
......
With the development of science and technology, getting AI-300 certification as one of the most powerful means to show your ability has attracted more and more people to be engaged in the related exams. Thus there is no doubt that candidates for the exam are facing ever-increasing pressure of competition. Since AI-300 Certification has become a good way for all of the workers to prove how capable and efficient they are. But it is universally accepted that only the studious people can pass the complex AI-300 exam.
Latest AI-300 Exam Cram: https://www.dumpsquestion.com/AI-300-exam-dumps-collection.html
DOWNLOAD the newest DumpsQuestion AI-300 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1gHQtpFiy1wlRZO-jJELmwPxnZdJ53lml