What's more, part of that PassReview NCP-BC-7.5 dumps now are free: https://drive.google.com/open?id=1yvgMcjNrgiychYWjB9YCvC3_aoRAfzUx
Our passing rate is 98%-100% and there is little possibility for you to fail in the exam. But if you are unfortunately to fail in the exam we will refund you in full immediately. Some people worry that if they buy our NCP-BC-7.5 exam questions they may fail in the exam and the procedure of the refund is complicated. But we guarantee to you if you fail in we will refund you in full immediately and the process is simple. If only you provide us the screenshot or the scanning copy of the NCP-BC-7.5 failure marks we will refund you immediately. If you have doubts or other questions please contact us by emails or contact the online customer service and we will reply you and solve your problem as quickly as we can. So feel relieved when you buy our NCP-BC-7.5 guide torrent.
| Section | Objectives |
|---|---|
| Topic 1: Nutanix Disaster Recovery Architecture | - Protection Domains - Replication Types (Sync/Async) - Nutanix Leap Overview |
| Topic 2: Recovery Operations | - Failover and Failback Procedures - Recovery Plans and Orchestration - Test Recovery Workflows |
| Topic 3: Disaster Recovery Fundamentals | - DR Concepts (RPO, RTO, SLAs) - Business Continuity Principles |
| Topic 4: Prism Central Management | - DR Monitoring and Operations - Cluster and Site Management |
| Topic 5: Data Protection and Backup Integration | - Snapshot Management - Backup Solutions Integration |
>> NCP-BC-7.5 Test Topics Pdf <<
As everybody knows, competitions appear ubiquitously in current society. In order to live a better live, people improve themselves by furthering their study, as well as increase their professional NCP-BC-7.5 skills. With so many methods can boost individual competitiveness, people may be confused, which can really bring them a glamorous work or brighter future? We are here to tell you that a NCP-BC-7.5 Certification definitively has everything to gain and nothing to lose for everyone.
NEW QUESTION # 86
Which combination of Replication Schedules within the same Recovery Plan will cause the recovery to fail?
Answer: B
Explanation:
A Recovery Plan in Nutanix is the orchestration engine that defines the power-on sequence, network mappings, and script execution for disaster recovery. While a single cluster can support various types of replication-Asynchronous, NearSync, and Synchronous-there are strict architectural limits on how these can be mixed within a single automated plan.
The primary conflict arises when mixing Synchronous (0 RPO) schedules with snapshot-based Asynchronous or NearSync schedules. Synchronous replication is an " Active-Standby " or " Active-Active " storage state where the destination site already has the data in a " mounted " but inactive container. In contrast, Asynchronous and NearSync recovery involve " restoring " a VM from a specific recovery point (snapshot), which includes registering the VM and attaching the disks during the failover process. Because the orchestration logic for a Zero-RPO synchronous failover is fundamentally different from a snapshot restoration, Nutanix prevents placing them in the same Recovery Plan. Attempting to do so will cause validation errors and lead to execution failure, as the orchestrator cannot simultaneously manage real-time failover and snapshot-based restoration for the same logical group. To successfully protect an environment with both types of RPO requirements, administrators must create separate Recovery Plans: one dedicated to Synchronous workloads and another for snapshot-based Asynchronous/NearSync workloads, ensuring that each set of VMs follows its appropriate recovery workflow.
NEW QUESTION # 87
After an unplanned outage, all VMs were successfully failed over to the recovery site, and users are now accessing workloads from there. The DR dashboard shows the failover is complete and replication from the original primary site has stopped. As part of post-failover cleanup, what is the most appropriate next action to ensure the DR configuration reflects the current production state and is ready for future protection?
Answer: A
Explanation:
Following a successful unplanned failover, the " Recovery Site " has technically become the new " Production Site " . However, the data protection relationship is now one-sided; while the VMs are running at the recovery site, they are likely no longer being replicated anywhere because the original protection policy was designed to move data from the (now failed) primary site to the recovery site.
The most critical post-failover task is to " re-protect " the workloads. This involves updating the Protection Policies in Prism Central to establish a new replication direction, typically from the current active site (the old recovery site) back to the original primary site (once it is restored) or to a third availability zone. Without re- protection, the business is running its production workloads without a safety net, leaving them vulnerable to a second failure. Deleting recovery points (Option A) is dangerous as it removes the only historical data available. Leaving the environment as-is (Option B) ignores the lack of ongoing protection. Initiating an immediate failback (Option D) is often impossible or unwise until the original site is fully stabilized and the data has been synchronized back. Therefore, establishing a new protection stream is the mandatory next step for operational resilience.
NEW QUESTION # 88
Which statement describes the automatic detachment timeout period for a snapshot disk mounted to a VM using the Nutanix Guest Tools (NGT) Self-Service Restore (SSR) feature?
Answer: C
Explanation:
Self-Service Restore (SSR) is designed to be a temporary recovery operation. When a user uses the SSR agent to mount a historical snapshot disk, that disk is attached to the VM via the hypervisor ' s virtual controller.
While it is a best practice for the user to " unmount " and " detach " the disk once they have recovered their files, the Nutanix system includes a safety mechanism to prevent these temporary disks from being left attached indefinitely.
Nutanix enforces a built-in automatic detachment timeout of 24 hours. If a disk remains attached via the SSR workflow for longer than 24 hours, the Nutanix orchestration engine will automatically trigger a detachment task to clean up the VM ' s configuration. This is essential for maintaining cluster " hygiene, " as stale snapshots attached to VMs can interfere with future backup operations, prevent VM migrations (vMotion), or lead to unnecessary storage overhead if the snapshots are kept " locked " by the attachment. Understanding this 24-hour timeout helps administrators reassure users that they have a full day to perform their recovery tasks while ensuring the infrastructure team that the environment will automatically revert to a clean state without manual intervention. This balance of user flexibility and system automation is a hallmark of the Nutanix BCDR design.
Here are questions 81 through 100 from the Nutanix Certified Professional - Business Continuity (NCP-BC)
7.5 exam set, formatted strictly as requested with detailed technical explanations for each.
NEW QUESTION # 89
An administrator has VMs in a container named VMData on Cluster A that need to be replicated to Cluster B.
In order to configure new replications to Cluster B, the administrator creates a container named VMData on Cluster B with an advertised capacity of 200GB.
The VMs on Cluster A in the VMData container have these characteristics:
* Large VMs taking up 4TB of space
* Low data churn rate
* 100GB of recovery points
* NGT is installed
* Recovery points are application-consistent
After replications begin the administrator quickly notices replications are not progressing.
What best explains what happened?
Answer: A
Explanation:
Replication in a Nutanix environment always begins with an " initial seed " . This first replication task is a full, 1-to-1 copy of all the data blocks currently occupied by the virtual machines on the source cluster. Unlike subsequent incremental snapshots-which only transfer the changed blocks-the initial seed requires sufficient physical or logical space at the destination to hold the entire data set of the protected VMs.
In this scenario, the administrator attempted to protect 4TB of virtual machine data but restricted the destination container ' s capacity to a mere 200GB. Because the destination container reports only 200GB of available space, the replication job will immediately stall or fail to progress as soon as the incoming data stream exceeds that limit. Nutanix replication requires a " landing zone " that can accommodate the full size of the initial snapshot before it can begin the process of data reduction (like compression or deduplication) at the remote site. To fix this, the administrator must increase the advertised capacity of the VMData container on Cluster B to at least 4TB (plus overhead for future growth and snapshots) to allow the initial full seed to complete successfully, thereby establishing the baseline for the BCDR protection schedule.
NEW QUESTION # 90
An administrator is troubleshooting a hung replication. When checking the replication status, the complete percent and bytes completed do not increase. The administrator checks the Stargate logs on the destination cluster and confirms the writes are failing with " nfs status 28 " . Checking the container info on the destination cluster, free space on the container is 0. The administrator confirms that there is sufficient space available in the storage pool. What could be the reason for free space on the container to be 0?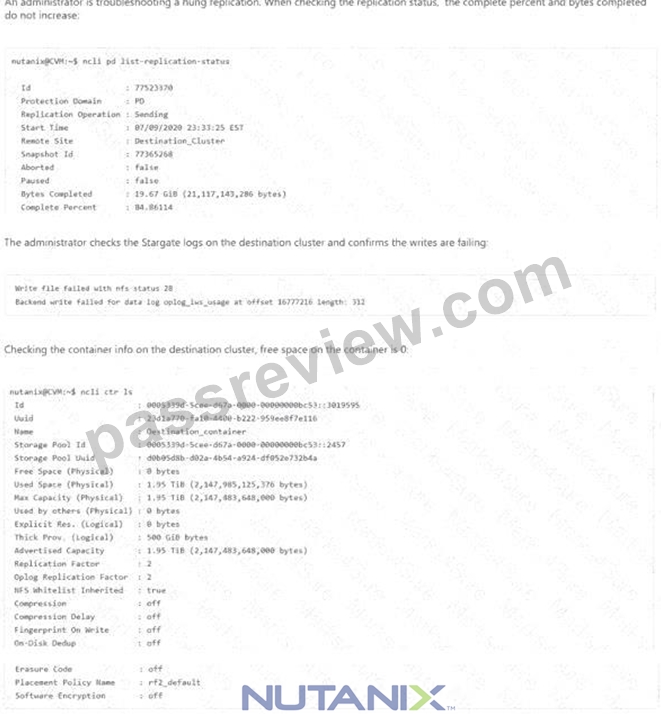
Answer: A
Explanation:
In a Nutanix environment, " Advertised Capacity " is a logical limit (a quota) that an administrator can set on a specific storage container. Even if the physical storage pool has terabytes of free space, if a container ' s advertised capacity is reached, the hypervisor and the Nutanix services will perceive the container as being
100% full.
In this troubleshooting scenario, the " nfs status 28 " error code is a standard indicator for " No space left on device " . Since the administrator confirmed the pool is healthy, the logical limit on the container is the only remaining bottleneck. Replication jobs will " hang " because the destination Stargate service cannot write the incoming data blocks to a container that reports zero free space. To resolve this, the administrator must either increase the advertised capacity value in Prism or remove the limit entirely to allow the container to consume the available physical space in the pool. This highlights a common configuration " trap " where logical quotas-intended for multi-tenant management-can inadvertently block critical BCDR processes like replication if not monitored or sized correctly according to the protected VM growth.
NEW QUESTION # 91
......
PassReview also presents desktop-based Nutanix NCP-BC-7.5 practice test software which is usable without any internet connection after installation and only required license verification. Nutanix NCP-BC-7.5 Practice Test software is very helpful for all those who desire to practice in an actual Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 (NCP-BC-7.5) exam-like environment.
NCP-BC-7.5 Latest Exam Online: https://www.passreview.com/NCP-BC-7.5_exam-braindumps.html
P.S. Free & New NCP-BC-7.5 dumps are available on Google Drive shared by PassReview: https://drive.google.com/open?id=1yvgMcjNrgiychYWjB9YCvC3_aoRAfzUx