All Databricks-Certified-Professional-Data-Engineer learning materials fall within the scope of this exam for your information. The content is written promptly and helpfully because we hired the most professional experts in this area to compile the Databricks-Certified-Professional-Data-Engineer Preparation quiz. And our experts are professional in this career for over ten years. Our Databricks-Certified-Professional-Data-Engineer practice materials will be worthy of purchase, and you will get manifest improvement.
| Section | Weight | Objectives |
|---|---|---|
| Monitoring and Alerting | 10% | - Performance and health monitoring - Setting up alerts and notifications - Pipeline observability and logging |
| Data Ingestion & Acquisition | 7% | - Connecting to diverse data sources - Schema inference and evolution - Auto Loader and streaming ingestion |
| Debugging and Deploying | 10% | - CI/CD and DevOps practices - Deployment using bundles, CLI, and APIs - Troubleshooting pipelines and errors |
| Data Modelling | 6% | - Schema design and management - Delta Lake table design - Medallion Architecture implementation |
| Cost & Performance Optimisation | 13% | - Storage optimization (partitioning, Z-order, indexing) - Cluster configuration and scaling - Query optimization and caching |
| Data Transformation, Cleansing, and Quality | 10% | - Data validation and quality checks - Standardization and normalization - Handling missing or inconsistent data |
| Ensuring Data Security and Compliance | 10% | - Data encryption and masking - Compliance standards implementation - Access control and permissions |
| Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
| Data Governance | 7% | - Data lineage and metadata tracking - Policy enforcement - Unity Catalog management |
| Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic - Integration with Databricks APIs and tools - Data transformation and aggregation |
>> Databricks-Certified-Professional-Data-Engineer Test Study Guide <<
Because our Databricks-Certified-Professional-Data-Engineer practice materials are including the best thinking from upfront experts with experience more than ten years. By using our Databricks-Certified-Professional-Data-Engineer study guide, your possibility of getting certificate and being success will increase dramatically and a series of benefits will come along in your life. So our Databricks-Certified-Professional-Data-Engineer real quiz is versatile and accessible to various exam candidates. Just trust us and you can get what you want for sure!
NEW QUESTION # 180
The DevOps team has configured a production workload as a collection of notebooks scheduled to run daily using the Jobs UI. A new data engineering hire is onboarding to the team and has requested access to one of these notebooks to review the production logic.
What are the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data?
Answer: E
Explanation:
Explanation
This is the correct answer because it is the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data. Notebook permissions are used to control access to notebooks in Databricks workspaces. There are four types of notebook permissions: Can Manage, Can Edit, Can Run, and Can Read. Can Manage allows full control over the notebook, including editing, running, deleting, exporting, and changing permissions. Can Edit allows modifying and running the notebook, but not changing permissions or deleting it. Can Run allows executing commands in an existing cluster attached to the notebook, but not modifying or exporting it. Can Read allows viewing the notebook content, but not running or modifying it. In this case, granting Can Read permission to the user will allow them to review the production logic in the notebook without allowing them to makeany changes to it or run any commands that may affect production data. Verified References: [Databricks Certified Data Engineer Professional], under "Databricks Workspace" section; Databricks Documentation, under "Notebook permissions" section.
NEW QUESTION # 181
A junior data engineer has configured a workload that posts the following JSON to the Databricks REST API endpoint 2.0/jobs/create.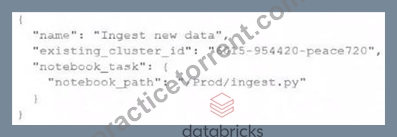
Assuming that all configurations and referenced resources are available, which statement describes the result of executing this workload three times?
Answer: A
Explanation:
This is the correct answer because the JSON posted to the Databricks REST API endpoint 2.0/jobs/create defines a new job with a name, an existing cluster id, and a notebook task. However, it does not specify any schedule or trigger for the job execution. Therefore, three new jobs with the same name and configuration will be created in the workspace, but none of them will be executed until they are manually triggered or scheduled. Verified Reference: [Databricks Certified Data Engineer Professional], under "Monitoring & Logging" section; [Databricks Documentation], under "Jobs API - Create" section.
NEW QUESTION # 182
A data engineer is designing a data pipeline. The source system generates files in a shared directory that is also
used by other processes. As a result, the files should be kept as is and will accumulate in the directory. The
data engineer needs to identify which files are new since the previous run in the pipeline, and set up the
pipeline to only ingest those new files with each run.
Which of the following tools can the data engineer use to solve this problem?
Answer: E
NEW QUESTION # 183
A platform engineer is creating catalogs and schemas for the development team to use.
The engineer has created an initial catalog, catalog_A, and initial schema, schema_A. The engineer has also granted USE CATALOG, USE SCHEMA, and CREATE TABLE to the development team so that the engineer can begin populating the schema with new tables.
Despite being owner of the catalog and schema, the engineer noticed that they do not have access to the underlying tables in Schema_A.
What explains the engineer's lack of access to the underlying tables?
Answer: A
Explanation:
schema.
Explanation:
In Databricks, catalogs, schemas (or databases), and tables are managed through the Unity Catalog or Hive Metastore, depending on the environment. Permissions and ownership within these structures are governed by access control lists (ACLs).
Catalog and Schema Ownership: When a platform engineer creates a catalog (such as catalog_A) and schema (such as schema_A), they automatically become the owner of those entities. This ownership gives them control over granting permissions for those entities (i.e., granting the USE CATALOG and USE SCHEMA privileges to others). However, ownership of the catalog or schema does not automatically extend to ownership or permission of individual tables within that schema.
Table Permissions: For tables within a schema, the permission model is more granular. The table creator (i.e., whoever creates the table) is automatically assigned as the owner of that table. In this case, the platform engineer owns the schema but does not automatically inherit permissions to any table created within the schema unless explicitly granted by the table's owner or unless they grant permissions to themselves.
Why the Engineer Lacks Access: The platform engineer notices that they do not have access to the underlying tables in schema_A despite being the owner of the schema. This occurs because the schema's ownership does not cascade to the tables. The engineer must either:
Grant permissions to themselves for the tables in schema_A, or
Be granted permissions by whoever created the tables within the schema.
Resolution: As the owner of the schema, the platform engineer can easily grant themselves the required permissions (such as SELECT, INSERT, etc.) for the tables in the schema. This explains why the owner of a schema may not automatically have access to the tables and must take explicit steps to acquire those permissions.
Reference
Databricks Unity Catalog Documentation: Manage Permissions
[Databricks Permissions and Ownership](https://docs.databricks.com/security/access-control/workspace-acl.html#permissions
NEW QUESTION # 184
The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
The following logic is used to process these records.
Which statement describes this implementation?
Answer: B
Explanation:
The logic uses the MERGE INTO command to merge new records from the view updates into the table customers. The MERGE INTO command takes two arguments: a target table and a source table or view. The command also specifies a condition to match records between the target and the source, and a set of actions to perform when there is a match or not. In this case, the condition is to match records by customer_id, which is the primary key of the customers table. The actions are to update the existing record in the target with the new values from the source, and set the current_flag to false to indicate that the record is no longer current; and to insert a new record in the target with the new values from the source, and set the current_flag to true to indicate that the record is current. This means that old values are maintained but marked as no longer current and new values are inserted, which is the definition of a Type 2 table. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Merge Into (Delta Lake on Databricks)" section.
NEW QUESTION # 185
......
If you fail Databricks-Certified-Professional-Data-Engineer exam unluckily, don’t worry about it, because we provide full refund for everyone who failed the exam. You can ask for a full refund once you show us your unqualified transcript to our staff. The whole process is time-saving and brief, which would help you pass the next Databricks-Certified-Professional-Data-Engineer Exam successfully. Please contact us through email when you need us. The Databricks-Certified-Professional-Data-Engineer question dumps produced by our company, is helpful for our customers to pass their exams and get the Databricks-Certified-Professional-Data-Engineer certification within several days. Our Databricks-Certified-Professional-Data-Engineer exam questions are your best choice.
Databricks-Certified-Professional-Data-Engineer Real Testing Environment: https://www.practicetorrent.com/Databricks-Certified-Professional-Data-Engineer-practice-exam-torrent.html