The Designing and Implementing Multi-Agent AI Solutions (AI-500) product can be easily accessed just after purchasing it from Prep4King. You can receive free Sitecore Dumps updates for up to 1 year after buying material. The 24/7 support system is also available for you, which helps you every time you get stuck somewhere. Many students have studied from the Prep4King Designing and Implementing Multi-Agent AI Solutions (AI-500) practice material and rated it positively because they have passed the Designing and Implementing Multi-Agent AI Solutions (AI-500) certification exam on the first try.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement guardrails
|
| Topic 2: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Optimize operational performance
|
| Topic 3: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Topic 4: Develop multi-agent solutions in Azure | 30-35% | - Build and integrate tool ecosystems
|
If you want to pass exam and get the related certification in the shortest time, the AI-500 AI-500 study materials from our company will be your best choice. Although there are a lot of same study materials in the market, we still can confidently tell you that our AI-500 Study Materials are most excellent in all aspects. With our experts and professors’ hard work and persistent efforts, the AI-500 study materials from our company have won the customers’ strong support in the past years.
NEW QUESTION # 72
You have a single-agent customer support copilot built by using Microsoft Foundry. The application that hosts the copilot runs on multiple stateless instances, and rolling upgrades restart the instances.
[Architect multi-agent solutions]
Customer investigations can last for several days. A user can have multiple unrelated investigations, and stable user preferences, such as a preferred contact method, must be available across sessions and devices Compliance reporting requires a one-year, queryable audit trail of thread messages and session metadata.
During long investigations, the model context window regularly approaches its limits. Temporary tool traces do NOT affect final outcomes after the run completes.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Yes / No / Yes
Persisting thread messages and session metadata in Azure Cosmos DB can satisfy the requirement for a durable, queryable audit trail when the appropriate retention and indexing policies are configured. Storing thread identifiers only in per-instance memory cannot survive rolling restarts and cannot support consistent routing across multiple stateless instances, so that statement is false. Separating unrelated investigations into task-scoped threads prevents one case from consuming the context budget of another. Removing temporary tool traces after the run when they no longer influence the outcome is also a valid compaction strategy for reducing context pressure. Current Agent Framework terminology commonly refers to this as compaction or tool-result eviction rather than "importance-weighted pruning," but the architectural effect described is sound.
Therefore the correct sequence is Yes, No, Yes. This choice also keeps the design composable as more agents are introduced. Clear interfaces, trust boundaries, and state ownership let a team change one domain without forcing unrelated agents to adopt the same permissions, context, or execution model.
Official Microsoft reference: Microsoft Foundry Agent Service - standard setup and durable state
NEW QUESTION # 73
You have a Microsoft Foundry project that includes four independent analysis agents. Each agent invocation consumes 500 tokens per minute (TPM) from a Foundry deployment that has a TPM rate limit of 1,000.
After each agent completes, it writes 200 small records to Microsoft Dataverse. Running multiple agents simultaneously causes write bursts that result in HTTP 429 (Too Many Requests) responses.
You need to reduce the end-to-end task duration, while preventing provider and platform throttling. The solution must meet the following requirements:
* Keep as much agent parallelism as the TPM rate limit permits.
* Handle Dataverse throttling without sending premature retries.
How should you configure the orchestration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Maximum agent concurrency: Two agents; Dataverse retry behavior: Respect the Retry-After duration returned by Dataverse.
Each analysis agent consumes 500 TPM and the deployment permits 1,000 TPM, so at most two agents can run simultaneously without exceeding the stated model limit. Running only one wastes available parallelism; running three or four violates the limit. The separate Dataverse problem is HTTP 429 service-protection throttling. Microsoft Dataverse returns a `Retry-After` duration that tells clients how long to wait before retrying. Respecting that value prevents premature retries from worsening the overload condition. A fixed retry interval or immediate retry ignores the server ' s current capacity signal. The orchestration should therefore cap model-side concurrency at two and, after each agent finishes, pace Dataverse writes according to the returned retry guidance. This combination minimizes task duration while honoring both provider and platform throttling constraints. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Dataverse service protection API limits
NEW QUESTION # 74
You have a Microsoft Foundry agent that handles customer support chats. The agent has two tools named get_contract_terms and calculate_refund.
On turns where refunds must be calculated, the agent inconsistently calls the tools.
You need to reliably force refund-estimate turns to call calculate_refund.
Which request configuration should you use?
Answer: A
Explanation:
The requirement is to force one specific tool, `calculate_refund`, whenever the application determines that a refund estimate is required. A named function in `tool_choice` removes ambiguity by directing the model to invoke that exact function. `tool_choice: " auto " ` allows the model to decide whether to call a tool and which tool to use. `tool_choice: " required " ` forces some tool call but does not guarantee that `calculate_refund` is selected when multiple tools are available. A natural-language instruction remains probabilistic and is not equivalent to an API-level enforcement setting. Microsoft ' s function-calling API documents named tool choice as the deterministic way to force a specific function. Therefore A is correct. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Azure OpenAI - Function calling and tool choice
NEW QUESTION # 75
You have a Microsoft Foundry multi-agent solution. The agents contain the CI/CD evaluation gates shown in the following table.
You call one of the agents by using the request context in the evaluation process as shown in the following table.
The agent receives the following results for the tool.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
SchemaGate: Yes; RelevanceGate: Yes; CompletenessGate: No.
The supplied tool result satisfies the structural requirements of SchemaGate: it includes a valid-looking UUID result identifier, a string sourceTool value, an items array, and the required fields on the item. RelevanceGate also passes because the request category is VPN, the returned item category is VPN, and its confidence value of 0.87 is above the required 0.80 threshold. CompletenessGate fails because the rule requires at least two items while the response contains only one. This is a deterministic gate evaluation rather than an LLM-judge interpretation, so the values should be checked directly against the declared criteria. Microsoft Foundry evaluation datasets and CI/CD quality gates are designed to make exactly these regression checks repeatable before release. Therefore the correct sequence is Yes, Yes, No. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - evaluation datasets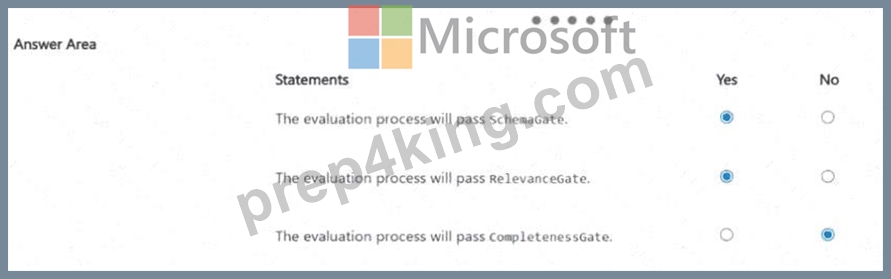
NEW QUESTION # 76
You need to modify claim Approval to prevent the prompt injection issue. Which guardrail should you use?
Answer: D
Explanation:
The malicious text is contained in an uploaded email rather than being typed directly as the user ' s prompt.
Microsoft classifies malicious instructions embedded in external or retrieved content as an indirect prompt- injection attack. Prompt Shields for documents is designed to detect those attacks in document content before the content can steer the model away from its system instructions. Prompt Shields for user prompts addresses direct attacks originating in the user ' s prompt and therefore targets the wrong attack surface here.
Groundedness evaluates whether a response is supported by context; it does not prevent an injected instruction from changing agent behavior. Task Adherence can assess whether an agent follows its task constraints, but it is not the primary control for document-borne prompt injection. Because the source of the attack is the uploaded email, the document-oriented Prompt Shields control is the technically aligned guardrail. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: Microsoft Foundry guardrails - intervention points and indirect attacks
NEW QUESTION # 77
......
The Microsoft AI-500 certification is on trending nowadays, and many Microsoft aspirants are trying to get it. Success in the AI-500 test helps you land well-paying jobs. Additionally, the AI-500 certification exam is also beneficial to get promotions in your current company. But the main problem that every applicant faces while preparing for the AI-500 Certification test is not finding updated Designing and Implementing Multi-Agent AI Solutions (AI-500) practice questions.
AI-500 Pass Test: https://www.prep4king.com/AI-500-exam-prep-material.html