P.S. Free & New DP-800 dumps are available on Google Drive shared by Pass4Leader: https://drive.google.com/open?id=1mi7LtKjArJyk5OWMY-IZlFqWmGntoLbK
For candidates who are going to prepare for the exam, they may need the training materials. The quality may be their first concern. DP-800 exam bootcamp of us is famous for the high-quality, and if you buy from us, you will never regret. We also pass guarantee and money back guarantee if you fail to pass the exam. In addition, we adopt international recognition third party for the payment of DP-800 Exam Dumps. Therefore, the safety of your money and account can be guarantee. Choose us, and you will never regret.
| Section | Objectives |
|---|---|
| Topic 1: Develop and manage database solutions | - Ensure security and compliance of data solutions - Optimize performance and scalability |
| Topic 2: Integrate AI capabilities with database systems | - Use Azure AI services with database workloads - Implement AI-assisted data processing |
| Topic 3: Design and implement data solutions | - Design database solutions using Azure data services - Implement data storage and data processing solutions |
| Topic 4: Monitor, troubleshoot, and maintain solutions | - Troubleshooting data pipeline issues - Monitoring database health and performance |
Selecting the right method will save your time and money. If you are preparing for DP-800 exam with worries, maybe the professional exam software provided by IT experts from Pass4Leader will be your best choice. Our Pass4Leader aims at helping you successfully Pass DP-800 Exam. If you are unlucky to fail DP-800 exam, we will give you a full refund of the cost you purchased our dump to make up part of your loss. Please trust us, and wish you good luck to pass DP-800 exam.
NEW QUESTION # 62
You need to recommend a solution that will resolve the ingestion pipeline failure issues. Which two actions should you recommend? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
Answer: A,B
Explanation:
The two correct actions are D and E because the ingestion failures are caused by malformed JSON and duplicate payloads , and these two controls address those two problems directly. Microsoft's JSON documentation states that SQL Server and Azure SQL support validating JSON with ISJSON , and Microsoft specifically recommends using a CHECK constraint to ensure JSON text stored in a column is properly formatted.
For the duplicate-payload issue, creating a unique index on a hash of the payload is the appropriate design.
Microsoft documents using hashing functions such as HASHBYTES to hash column values, and SQL Server allows a deterministic computed column to be used as a key column in a UNIQUE constraint or unique index . That makes a persisted hash-based computed column plus a unique index a practical and exam- consistent way to reject duplicate payloads efficiently.
The other options do not solve the stated root causes:
* Snapshot isolation addresses concurrency behavior, not malformed JSON or duplicate payload detection.
* A trigger to rewrite malformed JSON is not the right integrity control and is brittle.
* Foreign key constraints enforce referential integrity, not JSON validity or duplicate-payload prevention
Topic 1, Contoso Case Study
Existing Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure. The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.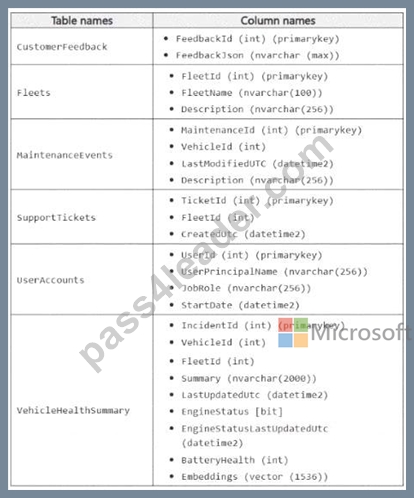
The FeedbackJson column has a full-text index and stores JSON documents in the following format.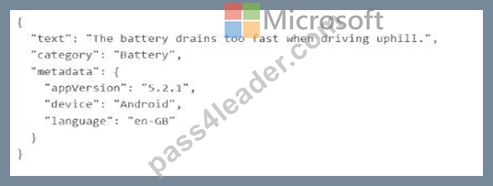
The support staff at Contoso never has the unmask permission.
Requirements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following;
* Al workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.
SELECT VehicleTd, Lastupdatedutc, EngineStatus, BatteryHealth FROM dbo.VehicleHealthSumary where fleetld - gFleetld ORDER BV LastUpdatedUtc DESC; You review the execution plan and discover that the plan shows a clustered index scan.
vehicleincidentReports often contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support Al-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracy JSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEvents table updates the corresponding value in the LastModif reduce column to the time of the change.
* Avoid recursive updates.
AI Search, Embedding's, and Vector indexing
The development learn at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases. Contoso identifies the following requirements for querying data in the FeedbackJson column of the customer-Feedback table:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
NEW QUESTION # 63
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.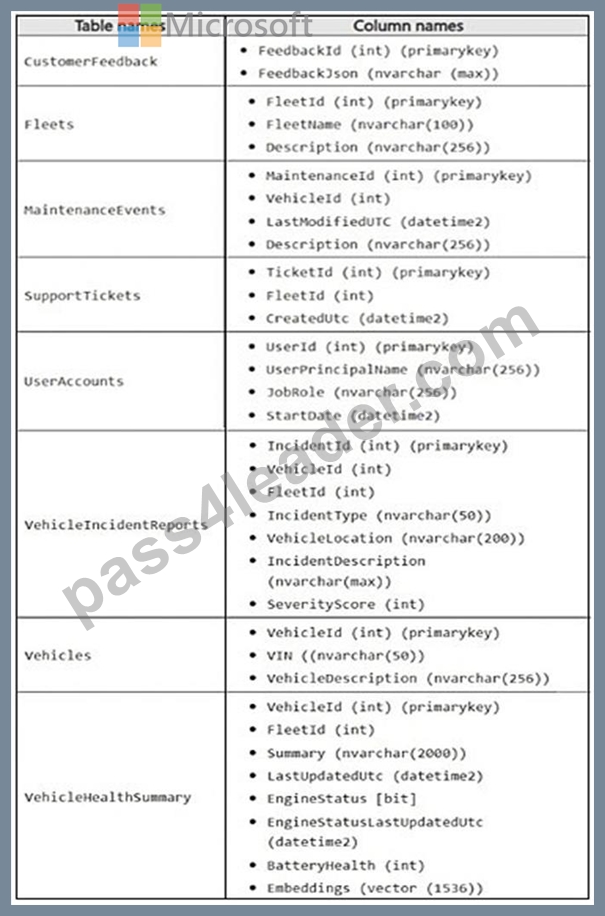
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.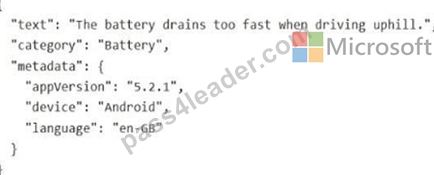
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.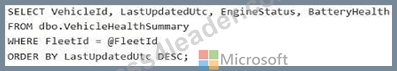
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
You need to recommend a solution for the development team to retrieve the live metadata. The solution must meet the development requirements. What should you include in the recommendation?
Answer: C
Explanation:
Scenario: Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
To retrieve live metadata from Azure SQL databases and use it with GitHub Copilot in Visual Studio Code (VS Code), you must use the SQL Server (mssql) extension. This extension provides the native capability to extract a database schema as a .dacpac file directly within the editor.
1. Export the Schema as a .dacpac File
You can extract the schema of your live Azure SQL database using the SQL Server (mssql) extension.
2. Load the .dacpac into GitHub Copilot Context
Once the .dacpac file is saved in your VS Code workspace, you can provide it as context to GitHub Copilot Chat using #-mentions or Drag & Drop.
Reference:
https://learn.microsoft.com/en-us/sql/tools/sql-database-projects/concepts/data-tier- applications/extract-dacpac-from-database
NEW QUESTION # 64
You are creating a table that will store customer profiles.
You have the following Transact-SQL code.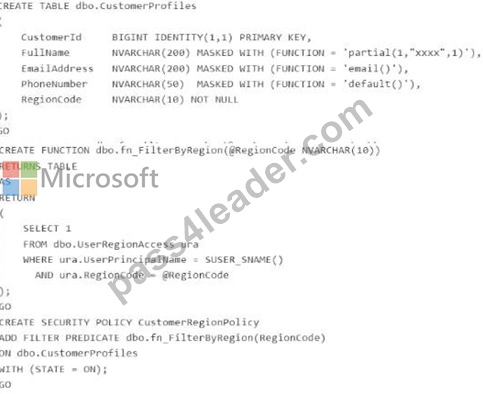
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection Is worth one point.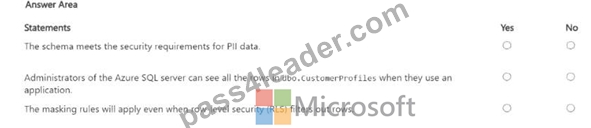
Answer:
Explanation: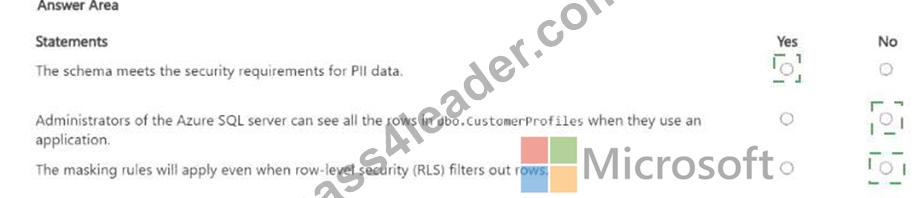
Explanation:
* The schema meets the security requirements for PII data. # Yes
* Administrators of the Azure SQL server can see all the rows in dbo.CustomerProfiles when they use an application. # No
* The masking rules will apply even when row-level security (RLS) filters out rows. # No The first statement is Yes because the design combines two relevant SQL security controls for personally identifiable information: Dynamic Data Masking (DDM) on sensitive columns such as FullName, EmailAddress, and PhoneNumber, and Row-Level Security (RLS) to restrict which rows a user can access based on RegionCode. Microsoft documents that DDM limits sensitive data exposure for nonprivileged users
, while RLS restricts row access according to the user executing the query. Together, these are valid and appropriate controls for protecting PII in Azure SQL Database.
The second statement is No . Administrative users can view unmasked data because administrative roles effectively have CONTROL, which includes UNMASK. However, that does not mean they automatically see all rows through the application query path defined by the RLS policy. The security policy filters rows based on SUSER_SNAME() and matching RegionCode, so row visibility is governed by the predicate unless the policy is altered or bypassed administratively. DDM and RLS solve different problems: DDM affects how returned values are shown, while RLS affects which rows are returned at all.
The third statement is No because masking only applies to data that is actually returned in the query result set.
Microsoft describes DDM as hiding sensitive data in the result set of a query . If RLS filters a row out, that row is not returned, so there is nothing left for masking to act on. In other words, RLS eliminates inaccessible rows first from the user's perspective, and DDM masks sensitive column values only on rows the user is allowed to see.
NEW QUESTION # 65
You need to create a table in the database to store the telemetry data. You have the following Transact-SQL code.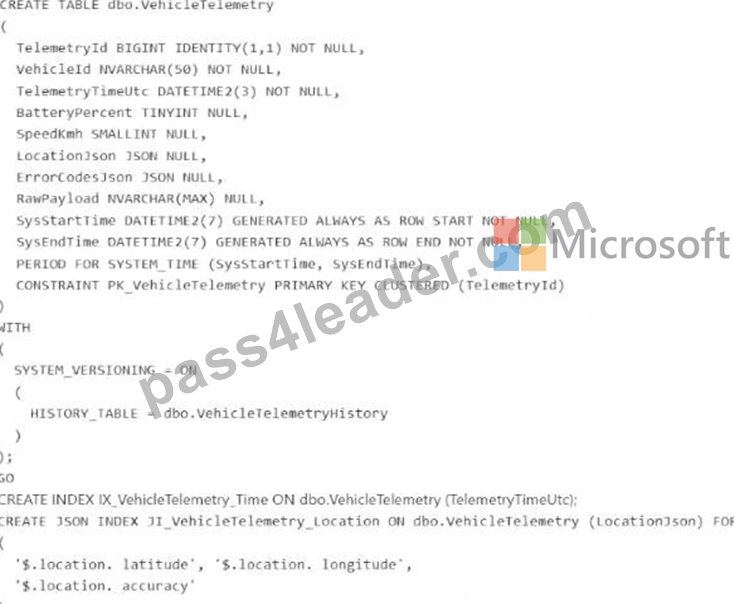
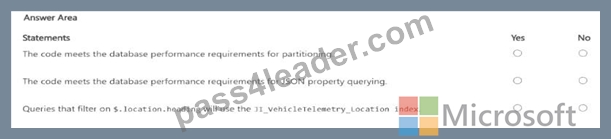
Answer:
Explanation: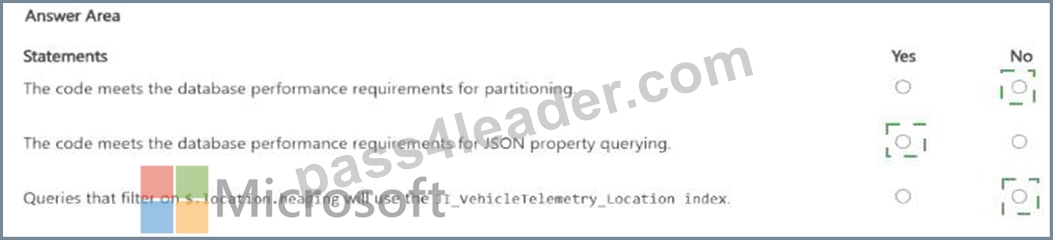
Explanation: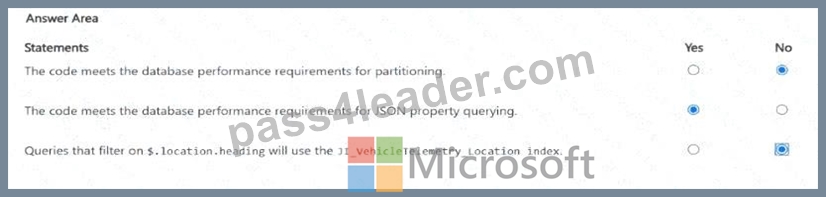
The first statement is No . The requirement says telemetry data must be stored in a partitioned table to provide predictable performance for ingestion and retention operations. However, the shown CREATE TABLE statement does not define a partition function or partition scheme, and the table is created with a regular clustered primary key on TelemetryId. Microsoft's partitioning guidance states that creating a partitioned table requires a partition function , a partition scheme , and creating the table or index on that partition scheme using a partitioning column. None of that appears in the code, so the table is not partitioned.
The second statement is Yes . The code creates a JSON index named JI_VehicleTelemetry_Location on LocationJson for these specific JSON paths: $.location.latitude, $.location.longitude, and $.location.accuracy.
That matches the requirement that those JSON properties must be filterable by using an index seek .
Microsoft documents that JSON indexing is used to optimize filtering and sorting on JSON properties, and the index only helps for the properties included in the index definition.
The third statement is No . The JSON index is defined only for latitude, longitude, and accuracy. A query filtering on $.location.heading references a different path that is not included in the index definition, so that query would not use JI_VehicleTelemetry_Location for that predicate. JSON indexes are path-specific; they do not automatically cover unrelated properties in the same JSON document.
NEW QUESTION # 66
What is a common pattern for integrating LLMs with SQL?
Answer: C
Explanation:
RAG ensures accurate, up-to-date responses using SQL data.
NEW QUESTION # 67
......
We understand your enthusiasm of effective practice materials, because they are the most hopeful tools help us gain more knowledge with the least time to achieve success, and we have been in your shoes. Our DP-800 exam questions can help you achieve that dreams easily. Whatever you want to master about this exam, our experts have compiled into them for your reference. A growing number of exam candidates are choosing our DP-800 Exam Questions, why are you still hesitating? As long as you have make up your mind, our Developing AI-Enabled Database Solutions study question is available in five minutes, so just begin your review now! This could be a pinnacle in your life.
Reliable DP-800 Guide Files: https://www.pass4leader.com/Microsoft/DP-800-exam.html
What's more, part of that Pass4Leader DP-800 dumps now are free: https://drive.google.com/open?id=1mi7LtKjArJyk5OWMY-IZlFqWmGntoLbK