Most candidates who register for Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification lack the right resources to help them achieve it. As a result, they face failure, which causes them to waste time and money, and sometimes even lose motivation to repeat their Microsoft DP-750 exam. DumpsValid will solve such problems for you by providing you with DP-750 Questions. The Microsoft DP-750 certification exam is undoubtedly a challenging task, but it can be made much easier with the help of DumpsValid's reliable preparation material.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 2: Prepare and process data | 30-35% | - Ingest and transform data
|
| Topic 3: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 4: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
>> DP-750 Official Practice Test <<
They work together and analyze the examination content to compile most probable DP-750 real dumps in three formats. These Microsoft Certification Exams questions will surely appear in the next Microsoft DP-750 exam. Memorizing these Microsoft DP-750 Valid Dumps will help you easily attempt the DP-750 exam within the allocated time. Thousands of aspirants have passed their DP-750 exam, and they all got help from our Microsoft DP-750 updated exam dumps.
NEW QUESTION # 83
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1.
Table1 stores customer profile data.
Business users must analyze how customer profile records change over time. They must also be able to query earlier versions of the table.
You need to implement a solution that:
* Maintains persistent historical versions of customer profile records for long-term analysis.
* Allows users to query earlier versions of the Delta table.
* Minimizes maintenance effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.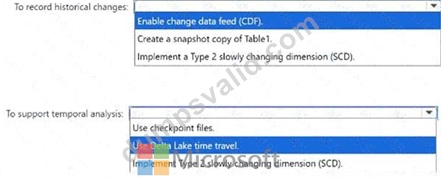
Answer:
Explanation: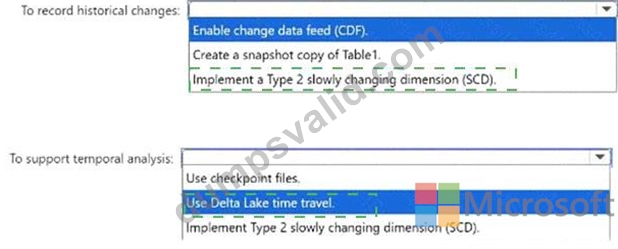
Explanation:
To record historical changes: Implement a Type 2 slowly changing dimension (SCD).
To support temporal analysis: Use Delta Lake time travel.
A Type 2 slowly changing dimension preserves customer-profile history by inserting a new record whenever a tracked attribute changes instead of overwriting the existing record. Effective dates, expiration dates, version values, or current-record indicators can identify which version applied during a particular period. This provides persistent business history for long-term analysis. Delta Lake time travel supports temporal analysis of the physical table by allowing users to query an earlier version with VERSION AS OF or TIMESTAMP AS OF. Time travel is useful for auditing and reproducing previous results, but its availability depends on retained Delta log entries and data files. Therefore, it should not replace a Type 2 SCD for permanent customer history. Together, the two features satisfy the historical-record and earlier-version requirements.
NEW QUESTION # 84
You need to configure the telemetry pipeline to support the planned changes for pipeline orchestration and address the resiliency issues.
What should you do?
Answer: B
Explanation:
Lakeflow Jobs provides native orchestration for multi-task Databricks workflows. Separate ingestion, cleansing, and curation tasks can be connected through explicit dependencies, ensuring that each stage starts only after its required upstream work succeeds. Each task can also have independent retry, notification, timeout, and compute settings, directly addressing the pipeline's resiliency requirements. Azure Data Factory could orchestrate notebooks, but it introduces another service when Lakeflow Jobs already provides the required functionality. A single notebook makes failures harder to isolate and can force successful stages to be rerun. Independently scheduled jobs rely on timing assumptions rather than actual task completion and can fail when an upstream stage runs longer than expected. Explicit Lakeflow Jobs dependencies provide reliable execution order and centralized monitoring. Microsoft Learn
NEW QUESTION # 85
You have an Azure Databricks workspace and a remote Git repository named Repo1. Repo1 contains two branches named main and Branch1.
You are on a development team that works in Repo1.
You commit changes to Branch1 and must merge the changes into main.
Before completing the merge, you need to meet the following requirements:
* Ensure that Branch1 includes the changes committed to main since Branch1 was created.
* Ensure that merge conflicts are detected and resolved.
What should you do first?
Answer: D
Explanation:
The latest remote changes from main must first be retrieved so that the development environment has the current main-branch state. After pulling those updates, main can be merged into Branch1, and any conflicts can be detected and resolved before Branch1 is proposed for integration into main. Immediately merging a stale local copy of main into Branch1 could omit commits added remotely after Branch1 was created. Pulling Branch1 only synchronizes the feature branch and does not retrieve the required main-branch changes.
Creating a pull request before updating and testing Branch1 would defer conflict discovery until later in the integration process. Pulling the latest main changes is therefore the correct first operation in the sequence.
Microsoft Learn
NEW QUESTION # 86
You have an Azure Databricks workspace.
You are creating a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically.
You need to configure compute for the pipeline. The solution must minimize operational costs and effort.
What should you use?
Answer: D
Explanation:
The best option for a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically while keeping costs and administrative effort low is a job cluster that uses autoscaling.
Lowest Costs: Job clusters (also called automated compute) are billed at a significantly lower Data Processing Unit (DBU) rate compared to all-purpose clusters. By enabling autoscaling, Databricks dynamically allocates or removes worker nodes based on real-time pipeline demand, ensuring you never pay for unutilized resources.
Low Administrative Effort: While Databricks generally recommends Serverless compute as the absolute ideal for zero-admin pipelines, when selecting from classic compute options, a job cluster automatically handles its own lifecycle. It deploys when the pipeline starts executing and terminates automatically when processing is finished.
Incorrect:
[Not A]
Databricks SQL warehouses are designed to run standalone materialized views and streaming tables via standard SQL. They are not the native compute vehicle for running a fully automated, dedicated Lakeflow Spark Declarative Pipelines (SDP) deployment framework.
[Not B]
All-purpose compute is meant for interactive development, debugging, and ad-hoc analysis. It is billed at a much higher DBU rate, which violates the requirement to keep costs low.
[Not D]
Aside from the higher billing rate of all-purpose compute, a single-node configuration does not scale horizontally. This directly conflicts with your requirement to build a pipeline that scales automatically.
Reference:
https://docs.databricks.com/gcp/en/ldp/auto-scaling
NEW QUESTION # 87
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1.
Table1 is written by batch jobs every hour and is queried frequently by filtering two columns named Customerid and EventDate.
You expect Table1 to grow significantly over time.
The rows in Table1 are frequently updated and deleted to support compliance requests.
You need to keep query performance consistent as Table1 grows. The solution must minimize update and deletion effort.
What should you include in the solution? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.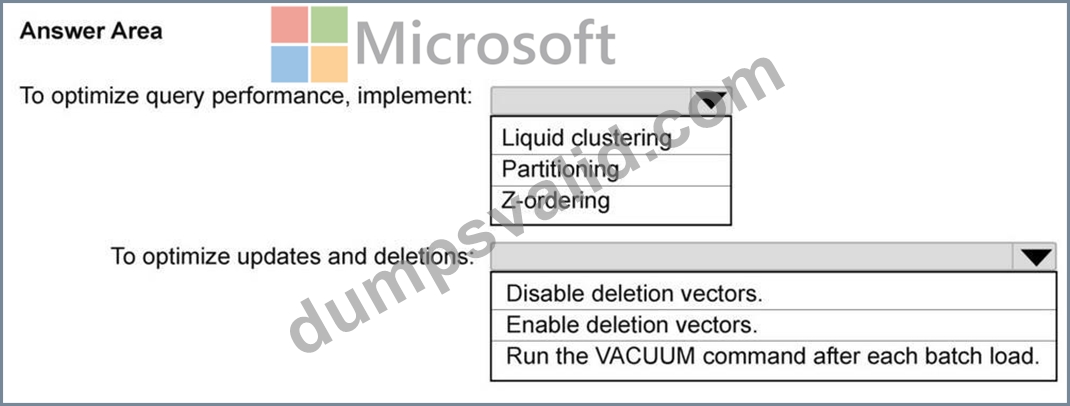
Answer:
Explanation: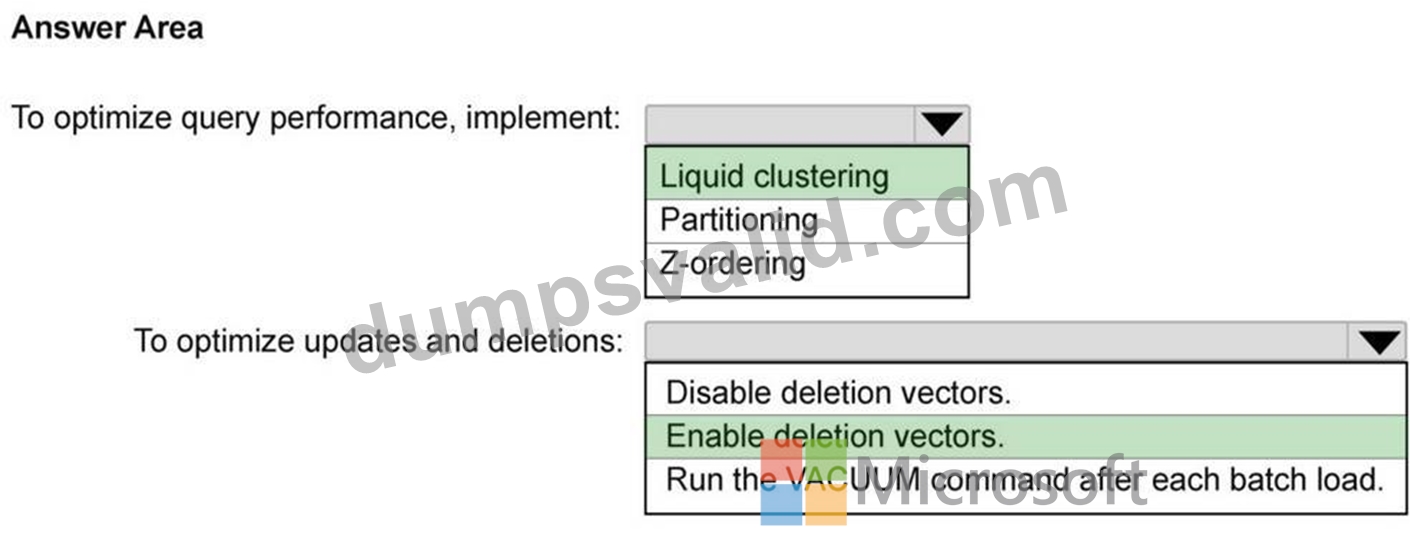
NEW QUESTION # 88
......
We have three versions of DP-750 learning materials available, including PDF, Software and APP online. The most popular one is PDF version of DP-750 study guide can be printed into papers so that you are able to write some notes or highlight the emphasis. On the other hand, Software version of our DP-750 Practice Questions is also welcomed by customers, especially for windows users. As for PPT online version, as long as you download the app into your computer. You can enjoy the nice service from us.
Guaranteed DP-750 Questions Answers: https://www.dumpsvalid.com/DP-750-still-valid-exam.html