2026 Latest Pass4training AI-300 PDF Dumps and AI-300 Exam Engine Free Share: https://drive.google.com/open?id=1eFV-vFAV-4yi4S4L_FGIM52z41D0f2SP
By purchasing our Pass4training Microsoft AI-300 dumps, you will finish the exam preparation. And then, you will get high quality tests questions and test answers. Pass4training Microsoft AI-300 test is your friend which is worth trusting forever. Our Pass4training Microsoft AI-300 Dumps Torrent provide certification training materials to the IT people in the world. It includes test questions and test answers. Quality product rate is 100% and customer rate also 100%.
| Section | Objectives |
|---|---|
| Topic 1: Implement generative AI quality assurance and observability | - Implement logging, tracing, and telemetry for GenAI applications - Evaluate generative AI outputs for quality, safety, and grounding - Monitor latency, token usage, cost, and error rates - Conduct red teaming, adversarial testing, and content filtering |
| Topic 2: Design and implement a GenAIOps infrastructure | - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Configure prompt orchestration, prompt flows, and agent frameworks - Manage API keys, rate limits, and responsible AI guardrails - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search |
| Topic 3: Design and implement an MLOps infrastructure | - Manage environments, data stores, and model registries - Implement security, governance, and compliance for MLOps - Configure source control, CI/CD pipelines, and automation for ML workflows - Set up Azure Machine Learning workspace and compute targets |
| Topic 4: Optimize generative AI systems and model performance | - Tune prompts, system messages, and grounding strategies - Fine-tune and distill models for specific use cases - Implement cost management and scaling strategies for GenAI workloads - Optimize inference performance, caching, and throughput |
| Topic 5: Implement machine learning model lifecycle and operations | - Train, register, and version models using Azure Machine Learning - Retrain, update, and manage model versions in production - Deploy models to real-time and batch endpoints - Monitor model performance, data drift, and operational health |
Pass4training provides exam dumps designed by experts to ensure that the candidates' success. This means that there is no need to worry about your results since everything AI-300 exam dumps are verified and updated by professionals. Microsoft AI-300 Exam are made to be a model of actual exam dumps. Therefore, it can help users to feel in a real exam such as a real exam. This will improve your confidence and lessen stress to be able to pass the actual tests.
NEW QUESTION # 108
An Azure Machine Learning workspace contains multiple registered versions of a model that is used in production.
An older model version must no longer be deployable, but it must remain available for compliance review and potential rollback.
You need to change the state of the model version to meet the requirements.
What should you do?
Answer: A
Explanation:
To ensure that older Azure Machine Learning model versions are no longer deployable but remain available for reference or historical tracking, you should archive those specific versions.
How to Archive Model Versions
Archiving a model version effectively hides it from standard list queries and management interfaces, preventing accidental deployment while maintaining its metadata and files in the workspace.
Behavior of Archived Models:
Hidden by Default: They will no longer appear in the Azure Machine Learning Studio model list unless you explicitly filter for archived assets.
Referenceable: You can still reference and use an archived model version in existing workflows if you have its specific version number.
Restoreable: If you need to redeploy the model in the future, you can use the restore command to make it active again.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-manage-models
NEW QUESTION # 109
During training, pipelines occasionally fail due to schema mismatch caused by upstream data changes. You need a robust and automated solution that prevents invalid data from reaching training steps. What is the BEST approach?
Answer: D
Explanation:
A data validation component ensures that incoming data matches the expected schema before training begins. This prevents pipeline failures and avoids training on corrupted or incomplete data. Ignoring schema mismatches can introduce silent errors, making debugging difficult and compromising model quality.
NEW QUESTION # 110
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You manage an Azure Machine Learning workspace. The Python script named script.py reads an argument named training_data. The training_data argument specifies the path to the training data in a file named dataset1.csv.
You plan to run the script.py Python script as a command job that trains a machine learning model.
You need to provide the command to pass the path for the dataset as a parameter value when you submit the script as a training job.
Solution: python script.py --trainingdata ${{inputs.training_data}}
Does the solution meet the goal?
Answer: A
Explanation:
Correct:
* python script.py --training_data ${{inputs.training_data}}
The scipt is named script.py.
For the parameter use ${{inputs.training_data}}
Incorrect:
* python script.py --training_data dataset1.csv
* python script.py dataset1.csv
* python train.py --training_data training_data
Note: Read a TabularDataset, Example
In the Input object, specify the type as AssetTypes.MLTABLE, and mode as InputOutputModes.DIRECT:
* Details omitted*
job = command(
code="./src", # Local path where the code is stored
*-> command="python train.py --inputs ${{inputs.input_data}}",
inputs=my_job_inputs,
environment="<environment_name>:<version>",
compute="cpu-cluster",
)
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-read-write-data-v2
NEW QUESTION # 111
Hotspot Question
A team is standardizing MLOps practices by using automated deployments.
The team requires infrastructure to be defined declaratively and deployed through automation pipelines.
You need to configure infrastructure deployment.
What should you configure for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.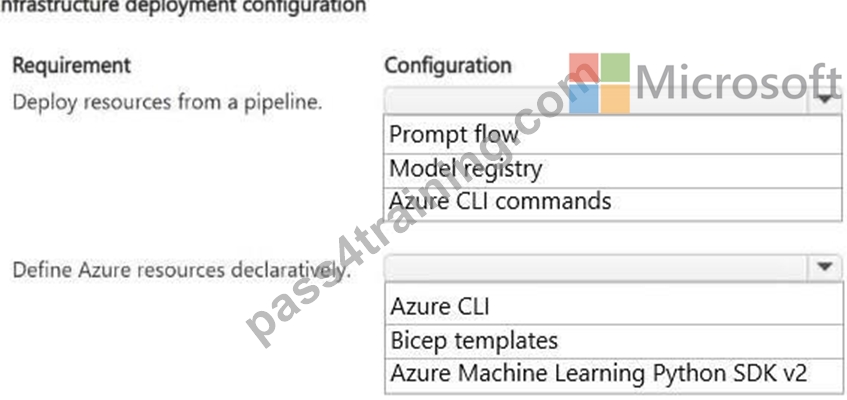
Answer:
Explanation: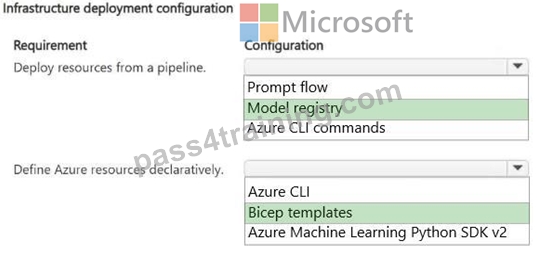
Explanation:
Box 1: Model Registry
Deploy resources from a pipeline.
To standardize MLOps practices with declarative infrastructure and automated pipelines, the best choice is to use a Model Registry via Infrastructure as Code (IaC) for your core setup, supplemented by Azure CLI inside your pipelines for operational tasks. Prompt Flow is an application development tool and should not be used to deploy infrastructure.
A Model Registry (like Azure Machine Learning registry or MLflow) is the standard architectural pattern for managing ML artifacts declaratively.
Declarative Tracking: It stores model versions, lineages, and environments as code-like configurations.
Pipeline Integration: CI/CD pipelines can natively fetch from or push to a registry using configuration files.
Environment Isolation: It allows you to promote the exact same model artifact across Dev, Staging, and Production environments without rebuilding.
Box 2: Bicep templates
Define Azure resources declaratively.
Bicep templates are an excellent choice for defining Azure resources declaratively in an automated MLOps pipeline.
Native Azure Integration: Bicep supports all Azure Machine Learning (Azure ML) resources immediately upon release.
Declarative Syntax: You define the desired end-state of your infrastructure without writing complex deployment scripts.
No State Management: Azure manages the state automatically, unlike Terraform which requires a remote state file.
Tooling Support: Deep integration with Azure Pipelines and GitHub Actions allows easy deployment validation.
Reference:
https://azure.microsoft.com/en-us/blog/new-azure-capabilities-to-simplify-deployment-and-management/
NEW QUESTION # 112
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You work in Microsoft Foundry with a prompt flow.
You must manually evaluate prompts and compare results across prompt variants.
You need to capture the inputs, outputs, token usage, and latencies for each flow run for the evaluation.
Solution: In Microsoft Foundry, turn on Tracing for the prompt flow of the project and execute test runs to produce trace data.
Does the solution meet the goal?
Answer: A
Explanation:
Correct:
* In Microsoft Foundry, turn on Tracing for the prompt flow of the project and execute test runs to produce trace data.
Incorrect:
* Create prompt variants and compare their outputs in the Evaluation experience.
* Use the prompt flow SDK to enable tracing for the flow before executing runs. Then run the flow to generate traceable results.
Note:
In Azure AI Foundry, you can capture and compare these metrics by enabling Tracing and using the Bulk Test feature. This allows you to systematically evaluate different prompt variants against a common dataset.
Steps to Evaluate and Compare Prompt Variants
*-> 1. Enable Tracing
Navigate to your Prompt Flow project.
Locate the Tracing toggle at the top of the flow authoring page.
Switch it to On.
This ensures every execution captures latency, token counts, and node-level inputs/outputs.
2. Create Prompt Variants
Within your flow, identify the LLM node you want to test.
Click Variants to create multiple versions of your prompt (e.g., Variant_0, Variant_1).
This allows you to test different instructions or few-shot examples side-by-side.
3. Run a Bulk Test (Evaluation)
4. Analyze the Results
Reference:
https://www.linkedin.com/pulse/streamlining-generative-ai-development-azure-foundry-tracing- taneja-mbwze
NEW QUESTION # 113
......
The Operationalizing Machine Learning and Generative AI Solutions (AI-300) certification has become a basic requirement to advance rapidly in the information technology sector. Since Operationalizing Machine Learning and Generative AI Solutions (AI-300) actual dumps are vital to prepare quickly for the examination. Therefore, you will need them if you desire to ace the Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam in a short time.
Updated AI-300 CBT: https://www.pass4training.com/AI-300-pass-exam-training.html
P.S. Free & New AI-300 dumps are available on Google Drive shared by Pass4training: https://drive.google.com/open?id=1eFV-vFAV-4yi4S4L_FGIM52z41D0f2SP