2026 Latest Pass4cram DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=1h39ZICFoy50pWKsoFRMzNDhabhe2Y1Up
Pass4cram's Microsoft DP-750 Exam Training materials allows candidates to learn in the case of mock examinations. You can control the kinds of questions and some of the problems and the time of each test. In the site of Pass4cram, you can prepare for the exam without stress and anxiety. At the same time, you also can avoid some common mistakes. So you will gain confidence and be able to repeat your experience in the actual test to help you to pass the exam successfully.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Topic 2: Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Topic 3: Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Topic 4: Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
Please believe that our Pass4cram team have the same will that we are eager to help you pass DP-750 exam. Maybe you are still worrying about how to prepare for the exam, but now we will help you gain confidence. By by constantly improving our dumps, our strong technical team can finally take proud to tell you that our DP-750 exam materials will give you unexpected surprises. You can download our free demo to try, and see which version of DP-750 Exam Materials are most suitable for you; then you can enjoy your improvement in IT skills that our products bring to you; and the sense of achievement from passing the DP-750 certification exam.
NEW QUESTION # 22
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You need to configure Cluster1 to meet the following requirements:
- The cluster must scale up automatically when workloads increase.
- The cluster must scale down automatically when workloads decrease.
The solution must minimize costs.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,C
Explanation:
Enabling autoscaling and setting a 30-minute auto-termination timeout is the correct configuration to meet the goals.
Autoscaling handles fluctuating workloads, while auto-termination prevents you from paying for idle compute resources.
Dynamic Scaling: Autoscaling automatically adds workers during high loads and removes them when demand drops.
Cost Control: The 30-minute termination window ensures the cluster shuts down completely if no jobs are running, stopping all compute charges.
Reference:
https://community.databricks.com/t5/get-started-discussions/cluster-auto-termination-best- practices/td-p/75826
NEW QUESTION # 23
You have an Azure Databricks workspace
You are creating a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically. You need to configure compute for the pipeline. The solution must minimize operational costs and effort. What should you use?
Answer: D
Explanation:
The correct answer is C - a job cluster that uses autoscaling.
Job clusters (also called pipeline clusters in the SDP context) are created exclusively for a pipeline run and terminated when the pipeline stops. You pay only for what the pipeline uses, and there's no idle cost between runs. Autoscaling on a job cluster lets the pipeline expand during heavy processing and contract during lighter stages - the combination of on-demand lifecycle and elastic scaling gives the lowest operational cost.
Option A (all-purpose cluster) runs at a higher DBU rate and persists beyond the pipeline's lifecycle, meaning you're paying for it even when the pipeline isn't running. Option B (SQL warehouse) is optimised for interactive BI and ad-hoc queries, not for the batch/streaming workloads SDP pipelines run. Option D (single- node all-purpose) has no scaling, runs at the all-purpose DBU rate, and is capped at one node - unsuitable for any production pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/configure-pipeline
NEW QUESTION # 24
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have an Apache Spark Structured Streaming job that writes data to a Delta table.
After the cluster restarts, the streaming job reprocesses previously ingested data.
You need to prevent the streaming job from reprocessing the data after the cluster restarts.
What should you do?
Answer: C
Explanation:
To prevent your Apache Spark Structured Streaming job from reprocessing previously ingested data after a cluster restart, you must configure a streaming checkpoint directory.
Core Solution
Enable Checkpointing: Define the checkpointLocation option in your streaming write configuration.
Track Progress: Spark uses this directory to save the exact offset ranges of processed data.
Automatic Recovery: Upon restart, the engine reads the checkpoint and resumes precisely where it left off.
Implementation Example in python
# Configure the streaming write with a checkpoint path
(df.writeStream
.format("delta")
.outputMode("append")
.option("checkpointLocation",
"/Volumes/catalog/schema/volume_name/checkpoints/job_name")
.toTable("catalog.schema.target_table"))
Reference:
https://medium.com/@salah.uddin_75300/architecture-of-a-streaming-machine-learning-data- pipeline-042200c8e7ff
NEW QUESTION # 25
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Tabid.
Table! is written by batch jobs every hour and is queried frequently by filtering two columns named Customerld and EventDate.
You expect Table1 to grow significantly over time.
The rows in Table1 are frequently updated and deleted to support compliance requests.
You need to keep query performance consistent as Table1 grows. The solution must minimize update and deletion effort.
What should you include in the solution? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.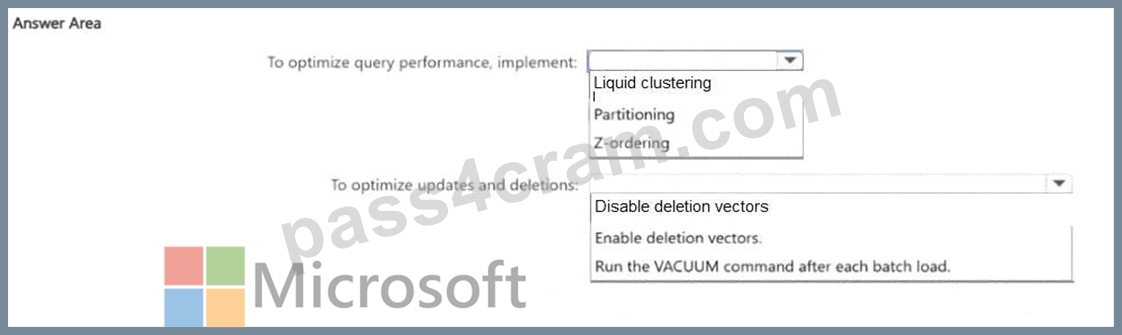
Answer:
Explanation: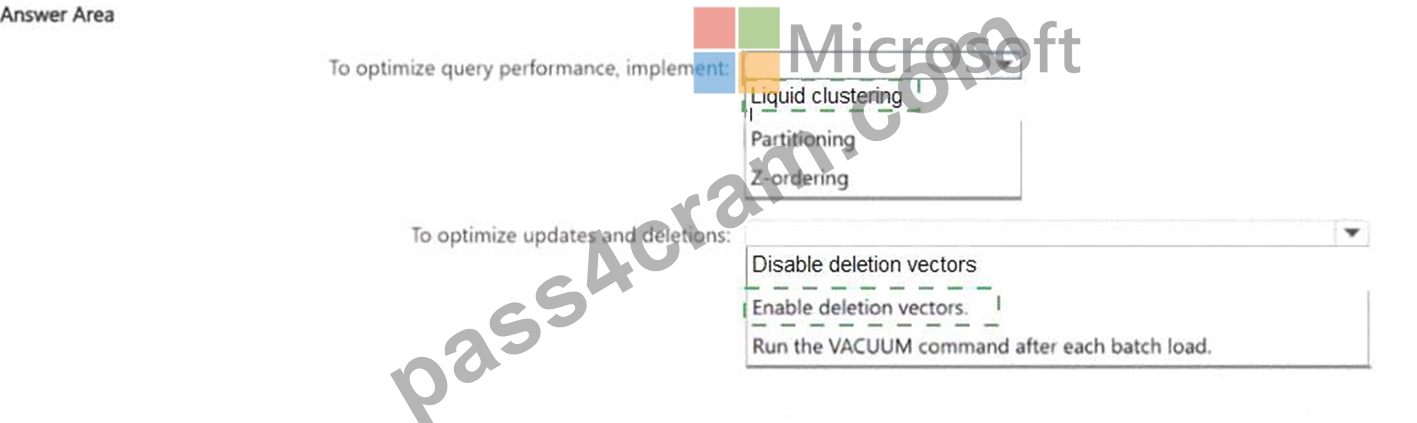
Explanation:
Two features work together to keep performance consistent and update costs low:
OPTIMIZE with ZORDER BY (CustomerId, EventDate). Z-Ordering co-locates rows with the same CustomerId and EventDate values in the same Parquet files. When a query filters on those columns, the Delta engine uses file statistics to skip files that can't possibly contain matching rows (data skipping). As the table grows, skipping scales proportionally - query time stays consistent.
Deletion Vectors (delta.enableDeletionVectors = true). When a row is updated or deleted, instead of rewriting the entire Parquet file, Delta marks the affected row in a small companion deletion vector file. This dramatically reduces write amplification for the frequent compliance-driven updates and deletions the question describes. Actual file rewrites are deferred to the next OPTIMIZE run.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/data-skipping
NEW QUESTION # 26
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster! You need to configure Cluster1 to meet the following requirements;
* The cluster must scale up automatically when workloads increase.
* The cluster must scale down automatically when workloads decrease.
The solution must minimize costs.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,C
Explanation:
The correct answers are C and D. Together they deliver cost-efficient autoscaling:
D (Enable autoscaling) allows the cluster to grow when workloads increase and shrink when they ease off.
This satisfies both scale-up and scale-down requirements without manual intervention.
C (Auto-termination after 30 minutes of inactivity) ensures the cluster stops entirely when no work is running, eliminating the cost of an idle cluster. This is the cheapest possible state.
Option A (disable Photon) reduces compute acceleration - that's a performance regression with no meaningful cost benefit for autoscaling. Option B (compute policy that lets users manage settings) adds governance overhead and doesn't address scaling behaviour. Option E (fixed number of workers) is the opposite of autoscaling - a static worker count that either over-provisions during quiet periods or under- provisions during peaks.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/configure#autoscaling
NEW QUESTION # 27
......
As the authoritative provider of DP-750 guide training, we can guarantee a high pass rate compared with peers, which is also proved by practice. Our good reputation is your motivation to choose our learning materials. We guarantee that if you under the guidance of our DP-750 study tool step by step you will pass the exam without a doubt and get a certificate. Our learning materials are carefully compiled over many years of practical effort and are adaptable to the needs of the exam. We firmly believe that you cannot be an exception. Choosing our DP-750 Exam Questions actually means that you will have more opportunities to be promoted in the near future. If you eventually fail the exam, we will refund the fee by the contract. We are confident that in the future, our DP-750 study tool will be more attractive and the pass rate will be further enhanced.
New DP-750 Exam Vce: https://www.pass4cram.com/DP-750_free-download.html
BTW, DOWNLOAD part of Pass4cram DP-750 dumps from Cloud Storage: https://drive.google.com/open?id=1h39ZICFoy50pWKsoFRMzNDhabhe2Y1Up