BONUS!!! Download part of Exams4Collection DP-800 dumps for free: https://drive.google.com/open?id=1wAlfIHIO1pdZ1xBzojvl0WHHH17GD3-I
You may be also one of them, you may still struggling to find a high quality and high pass rate Developing AI-Enabled Database Solutions study question to prepare for your exam. Your search will end here, because our study materials must meet your requirements. Our product is elaborately composed with major questions and answers. Our study materials are choosing the key from past materials to finish our DP-800 Torrent prep. It only takes you 20 hours to 30 hours to do the practice. After your effective practice, you can master the examination point from the DP-800 exam torrent. Then, you will have enough confidence to pass it. So start with our DP-800 torrent prep from now on. We can succeed so long as we make efforts for one thing.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure, optimize, and deploy database solutions (35–40%) | 35-40% | - Implement data platform resources
|
| Topic 2: Implement AI capabilities in database solutions (25–30%) | 25-30% | - Integrate Azure AI services
|
| Topic 3: Design and develop database solutions (35–40%) | 35-40% | - Implement data management
|
We strongly recommend using our DP-800 exam dumps to prepare for the Microsoft DP-800 certification. It is the best way to ensure success. With our Microsoft DP-800 Practice Questions, you can get the most out of your studying and maximize your chances of passing your Developing AI-Enabled Database Solutions (DP-800) exam.
NEW QUESTION # 25
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have an SDK-style SQL database project stored in a Git repository. The project targets an Azure SQL database.
The CI build fails with unresolved reference errors when the project references system objects.
You need to update the SQL database project to ensure that dotnet build validates successfully by including the correct system objects in the database model for Azure SQL Database.
Solution: Build the project by running dotnet build -bl -flp:v=diag.
Does this meet the goal?
Answer: A
Explanation:
Correct:
* Add the Microsoft.SqlServer.Dacpacs.Azure.Master NuGet package to the project.
To resolve system reference errors in an SDK-style SQL project targeting Azure SQL Database, you need to add a reference to the Microsoft.SqlServer.Dacpacs.Azure.Master NuGet package.
In your .sqlproj file, include the following item group:
<ItemGroup>
<PackageReference Include="Microsoft.SqlServer.Dacpacs.Azure.Master" Version="1.60.0" />
</ItemGroup>
Why this works:
System Objects: Standard SDK-style projects don't automatically include system views (like sys.database_principals or sys.dm_db_resource_stats). This package provides the necessary metadata for the compiler.
Azure Specifics: It includes Azure-only system objects that aren't present in the standard master database dacpac used for on-premises SQL Server.
CI/CD Friendly: Since it is a NuGet package, the dotnet build command will automatically restore it during the CI process without requiring manual file paths or local installations of Visual Studio.
Incorrect:
* Add an artifact reference to the Azure SQL Database master.dacpac file.
* Add the Microsoft.SqlServer.Dacpacs.Master NuGet package to the project.
* Build the project by running dotnet build -bl -flp:v=diag.
Reference:
https://learn.microsoft.com/en-us/sql/tools/sql-database-projects/concepts/system-objects
NEW QUESTION # 26
You have an Azure SQL database named SalesDB that contains a table named dbo. Articles, dbo.Articles contains two million articles with embeddmgs. The articles are updated frequently throughout the day.
You query the embeddings by using VECTOR_SEARQi
Users report that semantic search results do NOT reflect the updates until the following day.
Vou need to ensure that the embeddings are updated whenever the articles change. The solution must minimize CPU usage on SalesDB Which embedding maintenance method should you implement?
Answer: C
Explanation:
The correct answer is B because the problem is not the vector search operator itself. The problem is that embeddings are becoming stale when article content changes . Microsoft documents that change data capture (CDC) tracks insert, update, and delete operations on source tables, which makes it the right mechanism to identify only the rows that changed.
This also best satisfies the requirement to minimize CPU usage on SalesDB . With CDC, the database only records the row changes, and the embedding regeneration work can be moved to an external process such as an Azure Functions app. That avoids running embedding generation inline inside the database for every update and avoids repeatedly recalculating embeddings for unchanged rows. In contrast, an hourly full-table regeneration would be extremely wasteful on a table with two million frequently updated articles, and a trigger that calls embedding generation per row would push expensive AI work into the transactional path of the database.
Option A is incorrect because changing from VECTOR_SEARCH to VECTOR_DISTANCE does not regenerate embeddings; it only changes the retrieval method. Microsoft states that VECTOR_SEARCH is the ANN search function, while VECTOR_DISTANCE performs exact distance calculation, so neither option addresses stale embedding data.
So the right design is:
* use CDC to detect only changed articles,
* process those changes outside the database,
* regenerate embeddings only for changed rows,
* write back the refreshed embeddings for current semantic search results.
NEW QUESTION # 27
You are developing an Azure SQL solution by using Microsoft Visual Studio 2026. The solution uses a GitHub repository.
You plan to use GitHub Copilot Chat to access the GitHub repository tools by connecting to the GitHub MCP Server.
You need to configure Visual Studio to support the planned configuration. The solution must rely on OAuth to access the MCP server.
What should you create?
Answer: A
Explanation:
In this scenario, you need to create an mcp.json file. This file acts as the configuration bridge that tells Visual Studio 2026 and GitHub Copilot Chat how to connect to and communicate with the GitHub MCP Server.
Key Configuration Details
The mcp.json file is typically placed in your solution's root directory or a specific .mcp folder to enable project-specific tools Configuration Steps
1. Create the MCP Configuration File
You must define the connection to the GitHub MCP server so Copilot Chat can interact with your repository tools.
File Name: mcp.json
Location: Usually placed in %AppData%\Microsoft\VisualStudio\2026\mcp.json (or the project root depending on your specific extension settings).
Content:
{
"mcpServers": {
"github": {
"url": "https://api.githubcopilot.com/mcp/",
"auth": "OAuth"
}
}
}
2. Authenticate via OAuth
3. Connect Azure SQL in VS 2026
Reference:
https://www.workato.com/the-connector/mcp-server-tutorial/
NEW QUESTION # 28
You have an Azure SQL database that contains tables named dbo.ProductDocs and dbo.ProductDocsEmbeddings. dbo.ProductDocs contains product documentation and the following columns:
- DocID (int)
- Title (nvarchar(200))
- Body (nvarchar(max))
- LastModified (datetime2)
The documentation is edited throughout the day.
dbo.ProductDocsEmbeddings contains the following columns:
- DocID (int)
- ChunkOrder (int)
- ChunkText (nvarchar(max))
- Embedding (vector(1536))
The current embedding pipeline runs once per night.
You need to ensure that embeddings are updated every time the underlying documentation content changes. The solution must NOT require a nightly batch process.
What should you include in the solution?
Answer: B
Explanation:
To ensure embeddings are updated immediately when the product information table changes, you should implement Azure SQL Database Change Tracking combined with Azure Functions triggered via Event Grid. This approach eliminates daily batch processes by enabling an event- driven architecture that triggers embedding regeneration only for modified rows.
Reference:
https://medium.com/@granthgharewal/why-change-tracking-needs-to-be-enabled-for-sql-trigger- azure-functions-7d230a669fb8
NEW QUESTION # 29
Case Study 2 - Fabrikam
Existing Environment
Azure Environment
Fabrikam has a single Azure subscription in the East US 2 Azure region. The subscription contains an Azure SQL database named DB1. DB1 contains the following tables:
* Patients
* Employees
* Procedures
* Transactions
* UsefulPrompts
* ProcedureDocuments
You store a column master key as a secret in Azure Key Vault.
You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Problem Statements
Users report that after executing a long-running stored procedure named sp_UpdateProcedureForPatient, updates to the underlying data are sometimes inconsistent.
Requirements
Planned Changes
Fabrikam plans to manage all changes to Azure SQL Database objects by using source control in GitHub. Every pull request submitted to production will be validated before it can be merged.
Deployments must use the Release configuration.
Security Requirements
Fabrikam identifies the following security requirements:
* The TransactionProcessing application must use a passwordless connection to DB1.
* The Employees table contains two columns named TaxID and Salary that must be encrypted at rest.
* Auditors must have a tamper-evident history of transactions with cryptographic proof of changes to the employee data.
Database Performance Requirements
Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
AI Search, Embeddings, and Vector Indexing
Fabrikam identifies the following AI-related requirements:
* Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
* Users must be able to query the data in DB1 by using prompts in Copilot in Microsoft Fabric.
* The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
Development Requirements
Fabrikam identifies the following development requirements:
* Provide the functionality to retrieve all the transactions of a given patient between two dates, showing a running total.
* Expose a Data API builder (DAB) configuration file to enable Azure services to perform the following operations over a REST API:
- Read data from the procedures table without authentication.
- Read and insert data into the Transactions table once authenticated.
- Execute the sp_UpdateProcedurePatient stored procedure.
* Provide the functionality to retrieve a list of the names of patients who underwent medical procedures during the last 30 days.
* Information for each medical procedure will be stored in a table. The table will be used with a large language model (LLM) for user querying and will have the following structure.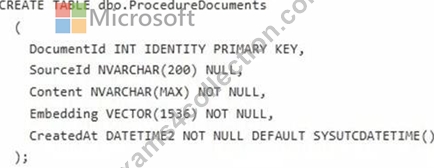
DAB
You create a DAB configuration file that meets the development requirements for DB1 and includes the following entities.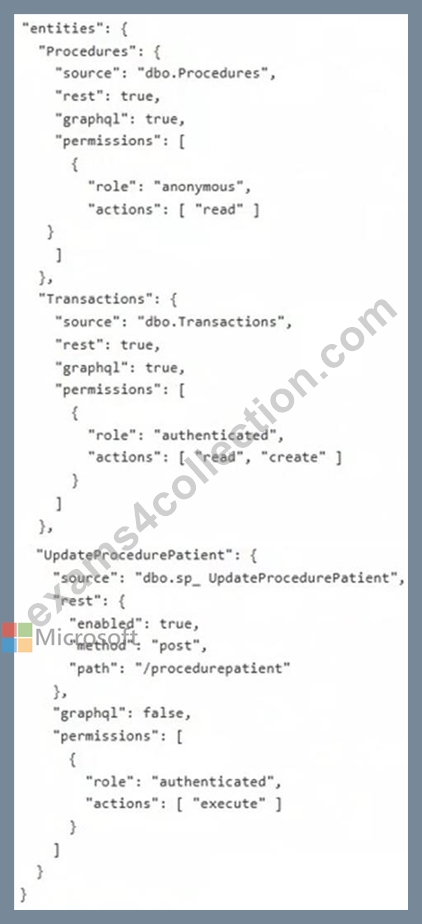
You implement ProcedureDocuments to support the planned changes.
When users consume data through the Retrieval Augmented Generation (RAG) pattern, they experience data retrieval delays.
You need to improve the data retrieval performance and reduce the number of tokens per retrieval.
What should you implement?
Answer: D
Explanation:
Scenario: Fabrikam identifies the following AI-related requirements: Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
To remedy data retrieval delays in a Retrieval Augmented Generation (RAG) pattern using Reciprocal Rank Fusion (RRF) on an Azure SQL Database table, you should use embeddings.
In a RAG architecture, retrieval delays often stem from inefficient or computationally heavy search processes. While RRF is excellent for merging results from multiple sources (like combining keyword and vector searches), the core of the speed problem typically lies in how the initial data is indexed and retrieved.
Role of Embeddings
Vector Search Acceleration: Embeddings convert text into high-dimensional vectors. Azure SQL Database can perform similarity searches on these vectors much faster than complex semantic text matching.
Hybrid Search Synergy: RRF is most effective when it fuses results from a keyword search (fast) and a vector search (powered by embeddings). Using embeddings ensures that the "semantic" side of the retrieval is streamlined.
Pre-computation: Since embeddings are generated once during ingestion, the retrieval phase only requires a distance calculation (e.g., Cosine Similarity), which is significantly faster than real- time natural language parsing during each query.
Reference:
https://pratikbarjatya.medium.com/unlocking-the-power-of-language-with-retrieval-augmented- generation-rag-14123cc275e6
NEW QUESTION # 30
......
There are a lot of excellent experts and professors in our company. In the past years, these experts and professors have tried their best to design the DP-800 exam questions for all customers. More importantly, we believe once you finally gain the DP-800 certification with our DP-800 exam questions and you will find enormous benefits: more enjoyment of life and better relationships and less stress and a better quality of life overall. So it is very significant for you to do everything in your power to pass the DP-800 Exam and get the related certification.
Valid DP-800 Practice Materials: https://www.exams4collection.com/DP-800-latest-braindumps.html
P.S. Free & New DP-800 dumps are available on Google Drive shared by Exams4Collection: https://drive.google.com/open?id=1wAlfIHIO1pdZ1xBzojvl0WHHH17GD3-I