Es ist nicht unmöglich, die Microsoft DP-800 Prüfung leicht zu bestehen. Dieses Gefühl haben schon viele Benutzer der Microsoft DP-800 Prüfungssoftware von unserer ZertFragen empfunden. Dieses Gefühl können Sie auch empfinden, solange Sie unsere kostenlose Demo probieren. Wir sind verantwortlich für jeder Kunde, der unsere Produkte wählt, und garantieren, dass unsere Kunden immer die neueste Version von Microsoft DP-800 Prüfungssoftware benutzen.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Microsoft Developing AI-Enabled Database Solutions (DP-800) |
| Exam Number: | DP-800 |
| Exam Format: | Multiple choice, Case studies |
| Certificate Validity Period: | 1 year (Microsoft role-based certifications require annual renewal) |
| Passing Score: | 700/1000 (typical Microsoft passing score; subject to confirmation) |
| Available Languages: | English |
| Recommended Training: | Microsoft Learn - Azure Data & AI Learning Paths |
| Exam Registration: | Microsoft Certification Dashboard |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or onsite testing center |
| Pre Condition: | No formal prerequisites required, but familiarity with Azure data services and database concepts is recommended |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/ |
Welche Schulungsunterlagen zur Microsoft DP-800 Zertifizierungsprüfung sind die zuverlässigste unten zahlreichen Webseiten? Selbstvertsändlich sind die Lehrbücher von ZertFragen die genauigste. ZertFragen verfügt über professionelle ausgebildete Arbeitnehmer, Zertifizierungsexperten, Techniker sowie Sprachmaster, sie erforschen ständig die neuesten Microsoft DP-800 Prüfung und aktualisieren sie. Deswegen können Sie ganz beruhigt unsere Schulungsunterlagen zur Microsoft DP-800 Zertifizierungsprüfung benutzen, und wir versprechen Ihnen, dass Sie die Microsoft DP-800 Zertifizierungsprüfung bestimmt bestehen können.
| Thema | Einzelheiten |
|---|---|
| Thema 1 |
|
| Thema 2 |
|
| Thema 3 |
|
88. Frage
You need to meet the development requirements for the FeedbackJson column How should you complete the Transact SQL query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.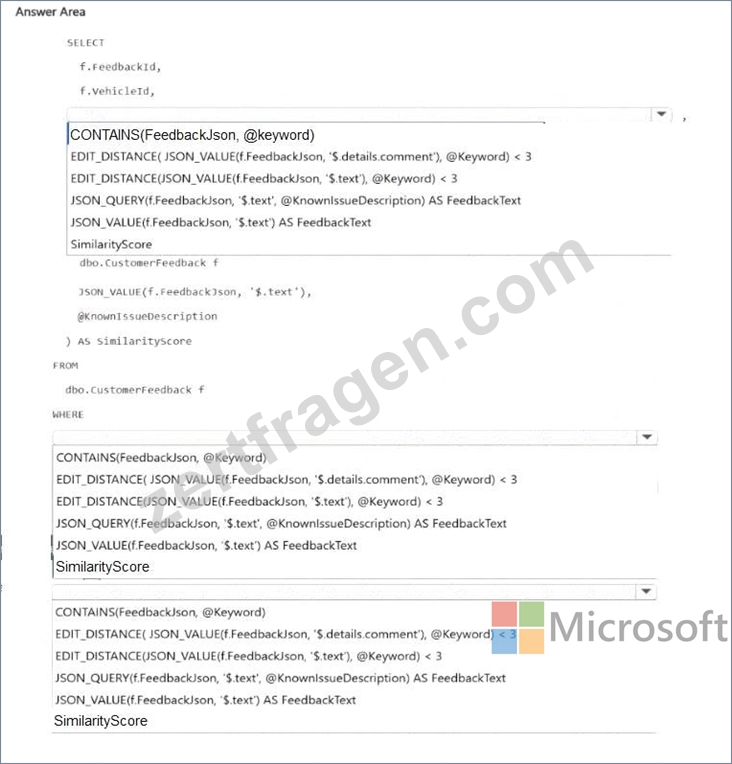
Antwort:
Begründung: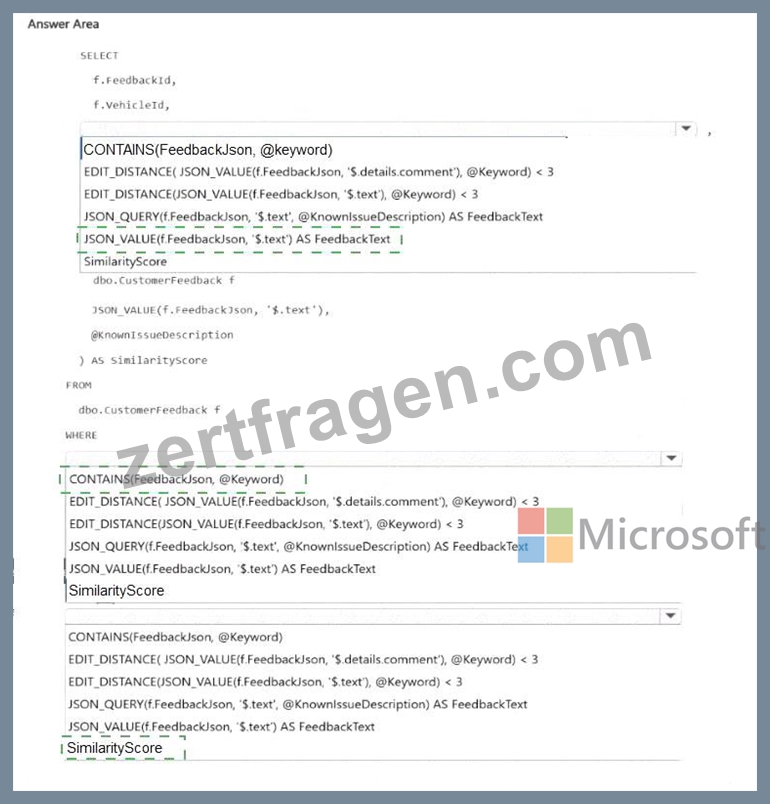
Explanation:
JSON_VALUE(f.FeedbackJson, ' $.text ' ) AS FeedbackText
CONTAINS(FeedbackJson, @Keyword)
SimilarityScore
These three selections are the correct way to complete the query because they align exactly with the stated requirements for the FeedbackJson column.
First, to extract the customer feedback text from the JSON document , the correct expression is JSON_VALUE(f.FeedbackJson, ' $.text ' ) AS FeedbackText . Microsoft documents that JSON_VALUE is used to extract a scalar value from JSON, while JSON_QUERY is used for returning an object or array .
Since $.text is the textual feedback string, JSON_VALUE is the correct function.
Second, to filter rows where the JSON text contains a keyword , the best choice is CONTAINS (FeedbackJson, @Keyword) . The scenario explicitly states that FeedbackJson already has a full-text index
, and Microsoft documents that CONTAINS is the full-text predicate used in the WHERE clause to search full-text indexed character data. That makes it more appropriate than using EDIT_DISTANCE for keyword filtering.
Third, to order the results by similarity score, highest first , the correct item is SimilarityScore in the ORDER BY clause, which would be paired with DESC in the query. This matches the requirement to sort by the computed fuzzy similarity value. The DP-800 study guide specifically includes writing queries that use fuzzy string matching functions such as EDIT_DISTANCE, which supports the earlier computed SimilarityScore expression in the query.
89. Frage
Hotspot Question
You have an Azure SQL database that contains a table named Table1. Table1 contains
25,000,000 rows of data and a datetime2 column named DateKey. The data in Table1 spans the years 2020 through 2021.
You need to partition the data in Table1 by year. The solution must minimize how long it takes to rebuild or reindex the table.
How should you complete the Transact-SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.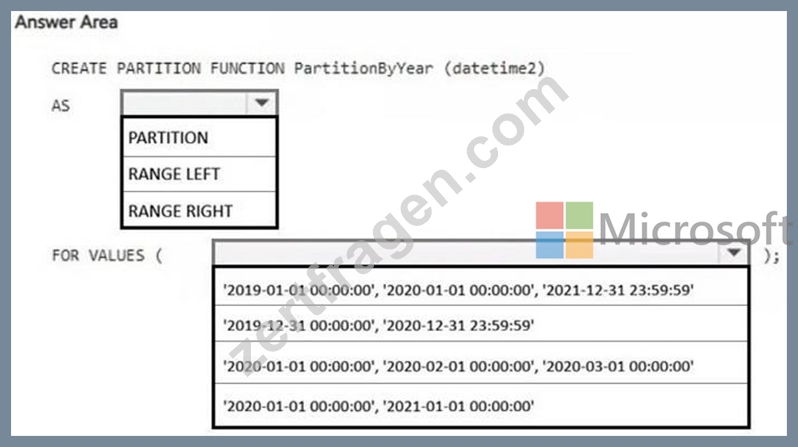
Antwort:
Begründung: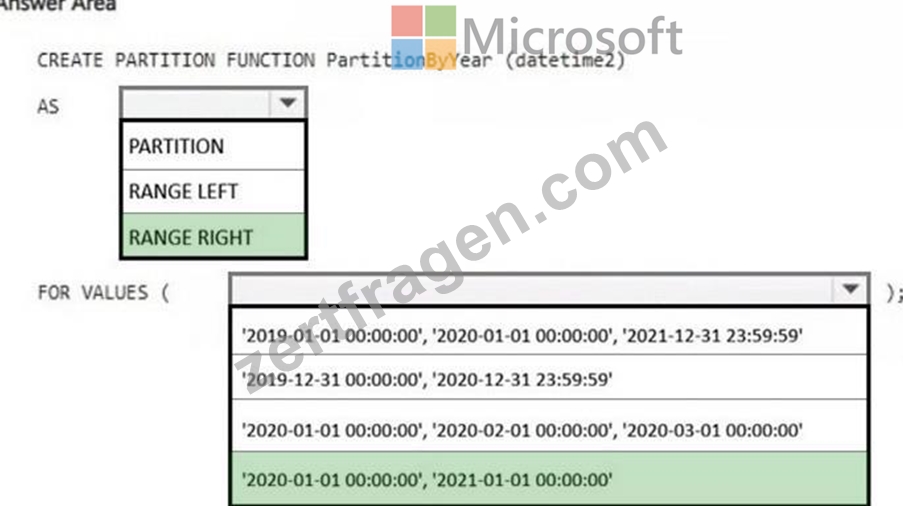
90. Frage
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders, dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.orders.
Solution: Run the following Transact-SQL statement.
DELETE FROM dbo.Orders
WHERE OrderDate < DATEADD(nonth, -36, SYSUTCDATETIME());
Does this meet the goal?
Antwort: A
Begründung:
This does not meet the goal. A row-by-row DELETE against the oldest month is not the lowest-impact way to purge data from a monthly partitioned table. Microsoft's partitioning guidance specifically says partitioning lets you perform maintenance and retention operations more efficiently by targeting just the relevant partition, including the ability to truncate data in a single partition .
The proposed statement:
DELETE FROM dbo.Orders
WHERE OrderDate < DATEADD(month, -36, SYSUTCDATETIME());
would log row deletions and can hold locks longer, creating more overhead for other queries than a partition- level maintenance operation. Since the table is already partitioned by month , the expected low-impact approach is to operate on the oldest partition directly, not issue a broad delete predicate over rows. Microsoft explicitly highlights partition-targeted truncation as a faster, more efficient retention operation than working against the whole table or rowset.
91. Frage
You have an Azure SQL database That contains a table named dbo.Products, dbo.Products contains three columns named Embedding Category, and Price. The Embedding column is defined as VECTOR(1536).
You use Ai_GENERME_EMBEDOINGS and VECTOR_SEARCH to support semantic search and apply additional filters on two columns named Category and Price.
You plan to change the embedding model from text-embedding-ada-002 to text-embedding-3-smalL Existing rows already contain embeddings in the Embedding column.
You need to implement the model change. Applications must be able to use VECTOR_SEARCH without runtime errors.
What should you do first?
Antwort: C
Begründung:
When you change embedding models, the stored vectors should be treated as belonging to a different embedding space unless you intentionally keep the entire corpus consistent. Microsoft's vector guidance notes that when most or all embeddings are replaced with fresh embeddings from a new model, the recommended practice is to reload the new embeddings and, for large-scale replacement scenarios, consider dropping and recreating the vector index afterward so search quality remains predictable.
This question also says applications must continue to use VECTOR_SEARCH without runtime errors .
VECTOR_SEARCH requires compatible vector dimensions, and the vector column already exists. Azure OpenAI documentation shows that text-embedding-ada-002 is fixed at 1536 dimensions and text- embedding-3-small supports up to 1536 dimensions . That means the migration can remain compatible with a VECTOR(1536) column, but the right implementation step is still to re-embed the existing rows so the table does not contain a mixed corpus produced by different models.
The other options are not appropriate:
* B normalization does not solve a model migration problem.
* C converting the vector column to nvarchar(max) would break vector-native search design.
* D a vector index improves performance, but it does not migrate old embeddings to the new model.
92. Frage
You have a Microsoft SQL Server 2025 database that contains a table named products. products contains two columns named description and embedding. embedding is generated from description.
You have an application named App1. App1 has a feature that uses the following query.
VECTOR_DISTANCE('cosine', @query_vector, embedding)
Users report that the feature is slow during peak usage times.
You discover that during peak usage times, the semantic search latency increases and CPU utilization spikes.
You need to reduce latency and CPU utilization related to the App1 feature.
What should you do?
Antwort: A
Begründung:
The correct answer is C because the current query uses VECTOR_DISTANCE( ' cosine ' , @query_vector, embedding) , which performs an exact vector distance calculation . Microsoft explicitly documents that VECTOR_DISTANCE does not use a vector index , even when one exists. Exact k-nearest-neighbor searches can require scanning large numbers of vectors and calculating distances row by row, which explains the observed CPU spikes and increased semantic-search latency during peak load.
A vector index on products.embedding is specifically designed to accelerate nearest-neighbor search, and VECTOR_SEARCH is the Transact-SQL function that can use that approximate nearest-neighbor index when the index metric matches the query metric. Using METRIC = ' cosine ' preserves the same similarity metric currently used by App1 while reducing the amount of computation required.
The other choices are incorrect:
* A normalizes vectors but does not replace the expensive exact search with indexed ANN retrieval.
* B replaces semantic vector search with lexical full-text search and changes the feature's behavior.
* D a standard nonclustered B-tree index cannot accelerate vector-distance operations.
* E converting embeddings to VARBINARY(8000) removes native vector semantics and does not solve the performance problem.
Therefore, the exam-aligned solution is create a vector index and use VECTOR_SEARCH with cosine distance .
93. Frage
......
DP-800 Quizfragen Und Antworten: https://www.zertfragen.com/DP-800_prufung.html