DOWNLOAD the newest ExamCost DY0-001 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1EYMTV01bZE68Us53g-VUf5v8t623rH65
For candidates who are going to buy the DY0-001 training materials online, the safety of the website is significant. We have professional technicians examine the website every day, if you buying DY0-001 exam braindumps from us, we will provide you with a clean and safe online shopping environment. Besides, we offer you free update for one year, and you can get the latest information about DY0-001 Exam Braindumps timely, so that you can change learning ways according to the new changes.
| Certification Vendor: | CompTIA |
|---|---|
| Exam Name: | CompTIA DataAI Certification Exam (V1) |
| Exam Number: | DY0-001 |
| Exam Format: | Performance-based questions, Multiple-choice |
| Real Exam Qty: | Up to 90 |
| Available Languages: | English, Japanese |
| Certificate Validity Period: | Approximately 3 years from launch (retirement expected around 2027) |
| Exam Duration: | 165 minutes |
| Passing Score: | Pass/Fail (no scaled score) |
| Related Certifications: | CompTIA DataX |
| Recommended Training: | CompTIA CertMaster Learn (DataAI) CompTIA Official Training Partners |
| Exam Registration: | CompTIA DataAI Official Page Pearson VUE CompTIA Registration |
| Sample Questions: | CompTIA DY0-001 Sample Questions |
| Exam Way: | Test center or online proctored exam (Pearson VUE) |
| Pre Condition: | Recommended: 5+ years experience in data science, analytics, or related technical roles |
| Official Syllabus URL: | https://www.comptia.org/en-us/certifications/dataai/ |
>> DY0-001 Exam Passing Score <<
To increase your chances of success, consider utilizing the DY0-001 Exam Questions, which are valid, updated, and reflective of the actual DY0-001 Exam. Don't miss the opportunity to strengthen your CompTIA DY0-001 exam preparation with these valuable questions.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 62
A data scientist has built a model that provides the likelihood of an error occurring in a factory. The historical accuracy of the model is 90%. At a specific factory, the model is reporting a likelihood score of 0.90. Which of the following explains a confidence score of 0.90?
Answer: B
Explanation:
# A likelihood score of 0.90 indicates the model's confidence that an error will occur in this particular instance. Interpreted probabilistically, it means that if this scenario happened 100 times, the model would expect an error in 90 of those cases.
Why the other options are incorrect:
* A: Confuses confidence with recall or precision.
* B: Refers to model sampling performance, not instance-level prediction.
* C: Implies a prediction of actual factory errors - not the model's forecast probability.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.2:"A confidence score in a classification model indicates the model's belief in the outcome of a specific prediction."
-
NEW QUESTION # 63
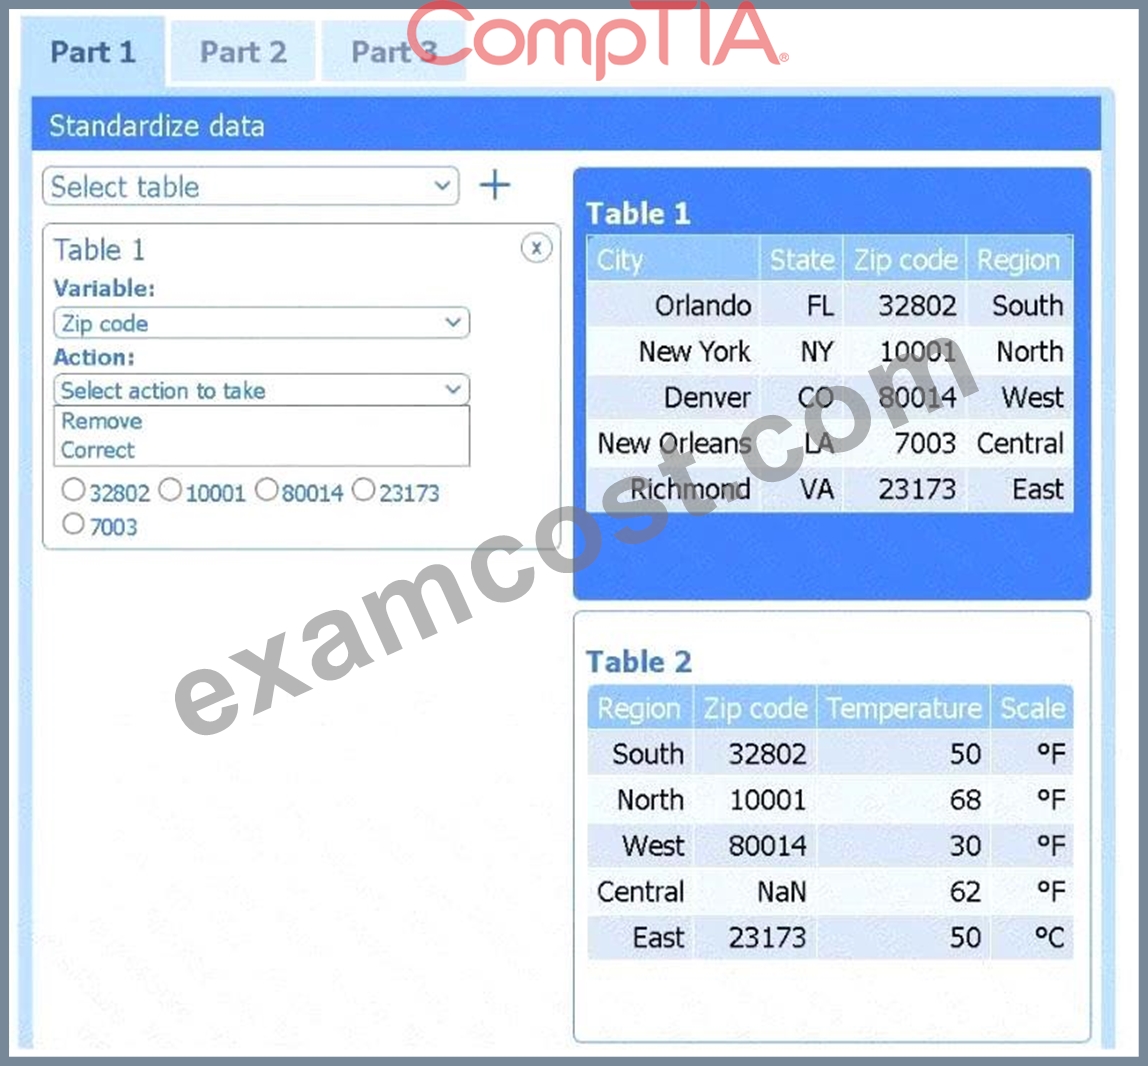
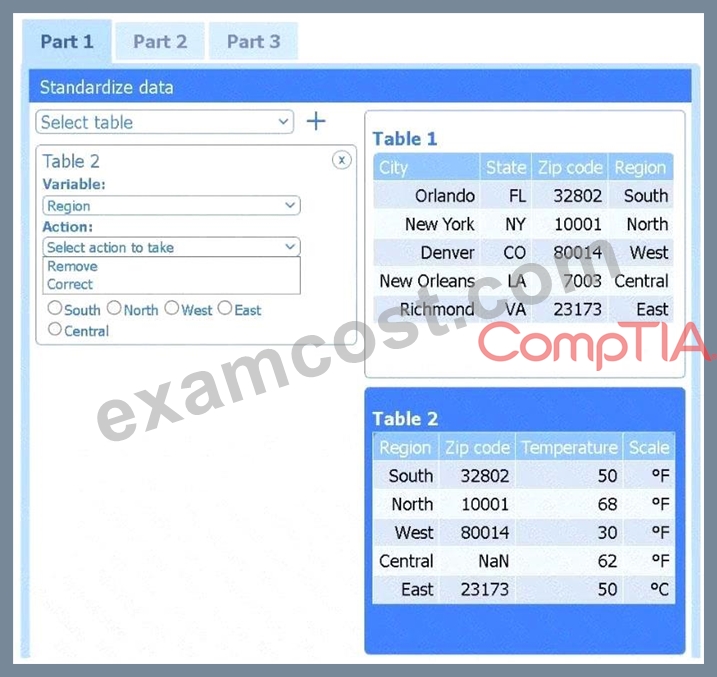
A client has gathered weather data on which regions have high temperatures. The client would like a visualization to gain a better understanding of the data.
INSTRUCTIONS
Part 1
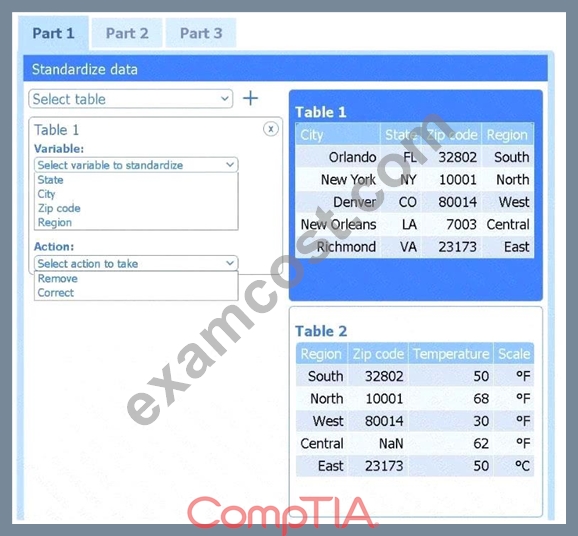
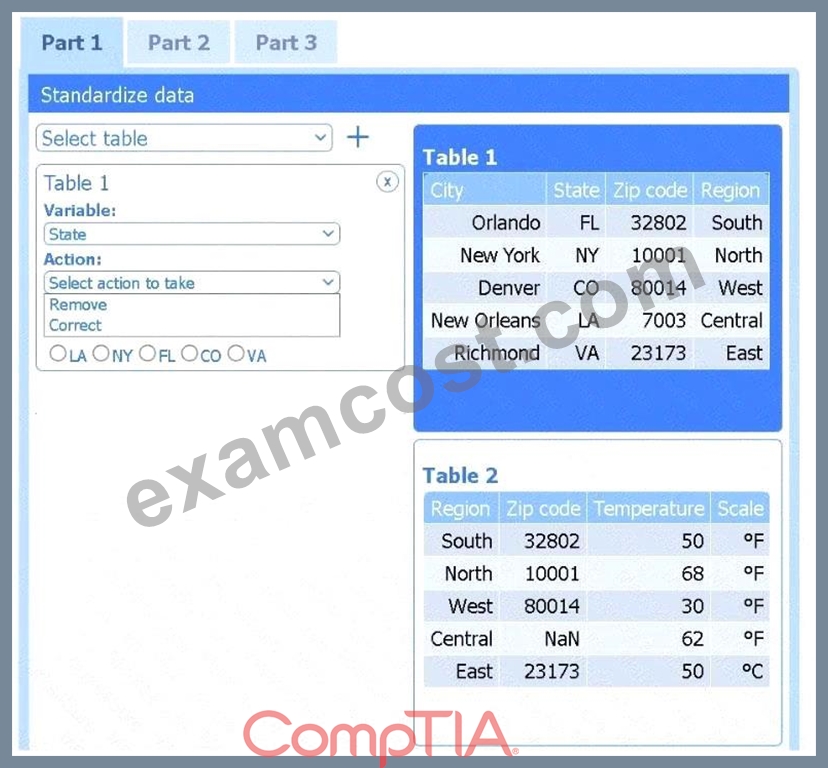
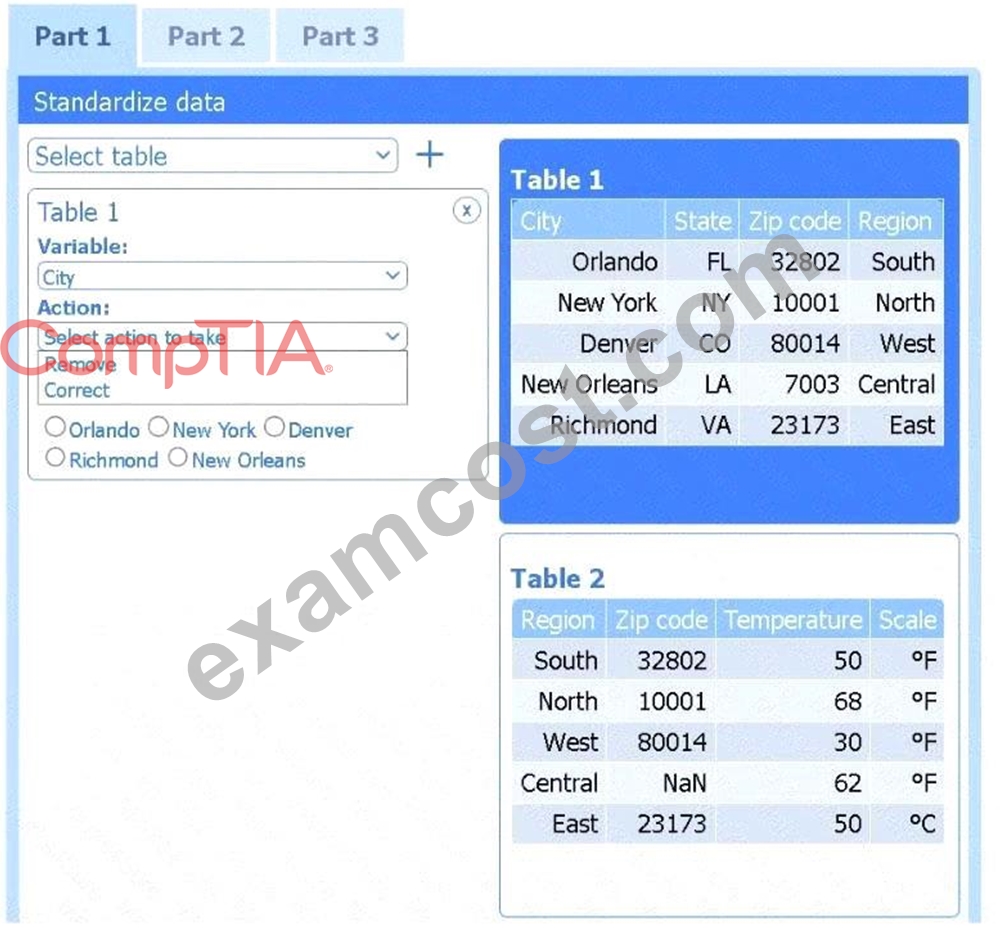
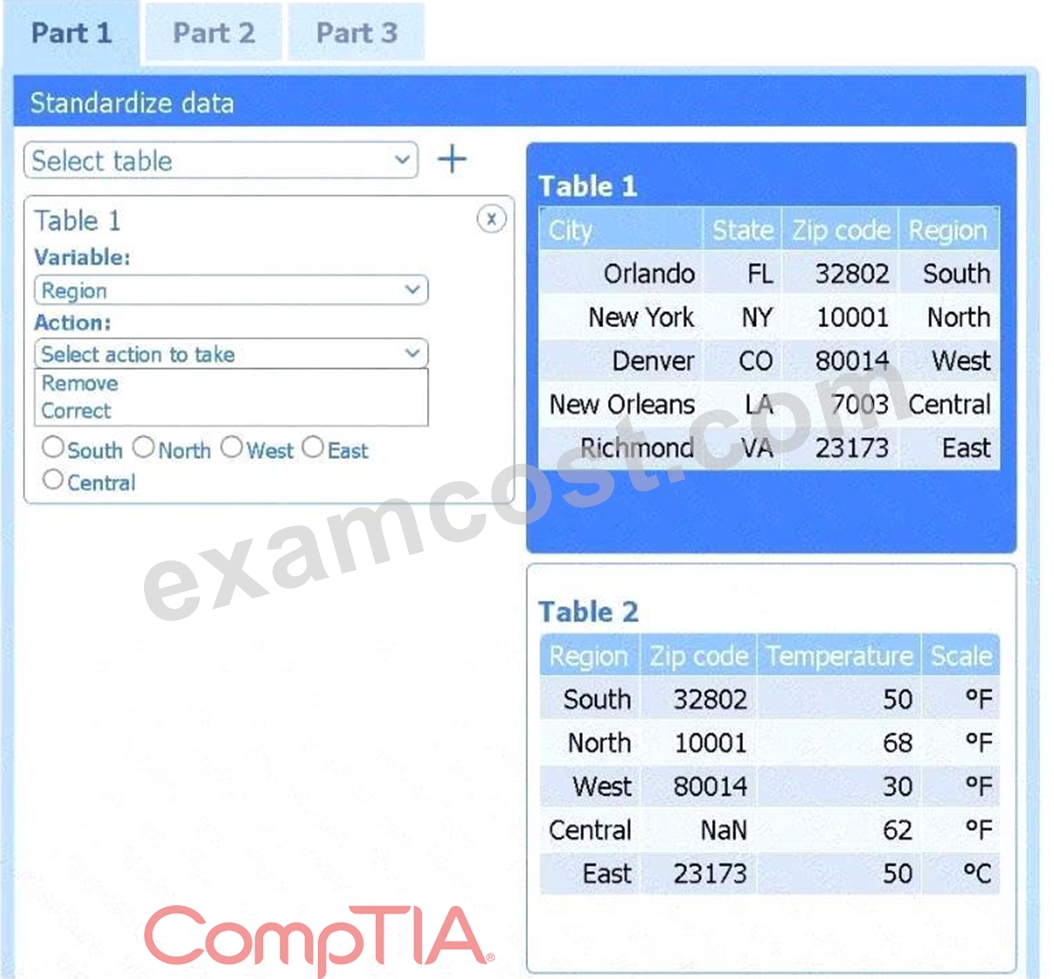
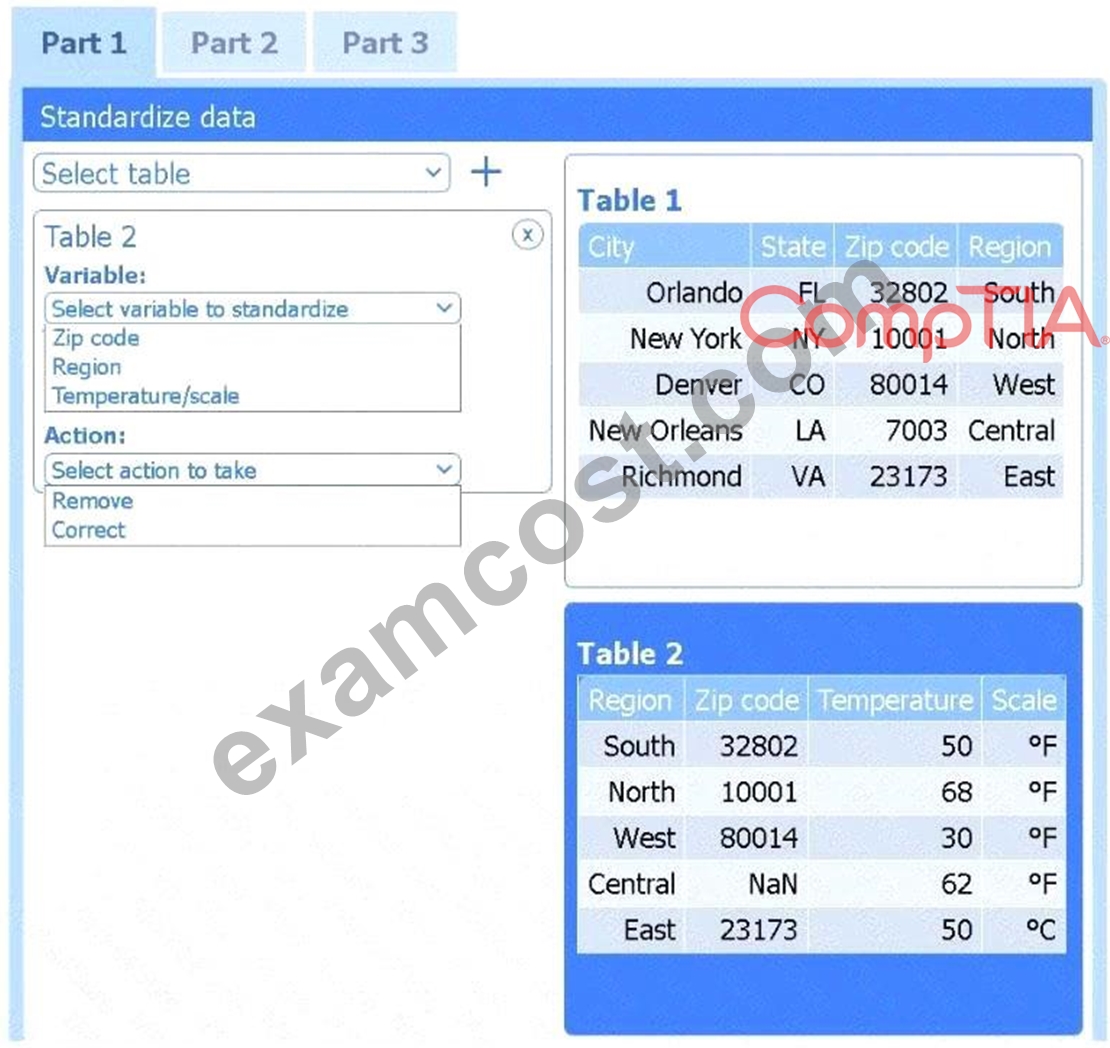
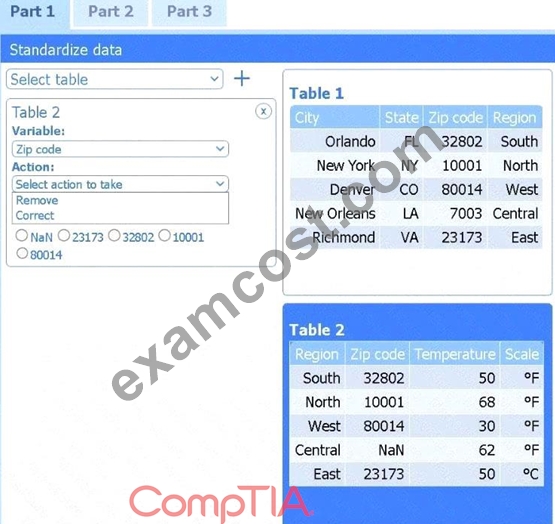
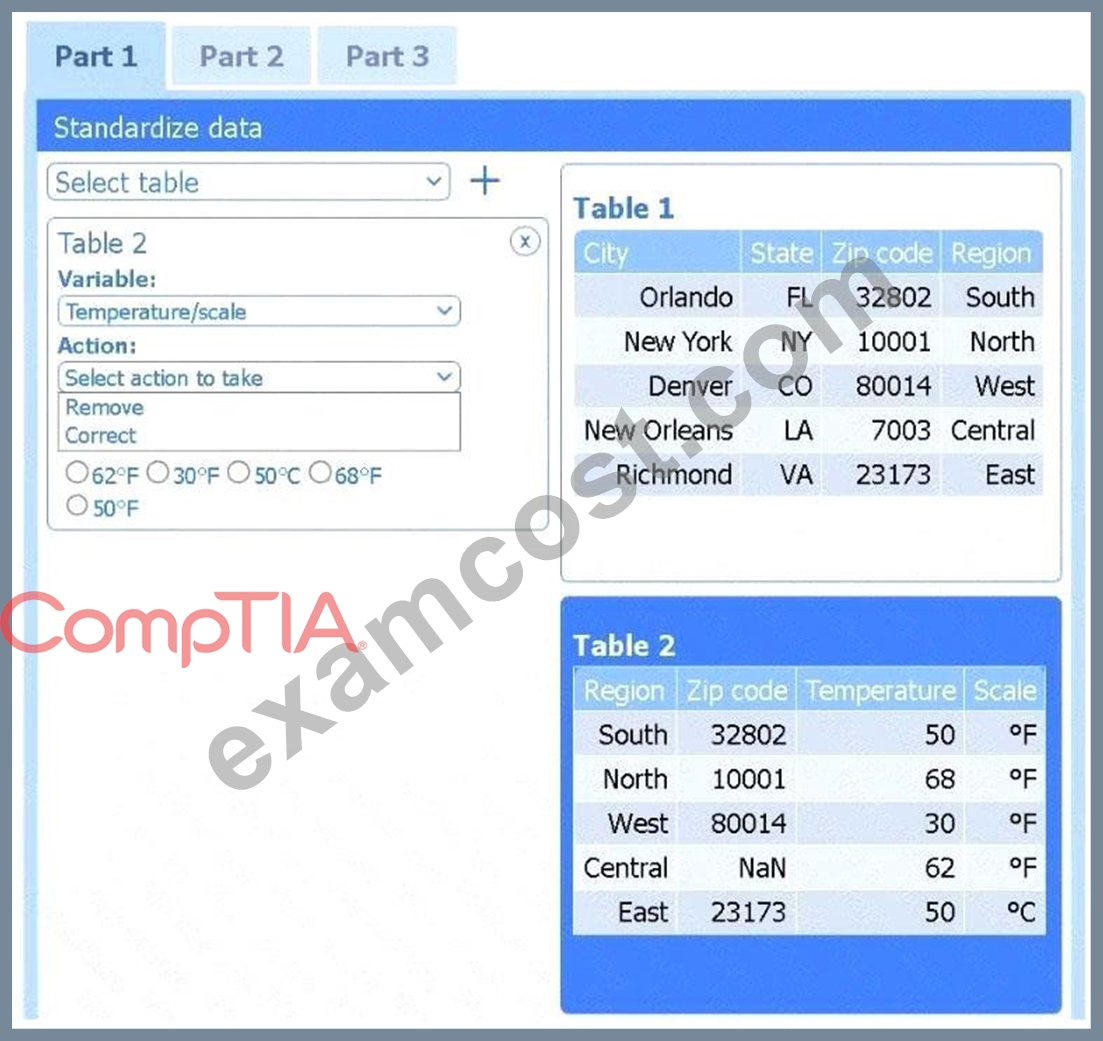
Review the charts provided and use the drop-down menu to select the most appropriate way to standardize the data.
Part 2
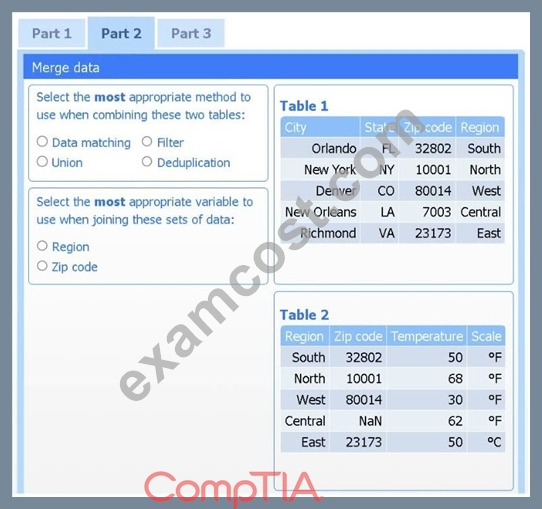
Answer the questions to determine how to create one data set.
Part 3
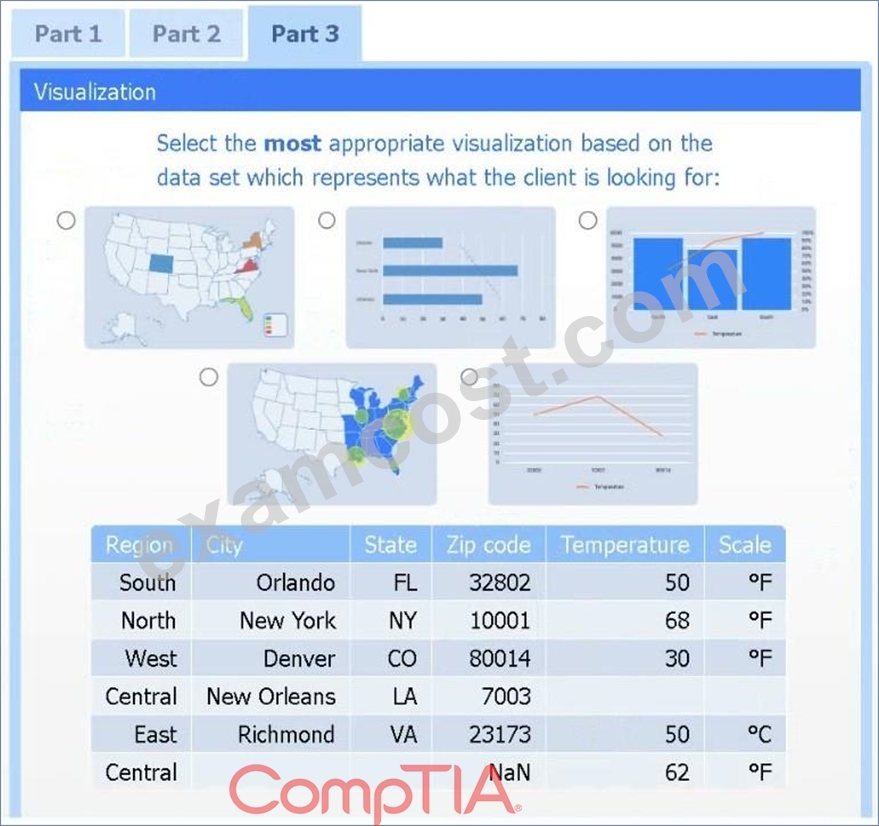
Select the most appropriate visualization based on the data set that represents what the client is looking for.
If at any time you would like to bring back the initial state of the simulation, please click the Reset All button.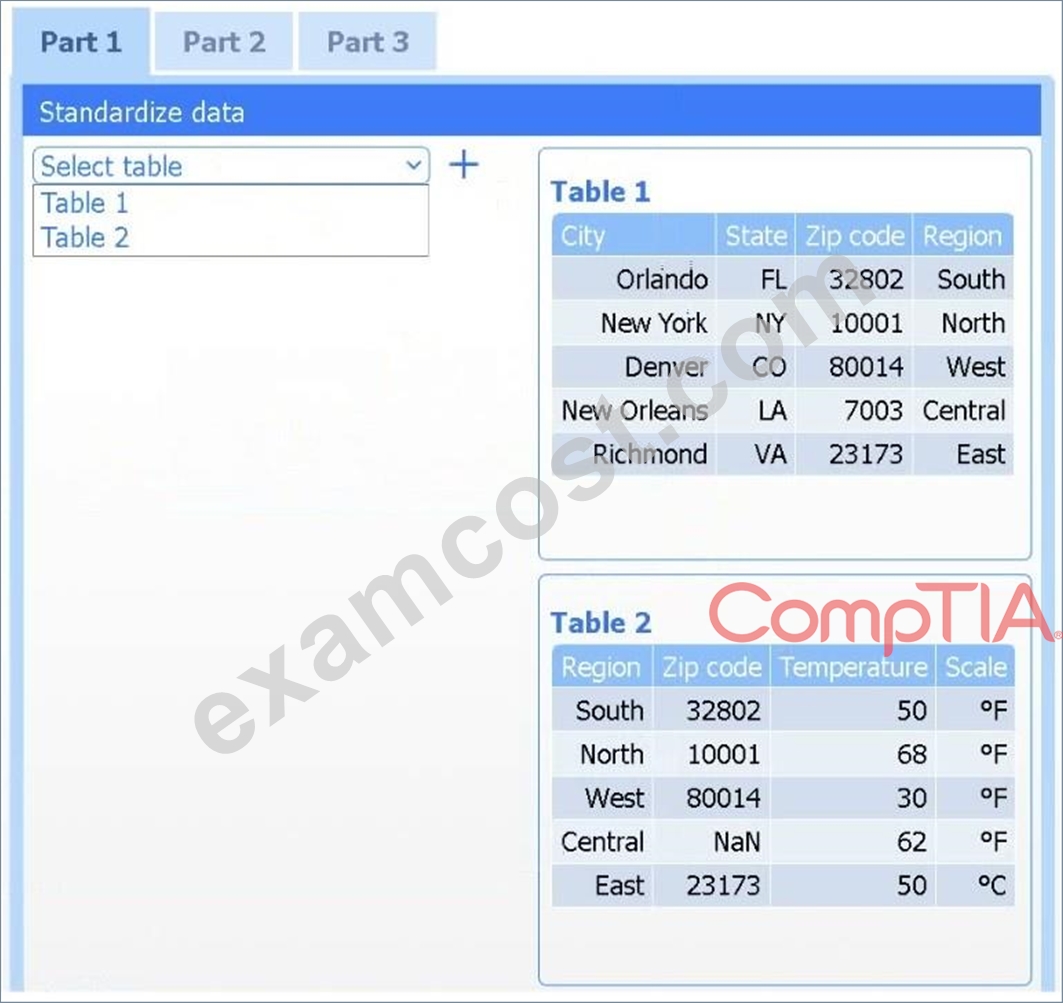
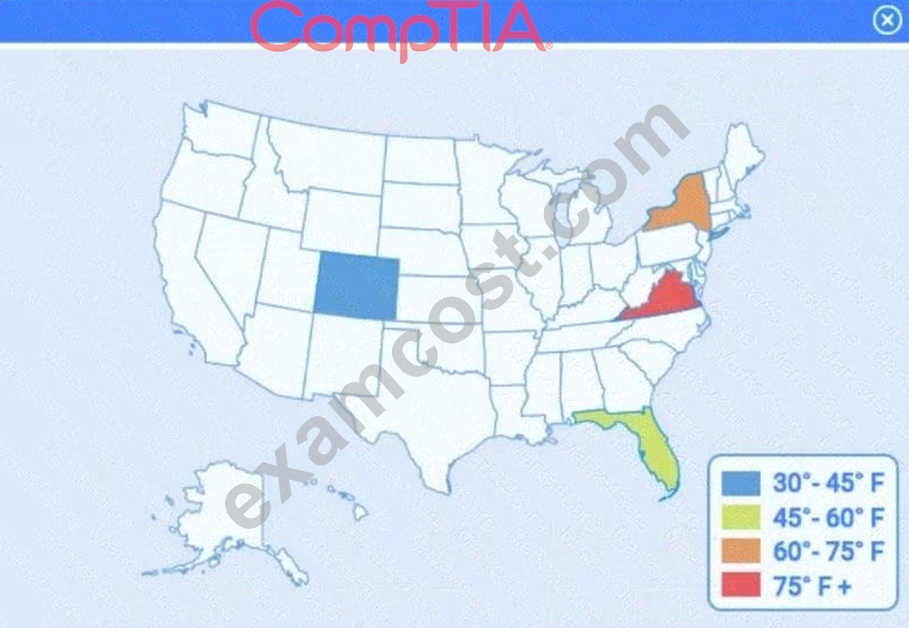
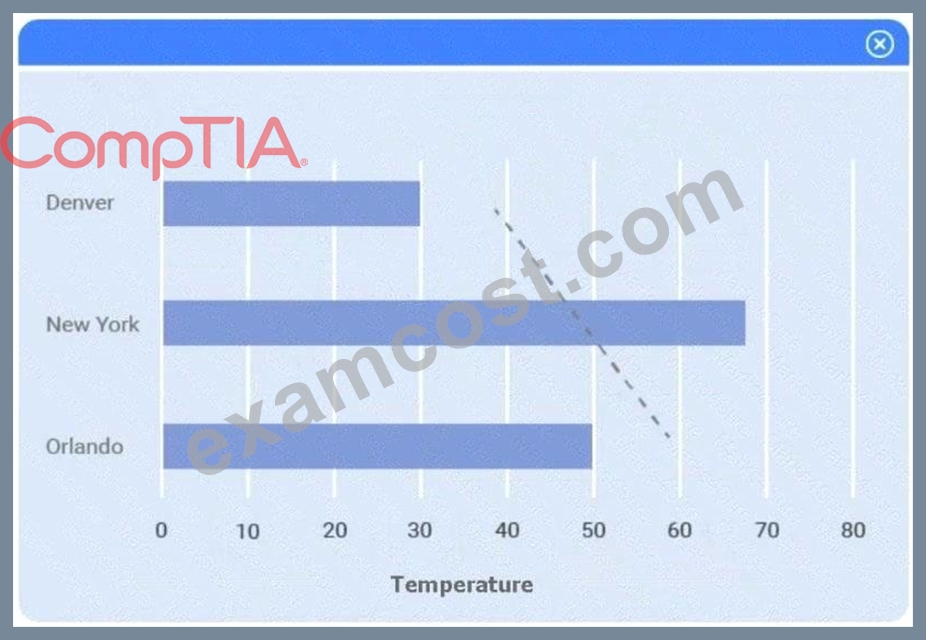
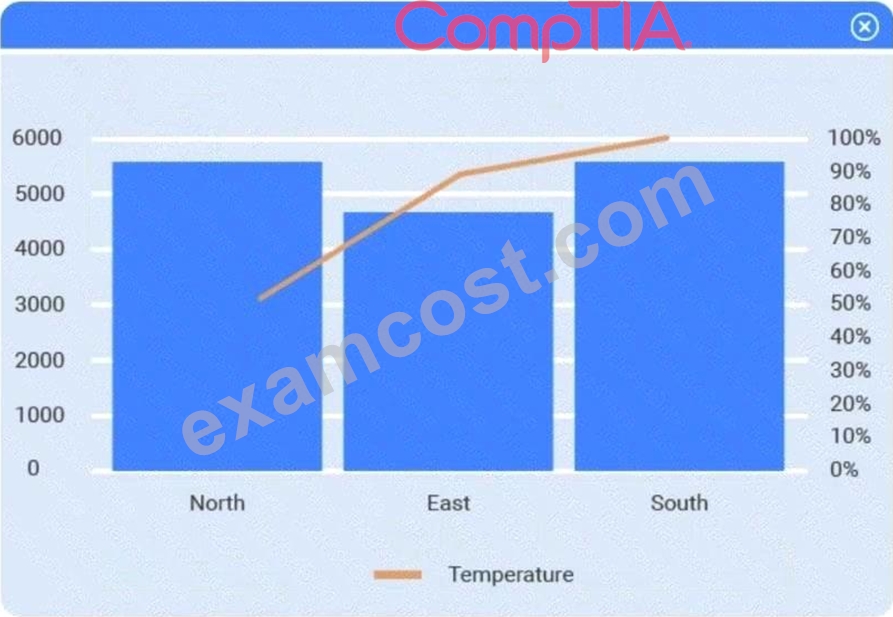
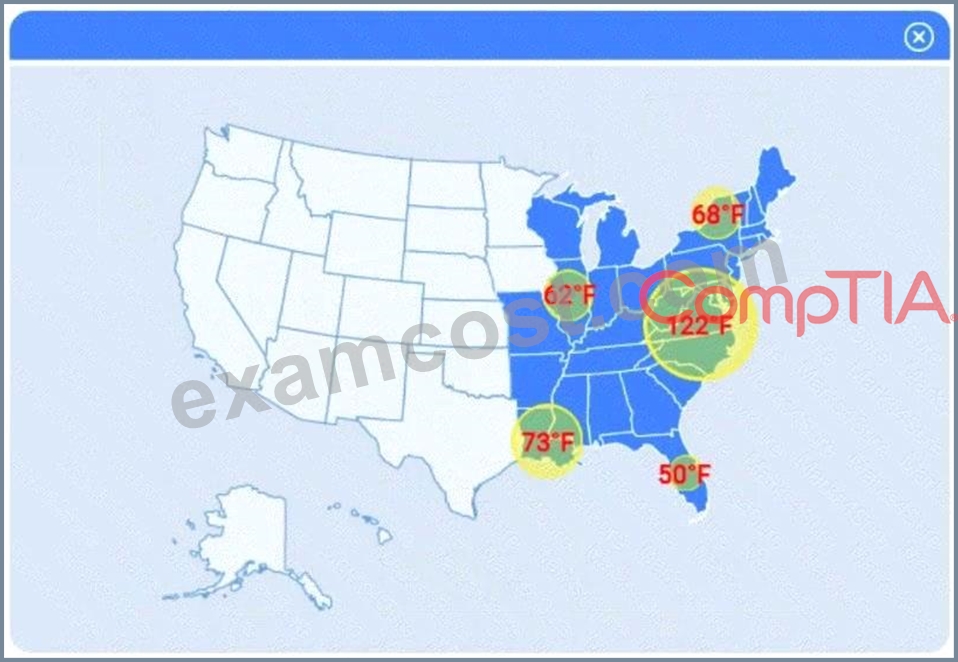
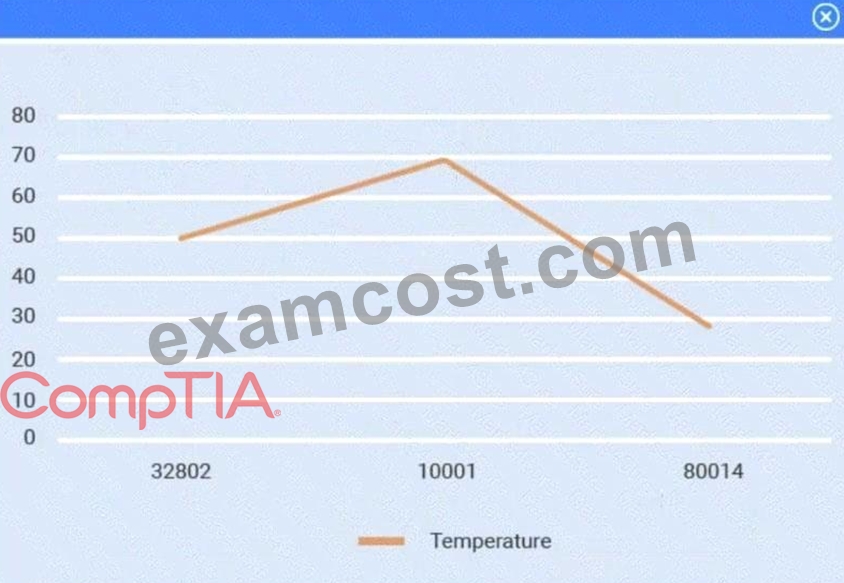
Answer:
Explanation:
See explanation below.
Explanation:
Part 1
Select Table 2. Table 2 contains mixed temperature scales (°F and °C) that must be standardized before visualization.
Variable: Temperature/scale
Action: Correct
Value to correct: 50 °C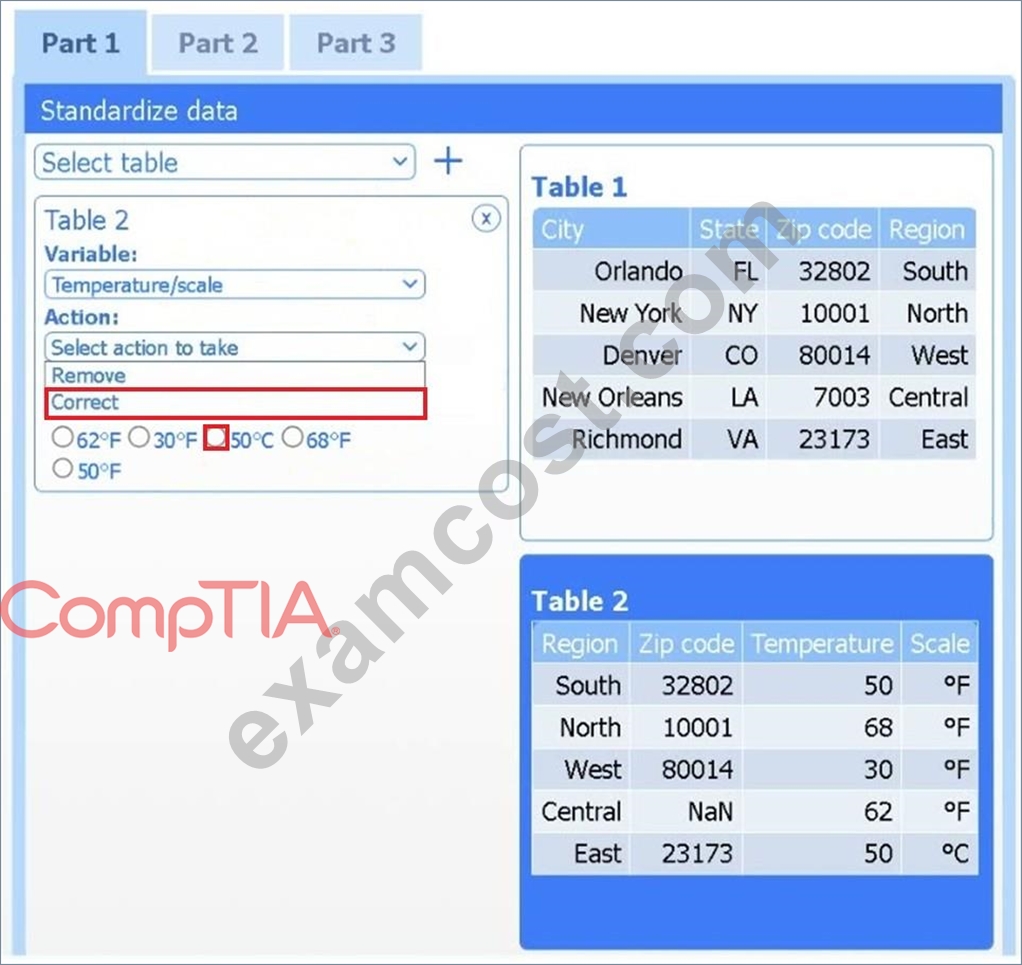
Part 2
Method: Data matching
Join variable: Zip code
You need to merge the two tables by aligning matching records, which is a data-matching (join) operation, and ZIP code is the shared, uniquely identifying field linking each region's weather reading to its city.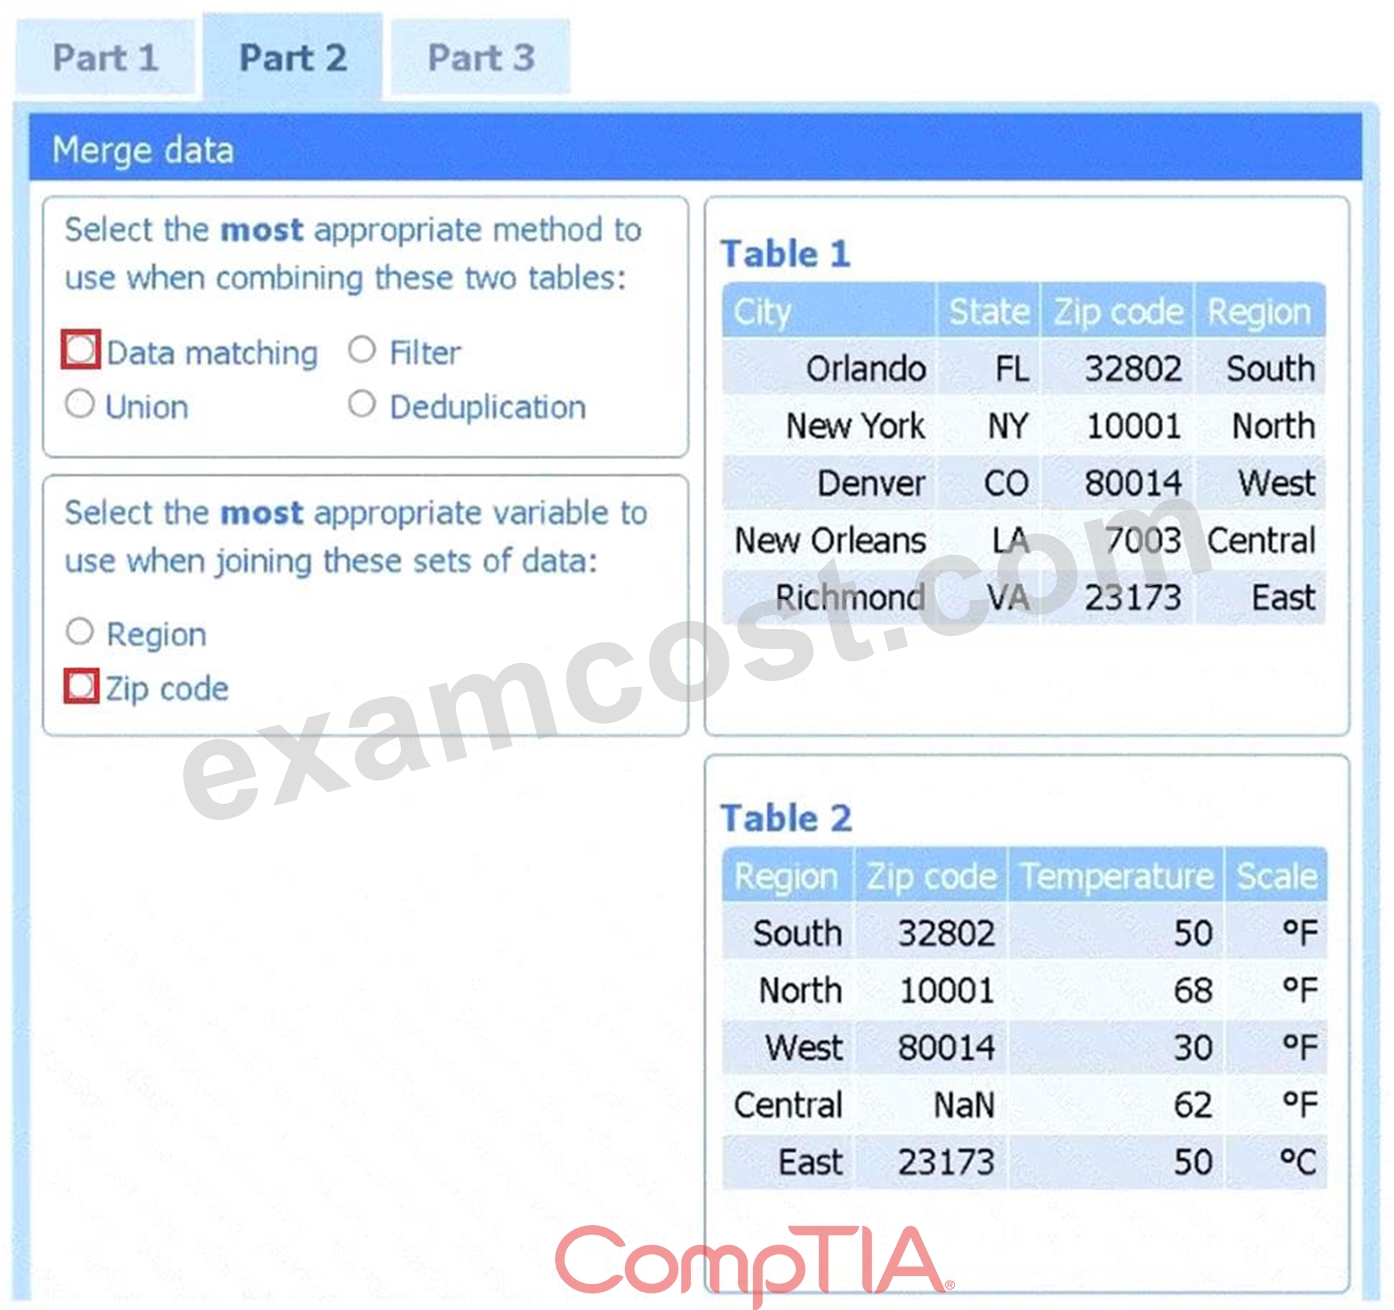
Part 3
Choose the choropleth map (the first option).
A choropleth map best shows geographic variation in temperature by coloring each state (or region) according to its recorded value. This lets the client immediately see where the highest and lowest temperatures occur across the U.S. without distracting elements like bubble size or combined chart axes.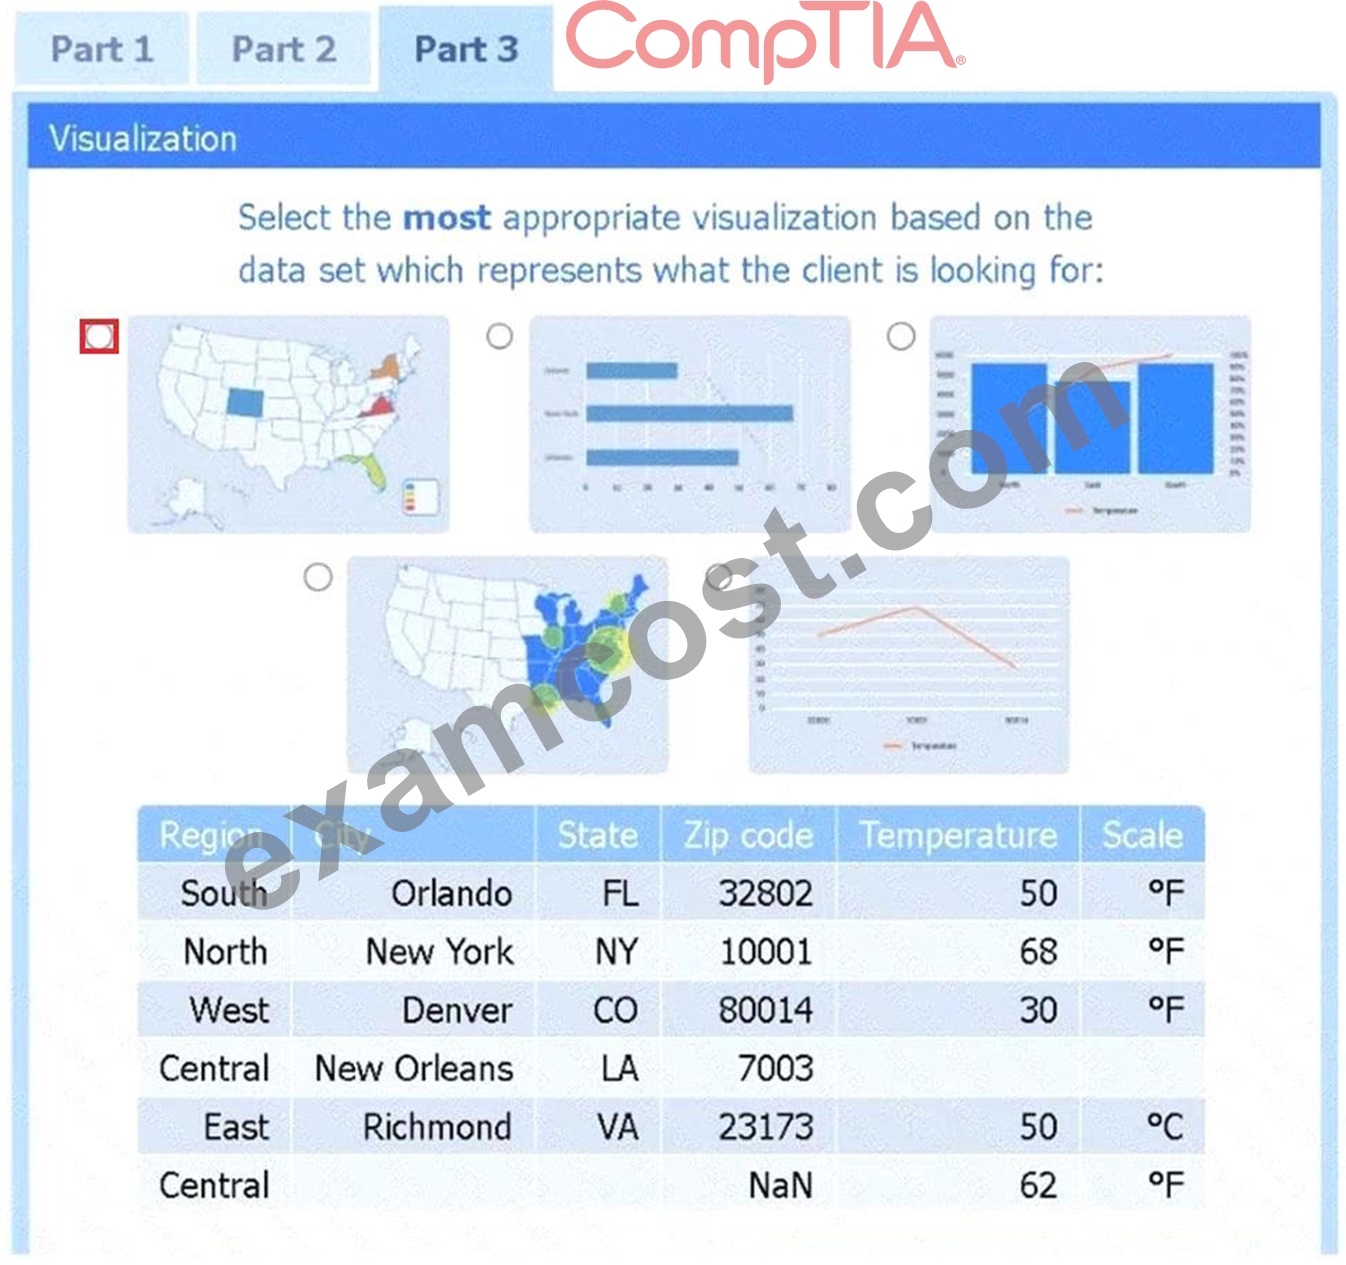
NEW QUESTION # 64
Which of the following distributions would be best to use for hypothesis testing on a data set with 20 observations?
Answer: B
Explanation:
With only 20 observations and an unknown population variance, the t-distribution (with 𝑛 - 1 degrees of freedom) properly accounts for the extra uncertainty in the standard error when performing hypothesis tests.
NEW QUESTION # 65
A data scientist has constructed a model that meets the minimum performance requirements specified in the proposal for a prediction project. The data scientist thinks the model's accuracy should be improved, but the proposed deadline is approaching. Which of the following actions should the data scientist take first?
Answer: B
Explanation:
Since the model already meets the agreed-upon requirements and the deadline is near, the first step is to confirm with the stakeholder whether pursuing further accuracy gains is worth the additional time and resources. This ensures you align with business priorities before collecting more data, requesting funding, or tweaking the model further.
NEW QUESTION # 66
A data scientist wants to digitize historical hard copies of documents. Which of the following is the best method for this task?
Answer: B
Explanation:
# Optical Character Recognition (OCR) is the process of converting scanned images or hard copy text into machine-encoded text. It is the standard technique for digitizing printed or handwritten content.
Why the other options are incorrect:
* A: Word2vec is for generating word embeddings from digital text.
* C: Latent Semantic Analysis analyzes semantic structure of existing digital documents.
* D: Semantic segmentation is used in image processing for pixel-wise classification - not text extraction.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 6.3:"OCR converts scanned physical documents into text files that can be searched, analyzed, or stored digitally."
* Practical NLP Applications, Chapter 2:"OCR is a prerequisite for turning printed or written material into structured data suitable for text analytics."
-
NEW QUESTION # 67
......
Exam DY0-001 Simulator Online: https://www.examcost.com/DY0-001-practice-exam.html
What's more, part of that ExamCost DY0-001 dumps now are free: https://drive.google.com/open?id=1EYMTV01bZE68Us53g-VUf5v8t623rH65