BONUS!!! Download part of itPass4sure DP-800 dumps for free: https://drive.google.com/open?id=1s3XRYCyVXFs0raycqm9JbqOKAF3SkCqT
Do you feel that you are always nervous in your actual DP-800 exam and difficult to adapt yourself to the real exam? If you answer is yes, I think you can try to use the software version of our DP-800 exam quiz. I believe the software version of our DP-800 trianing guide will be best choice for you, because the software version can simulate real test environment, you can feel the atmosphere of the DP-800 exam in advance by the software version.
| Section | Weight | Objectives |
|---|---|---|
| Secure, optimize, and deploy database solutions | 35-40% | - Optimize performance and reliability
|
| Implement AI capabilities in database solutions | 25-30% | - Use AI-assisted development tools
|
| Design and develop database solutions | 35-40% | - Develop database solutions
|
>> Latest DP-800 Test Format <<
Our website is a pioneer in providing comprehensive Microsoft dumps torrent because we have a group of dedicated IT experts who have more than 10 years of experience in the study of DP-800 test questions and answers. They work in advance to make sure that our candidates will get latest and accurate DP-800 Exam Prep materials. You will get DP-800 passing score with the shortest duration for exam preparation.
NEW QUESTION # 74
You have an Azure SQL database That contains a table named dbo.Products, dbo.Products contains three columns named Embedding Category, and Price. The Embedding column is defined as VECTOR(1536).
You use Ai_GENERME_EMBEDOINGS and VECTOR_SEARCH to support semantic search and apply additional filters on two columns named Category and Price.
You plan to change the embedding model from text-embedding-ada-002 to text-embedding-3-smalL Existing rows already contain embeddings in the Embedding column.
You need to implement the model change. Applications must be able to use VECTOR_SEARCH without runtime errors.
What should you do first?
Answer: D
Explanation:
When you change embedding models, the stored vectors should be treated as belonging to a different embedding space unless you intentionally keep the entire corpus consistent. Microsoft's vector guidance notes that when most or all embeddings are replaced with fresh embeddings from a new model, the recommended practice is to reload the new embeddings and, for large-scale replacement scenarios, consider dropping and recreating the vector index afterward so search quality remains predictable.
This question also says applications must continue to use VECTOR_SEARCH without runtime errors .
VECTOR_SEARCH requires compatible vector dimensions, and the vector column already exists. Azure OpenAI documentation shows that text-embedding-ada-002 is fixed at 1536 dimensions and text- embedding-3-small supports up to 1536 dimensions . That means the migration can remain compatible with a VECTOR(1536) column, but the right implementation step is still to re-embed the existing rows so the table does not contain a mixed corpus produced by different models.
The other options are not appropriate:
* B normalization does not solve a model migration problem.
* C converting the vector column to nvarchar(max) would break vector-native search design.
* D a vector index improves performance, but it does not migrate old embeddings to the new model.
NEW QUESTION # 75
You have an Azure SQL database that supports an OLTP application.
You need to write Transact-SQL code that returns blocking chain details. The output must return only sessions that ate blocked or are blocking other sessions.
How should you complete the code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.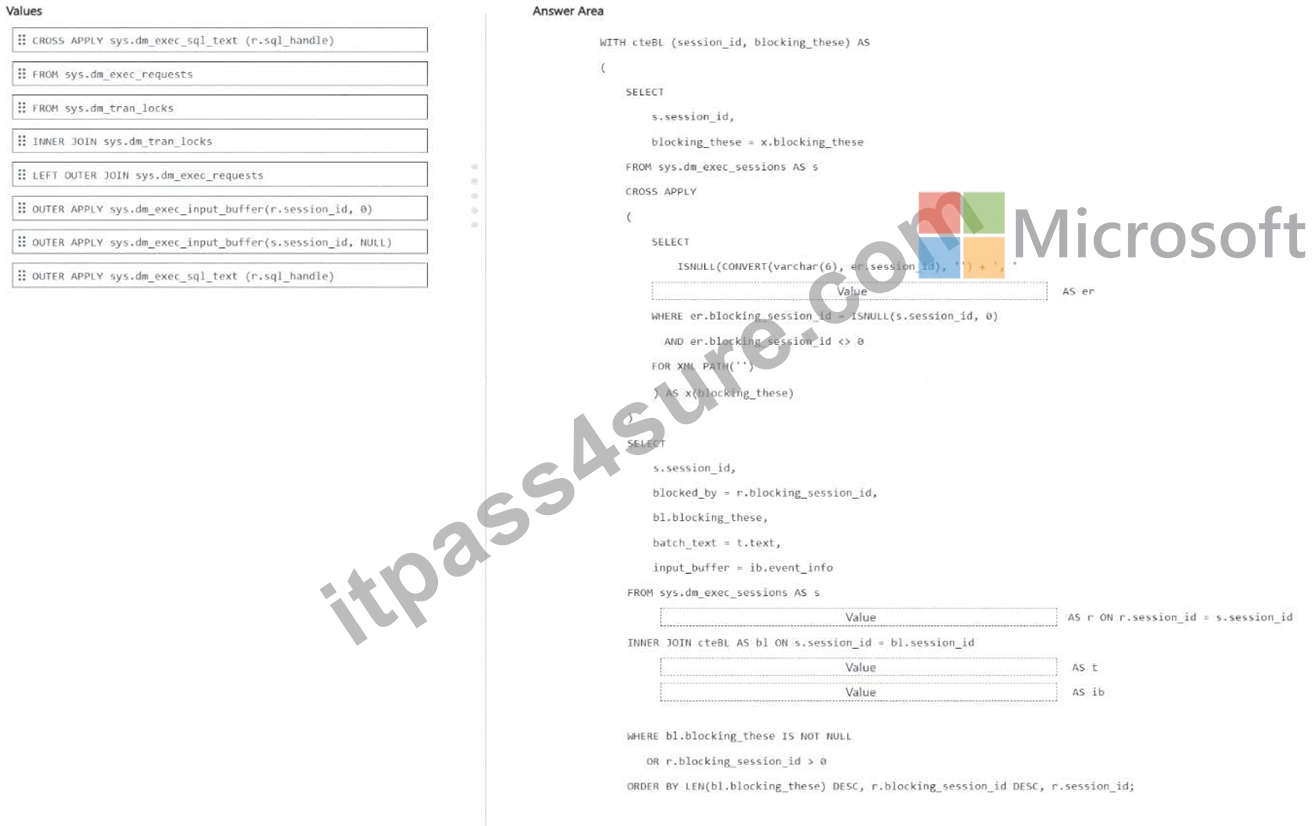
Answer:
Explanation: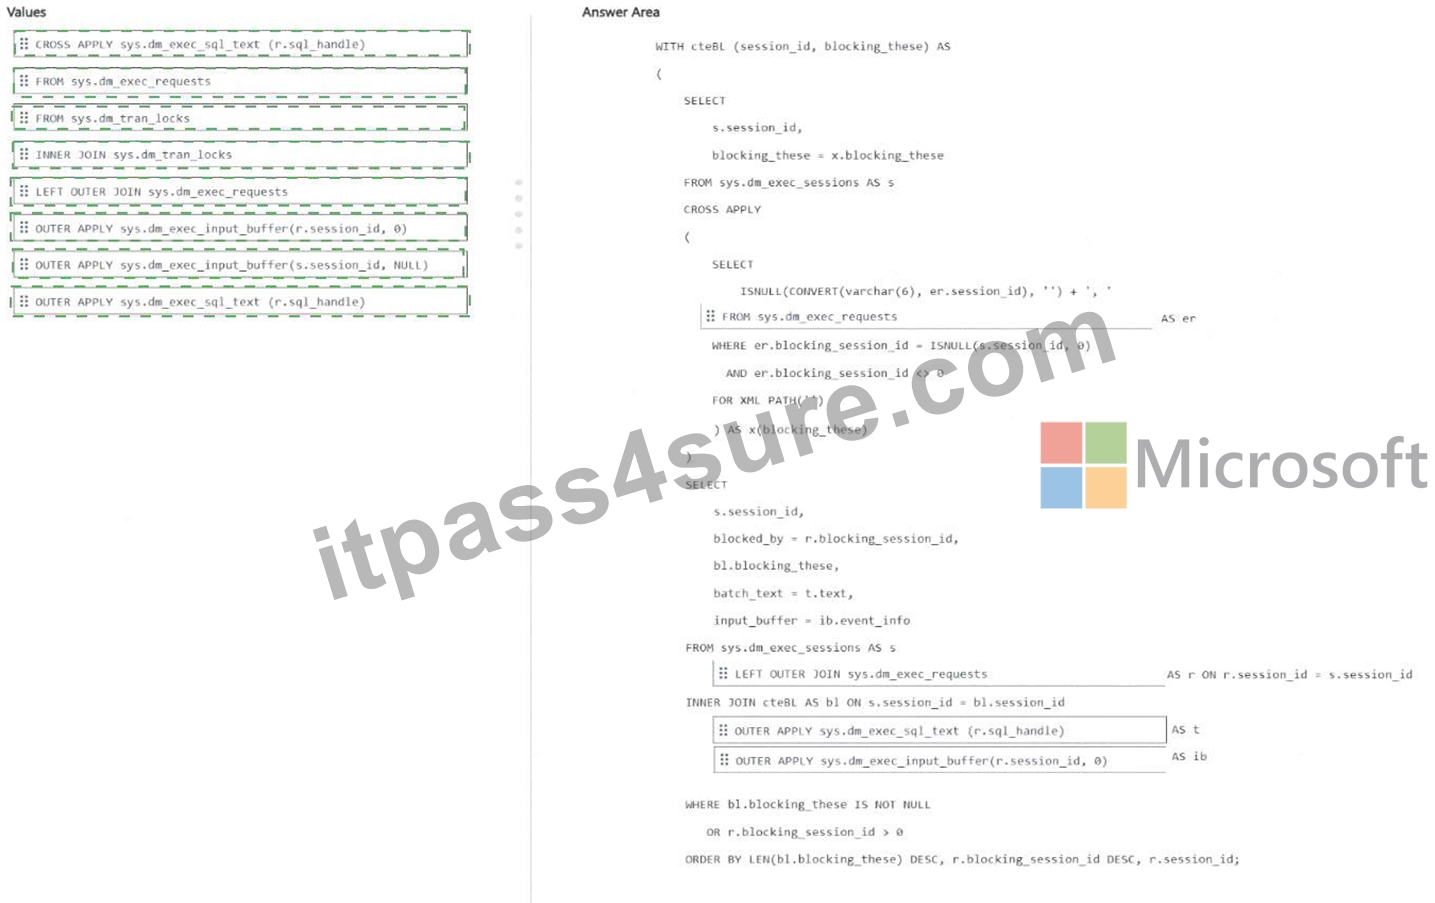
Explanation:
* CTE inner source # FROM sys.dm_exec_requests
* Join after sys.dm_exec_sessions AS s # LEFT OUTER JOIN sys.dm_exec_requests
* Text retrieval # OUTER APPLY sys.dm_exec_sql_text(r.sql_handle)
* Input buffer retrieval # OUTER APPLY sys.dm_exec_input_buffer(r.session_id, r.request_id) The correct drag-and-drop choices are based on how blocking-chain details are normally assembled in Azure SQL Database.
The CTE must read from sys.dm_exec_requests because the alias er is used with er.session_id and er.
blocking_session_id, and those columns come from sys.dm_exec_requests. Microsoft documents that sys.
dm_exec_requests returns information about executing requests and includes the blocking_session_id column used to identify blockers.
After FROM sys.dm_exec_sessions AS s, the correct join is LEFT OUTER JOIN sys.dm_exec_requests so the query can still return sessions from sys.dm_exec_sessions even when a current request row is missing.
This is useful when showing sessions that are blocked or blocking, while still attempting to attach current request details when available.
For batch text, use OUTER APPLY sys.dm_exec_sql_text(r.sql_handle) because Microsoft documents sys.
dm_exec_sql_text(sql_handle) as the function that returns the SQL batch text for the specified sql_handle.
For the input buffer, use OUTER APPLY sys.dm_exec_input_buffer(r.session_id, r.request_id) because Microsoft documents that sys.dm_exec_input_buffer takes session_id and request_id and returns event_info, which is commonly used when sys.dm_exec_sql_text is null or when you want the last command text.
So the completed code uses:
* FROM sys.dm_exec_requests
* LEFT OUTER JOIN sys.dm_exec_requests
* OUTER APPLY sys.dm_exec_sql_text(r.sql_handle)
* OUTER APPLY sys.dm_exec_input_buffer(r.session_id, r.request_id)
NEW QUESTION # 76
Case Study 2 - Fabrikam
Existing Environment
Azure Environment
Fabrikam has a single Azure subscription in the East US 2 Azure region. The subscription contains an Azure SQL database named DB1. DB1 contains the following tables:
* Patients
* Employees
* Procedures
* Transactions
* UsefulPrompts
* ProcedureDocuments
You store a column master key as a secret in Azure Key Vault.
You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Problem Statements
Users report that after executing a long-running stored procedure named sp_UpdateProcedureForPatient, updates to the underlying data are sometimes inconsistent.
Requirements
Planned Changes
Fabrikam plans to manage all changes to Azure SQL Database objects by using source control in GitHub. Every pull request submitted to production will be validated before it can be merged.
Deployments must use the Release configuration.
Security Requirements
Fabrikam identifies the following security requirements:
* The TransactionProcessing application must use a passwordless connection to DB1.
* The Employees table contains two columns named TaxID and Salary that must be encrypted at rest.
* Auditors must have a tamper-evident history of transactions with cryptographic proof of changes to the employee data.
Database Performance Requirements
Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
AI Search, Embeddings, and Vector Indexing
Fabrikam identifies the following AI-related requirements:
* Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
* Users must be able to query the data in DB1 by using prompts in Copilot in Microsoft Fabric.
* The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
Development Requirements
Fabrikam identifies the following development requirements:
* Provide the functionality to retrieve all the transactions of a given patient between two dates, showing a running total.
* Expose a Data API builder (DAB) configuration file to enable Azure services to perform the following operations over a REST API:
- Read data from the procedures table without authentication.
- Read and insert data into the Transactions table once authenticated.
- Execute the sp_UpdateProcedurePatient stored procedure.
* Provide the functionality to retrieve a list of the names of patients who underwent medical procedures during the last 30 days.
* Information for each medical procedure will be stored in a table. The table will be used with a large language model (LLM) for user querying and will have the following structure.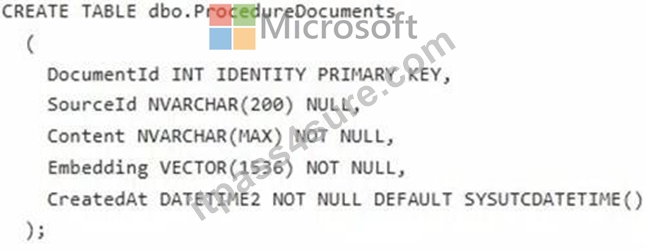
DAB
You create a DAB configuration file that meets the development requirements for DB1 and includes the following entities.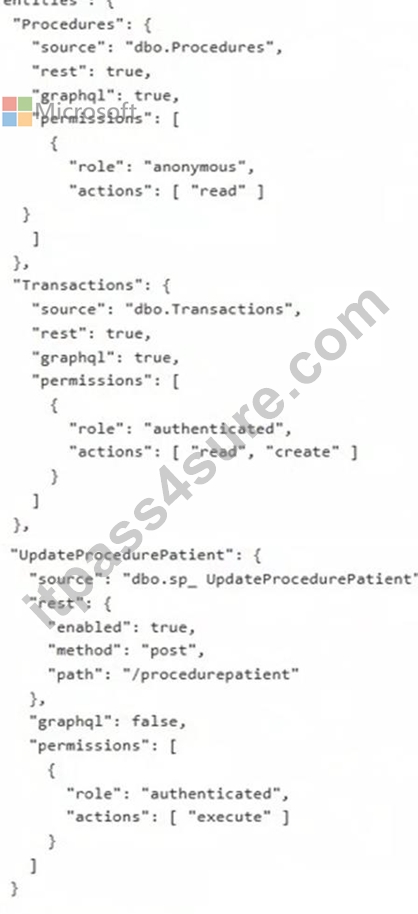
Hotspot Question
You need to create a solution that meets the development requirements for retrieving the patient transaction data. The solution must ensure that database developers use the resulting data to join to other tables.
How should you complete the Transact-SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.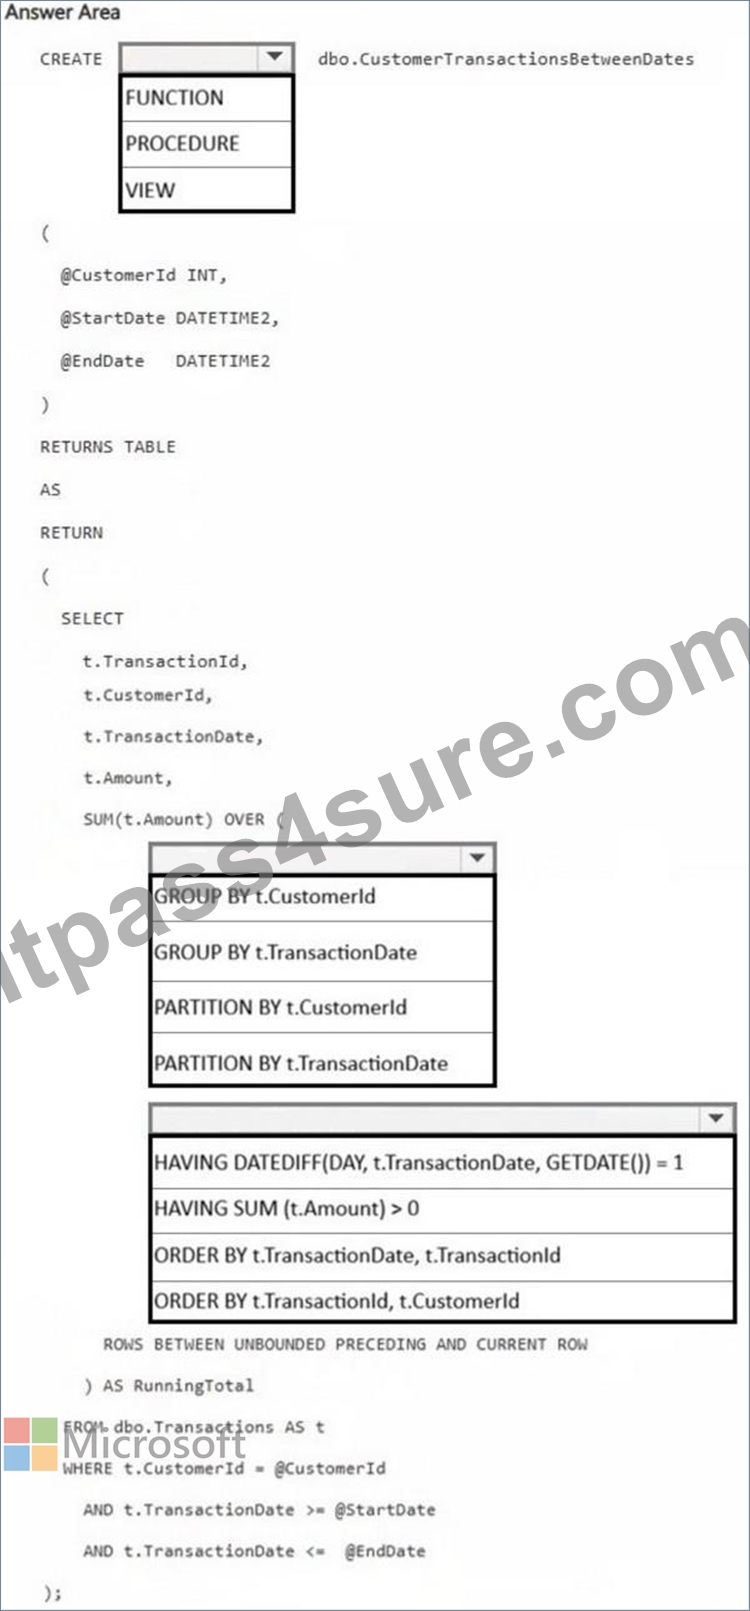
Answer:
Explanation: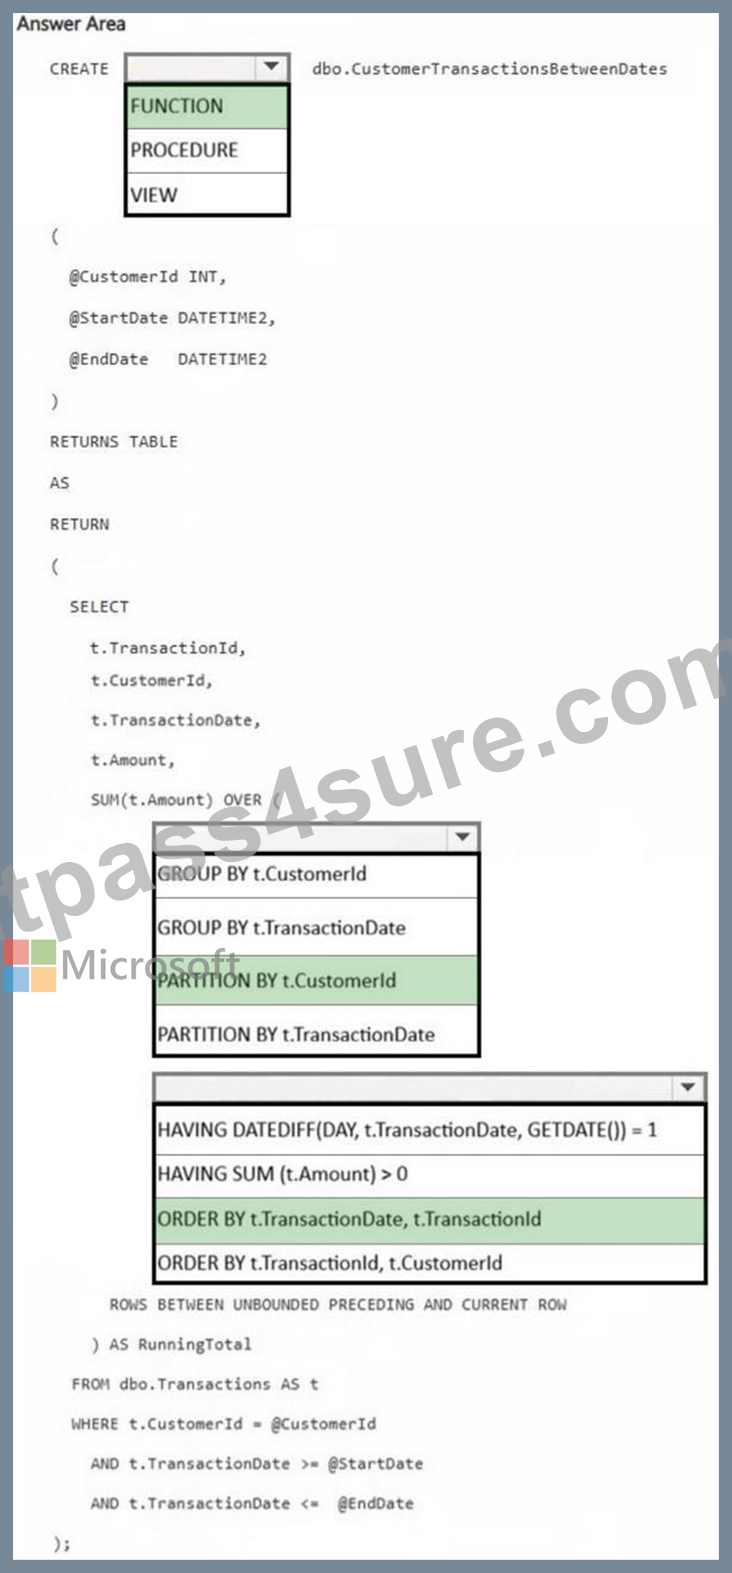
NEW QUESTION # 77
You need to design a generative Al solution that uses a Microsoft SOL Server 2025 database named DB1 as a data source. The solution must generate responses that meet the following requirements:
* Ait ' grounded In the latest transactional and reference data stored in D61
* Do NOT require retraining or fine-tuning the language model when the data changes
* Can include citations or references to the source data used in the response Which scenario is the best use case for implementing a Retrieval Augmented Generation (RAG) pattern?
More than one answer choice may achieve the goal. Select the BEST answer
Answer: D
Explanation:
The best use case for RAG is answering user questions based on company-specific knowledge . Microsoft defines RAG as a pattern that augments a language model with a retrieval system that provides grounding data at inference time, which is exactly what you need when responses must be based on the latest transactional and reference data , must avoid retraining/fine-tuning , and should be able to include citations or references to source data.
The other options do not fit as well:
* summarizing free-form user input does not inherently require retrieval from DB1,
* training a custom model contradicts the requirement to avoid retraining/fine-tuning,
* generating marketing slogans is a creative generation task, not a grounding-and-citation scenario. RAG is specifically strong when answers must come from your organization's own changing knowledge.
NEW QUESTION # 78
You have a database named DB1. The schema is stored in a GitHub repository as an SDK style SQL database project.
You use a feature branch workflow to deploy changes to DB1
You need to update the local feature branch with the latest changes to main, and then create a pull request to merge the feature branch into main for review.
How should you complete the GitHub CLI script? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.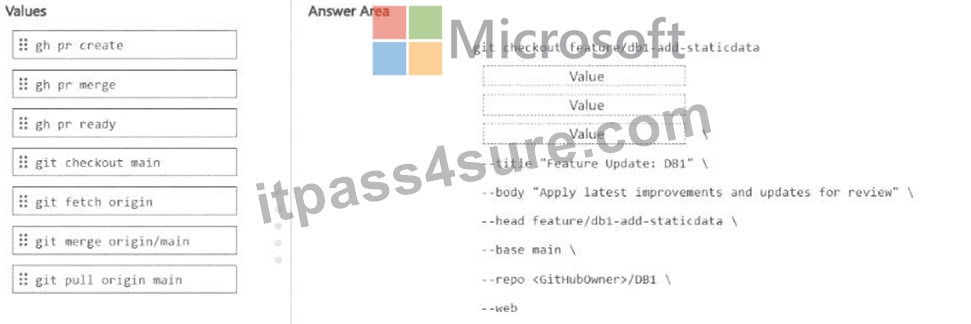
Answer:
Explanation: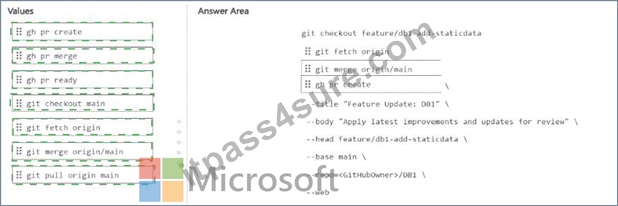
Explanation: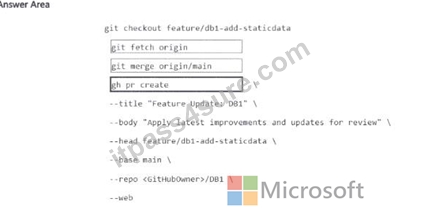
The correct sequence is:
* git fetch origin
* git merge origin/main
* gh pr create
This is the right workflow because the script starts on the local feature branch:
git checkout feature/db1-add-staticdata
To update that local feature branch with the latest changes from main, you first fetch the latest remote refs with git fetch origin , then merge the updated remote main branch into the current feature branch with git merge origin/main . After the feature branch is up to date, the correct GitHub CLI command to open the pull request is gh pr create . GitHub's CLI documentation shows that gh pr create is the command used to create a pull request, and supports flags such as --title, --body, --head, --base, --repo, and --web, which match the script shown in the question.
The other commands are not the best fit here:
* git checkout main would move you off the feature branch, which is not what you want before merging main into the feature branch.
* git pull origin main could update from remote main, but the script pattern here clearly separates fetching and then merging.
* gh pr merge merges an existing pull request, not create one.
* gh pr ready marks a draft PR as ready for review, but does not create the PR.
NEW QUESTION # 79
......
The Channel Partner Program Developing AI-Enabled Database Solutions DP-800 certification is a valuable credential earned by individuals to validate their skills and competence to perform certain job tasks. Your Developing AI-Enabled Database Solutions DP-800 Certification is usually displayed as proof that you’ve been trained, educated, and prepared to meet the specific requirement for your professional role.
Reliable DP-800 Exam Sims: https://www.itpass4sure.com/DP-800-practice-exam.html
What's more, part of that itPass4sure DP-800 dumps now are free: https://drive.google.com/open?id=1s3XRYCyVXFs0raycqm9JbqOKAF3SkCqT