2026 Latest TestkingPass SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1ucKONNu5RJWerafr42bojFRyq-VnfFV7
They check each Snowflake SPS-C01 practice test question and ensure the top standard of Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam questions all the time. So you can trust TestkingPass Snowflake SPS-C01 practice test questions and start Snowflake SPS-C01 exam preparation with confidence. The TestkingPass is a leading platform committed to making entire Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam preparation simple, quick, and easy for everyone. To fulfill this objective the TestkingPass are offering top-rated and real Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) practice test questions in three different formats.
| Section | Objectives |
|---|---|
| Topic 1: DataFrame Operations and Data Processing | - Data transformation workflows
|
| Topic 2: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Topic 3: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 4: Data Engineering with Snowpark | - Pipeline development
|
| Topic 5: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 6: Testing, Debugging, and Deployment | - Production readiness
|
Do you want to pass the SPS-C01 exam and get the certificate? If you want to pass the exam easily, come to learn our SPS-C01 study materials. Our SPS-C01 learning guide is very excellent, which are compiled by professional experts who have been devoting themself to doing research in this career for over ten years. I can say that no one can know more than them. So they know evey detail of the SPS-C01 Exam Questions, and they will adopt the advices of our loyal customers to make better.
NEW QUESTION # 164
A data engineer wants to create a Snowpark session using environment variables defined in a .env' file. The file contains the following: SNOWFLAKE ACCOUNT=myaccount.snowflakecomputing.com SNOWFLAKE USER=snowpark_user SNOWFLAKE SNOWFLAKE DATABASE=mydb SNOWFLAKE SCHEMA=myschema SNOWFLAKE WAREHOUSE=mywarehouse Which code snippet correctly establishes a Snowpark session using these environment variables?





Answer: D
Explanation:
Option E is the most concise and recommended way to create a Snowpark session using environment variables defined in a .env file, by using method. Option B works but requires manual loading of environment variables. Options A and C do not correctly access environment variables. Option D would require the environment variables to be named exactly as the session builder expects and doesn't use the dotenv library which is designed for this purpose.
NEW QUESTION # 165
You are working with a Snowpark application designed to process data from an event table. While testing a complex transformation involving several joins and window functions, you encounter the following error: 'java.lang.OutOfMemoryError: Java heap space'. The application uses Snowpark DataFrames and is running on a reasonably sized virtual warehouse. What is the MOST likely cause of this error in the context of Snowpark and Snowflake?
Answer: B
Explanation:
OutOfMemoryError in Snowpark is most often due to the driver process attempting to load a large result set into memory. Snowpark is designed to push down computations to Snowflake, but certain operations can force data to be collected on the driver. The correct response highlight this. While the other options might contribute, they are less likely to be the direct cause of a Java heap space error specifically.
NEW QUESTION # 166
Given a Snowpark DataFrame 'employees_df with columns 'employee_id' , 'department' , and 'salary' , and a second Snowpark DataFrame 'departments_df with columns 'department_id' and which of the following Snowpark code snippets correctly performs a join to retrieve employee information along with their department name, filtering for employees with salaries greater than $60,000, and then orders the result by department name?



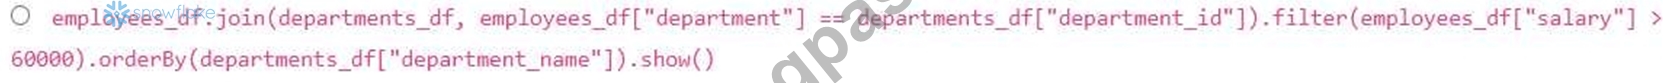

Answer: A
Explanation:
Explanation:Option E first filters the 'employees_df for salaries greater than $60,000, then joins with 'departments_df using the appropriate join condition (employee.department = department.department_id), and finally orders the result by department name. Using instead of and instead of also acceptable syntax. It's more efficient to filter before joining, so E is better than D, and more importantly E and D work correctly. The other options will throw an error.
NEW QUESTION # 167
A UDTF (User-Defined Table Function) named 'split_sentences" takes a text string as input and returns a table with each row containing a single sentence from the input. You need to grant SELECT privilege on this UDTF to a specific role, 'DATA ANALYST'. Which of the following SQL statements will achieve this?
Answer: C
Explanation:
Since UDTFs return a table, you need to grant the 'SELECT privilege on the table function to allow the role to query the results produced by the UDTF. The syntax is 'GRANT SELECT ON TABLE FUNCTION'. option A is wrong it's for UDE Options C and E provide too many privileges, potentially allowing unintended modifications. Option D is not the correct Privilege.
NEW QUESTION # 168
You have a Snowpark DataFrame 'customer data df containing customer information, including 'customer id', 'email', and phone number'. You need to anonymize the 'email' and 'phone number" columns for customers residing in specific countries (e.g., 'USA', 'Canada') before persisting the changes back to the 'customers' table. Anonymization should replace sensitive data with 'XXXXX'. You want to leverage UDF for obfuscation. What is correct and optimal approach considering performance and security?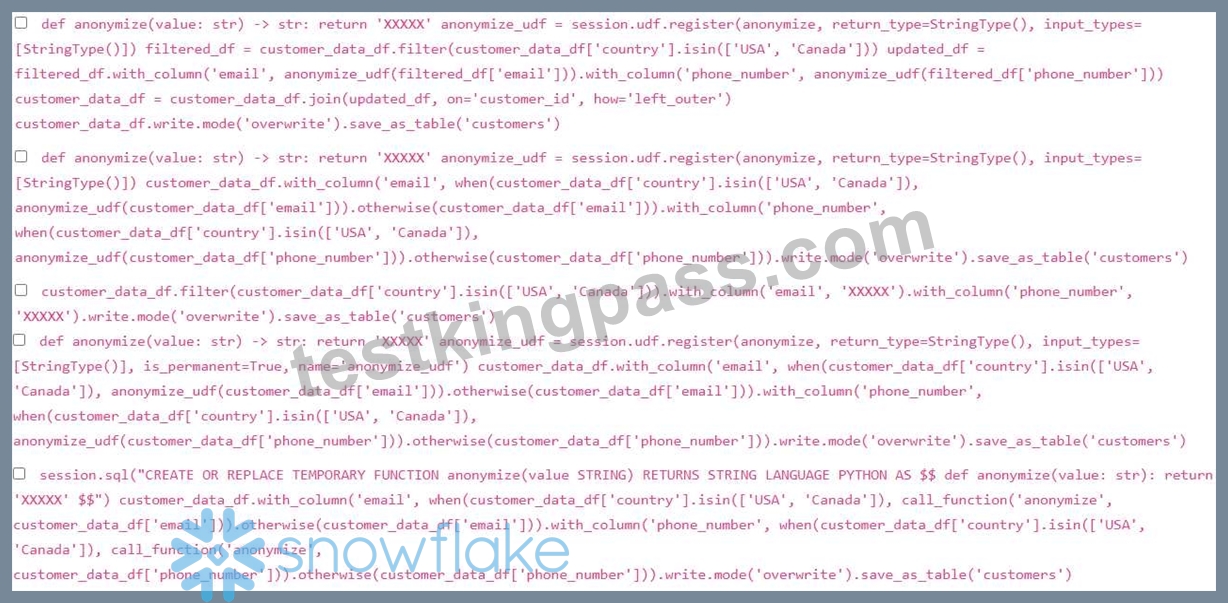
Answer: B,C
Explanation:
Options B and E provide the most efficient and secure solutions. Option B correctly utilizes the 'when' function along with a registered UDF ('anonymize_udf) to conditionally anonymize the 'email' and 'phone_number' columns only for customers in 'USA' or 'Canada'. This ensures that only the necessary data is modified. Option E creates and uses a temporary UDF with SQL, achieving the same result in a different (yet valid) way. Option A is less efficient because it filters the DataFrame, updates it, and then joins it back with the original, which can be computationally expensive. Additionally, join can produce cartesian results if not done properly. Option C, while straightforward, hardcodes the anonymized value directly, which might not be the best practice in all scenarios and doesn't use a UDF. Option D, although similar to B, attempts to create a permanent UDF without specifying the stage location, which may lead to errors and is not best practice unless you manage it. Also creating a UDF in Python using SQL can be faster and safer.
NEW QUESTION # 169
......
The three versions of our SPS-C01 training materials each have its own advantage. On the one hand, the software version can simulate the real SPS-C01 examination for all of the users in windows operation system. By actually simulating the real test environment. On the other hand, if you choose to use the software version, you can download our SPS-C01 Exam Prep only for Windows system. We strongly believe that the software version of our SPS-C01 study materials will be of great importance for you to prepare for the exam and all of the employees in our company wish you early success.
SPS-C01 Online Lab Simulation: https://www.testkingpass.com/SPS-C01-testking-dumps.html
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by TestkingPass: https://drive.google.com/open?id=1ucKONNu5RJWerafr42bojFRyq-VnfFV7