MLA-C01日本語版と英語版、MLA-C01予想試験

BONUS!!! GoShiken MLA-C01ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=16pz3jgN1bHHFmHW0CcVxk9QeCsXniJPr
MLA-C01「AWS Certified Machine Learning Engineer - Associate」試験は簡単ではありません。専門的な知識が必要で、もしあなたはまだこの方面の知識を欠かれば、GoShikenは君に向ける知識を提供いたします。GoShikenの専門家チームは彼らの知識や経験を利用してあなたの知識を広めることを助けています。そしてあなたにMLA-C01試験に関するテスト問題と解答が分析して差し上げるうちにあなたのIT専門知識を固めています。
Amazon MLA-C01 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - ML Solution Monitoring, Maintenance, and Security: This section of the exam measures skills of Fraud Examiners and assesses the ability to monitor machine learning models, manage infrastructure costs, and apply security best practices. It includes setting up model performance tracking, detecting drift, and using AWS tools for logging and alerts. Candidates are also tested on configuring access controls, auditing environments, and maintaining compliance in sensitive data environments like financial fraud detection.
|
| トピック 2 | - Deployment and Orchestration of ML Workflows: This section of the exam measures skills of Forensic Data Analysts and focuses on deploying machine learning models into production environments. It covers choosing the right infrastructure, managing containers, automating scaling, and orchestrating workflows through CI
- CD pipelines. Candidates must be able to build and script environments that support consistent deployment and efficient retraining cycles in real-world fraud detection systems.
|
| トピック 3 | - Data Preparation for Machine Learning (ML): This section of the exam measures skills of Forensic Data Analysts and covers collecting, storing, and preparing data for machine learning. It focuses on understanding different data formats, ingestion methods, and AWS tools used to process and transform data. Candidates are expected to clean and engineer features, ensure data integrity, and address biases or compliance issues, which are crucial for preparing high-quality datasets in fraud analysis contexts.
|
| トピック 4 | - ML Model Development: This section of the exam measures skills of Fraud Examiners and covers choosing and training machine learning models to solve business problems such as fraud detection. It includes selecting algorithms, using built-in or custom models, tuning parameters, and evaluating performance with standard metrics. The domain emphasizes refining models to avoid overfitting and maintaining version control to support ongoing investigations and audit trails.
|
>> MLA-C01日本語版と英語版 <<
試験の準備方法-一番優秀なMLA-C01日本語版と英語版試験-更新するMLA-C01予想試験
弊社のAmazon MLA-C01問題集を使用した後、MLA-C01試験に合格するのはあまりに難しくないことだと知られます。我々GoShiken提供するMLA-C01問題集を通して、試験に迅速的にパースする技をファンドできます。あなたのご遠慮なく購買するために、弊社は提供する無料のAmazon MLA-C01問題集デーモをダウンロードします。
Amazon AWS Certified Machine Learning Engineer - Associate 認定 MLA-C01 試験問題 (Q125-Q130):
質問 # 125
An ML engineer is using an Amazon SageMaker AI shadow test to evaluate a new model that is hosted on a SageMaker AI endpoint. The shadow test requires significant GPU resources for high performance. The production variant currently runs on a less powerful instance type.
The ML engineer needs to configure the shadow test to use a higher performance instance type for a shadow variant. The solution must not affect the instance type of the production variant.
Which solution will meet these requirements?
- A. Create a separate SageMaker AI endpoint for the shadow variant that uses the larger instance type.
Create an AWS Lambda function that routes a portion of the traffic to the shadow endpoint. Assign the Lambda function to the original endpoint. - B. Use the CreateEndpointConfig action to define a new configuration. Specify the existing production variant in the configuration and add a separate ShadowProductionVariants list. Specify the larger instance type for the shadow variant. Use the CreateEndpoint action and pass the new configuration to the endpoint.
- C. Modify the existing ProductionVariant configuration in the endpoint to include a ShadowProductionVariants list. Specify the larger instance type for the shadow variant.
- D. Create a new endpoint configuration with two ProductionVariant definitions. Configure one definition for the existing production variant and one definition for the shadow variant with the larger instance type. Use the UpdateEndpoint action to apply the new configuration.
正解:B
解説:
Amazon SageMaker AI shadow testing enables ML engineers to evaluate new model versions by sending a copy of live production traffic to a shadow variant without affecting production inference responses. AWS documentation specifies that shadow variants are configured separately from production variants and can use different instance types, including higher-performance GPU instances.
The correct approach is to create a new endpoint configuration using the CreateEndpointConfig API. This configuration includes the existing production variant and a separate ShadowProductionVariants list. The shadow variant can be assigned a larger instance type to meet GPU performance requirements while leaving the production variant unchanged. After creating the configuration, the engineer deploys it using the CreateEndpoint action.
Option A is incorrect because production variant configurations cannot be directly modified to include shadow variants. Option B is incorrect because shadow variants are not defined as standard production variants; defining two production variants would route traffic differently and could affect production behavior. Option C introduces unnecessary complexity and deviates from SageMaker's built-in shadow testing functionality.
AWS explicitly documents that shadow variants are designed to isolate testing resources, support different instance types, and ensure zero impact on production inference. Therefore, Option D is the correct and AWS- recommended solution.
質問 # 126
An ML engineer is preparing a dataset that contains medical records to train an ML model to predict the likelihood of patients developing diseases.
The dataset contains columns for patient ID, age, medical conditions, test results, and a "Disease" target column.
How should the ML engineer configure the data to train the model?
- A. Remove the "Disease" target column.
- B. Remove the patient ID column.
- C. Remove the medical conditions and test results columns.
- D. Remove the age column.
正解:B
解説:
Patient ID is a unique identifier and does not contain predictive information. Including it can cause the model to overfit by memorizing records rather than learning meaningful patterns.
AWS ML best practices recommend removing identifiers that are not causally related to the target variable.
Age, medical conditions, and test results are clinically relevant features and should be retained. The target column must remain for supervised learning.
Therefore, Option A is the correct and AWS-aligned choice.
質問 # 127
A company runs an ML model on Amazon SageMaker. The company uses an automatic process that makes API calls to create training jobs for the model. The company has new compliance rules that prohibit the collection of aggregated metadata from training jobs. Which solution will prevent SageMaker from collecting metadata from the training jobs?
- A. Reconfigure the training jobs to use only AWS Nitro instances.
- B. Encrypt the training data with an AWS Key Management Service (AWS KMS) customer managed key.
- C. Ensure that training jobs are running in a private subnet in a custom VPC.
- D. Opt out of metadata tracking for any training job that is submitted.
正解:D
解説:
Amazon SageMaker automatically collects training job metadata, but you can opt out of metadata tracking when submitting a training job. This disables collection of aggregated metadata, ensuring compliance with rules that prohibit metadata collection.
質問 # 128
A company runs Amazon SageMaker ML models that use accelerated instances. The models require real-time responses. Each model has different scaling requirements. The company must not allow a cold start for the models.
Which solution will meet these requirements?
- A. Create a SageMaker Serverless Inference endpoint for each model. Use provisioned concurrency for the endpoints.
- B. Create a SageMaker endpoint. Create an inference component for each model. In the inference component settings, specify the newly created endpoint. Create an auto scaling policy for each inference component. Set the parameter for the minimum number of copies to at least 1.
- C. Create a SageMaker Asynchronous Inference endpoint for each model. Create an auto scaling policy for each endpoint.
- D. Create an Amazon S3 bucket. Store all the model artifacts in the S3 bucket. Create a SageMaker multi-model endpoint. Point the endpoint to the S3 bucket. Create an auto scaling policy for the endpoint. Set the parameter for the minimum number of copies to at least 1.
正解:B
質問 # 129
A data scientist is evaluating different binary classification models. A false positive result is 5 times more expensive (from a business perspective) than a false negative result.
The models should be evaluated based on the following criteria:
1) Must have a recall rate of at least 80%
2) Must have a false positive rate of 10% or less
3) Must minimize business costs
After creating each binary classification model, the data scientist generates the corresponding confusion matrix.
Which confusion matrix represents the model that satisfies the requirements?
- A. TN = 99, FP = 1
FN = 21, TP = 79 - B. TN = 98, FP = 2
FN = 18, TP = 82 - C. TN = 96, FP = 4
FN = 10, TP = 90 - D. TN = 91, FP = 9
FN = 22, TP = 78
正解:B
解説:
The following calculations are required:
TP = True Positive
FP = False Positive
FN = False Negative
TN = True Negative
FN = False Negative
Recall = TP / (TP + FN)
False Positive Rate (FPR) = FP / (FP + TN)
Cost = 5 * FP + FN
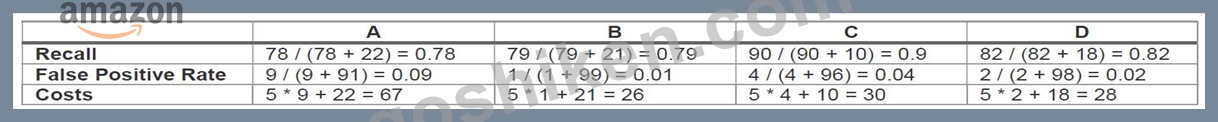
質問 # 130
......
MLA-C01ガイドトレントの3つの異なるバージョンの中で最も普及しているのはPDFバージョンであり、Amazonは特に適切であり、若者に歓迎されていることは間違いありません。このバージョンにはいくつかの機能があります。まず、MLA-C01準備ガイドのPDFバージョンを紙に印刷できます。ただし、メモを作成して重要な試験ポイントを強調することができます。前述のように、MLA-C01試験トレントサポート無料のデモダウンロードに加えて、MLA-C01準備ガイドを十分に理解し、適切で満足できる場合は購入することが理想的です。
MLA-C01予想試験: https://www.goshiken.com/Amazon/MLA-C01-mondaishu.html
- MLA-C01問題無料 🧓 MLA-C01最新な問題集 😆 MLA-C01日本語練習問題 🔑 時間限定無料で使える⏩ MLA-C01 ⏪の試験問題は{ www.passtest.jp }サイトで検索MLA-C01日本語関連対策
- MLA-C01関連日本語版問題集 🅾 MLA-C01教育資料 🐯 MLA-C01最新知識 🥬 サイト➤ www.goshiken.com ⮘で➽ MLA-C01 🢪問題集をダウンロードMLA-C01無料試験
- MLA-C01関連受験参考書 ↖ MLA-C01的中合格問題集 👇 MLA-C01最新知識 🐦 ➥ www.goshiken.com 🡄の無料ダウンロード( MLA-C01 )ページが開きますMLA-C01日本語版受験参考書
- MLA-C01資格模擬 💅 MLA-C01日本語関連対策 🧒 MLA-C01資格難易度 🥞 ➽ www.goshiken.com 🢪に移動し、✔ MLA-C01 ️✔️を検索して、無料でダウンロード可能な試験資料を探しますMLA-C01日本語版受験参考書
- 高品質なAmazon MLA-C01日本語版と英語版 - 合格スムーズMLA-C01予想試験 | 実用的なMLA-C01試験準備 🌽 ➽ jp.fast2test.com 🢪で使える無料オンライン版➤ MLA-C01 ⮘ の試験問題MLA-C01資格難易度
- MLA-C01無料試験 🆔 MLA-C01最新知識 📩 MLA-C01模擬試験 🟦 ➽ www.goshiken.com 🢪サイトにて✔ MLA-C01 ️✔️問題集を無料で使おうMLA-C01問題無料
- MLA-C01日本語版受験参考書 📱 MLA-C01日本語練習問題 📜 MLA-C01問題無料 💔 最新[ MLA-C01 ]問題集ファイルは⇛ www.shikenpass.com ⇚にて検索MLA-C01勉強資料
- MLA-C01試験の準備方法|便利なMLA-C01日本語版と英語版試験|100%合格率のAWS Certified Machine Learning Engineer - Associate予想試験 🌍 サイト[ www.goshiken.com ]で“ MLA-C01 ”問題集をダウンロードMLA-C01日本語独学書籍
- MLA-C01最新知識 🧟 MLA-C01的中合格問題集 🍯 MLA-C01日本語版受験参考書 🦃 今すぐ( www.japancert.com )を開き、▛ MLA-C01 ▟を検索して無料でダウンロードしてくださいMLA-C01日本語認定
- MLA-C01的中合格問題集 💱 MLA-C01日本語関連対策 🎿 MLA-C01模擬試験 💐 ⏩ www.goshiken.com ⏪に移動し、➡ MLA-C01 ️⬅️を検索して無料でダウンロードしてくださいMLA-C01模擬解説集
- MLA-C01日本語関連対策 💥 MLA-C01資格模擬 ⏏ MLA-C01模擬解説集 📁 ⇛ www.mogiexam.com ⇚で( MLA-C01 )を検索して、無料で簡単にダウンロードできますMLA-C01日本語認定
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
さらに、GoShiken MLA-C01ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=16pz3jgN1bHHFmHW0CcVxk9QeCsXniJPr