P.S. Free 2026 Google Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by PrepPDF: https://drive.google.com/open?id=1esCaaeU477C5TrUzIGRu6zftpu4iOIsO
First and foremost, the pass rate on our Professional-Machine-Learning-Engineer exam dumps among our customers has reached as high as 98% to 100%, which marks the highest pass rate in the field, we are waiting for you to be the next beneficiary. Second, you can get our Professional-Machine-Learning-Engineer practice dumps only in 5 to 10 minutes after payment, which enables you to devote yourself to study as soon as possible. Last but not least, you will get the privilege to enjoy free renewal of our Professional-Machine-Learning-Engineer Preparation materials during the whole year.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Train and deploy models | 20% | - Implement generative AI deployment patterns - Use Vertex AI deployment features and infrastructure - Deploy models for online, batch, and streaming prediction - Configure training jobs and environments |
| Topic 2: Collaborate to manage data and models | 16% | - Manage datasets and features in Vertex AI - Organize and prepare enterprise data
|
| Topic 3: Automate and orchestrate ML pipelines | 18% | - Implement CI/CD for ML systems - Automate retraining and model updates - Use Vertex AI Pipelines, TFX, and other orchestration tools - Design end-to-end ML workflows |
| Topic 4: Monitor and optimize AI solutions | 16% | - Monitor model performance, fairness, and drift - Troubleshoot and maintain production systems - Monitor data quality and pipeline health - Optimize cost, latency, and resource usage |
| Topic 5: Scale prototypes into AI models | 18% | - Select appropriate model architectures and frameworks - Work with foundation models and generative AI techniques - Optimize model performance and generalization - Design and run experiments |
| Topic 6: Architect low-code AI solutions | 12% | - Identify use cases for low-code/no-code AI tools - Apply responsible AI principles to low-code designs - Design solutions using Vertex AI Studio, Model Garden, and Agent Builder |
>> Google Professional-Machine-Learning-Engineer Exam Cram Questions <<
If you are preparing for the Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam dumps our Professional-Machine-Learning-Engineer Questions help you to get high scores in your Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam. Test your knowledge of the Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam dumps with PrepPDF Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) practice questions. The software is designed to help with Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam dumps preparation. Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) practice test software can be used on devices that range from mobile devices to desktop computers.
NEW QUESTION # 297
You have developed an ML model to detect the sentiment of users' posts on your company's social media page to identify outages or bugs. You are using Dataflow to provide real-time predictions on data ingested from Pub/Sub. You plan to have multiple training iterations for your model and keep the latest two versions live after every run. You want to split the traffic between the versions in an 80:20 ratio, with the newest model getting the majority of the traffic. You want to keep the pipeline as simple as possible, with minimal management required. What should you do?
Answer: B
Explanation:
The recommended approach to achieve the desired outcome would be to deploy the ML models to a Vertex AI endpoint and configure the traffic splitting using the traffic-split parameter. The traffic-split parameter enables you to split traffic between multiple versions of a model based on a percentage split. In this case, the newest model should receive the majority of the traffic, which can be achieved by setting the traffic-split parameter to 0=80. The previous version of the model should receive the remaining 20% of the traffic, which can be achieved by setting the PREVIOUS_MODEL_ID parameter to 20.
NEW QUESTION # 298
You are developing an ML model that uses sliced frames from video feed and creates bounding boxes around specific objects. You want to automate the following steps in your training pipeline: ingestion and preprocessing of data in Cloud Storage, followed by training and hyperparameter tuning of the object model using Vertex AI jobs, and finally deploying the model to an endpoint. You want to orchestrate the entire pipeline with minimal cluster management. What approach should you use?
Answer: B
Explanation:
* Option A is incorrect because using Kubeflow Pipelines on Google Kubernetes Engine is not the most convenient way to orchestrate the entire pipeline with minimal cluster management. Kubeflow Pipelines is an open-source platfor m that allows you to build, run, and manage ML pipelines using containers 1 . Google Kubernetes Engine is a service that allows you to create and manage clusters of virtual machines that run Kubernetes, an open-source system for orchestrat ing containerized applications 2 . However, this option requires more effort and re sources than option B, as it involves creating and configuring the clusters, installing and maintaining Kubeflow Pipelines, and writing and running the pipeline code.
* Option B is correct because using Vertex AI Pipelines with TensorFlow Extended (TFX) SDK is the best way to orchestrate the entire pipeline with minimal cluster management. Vertex AI Pipelines is a service that allows you to create and run scalable and portable ML pipelines on Google Cloud 3
. TensorFlow Extended (TFX) is a framework that provides a set of components and libraries for building production-ready ML pipelines using TensorFlow 4 . You can use Vertex AI Pipelines with TFX SDK to ingest and preprocess the data in Cloud Storage, train and tune the object model using Vertex AI jobs, and deploy the model to an endpoint, using predefined or custom components. Vertex AI Pipelines handles the underlying infrastructure and orchestration for you, so you don't need to worry about cluster management or scalability.
* Option C is incorrect because using Vertex AI Pipelines with Kubeflow Pipelines SDK is not the most suitable way to orchestrate the entire pipeline with minimal cluster management. Kubeflow Pipelines SDK is a library that allows you to build and run ML pipelines using Kubeflow Pipelines 5 . You can use Vertex AI Pipelines with Kubeflow Pipelines SDK to create and run ML pipelines on Google Cloud, using containers. However, this option is less convenient and consistent than option B, as it requires you to use different APIs and tools for different steps of the pipeline, such as Vertex AI SDK for training and deployment, and Kubeflow Pipelines SDK for ingestion and preprocessing. Moreover, this option does not leverage the benefits of TFX, such as the standard components, the metadata store, or the ML Metadata library.
* Option D is incorrect because using Cloud Composer for the orchestration is not the most efficient way to orchestrate the entire pipeline with minimal cluster management. Cloud Composer is a service that allows you to create and run workflows using Apache Airflow, an open-source platform for orchestrating complex tasks. You can use Cloud Composer to orchestrate the entire pipeline, by creating and managing DAGs (directed acyclic graphs) that define the dependencies and order of the tasks. However, this option is more complex and costly than option B, as it involves creating and configuring the environments, installing and maintaining Airflow, and writing and running the DAGs.
References:
Kubeflow Pipelines documentation
Google Kubernetes Engine documentation
Vertex AI Pipelines documentation
TensorFlow Extended documentation
Kubeflow Pipelines SDK documentation
[Cloud Composer documentation]
[Vertex AI documentation]
[Cloud Storage documentation]
[TensorFlow documentation]
NEW QUESTION # 299
You are training and deploying updated versions of a regression model with tabular data by using Vertex Al Pipelines. Vertex Al Training Vertex Al Experiments and Vertex Al Endpoints. The model is deployed in a Vertex Al endpoint and your users call the model by using the Vertex Al endpoint. You want to receive an email when the feature data distribution changes significantly,so you can retrigger the training pipeline and deploy an updated version of your model What should you do?
Answer: B
Explanation:
Prediction drift is the change in the distribution of feature values or labels over time. It can affect the performance and accuracy of the model, and may require retraining or redeploying the model. Vertex AI Model Monitoring allows you to monitor prediction drift on your deployed models and endpoints, and set up alerts and notifications when the drift exceeds a certain threshold. You can specify an email address to receive the notifications, and use the information to retrigger the training pipeline and deploy an updated version of your model. This is the most direct and convenient way to achieve your goal. References:
* Vertex AI Model Monitoring
* Monitoring prediction drift
* Setting up alerts and notifications
NEW QUESTION # 300
Your organization ' s call center has asked you to develop a model that analyzes customer sentiments in each call. The call center receives over one million calls daily, and data is stored in Cloud Storage. The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. You need to select components for data processing and for analytics. How should the data pipeline be designed?
Answer: B
Explanation:
A data pipeline is a set of steps or processes that move data from one or more sources to one or more destinations, usually for the purpose of analysis, transformation, or storage. A data pipeline can be designed using various components, such as data sources, data processing tools, data storage systems, and data analytics tools 1 To design a data pipeline for analyzing customer sentiments in each call, one should consider the following requirements and constraints:
* The call center receives over one million calls daily, and data is stored in Cloud Storage. This implies that the data is large, unstructured, and distributed, and requires a scalable and efficient data processing tool that can handle various types of data formats, such as audio, text, or image.
* The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. This implies that the data is sensitive and subject to data privacy and compliance regulations, and requires a secure and reliable data storage system that can enforce data encryption, access control, and regional policies.
* The data science team has a third-party tool for visualization and access which requires a SQL ANSI-
2011 compliant interface. This implies that the data analytics tool is external and independent of the data pipeline, and requires a standard and compatible data interface that can support SQL queries and operations.
One of the best options for selecting components for data processing and for analytics is to use Dataflow for data processing and BigQuery for analytics. Dataflow is a fully managed service for executing Apache Beam pipelines for data processing, such as batch or stream processing, extract-transform-load (ETL), or data integration. BigQuery is a serverless, scalable, and cost-effective data warehouse that allows you to run fast and complex queries on large-sca le data 2 3 Using Dataflow and BigQuery has several advantages for this use case:
* Dataflow can process large and unstructured data from Cloud Storage in a parallel and distributed manner, and apply various transformations, such as converting audio to text, extracting sentiment scores, or anonymizing PII. Dataflow can also handle both batch and stream processing, which can enable real-time or near-real-time analysis of the call data.
* BigQuery can store and analyze the processed data from Dataflow in a secure and reliable way, and enforce data encryption, access control, and regional policies. BigQuery can also support SQL ANSI-
2011 compliant interface, which can enable the data science team to use their third-party tool for visualization and access. BigQuery can also integrate with various Google Cloud services and tools, such as AI Platform, Data Studio, or Looker.
* Dataflow and BigQuery can work seamlessly together, as they are both part of the Google Cloud ecosystem, and support various data formats, such as CSV, JSON, Avro, or Parquet. Dataflow and BigQuery can also leverage the benefits of Google Cloud infrastructure, such as scalability, performance, and cost-effectiveness.
The other options are not as suitable or feasible. Using Pub/Sub for data processing and Datastore for analytics is not ideal, as Pub/Sub is mainly designed for event-driven and asynchronous messaging, not data processing, and Datastore is mainly designed for low-latency and high-throughput key-value operations, not analytics. Using Cloud Function for data processing and Cloud SQL for analytics is not optimal, as Cloud Function has limitations on the memory, CPU, and execution time, and does not support complex data processing, and Cloud SQL is a relational database service that may not scale well for large-scale data. Using Cloud Composer for data processing and Cloud SQL for analytics is not relevant, as Cloud Composer is mainly designed for orchestrating complex workflows across multiple systems, not data processing, and Cloud SQL is a relational database service that may not scale well for large-scale data.
References: 1 : Data pipeline 2 : Dataflow overview 3 : BigQuery overview : [Dataflow documentation] : [BigQuery documentation]
NEW QUESTION # 301
You are designing an architecture with a serverless ML system to enrich customer support tickets with informative metadata before they are routed to a support agent. You need a set of models to predict ticket priority, predict ticket resolution time, and perform sentiment analysis to help agents make strategic decisions when they process support requests. Tickets are not expected to have any domain-specific terms or jargon.
The proposed architecture has the following flow: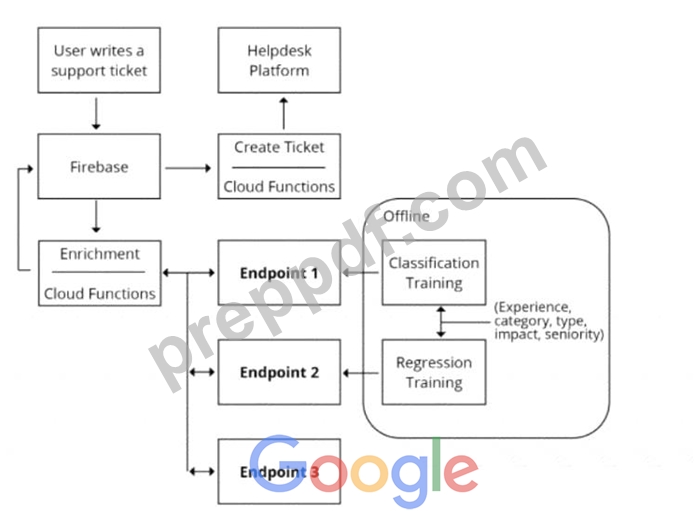
Which endpoints should the Enrichment Cloud Functions call?
Answer: D
Explanation:
Vertex AI is a unified platform for building and deploying ML models on Google Cloud. It supports both custom and AutoML models, and provides various tools and services for ML development, such as Vertex Pipelines, Vertex Vizier, Vertex Explainable AI, and Vertex Feature Store. Vertex AI can be used to create models for predicting ticket priority and resolution time, as these are domain-specific tasks that require custom training data and evaluation metrics. Cloud Natural Language API is a pre-trained service that provides natural language understanding capabilities, such as sentiment analysis, entity analysis, syntax analysis, and content classification. Cloud Natural Language API can be used toperform sentiment analysis on the support tickets, as this is a general task that does not require domain-specific knowledge or jargon. The other options are not suitable for the given architecture. AutoML Natural Language and AutoML Vision are services that allow users to create custom natural language and vision models using their own data and labels. They are not needed for sentiment analysis, as Cloud Natural Language API already provides this functionality. Cloud Vision API is a pre-trained service that provides image analysis capabilities, such as object detection, face detection, text detection, and image labeling. It is not relevant for the support tickets, as they are not expected to have any images. References:
* Vertex AI documentation
* Cloud Natural Language API documentation
NEW QUESTION # 302
......
The Professional-Machine-Learning-Engineer exam prep is produced by our expert, is very useful to help customers pass their Professional-Machine-Learning-Engineer exams and get the certificates in a short time. If you want to know the quality of our Professional-Machine-Learning-Engineer guide braindumps befor you buy it, you can just free download the demo of our Professional-Machine-Learning-Engineer Exam Questions. We can sure that our Professional-Machine-Learning-Engineer training guide will help you get the certificate easily. If you are wailing to believe us and try to learn our Professional-Machine-Learning-Engineer exam torrent, you will get an unexpected result.
Professional-Machine-Learning-Engineer Reliable Real Exam: https://www.preppdf.com/Google/Professional-Machine-Learning-Engineer-prepaway-exam-dumps.html
P.S. Free 2026 Google Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by PrepPDF: https://drive.google.com/open?id=1esCaaeU477C5TrUzIGRu6zftpu4iOIsO