BONUS!!! Laden Sie die vollständige Version der Pass4Test Databricks-Certified-Professional-Data-Engineer Prüfungsfragen kostenlos herunter: https://drive.google.com/open?id=1byK_ZuPWkTWKyGNjnhhPNqSNV369ox6W
Wenn Sie sich noch anstrengend um die Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung bemühen, dann kann Pass4Test in diesem Moment Ihnen helfen, Problem zu lösen. Pass4Test bietet Ihnen Schulungsunterlagen von hoher Qualität, damit Sie die Prüfung bestehen und exzellentes Mitglied der Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierung werden können. Wenn Sie sich entscheiden, durch die Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung sich zu verbessern, dann wählen Sie bitte Pass4Test. Pass4Test zu wählen ist keinesfalls nicht falsch. Unser Pass4Test verspricht, dass Sie beim ersten Versuch die Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung bestehen und somit das Zertifikat bekommen können. So können Sie sich sicher verbessern.
| Section | Objectives |
|---|---|
| Data Modeling and Storage | - Schema evolution and data partitioning strategies - Design scalable data lakehouse architectures - Delta Lake table design and optimization |
| Security, Governance, Monitoring, and Optimization | - Cost optimization and performance tuning - Implement Unity Catalog governance and access control - Monitor and optimize Spark workloads |
| Production Pipelines and Orchestration | - Build and manage workflows using Databricks Jobs - Automate ETL pipelines and scheduling - Pipeline reliability and fault tolerance |
| Data Ingestion and Transformation | - Transform and clean datasets using Spark SQL and DataFrame APIs - Ingest data using Apache Spark and Databricks - Handle batch and streaming data pipelines |
>> Databricks-Certified-Professional-Data-Engineer Deutsche <<
Bemühen Sie sich noch um die Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung? Wollen Sie schneller Ihren Traum verwirklichen? Bitte wählen Sie die Databricks-Certified-Professional-Data-Engineer Schulungsmaterialien von Pass4Test. Wenn Sie Pass4Test wählen, ist es kein Traum mehr, das Databricks Databricks-Certified-Professional-Data-Engineer Zertifikat zu erhalten.
71. Frage
A data engineer is designing a Lakeflow Declarative Pipeline to process streaming order data. The pipeline uses Auto Loader to ingest data and must enforce data quality by ensuring customer_id and amount are greater than zero. Invalid records should be dropped.
Which Lakeflow Declarative Pipelines configurations implement this requirement using Python?
Antwort: A
Begründung:
Lakeflow Declarative Pipelines (LDP), formerly Delta Live Tables (DLT), supports enforcing data quality using expectations . Expectations can either:
* Track violations (expect) # records that do not meet conditions are flagged but still included in the pipeline.
* Drop violations (expect_or_drop) # records that do not meet conditions are excluded from downstream tables.
* Fail pipeline on violations (expect_or_fail) # records that fail conditions stop the pipeline.
In this scenario, the requirement explicitly states that invalid records (where customer_id is null or amount #
0) must be dropped . According to the official documentation, the correct method is .expect_or_drop( " expectation_name " , " SQL_predicate " ) applied on the streaming input.
* Option A is correct: It uses .expect_or_drop directly within the transformation chain for both rules, ensuring records that fail are removed before writing to the silver table.
* Option B incorrectly uses @dlt.expect decorators, which only track violations but do not drop invalid rows.
* Option C uses .expect, which also only flags rows, not drop them.
* Option D uses @dlt.expect_or_drop decorator syntax, which is not supported in Python API; expect_or_drop must be applied as a method on the DataFrame, not as a decorator.
Therefore, the correct solution is Option A , which ensures compliance by enforcing data quality and dropping invalid rows programmatically during ingestion.
Reference: Databricks Lakeflow Declarative Pipelines Documentation - Expectations (expect, expect_or_drop, expect_or_fail)
72. Frage
The data engineering team has configured a Databricks SQL query and alert to monitor the values in a Delta Lake table. The recent_sensor_recordings table contains an identifying sensor_id alongside the timestamp and temperature for the most recent 5 minutes of recordings.
The below query is used to create the alert: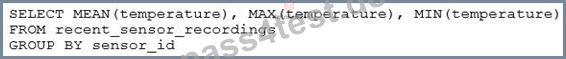
The query is set to refresh each minute and always completes in less than 10 seconds. The alert is set to trigger when mean (temperature) > 120 . Notifications are triggered to be sent at most every 1 minute.
If this alert raises notifications for 3 consecutive minutes and then stops, which statement must be true?
Antwort: C
Begründung:
This is the correct answer because the query is using a GROUP BY clause on the sensor_id column, which means it will calculate the mean temperature for each sensor separately. The alert will trigger when the mean temperature for any sensor is greater than 120, which means at least one sensor had an average temperature above 120 for three consecutive minutes. The alert will stop when the mean temperature for all sensors drops below 120. Verified References: [Databricks Certified Data Engineer Professional], under "SQL Analytics" section; Databricks Documentation, under "Alerts" section.
73. Frage
Which of the following is the correct statement for a session scoped temporary view?
Antwort: D
Begründung:
Explanation
The answer is Temporary views are lost once the notebook is detached and attached There are two types of temporary views that can be created, Session scoped and Global
*A local/session scoped temporary view is only available with a spark session, so another notebook in the same cluster can not access it. if a notebook is detached and reattached local temporary view is lost.
*A global temporary view is available to all the notebooks in the cluster, if a cluster restarts global temporary view is lost.
74. Frage
You have written a notebook to generate a summary data set for reporting, Notebook was scheduled using the job cluster, but you realized it takes an average of 8 minutes to start the cluster, what feature can be used to start the cluster in a timely fashion?
Antwort: E
Begründung:
Explanation
Cluster pools allow us to reserve VM's ahead of time, when a new job cluster is created VM are grabbed from the pool. Note: when the VM's are waiting to be used by the cluster only cost incurred is Azure. Databricks run time cost is only billed once VM is allocated to a cluster.
Here is a demo of how to setup and follow some best practices,
https://www.youtube.com/watch?v=FVtITxOabxg&ab_channel=DatabricksAcademy
75. Frage
To reduce storage and compute costs, the data engineering team has been tasked with curating a series of aggregate tables leveraged by business intelligence dashboards, customer-facing applications, production machine learning models, and ad hoc analytical queries.
The data engineering team has been made aware of new requirements from a customer-facing application, which is the only downstream workload they manage entirely. As a result, an aggregate table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added.
Which of the solutions addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed?
Antwort: B
Begründung:
Explanation
This is the correct answer because it addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed. The situation is that an aggregate table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added, due to new requirements from a customer-facing application. By configuring a new table with all the requisite fields and new names and using this as the source for the customer-facing application, the data engineering team can meet the new requirements without affecting other teams that rely on the existing table schema and name. By creating a view that maintains the original data schema and table name by aliasing select fields from the new table, the data engineering team can also avoid duplicating data or creating additional tables that need to be managed. Verified References: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under
"CREATE VIEW" section.
76. Frage
......
Nach den Forschungen in den letzten Jahren sind die Fragen und Antworten zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung von Pass4Test den realen Prüfung sehr ähnlich. Pass4Test verspricht, dass Sie zum ersten Mal die Databricks Databricks-Certified-Professional-Data-Engineer (Databricks Certified Professional Data Engineer Exam) Zertifizierungsprüfung 100% bestehen können.
Databricks-Certified-Professional-Data-Engineer Exam Fragen: https://www.pass4test.de/Databricks-Certified-Professional-Data-Engineer.html
P.S. Kostenlose 2026 Databricks Databricks-Certified-Professional-Data-Engineer Prüfungsfragen sind auf Google Drive freigegeben von Pass4Test verfügbar: https://drive.google.com/open?id=1byK_ZuPWkTWKyGNjnhhPNqSNV369ox6W