New SPS-C01 Exam Practice, Book SPS-C01 Free

P.S. Free & New SPS-C01 dumps are available on Google Drive shared by BraindumpsIT: https://drive.google.com/open?id=1uJ8wkk-Xq9IPqoJpdCSNj1uSzbmQ3NWg
Do not hesitate to seek our extraordinary Snowflake SPS-C01 practice material to make a name in the field of Technology. BraindumpsIT has designed the Snowflake SPS-C01 product in three formats. You will find their specifications below to comprehend them better.
| Section | Objectives |
|---|
| Testing, Debugging, and Deployment | - Production readiness
- 1. Debugging Snowpark applications
- 2. Deployment strategies
|
| Data Engineering with Snowpark | - Pipeline development
- 1. Integration with Snowflake data pipelines
- 2. Batch processing workflows
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
- 1. Snowflake execution model overview
- 2. Snowpark APIs and supported languages
|
| DataFrame Operations and Data Processing | - Data transformation workflows
- 1. Joins and window functions
- 2. Filtering, selecting, and aggregations
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
- 1. Stored procedures in Snowpark
- 2. Python UDFs
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
- 1. Pushdown optimization concepts
- 2. Resource utilization tuning
|
>> New SPS-C01 Exam Practice <<
Book SPS-C01 Free | SPS-C01 Test Torrent
It is well known that even the best people fail sometimes, not to mention the ordinary people. In face of the Snowflake SPS-C01 exam, everyone stands on the same starting line, and those who are not excellent enough must do more. If you happen to be one of them, our Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 Learning Materials will greatly reduce your burden and improve your possibility of passing the exam. Our advantages of time-saving and efficient can make you no longer be afraid of the SPS-C01 exam.
Snowflake Certified SnowPro Specialty - Snowpark Sample Questions (Q216-Q221):
NEW QUESTION # 216
You have a Snowpark Python UDTF that splits a comma-separated string into individual elements and returns them as rows. The UDTF is defined as follows:
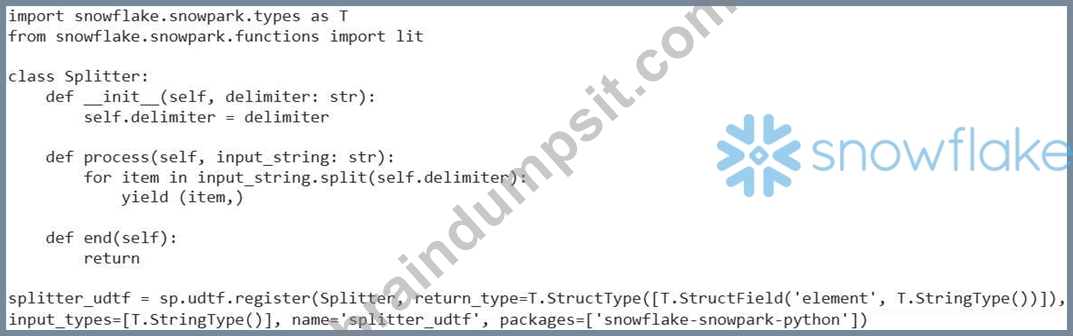
Which of the following SQL queries correctly calls and uses this UDTF?
Answer: E
Explanation:
UDTFs must be called using the 'TABLE()' function in SQL. The 'LATERAL' keyword is used because the UDTF depends on the data from the preceding 'VALUES' clause. The select statement is 'lateral (select from values ('a,b,c') as t(columnl))' , which provides the input to the 'splitter_udtf. Options A and B are incorrect because they lack the proper and 'LATERAL' syntax or fail to provide an appropriate input using 'VALUES. C and D are incorrect since they dont select all fields to pass as parameter.
NEW QUESTION # 217
A data engineering team is using Snowpark Python to build a complex ETL pipeline. They notice that certain transformations are not being executed despite being defined in the code. Which of the following are potential reasons why transformations in Snowpark might not be executed immediately, reflecting the principle of lazy evaluation? Select TWO correct answers.
- A. The 'eager_execution' session parameter is set to 'True'.
- B. Snowpark automatically executes all transformations as soon as they are defined, regardless of whether the results are needed.
- C. The size of the data being processed exceeds Snowflake's memory limits, causing transformations to be skipped.
- D. Snowpark operations are only executed when an action (e.g., 'collect()', 'show()', is called on the DataFrame or when the DataFrame is materialized.
- E. Snowpark employs lazy evaluation to optimize query execution by delaying the execution of transformations until the results are actually required.
Answer: D,E
Explanation:
Snowpark employs lazy evaluation, which means transformations are not executed until an action is performed on the DataFrame. This allows Snowflake to optimize the entire query plan before execution. Setting 'eager_execution' to True does NOT exist in Snowpark Python. Data size exceeding Snowflake's limits would result in an error, not skipped transformations.
NEW QUESTION # 218
You are tasked with creating a Snowpark Python stored procedure that reads data from a Snowflake table, performs a complex data transformation using a 3rd party Python library (e.g., pandas, scikit-learn), and writes the transformed data to another Snowflake table.
The data transformation requires significant memory. You need to register this stored procedure in Snowflake. Which of the following approaches is the MOST appropriate for registering the stored procedure and managing the dependencies?
- A. Use the function to add the required Python libraries before registering the stored procedure with the '@sproc' decorator.
- B. Create a Snowflake stage, upload the Python libraries as .zip files to the stage, and specify the stage path in the '@sproc' decorator's 'imports' parameter.
- C. Install the required Python libraries directly on the Snowflake compute warehouse using a SQL command.
- D. Create a conda environment file ('environment.yml') specifying the dependencies, upload it to a stage, and then use the '@sproc' decorator with the 'packages' argument referencing the conda environment.
- E. Use the '@sproc' decorator without specifying any dependencies, assuming that the necessary libraries are pre-installed on the Snowflake worker nodes.
Answer: D
Explanation:
Using a conda environment file ('environment.ymlS) uploaded to a stage is the recommended and most reliable way to manage dependencies for Snowpark Python stored procedures. It ensures that all required libraries and their versions are consistently available. Option A is incorrect as libraries are not pre-installed. Option B is deprecated. Option C is possible but less manageable than a conda environment. Option E is not possible, you cannot directly install onto the warehouse.
NEW QUESTION # 219
You have a Snowpark application that reads data from a large Snowflake table and performs several transformations. During testing, you observe that the application's performance is inconsistent, with some runs taking significantly longer than others, even with the same input data'. You suspect that data locality might be a contributing factor. What steps can you take within your Snowpark application to investigate and potentially improve data locality and performance consistency?
- A. Disable Snowflake's result cache. This ensures that the application always reads the most recent data from disk, regardless of performance impact.
- B. Enable Snowflake's automatic clustering on the underlying table if it's not already enabled. This will physically organize the data on disk based on the clustering key.
- C. Ensure the Snowpark session is configured with a large enough warehouse size to minimize data spilling to disk.
- D. Implement caching using , combined with a targeted 'repartition()' to ensure that frequently accessed data is readily available in memory close to the processing nodes.
- E. Use to redistribute the data across the cluster based on a relevant key. This can improve data locality for subsequent operations.
Answer: B,D,E
Explanation:
'DataFrame.repartition(V allows you to redistribute data based on a chosen key, improving locality for operations that depend on that key. Snowflake's automatic clustering physically organizes data on disk, improving read performance. Combining with repartition()' ensures that frequently accessed, well-partitioned data is readily available in memory close to the processing nodes, boosting performance. Disabling the cache makes the application's performance worse. The warehouse size, if not large enough, can also lead to data spilling to disk, decreasing the performance.
NEW QUESTION # 220
You have a Snowpark DataFrame containing sales data with columns 'sale_date', and 'sale_amount'. You need to calculate the cumulative sales amount for each product over time, ordered by 'sale_date'. Which of the following Snowpark code snippets correctly implements this using window functions?
Answer: E
Explanation:
Option A is correct. It correctly uses to group by 'product_id' and 'order_by' to sort by 'sale_date' within each product group. It then calculates the cumulative sum using Options B, C, D and E contain typos or incorrect function usage or order of arguments. 'cumulative_surn' is not a standard function provided.
NEW QUESTION # 221
......
We are a group of IT experts to provide professional study materials to people preparing Snowflake certification exam. There are free demo you can download to check the accuracy of our SPS-C01 Braindumps. It just needs to take one or two days to practice BraindumpsIT SPS-C01 dumps torrent and review the key points of our pass guide. Clearing exam is 100% guaranteed.
Book SPS-C01 Free: https://www.braindumpsit.com/SPS-C01_real-exam.html
- Unparalleled Snowflake New SPS-C01 Exam Practice With Interarctive Test Engine - The Best Book SPS-C01 Free 😳 Search for ➡ SPS-C01 ️⬅️ and obtain a free download on 《 www.practicevce.com 》 🧏New SPS-C01 Test Tips
- SPS-C01 Valid Exam Syllabus 🎐 SPS-C01 Exam Bootcamp 🥿 SPS-C01 Valid Exam Dumps 🆓 Search for 「 SPS-C01 」 and obtain a free download on ➤ www.pdfvce.com ⮘ 🎊SPS-C01 Valid Exam Syllabus
- SPS-C01 Exam Torrent - Snowflake Certified SnowPro Specialty - Snowpark Prep Torrent -amp; SPS-C01 Test Braindumps 👿 Search for ➠ SPS-C01 🠰 and download exam materials for free through ( www.exam4labs.com ) 🥍SPS-C01 Book Free
- SPS-C01 – 100% Free New Exam Practice | Professional Book Snowflake Certified SnowPro Specialty - Snowpark Free 🚏 Search on “ www.pdfvce.com ” for 《 SPS-C01 》 to obtain exam materials for free download 🔋SPS-C01 Valid Exam Dumps
- Free PDF Quiz 2026 SPS-C01: High-quality New Snowflake Certified SnowPro Specialty - Snowpark Exam Practice ⚓ Enter ➥ www.exam4labs.com 🡄 and search for 「 SPS-C01 」 to download for free ⛄Exam SPS-C01 Pattern
- SPS-C01 Reliable Test Preparation 📔 New SPS-C01 Test Tips 📆 Reliable SPS-C01 Exam Materials 🤘 Easily obtain free download of ⮆ SPS-C01 ⮄ by searching on ▷ www.pdfvce.com ◁ 🙂Exam SPS-C01 Pattern
- Relevant SPS-C01 Answers 💿 Vce SPS-C01 Download 🖊 Exam SPS-C01 Pattern 🦌 Search for [ SPS-C01 ] on ⇛ www.prepawaypdf.com ⇚ immediately to obtain a free download 🪐New SPS-C01 Test Tips
- SPS-C01 Exam Bootcamp 🎀 SPS-C01 Valid Exam Syllabus 🕊 Exam Sample SPS-C01 Online 🚹 Simply search for ▶ SPS-C01 ◀ for free download on ⮆ www.pdfvce.com ⮄ 🦯SPS-C01 Latest Exam Cram
- Exam Sample SPS-C01 Online 🙀 SPS-C01 Exam Bootcamp 🌀 SPS-C01 Valid Exam Syllabus 🗺 Search on ➡ www.practicevce.com ️⬅️ for 【 SPS-C01 】 to obtain exam materials for free download 🐧Examcollection SPS-C01 Dumps
- Absolute Your Exam Preparation With Snowflake SPS-C01 Dumps 🦎 Copy URL ▷ www.pdfvce.com ◁ open and search for “ SPS-C01 ” to download for free 👨Exam SPS-C01 Pattern
- SPS-C01 Exam Torrent - Snowflake Certified SnowPro Specialty - Snowpark Prep Torrent -amp; SPS-C01 Test Braindumps 🔭 Search on 【 www.examcollectionpass.com 】 for ⇛ SPS-C01 ⇚ to obtain exam materials for free download 🚄Reliable SPS-C01 Exam Materials
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by BraindumpsIT: https://drive.google.com/open?id=1uJ8wkk-Xq9IPqoJpdCSNj1uSzbmQ3NWg









