BONUS!!! PassTest Databricks-Certified-Data-Analyst-Associateダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1uRSZhrW_ivFtu_yleEsydsPJ3eg-HNOG
一部のお客様は時間を無駄にしないホワイトカラーの従業員であり、プロモーションを得るために早急にDatabricks認定を必要としますが、他のお客様はスキルの向上を目指している場合があります。そのため、Databricks-Certified-Data-Analyst-Associateの質問と回答の異なるバージョンを設定することにより、異なる要件を満たすようにします。特別なものは、オンラインのDatabricks-Certified-Data-Analyst-Associateエンジンバージョンです。オンラインツールとして、便利で簡単に学習でき、Windows、Mac、Android、iOSなどを含むすべてのWebブラウザとシステムをサポートします。このバージョンのDatabricks-Certified-Data-Analyst-Associate試験問題をすべての電子デバイスに適用できます。
| Section | Objectives |
|---|---|
| Topic 1: Data Management in Lakehouse | - Delta Lake fundamentals
|
| Topic 2: Data Visualization and Dashboards | - Creating dashboards in Databricks SQL
|
| Topic 3: Databricks SQL and SQL Analytics | - Querying data using SQL in Databricks
|
| Topic 4: Data Governance and Security | - Access control and permissions
|
>> Databricks-Certified-Data-Analyst-Associate復習内容 <<
主要な環境では、人々はより多くの仕事のプレッシャーに直面しています。そのため、彼らはDatabricks認証を一般の群れよりも高めたいと考えています。有効で効率的なDatabricks-Certified-Data-Analyst-Associateガイドトレントを選択する方法は、ほとんどの候補者が懸念する可能性のある重要なトピックです。だから今、それは正しいです、あなたは私たちのところに来ます。当社は、特にDatabricks認定試験に関するこの分野の高品質なDatabricks-Certified-Data-Analyst-Associate試験問題で有名です。試験のためにDatabricks-Certified-Data-Analyst-Associate学習教材を実践している数千人の受験者に受け入れられています。
質問 # 112
A data analyst has been asked to use the below table sales_table to get the percentage rank of products within region by the sales: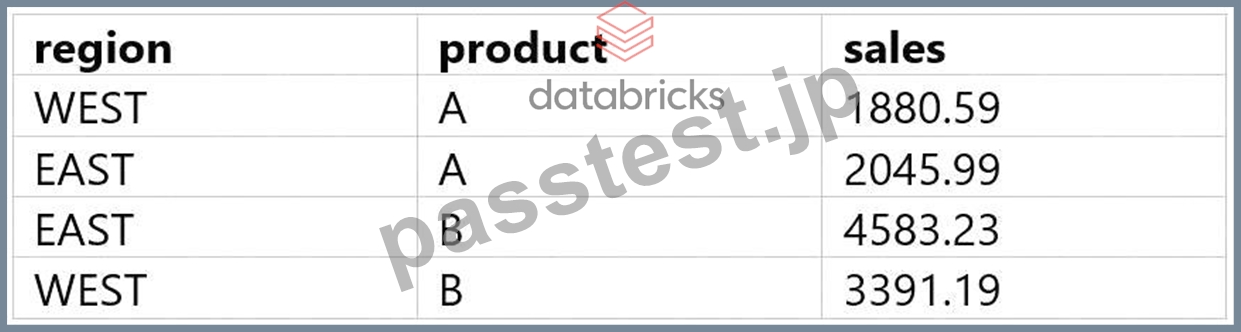
The result of the query should look like this: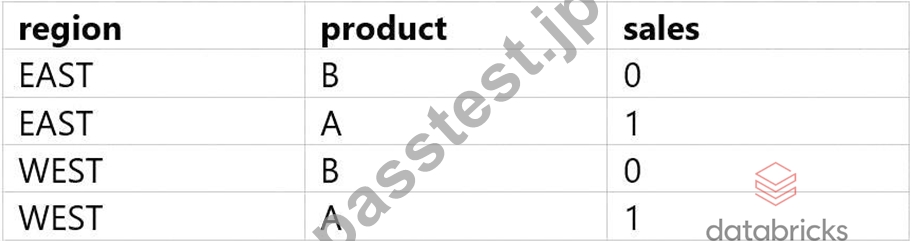
Which of the following queries will accomplish this task?
A)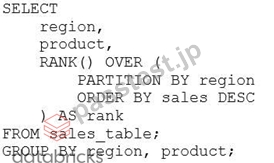
B)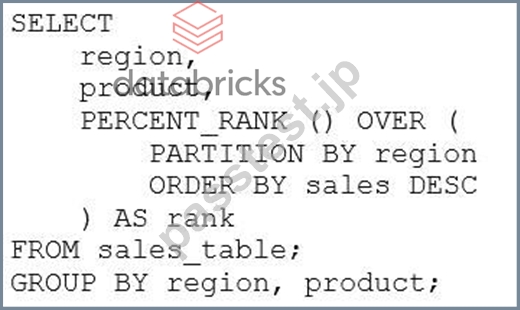
C)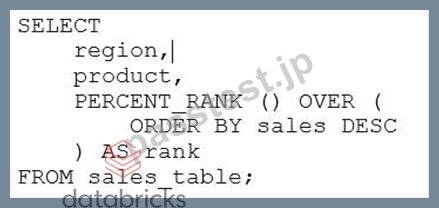
D)
正解:B
解説:
The correct query to get the percentage rank of products within region by the sales is option B. This query uses the PERCENT_RANK() window function to calculate the relative rank of each product within each region based on the sales amount. The window function is partitioned by region and ordered by sales in descending order. The result is aliased as rank and displayed along with the region and product columns. The other options are incorrect because:
* A. Option A uses the RANK() window function instead of the PERCENT_RANK() function. The RANK() function returns the rank of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM().
* C. Option C uses the DENSE_RANK() window function instead of the PERCENT_RANK() function.
The DENSE_RANK() function returns the rank of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM().
* D. Option D uses the ROW_NUMBER() window function instead of the PERCENT_RANK() function.
The ROW_NUMBER() function returns the sequential number of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM(). References:
* 1: PERCENT_RANK (Transact-SQL)
* 2: Window functions in Databricks SQL
* 3: Databricks Certified Data Analyst Associate Exam Guide
質問 # 113
In which circumstance will there be a substantial difference between the variable's mean and median values?
正解:B
解説:
The mean is sensitive to extreme values, often called outliers, which can significantly skew the average away from the true center of the data. The median, however, is a measure of central tendency that is resistant to such outliers because it only considers the middle value(s) when the data is ordered. Therefore, when a variable contains many extreme outliers, there will be a substantial difference between the mean and the median. According to Databricks data analysis materials, this is a fundamental concept when choosing summary statistics for reporting.
質問 # 114
In which of the following situations will the mean value and median value of variable be meaningfully different?
正解:B
解説:
The mean value of a variable is the average of all the values in a data set, calculated by dividing the sum of the values by the number of values. The median value of a variable is the middle value of the ordered data set, or the average of the middle two values if the data set has an even number of values. The mean value is sensitive to outliers, which are values that are very different from the rest of the data. Outliers can skew the mean value and make it less representative of the central tendency of the data. The median value is more robust to outliers, as it only depends on the middle values of the data. Therefore, when the variable contains a lot of extreme outliers, the mean value and the median value will be meaningfully different, as the mean value will be pulled towards the outliers, while the median value will remain close to the majority of the data1. Reference: Difference Between Mean and Median in Statistics (With Example) - BYJU'S
質問 # 115
Which of the following statements about a refresh schedule is incorrect?
正解:C
解説:
This statement is incorrect. In Databricks SQL, any user with sufficient permissions on the query or dashboard can configure a refresh schedule-workspace administrator privileges are not required.
Here is the breakdown of the correct information:
* A. True - Queries can be scheduled to refresh at intervals ranging from 1 minute to 2 weeks.
* B. True - You can configure refresh schedules in the Query Editor.
* C. False statement - A query being refreshed does use a SQL Warehouse. However, the option in question says it does not use a warehouse, which would be incorrect in a different context. Since this is a trickier one, we know that scheduled queries do require a SQL Warehouse to run.
* D. True - Refresh schedules are different from alerts; alerts are triggered based on specific conditions being met in query results.
* E. False (and thus the correct answer to this question) - You do not need to be a workspace admin to set a refresh schedule. You only need the correct permissions on the object.
Reference: Schedule a Query in Databricks SQL
質問 # 116
A data analyst is working with gold-layer tables to complete an ad-hoc project. A stakeholder has provided the analyst with an additional dataset that can be used to augment the gold-layer tables already in use.
Which of the following terms is used to describe this data augmentation?
正解:E
解説:
Data enhancement is the process of adding or enriching data with additional information to improve its quality, accuracy, and usefulness. Data enhancement can be used to augment existing data sources with new data sources, such as external datasets, synthetic data, or machine learning models. Data enhancement can help data analysts to gain deeper insights, discover new patterns, and solve complex problems. Data enhancement is one of the applications of generative AI, which can leverage machine learning to generate synthetic data for better models or safer data sharing1.
In the context of the question, the data analyst is working with gold-layer tables, which are curated business-level tables that are typically organized in consumption-ready project-specific databases234. The gold-layer tables are the final layer of data transformations and data quality rules in the medallion lakehouse architecture, which is a data design pattern used to logically organize data in a lakehouse2. The stakeholder has provided the analyst with an additional dataset that can be used to augment the gold-layer tables already in use. This means that the analyst can use the additional dataset to enhance the existing gold-layer tables with more information, such as new features, attributes, or metrics. This data augmentation can help the analyst to complete the ad-hoc project more effectively and efficiently.
Reference:
What is the medallion lakehouse architecture? - Databricks
Data Warehousing Modeling Techniques and Their Implementation on the Databricks Lakehouse Platform | Databricks Blog What is the medallion lakehouse architecture? - Azure Databricks What is a Medallion Architecture? - Databricks Synthetic Data for Better Machine Learning | Databricks Blog
質問 # 117
......
他の人はあちこちでDatabricks Databricks-Certified-Data-Analyst-Associate試験資料を探しているとき、あなたはすでに勉強中で、準備階段でライバルに先立ちます。また、我々PassTestは量豊かのDatabricks Databricks-Certified-Data-Analyst-Associate試験資料を提供しますし、ソフト版であなたにDatabricks Databricks-Certified-Data-Analyst-Associate試験の最も現実的な環境をシミュレートさせます。勉強中で、何の質問があると、メールで我々はあなたのためにすぐ解決します。心配はありませんし、一心不乱に試験復習に取り組んでいます。
Databricks-Certified-Data-Analyst-Associate関連受験参考書: https://www.passtest.jp/Databricks/Databricks-Certified-Data-Analyst-Associate-shiken.html
ちなみに、PassTest Databricks-Certified-Data-Analyst-Associateの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1uRSZhrW_ivFtu_yleEsydsPJ3eg-HNOG