
Außerdem sind jetzt einige Teile dieser Zertpruefung MLA-C01 Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1X5UKX49sD0z2kF4vIjGhZ-66qKt0Ij98
Um die Bedürfnisse von den meisten IT-Fachleuten abzudecken, haben das Expertenteam die Prüfungsthemen in den letzten Jahren studiert. So kommen die zielgerichteten Fragen und Antworten zur Amazon MLA-C01 Zertifizierungsprüfung vor. Die Ähnlichkeit unserere Dumps mit den echten Prüfung beträgt 95%. Zertpruefung wird Ihnen helfen, die Amazon MLA-C01 Prüfung 100% zu bestehen. Sonst erstatteten wir Ihnen die gesammte Summe zurück. Sie können im Internet die Demo zur Amazon MLA-C01 Zertifizierungsprüfung kostenlos herunterladen, so dass Sie die Zuverlässigkeit unserer Produkte testen können. Schicken Sie doch die Produkte von Zertpruefung in den Warenkorb. Zertpruefung wird Ihren Traum verwirklichen.
| Thema | Einzelheiten |
|---|---|
| Thema 1 |
|
| Thema 2 |
|
| Thema 3 |
|
| Thema 4 |
|
>> MLA-C01 Online Praxisprüfung <<
Die Zuverlässigkeit basiert sich auf die hohe Qualität, deshalb ist unsere Amazon MLA-C01 vertrauenswürdig. Allein die mit einer Höhe von fast 100% Bestehensquote überzeugen Sie vielleicht nicht. Dann laden Sie bitte die kostenlose Demos der Amazon MLA-C01 herunter und probieren! Um verschiedene Gewohnheiten der Prüfungsteilnehmer anzupassen, bieten wir insgesamt 3 Versionen von Amazon MLA-C01. Nach den Informationenen über die Ermäßigung u.a. können Sie auf unserer Webseite online erkundigen.
108. Frage
A company needs to combine data from multiple sources. The company must use Amazon Redshift Serverless to query an AWS Glue Data Catalog database and underlying data that is stored in an Amazon S3 bucket.
Select and order the correct steps from the following list to meet these requirements. Select each step one time or not at all. (Select and order three.)
* Attach the IAM role to the Redshift cluster.
* Attach the IAM role to the Redshift namespace.
* Create an external database in Amazon Redshift to point to the Data Catalog schema.
* Create an external schema in Amazon Redshift to point to the Data Catalog database.
* Create an IAM role for Amazon Redshift to use to access only the S3 bucket that contains underlying data.
* Create an IAM role for Amazon Redshift to use to access the Data Catalog and the S3 bucket that contains underlying data.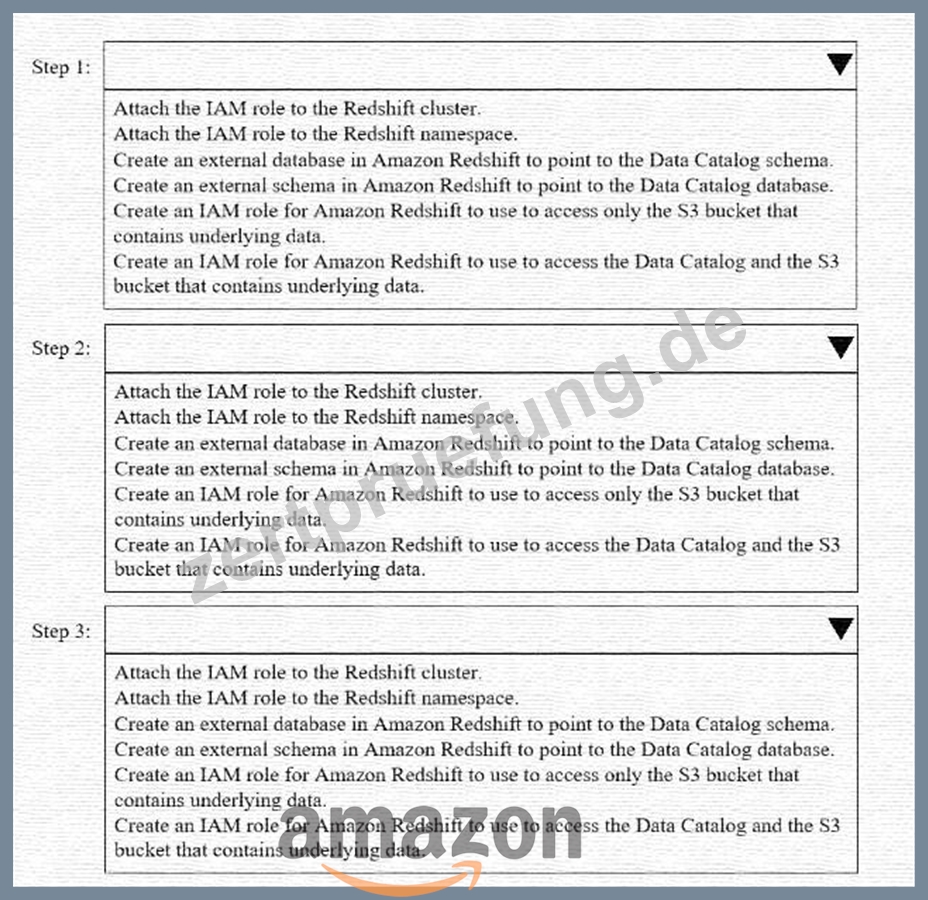
Antwort:
Begründung: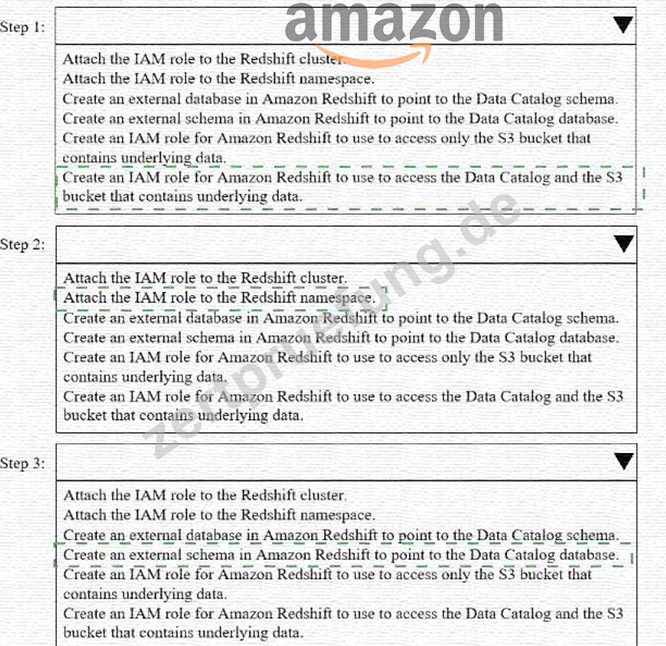
Explanation:
Step 1
Create an IAM role for Amazon Redshift to use to access the Data Catalog and the S3 bucket that contains underlying data.
This role must include:
* Permissions for AWS Glue Data Catalog (e.g., glue:GetDatabase, glue:GetTables)
* Permissions for the Amazon S3 bucket that stores the underlying data
Step 2
Attach the IAM role to the Redshift namespace.
Redshift Serverless uses a namespace, not a cluster, so the role must be associated with the namespace to allow Redshift to assume it when querying external data.
Step 3
Create an external schema in Amazon Redshift to point to the Data Catalog database.
The external schema maps Redshift to the Glue Data Catalog database so Redshift can query the tables stored in S3.
109. Frage
A company is using an Amazon Redshift database as its single data source. Some of the data is sensitive.
A data scientist needs to use some of the sensitive data from the database. An ML engineer must give the data scientist access to the data without transforming the source data and without storing anonymized data in the database.
Which solution will meet these requirements with the LEAST implementation effort?
Antwort: A
110. Frage
An ML engineer is deploying a generative AI model-based customer support agent that uses Amazon SageMaker AI for inference. The customer support agent must respond to customer questions about topics such as shipping policies, refund processes, and account management. The generative AI model generates one token at a time.
Customers report dissatisfaction with how long the customer support agent takes to generate lengthy responses to questions. The ML engineer must apply an inference optimization technique to improve the performance of the customer support agent.
Which solution will meet this requirement?
Antwort: A
Begründung:
Option B is correct because AWS documentation states that speculative decoding is specifically a technique to speed up the decoding process of large language models. The question highlights that the model generates one token at a time and that users are unhappy with the time needed to generate lengthy responses. That is exactly the stage of inference targeted by speculative decoding. AWS explains that this method improves latency without compromising the quality of the generated text.
According to AWS, speculative decoding works by using a smaller, faster draft model to generate candidate tokens first. The larger target model then verifies those tokens. AWS further explains that the draft model can generate multiple candidate tokens quickly, and the target model evaluates them in parallel, which speeds up the final response. This directly addresses the problem in the scenario: the customer support agent is slow not because of startup time, but because long answers require many decoding steps.
The other options are not the best fit. Compilation reduces deployment time and auto-scaling latency through ahead-of-time compilation, but AWS documents it primarily as helping model deployment and hardware optimization rather than token-by-token response generation. Quantization reduces hardware requirements and can lower cost, but the docs do not present it as the most direct answer to slow sequential decoding. Fast model loading improves how quickly the model loads onto instances, which helps startup and scale-out time, not long response generation after the model is already serving traffic. Therefore, the best AWS-documented answer is B.
111. Frage
A company has a conversational AI assistant that sends requests through Amazon Bedrock to an Anthropic Claude large language model (LLM). Users report that when they ask similar questions multiple times, they sometimes receive different answers. An ML engineer needs to improve the responses to be more consistent and less random.
Which solution will meet these requirements?
Antwort: B
Begründung:
Thetemperatureparameter controls the randomness in the model's responses. Lowering the temperature makes the model produce more deterministic and consistent answers.
Thetop_kparameter limits the number of tokens considered for generating the next word. Reducing top_k further constrains the model's options, ensuring more predictable responses.
By decreasing both parameters, the responses become more focused and consistent, reducing variability in similar queries.
112. Frage
A company has deployed an XGBoost prediction model in production to predict if a customer is likely to cancel a subscription. The company uses Amazon SageMaker Model Monitor to detect deviations in the F1 score.
During a baseline analysis of model quality, the company recorded a threshold for the F1 score.
After several months of no change, the model's F1 score decreases significantly.
What could be the reason for the reduced F1 score?
Antwort: C
113. Frage
......
Wenn Sie deprimiert sind, sollen Sie am besten etwas lernen. Lernen werden Sie unbesiegbar machen. Die Fragenkataloge zur Amazon MLA-C01 Zertifizierungsprüfung von Zertpruefung werden Sie sicher unbesiegbar machen. Mit diesen Fragenkataloge können Sie sicher das internationale akzeptierte Amazon MLA-C01 Zertifikat bekommen. Sie können deshalb viel Geld verdienen und Ihre Lebensumstände werden sicher gründlich verbessert. Werden Sie noch deprimiert? Nein, Sie werden sicher stolz darauf. Sie sollen Zertpruefung danken, die Ihnen so gute Fragenkataloge bietet. Zertpruefung hilft Ihnen, wenn Sie deprimiert sind. Er hilft Ihnen, Ihre Qualität zu verbessern und Ihren perfekten Lebenswert zu repräsentieren.
MLA-C01 Vorbereitungsfragen: https://www.zertpruefung.de/MLA-C01_exam.html
Laden Sie die neuesten Zertpruefung MLA-C01 PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1X5UKX49sD0z2kF4vIjGhZ-66qKt0Ij98