Certification Certified-Data-Engineer-Professional Exam, Valid Certified-Data-Engineer-Professional Torrent

Some practice materials keep droning on the useless points of knowledge. In contrast, being venerated for high quality and accuracy rate, our Certified-Data-Engineer-Professional training quiz received high reputation for their efficiency and accuracy rate originating from your interests, and the whole review process may cushier than you have imagined before. Numerous of our loyal customers wrote to us to praise that the Certified-Data-Engineer-Professional Exam Questions are the same with the real exam questions and they passed Certified-Data-Engineer-Professional exam with ease.
| Section | Objectives |
|---|
| Topic 1: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Topic 2: Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
- Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
|
| Topic 3: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Topic 4: Data Modeling | - Design and optimize data models
- 1. Design dimensional models for analytical workloads with efficient querying and aggregation
- 2. Simplify data layout decisions and optimize query performance using liquid clustering
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Identify the benefits of liquid clustering over partitioning and Z-Ordering
|
| Topic 5: Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Topic 6: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Topic 7: Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 2. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 3. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 4. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 5. Create pipeline components using control flow operators such as if/else and foreach
- 6. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 7. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 8. Explain the advantages and disadvantages of streaming tables compared to materialized views
- Using Python and Tools for Development
- 1. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
|
| Topic 8: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 2. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 3. Apply Change Data Feed to address streaming table limitations and improve latency
- 4. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 5. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
|
| Topic 9: Monitoring and Alerting | - Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
- Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Query Profile and Spark UI to monitor workloads
|
| Topic 10: Data Sharing and Federation | - Share and federate data
- 1. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
>> Certification Certified-Data-Engineer-Professional Exam <<
Valid Certified-Data-Engineer-Professional Torrent & Valid Dumps Certified-Data-Engineer-Professional Free
Facts proved that if you do not have the certification, you will be washed out by the society. So it is very necessary for you to try your best to get the Certified-Data-Engineer-Professional certification in a short time. It is known to us that getting the Certified-Data-Engineer-Professional certification has become more and more popular for a lot of people in different area, including students, teachers, and housewife and so on. Everyone is desired to have the certification. Because The Certified-Data-Engineer-Professional Certification can bring a lot of benefits for people, including money, a better job and social status and so on.
Databricks Certified Data Engineer Professional Sample Questions (Q16-Q21):
NEW QUESTION # 16
The data engineering team is migrating an enterprise system with thousands of tables and views into the Lakehouse. They plan to implement the target architecture using a series of bronze, silver, and gold tables. Bronze tables will almost exclusively be used by production data engineering workloads, while silver tables will be used to support both data engineering and machine learning workloads. Gold tables will largely serve business intelligence and reporting purposes. While personal identifying information (PII) exists in all tiers of data, pseudonymization and anonymization rules are in place for all data at the silver and gold levels.
The organization is interested in reducing security concerns while maximizing the ability to collaborate across diverse teams.
Which statement exemplifies best practices for implementing this system?
- A. Working in the default Databricks database provides the greatest security when working with managed tables, as these will be created in the DBFS root.
- B. Because all tables must live in the same storage containers used for the database they're created in, organizations should be prepared to create between dozens and thousands of databases depending on their data isolation requirements.
- C. Because databases on Databricks are merely a logical construct, choices around database organization do not impact security or discoverability in the Lakehouse.
- D. Isolating tables in separate databases based on data quality tiers allows for easy permissions management through database ACLs and allows physical separation of default storage locations for managed tables.
- E. Storinq all production tables in a single database provides a unified view of all data assets available throughout the Lakehouse, simplifying discoverability by granting all users view privileges on this database.
Answer: D
Explanation:
This is the correct answer because it exemplifies best practices for implementing this system. By isolating tables in separate databases based on data quality tiers, such as bronze, silver, and gold, the data engineering team can achieve several benefits. First, they can easily manage permissions for different users and groups through database ACLs, which allow granting or revoking access to databases, tables, or views. Second, they can physically separate the default storage locations for managed tables in each database, which can improve performance and reduce costs. Third, they can provide a clear and consistent naming convention for the tables in each database, which can improve discoverability and usability.
NEW QUESTION # 17
The data engineer is using Spark's MEMORY_ONLY storage level. Which indicators should the data engineer look for in the spark UI's Storage tab to signal that a cached table is not performing optimally?
- A. The RDD Block Name included the '' annotation signaling failure to cache
- B. On Heap Memory Usage is within 75% of off Heap Memory usage
- C. Size on Disk is> 0
- D. The number of Cached Partitions> the number of Spark Partitions
- E. Size on Disk is < Size in Memory
Answer: C
Explanation:
When using Spark's MEMORY_ONLY storage level, the ideal scenario is that the data is fully cached in memory, and the Size on Disk should be 0 (indicating that the data is not spilled to disk). If the Size on Disk is greater than 0, it suggests that some data has been spilled to disk, which can lead to degraded performance as reading from disk is slower than reading from memory.
NEW QUESTION # 18
An external object storage container has been mounted to the location /mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team:
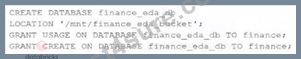
After the database was successfully created and permissions configured, a member of the finance team runs the following code:
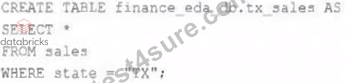
If all users on the finance team are members of the finance group, which statement describes how the tx_sales table will be created?
- A. An managed table will be created in the storage container mounted to /mnt/finance_eda_bucket.
- B. A logical table will persist the query plan to the Hive Metastore in the Databricks control plane.
- C. A logical table will persist the physical plan to the Hive Metastore in the Databricks control plane.
- D. An external table will be created in the storage container mounted to /mnt/finance eda bucket.
- E. A managed table will be created in the DBFS root storage container.
Answer: A
Explanation:
https://docs.databricks.com/en/data-governance/unity-catalog/create-schemas.html#language-SQL
NEW QUESTION # 19
A DLT pipeline includes the following streaming tables:
Raw_lot ingest raw device measurement data from a heart rate tracking device.
Bpm_stats incrementally computes user statistics based on BPM measurements from raw_lot.
How can the data engineer configure this pipeline to be able to retain manually deleted or updated records in the raw_iot table while recomputing the downstream table when a pipeline update is run?
- A. Set the pipelines, reset, allowed property to false on raw_iot
- B. Set the SkipChangeCommits flag to true raw_lot
- C. Set the pipelines, reset, allowed property to false on bpm_stats
- D. Set the skipChangeCommits flag to true on bpm_stats
Answer: A
Explanation:
In Databricks Lakehouse, to retain manually deleted or updated records in the raw_iot table while recomputing downstream tables when a pipeline update is run, the property pipelines.reset.allowed should be set to false. This property prevents the system from resetting the state of the table, which includes the removal of the history of changes, during a pipeline update. By keeping this property as false, any changes to the raw_iot table, including manual deletes or updates, are retained, and recomputation of downstream tables, such as bpm_stats, can occur with the full history of data changes intact.
NEW QUESTION # 20
A data engineering team has a time-consuming data ingestion job with three data sources. Each notebook takes about one hour to load new data. One day, the job fails because a notebook update introduced a new required configuration parameter. The team must quickly fix the issue and load the latest data from the failing source. Which action should the team take?
- A. Repair the run with the new parameter, and update the task by adding the missing task parameter.
- B. Share the analysis with the failing notebook owner so that they can fix it quickly.
- C. Update the task by adding the missing task parameter, and manually run the job.
- D. Repair the run with the new parameter.
Answer: A
Explanation:
The repair run capability in Databricks Jobs allows re-execution of failed tasks without re-running successful ones. When a parameterized job fails due to missing or incorrect task configuration, engineers can perform a repair run to fix inputs or parameters and resume from the failed state.
This approach saves time, reduces cost, and ensures workflow continuity by avoiding unnecessary recomputation. Additionally, updating the task definition with the missing parameter prevents future runs from failing.
Running the job manually (B) loses run context; (C) alone does not prevent recurrence; (D) delays resolution. Thus, A follows the correct operational and recovery practice.
NEW QUESTION # 21
......
Our Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice exam can be modified in terms of length of time and number of questions to help you prepare for the Databricks real test. We're certain that our Certified-Data-Engineer-Professional Questions are quite similar to those on Certified-Data-Engineer-Professional real exam since we regularly update and refine the product based on the latest exam content.
Valid Certified-Data-Engineer-Professional Torrent: https://www.test4sure.com/Certified-Data-Engineer-Professional-pass4sure-vce.html
- New Databricks Certified-Data-Engineer-Professional Practice Test - Get Ready With Certified-Data-Engineer-Professional Exam Dumps [2026] 💦 Search for ➤ Certified-Data-Engineer-Professional ⮘ and download it for free on ☀ www.prep4away.com ️☀️ website 🦃Certified-Data-Engineer-Professional Interactive Questions
- Unparalleled Certification Certified-Data-Engineer-Professional Exam - Pass Certified-Data-Engineer-Professional Exam 🟢 Simply search for ▶ Certified-Data-Engineer-Professional ◀ for free download on ✔ www.pdfvce.com ️✔️ 🌖Real Certified-Data-Engineer-Professional Question
- Monitor Your Progress with Certified-Data-Engineer-Professional Practice Test Software 💠 Immediately open 【 www.examdiscuss.com 】 and search for ▶ Certified-Data-Engineer-Professional ◀ to obtain a free download 🕋Detail Certified-Data-Engineer-Professional Explanation
- Test Certified-Data-Engineer-Professional Dates 🏯 New Certified-Data-Engineer-Professional Test Materials 🚞 Certified-Data-Engineer-Professional Pass Guaranteed 🛒 Enter ⇛ www.pdfvce.com ⇚ and search for 《 Certified-Data-Engineer-Professional 》 to download for free 🗣Certified-Data-Engineer-Professional Actual Exam Dumps
- Pursue Certifications Certified-Data-Engineer-Professional Certification Exam Exam Questions 🎦 Open ➤ www.prep4sures.top ⮘ enter ☀ Certified-Data-Engineer-Professional ️☀️ and obtain a free download 😂Certified-Data-Engineer-Professional Interactive Questions
- Certified-Data-Engineer-Professional Certification Exam Cost 🕍 Certified-Data-Engineer-Professional Clearer Explanation 🕞 Certified-Data-Engineer-Professional Clearer Explanation 🐉 Copy URL 《 www.pdfvce.com 》 open and search for ➥ Certified-Data-Engineer-Professional 🡄 to download for free 🕕Test Certified-Data-Engineer-Professional Dates
- New Databricks Certified-Data-Engineer-Professional Practice Test - Get Ready With Certified-Data-Engineer-Professional Exam Dumps [2026] 🏛 Search for ✔ Certified-Data-Engineer-Professional ️✔️ and easily obtain a free download on ⮆ www.prepawaypdf.com ⮄ 🌌Test Certified-Data-Engineer-Professional Dates
- 100% Pass Quiz 2026 Databricks Certified-Data-Engineer-Professional – High Hit-Rate Certification Exam 🚋 Immediately open { www.pdfvce.com } and search for ( Certified-Data-Engineer-Professional ) to obtain a free download 🔔Certified-Data-Engineer-Professional Download Pdf
- Real Certified-Data-Engineer-Professional Question 🏈 Test Certified-Data-Engineer-Professional Dates 🍐 Certified-Data-Engineer-Professional Practice Exams Free 👄 Search on 「 www.troytecdumps.com 」 for ➠ Certified-Data-Engineer-Professional 🠰 to obtain exam materials for free download 🧟Certified-Data-Engineer-Professional Clearer Explanation
- Quiz 2026 Databricks Certified-Data-Engineer-Professional: Reliable Certification Databricks Certified Data Engineer Professional Exam 🌜 Search for ➤ Certified-Data-Engineer-Professional ⮘ and obtain a free download on ➽ www.pdfvce.com 🢪 💱Certified-Data-Engineer-Professional Download Pdf
- Certified-Data-Engineer-Professional Latest Exam Fee ⏭ Reliable Certified-Data-Engineer-Professional Test Pass4sure 🆗 Guide Certified-Data-Engineer-Professional Torrent 🧢 Enter ✔ www.dumpsmaterials.com ️✔️ and search for ➡ Certified-Data-Engineer-Professional ️⬅️ to download for free ✉Certified-Data-Engineer-Professional Exam Prep
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.prodesigns.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes