BTW, DOWNLOAD part of PassReview Databricks-Certified-Data-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1OVTrddFt1oOdUQ7Mii3wGBsk_uyoaVP5
Having more competitive advantage means that you will have more opportunities and have a job that will satisfy you. This is why more and more people have long been eager for the certification of Databricks-Certified-Data-Engineer-Associate. There is no doubt that obtaining this Databricks-Certified-Data-Engineer-Associate certification is recognition of their ability so that they can find a better job and gain the social status that they want. Most people are worried that it is not easy to obtain the certification of Databricks-Certified-Data-Engineer-Associate, so they dare not choose to start. We are willing to appease your troubles and comfort you. We are convinced that our Databricks-Certified-Data-Engineer-Associate test material can help you solve your problems. Compared to other learning materials, our products are of higher quality and can give you access to the Databricks-Certified-Data-Engineer-Associate certification that you have always dreamed of. Now let me introduce our Databricks-Certified-Data-Engineer-Associate test questions for you. I will show you our study materials.
Databricks Certified Data Engineer Associate exam consists of 60 multiple-choice questions that must be completed within 90 minutes. Candidates are required to score at least 70% to pass the exam. Databricks-Certified-Data-Engineer-Associate Exam is administered online through the GAQM testing platform, which allows candidates to take the exam from anywhere in the world.
Databricks Certified Data Engineer Associate Exam covers a wide range of topics, including data ingestion, data transformation, data storage, data processing, and data analysis. It is designed to test the candidate's ability to work with a variety of data sources and formats, including structured, semi-structured, and unstructured data. It also tests the candidate's knowledge of data engineering best practices, such as data quality, data governance, and data security.
>> Databricks-Certified-Data-Engineer-Associate Reliable Test Duration <<
Our Databricks-Certified-Data-Engineer-Associate practice dumps is high quality product revised by hundreds of experts according to the changes in the syllabus and the latest developments in theory and practice, it is focused and well-targeted, so that each student can complete the learning of important content in the shortest time. With Databricks-Certified-Data-Engineer-Associate training prep, you only need to spend 20 to 30 hours of practice before you take the Databricks-Certified-Data-Engineer-Associate exam.
The Databricks Certified Data Engineer Associate Exam certification exam focuses on various topics related to data engineering, including data ingestion, data processing, data warehousing, and data analytics. It also covers the fundamentals of big data processing and distributed computing, making it an ideal certification for professionals who want to work with large-scale data sets.
NEW QUESTION # 265
Which of the following describes a scenario in which a data engineer will want to use a single-node cluster?
Answer: C
Explanation:
The scenario in which a data engineer will want to use a single-node cluster is when they are working interactively with a small amount of data. A single-node cluster is a cluster consisting of an Apache Spark driver and no Spark workers1. A single-node cluster supports Spark jobs and all Spark data sources, including Delta Lake1. A single-node cluster is helpful for single-node machine learning workloads that use Spark to load and save data, and for lightweight exploratory data analysis1. A single-node cluster can run Spark locally, spawn one executor thread per logical core in the cluster, and save all log output in the driver log1. A single-node cluster can be created by selecting the Single Node button when configuring a cluster1.
The other options are not suitable for using a single-node cluster. When running automated reports to be refreshed as quickly as possible, a data engineer will want to use a multi-node cluster that can scale up and down automatically based on the workload demand2. When working with SQL within Databricks SQL, a data engineer will want to use a SQL Endpoint that can execute SQL queries on a serverless pool or an existing cluster3. When concerned about the ability to automatically scale with larger data, a data engineer will want to use a multi-node cluster that can leverage the Databricks Lakehouse Platform and the Delta Engine to handle large-scale data processing efficiently and reliably4. When manually running reports with a large amount of data, a data engineer will want to use a multi-node cluster that can distribute the computation across multiple workers and leverage the Spark UI to monitor the performance and troubleshoot the issues.
Reference:
1: Single Node clusters | Databricks on AWS
2: Autoscaling | Databricks on AWS
3: SQL Endpoints | Databricks on AWS
4: Databricks Lakehouse Platform | Databricks on AWS
5: [Spark UI | Databricks on AWS]
NEW QUESTION # 266
A data engineer has written a function in a Databricks Notebook to calculate the population of bacteria in a given medium.
Analysts use this function in the notebook and sometimes provide input arguments of the wrong data type, which can cause errors during execution.
Which Databricks feature will help the data engineer quickly identify if an incorrect data type has been provided as input?
Answer: B
NEW QUESTION # 267
A data engineering team has noticed that their Databricks SQL queries are running too slowly when they are submitted to a non-running SQL endpoint. The data engineering team wants this issue to be resolved.
Which of the following approaches can the team use to reduce the time it takes to return results in this scenario?
Answer: E
Explanation:
Option D is the correct answer because it enables the Serverless feature for the SQL endpoint, which allows the endpoint to automatically scale up and down based on the query load. This way, the endpoint can handle more concurrent queries and reduce the time it takes to return results. The Serverless feature also reduces the cold start time of the endpoint, which is the time it takes to start the cluster when a query is submitted to a non- running endpoint. The Serverless feature is available for both AWS and Azure Databricks platforms.
Databricks SQL Serverless, Serverless SQL endpoints, New Performance Improvements in Databricks SQL
NEW QUESTION # 268
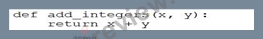
A data engineer that is new to using Python needs to create a Python function to add two integers together and return the sum?
Which of the following code blocks can the data engineer use to complete this task?
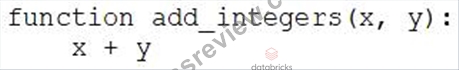
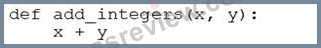
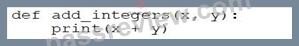
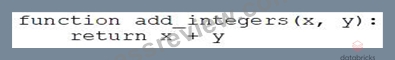
Answer: E
Explanation:
https://www.w3schools.com/python/python_functions.asp
https://www.geeksforgeeks.org/python-functions/
NEW QUESTION # 269
Which of the following describes the storage organization of a Delta table?
Answer: C
Explanation:
Explanation
Delta tables store data in a structured manner using Parquet files, and they also maintain metadata and transaction logs in separate directories. This organization allows for versioning, transactional capabilities, and metadata tracking in Delta Lake. Thank you for pointing out the error, and I appreciate your understanding.
NEW QUESTION # 270
......
Test Databricks-Certified-Data-Engineer-Associate Question: https://www.passreview.com/Databricks-Certified-Data-Engineer-Associate_exam-braindumps.html
BTW, DOWNLOAD part of PassReview Databricks-Certified-Data-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1OVTrddFt1oOdUQ7Mii3wGBsk_uyoaVP5