Professional New Databricks-Machine-Learning-Professional Test Tips–100% High Pass-Rate Latest Databricks Certified Machine Learning Professional Exam Objectives

DOWNLOAD the newest ExamcollectionPass Databricks-Machine-Learning-Professional PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=15MmoIiHca5pEs8iIOIHXr9NjSqJhqVV7
There is no denying the fact that everyone in the world wants to find a better job to improve the quality of life. Generally speaking, these jobs are offered only by some well-known companies. In order to enter these famous companies, we must try our best to get some certificates as proof of our ability such as the Databricks-Machine-Learning-Professional Certification. Nowadays, the Databricks-Machine-Learning-Professional certification has been one of the criteria for many companies to recruit employees. And in order to obtain the Databricks-Machine-Learning-Professional certification, taking the Databricks-Machine-Learning-Professional exam becomes essential.
| Topic | Details |
|---|
| Topic 1 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
| Topic 2 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Topic 3 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Topic 4 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
| Topic 5 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| Topic 6 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Topic 7 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| Topic 8 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
| Topic 9 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Topic 10 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Topic 11 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
>> New Databricks-Machine-Learning-Professional Test Tips <<
Use Databricks-Machine-Learning-Professional Exam Questions - Best Way To Get Success
If you prefer to practice Databricks-Machine-Learning-Professional questions and answers on paper, then our Databricks-Machine-Learning-Professional exam dumps are your best choice. Databricks-Machine-Learning-Professional PDF version is printable, and you can print them into a hard one and take notes on them, and you can take them with you. Databricks-Machine-Learning-Professional exam bootcamp offers you free demo for you to have a try before buying, so that you can have a better understanding of what you are going to buy. Databricks-Machine-Learning-Professional Exam Materials contain both questions and answers, and you can have a convenient check after practicing.
Databricks Certified Machine Learning Professional Sample Questions (Q182-Q187):
NEW QUESTION # 182
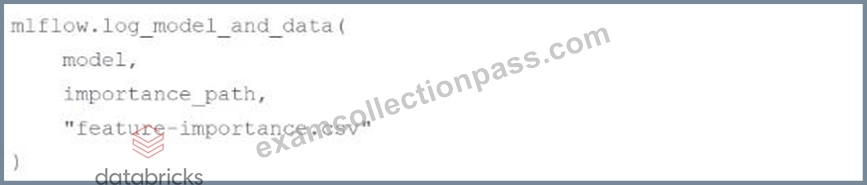
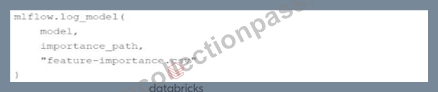
A machine learning engineer wants to log feature importance data from a CSV file at path importance_path with an MLflow run for model model.
Which of the following code blocks will accomplish this task inside of an existing MLflow run block?
A)
B)
C) mlflow.log_data(importance_path, "feature-importance.csv")
D) mlflow.log_artifact(importance_path, "feature-importance.csv")
E) None of these code blocks tan accomplish the task.
- A. Option C
- B. Option A
- C. Option E
- D. Option D
- E. Option B
Answer: B
NEW QUESTION # 183
A data scientist would like to enable MLflow Autologging for all machine learning libraries used in a notebook. They want to ensure that MLflow Autologging is used no matter what version of the Databricks Runtime for Machine Learning is used to run the notebook and no matter what workspace-wide configurations are selected in the Admin Console. Which of the following lines of code can they use to accomplish this task?
- A. mlflow.spark.autolog()
- B. mlflow.sklearn.autolog()
- C. It is not possible to automatically log MLflow runs.
- D. spark.conf.set("autologging", True)
- E. mlflow.autolog()
Answer: D
NEW QUESTION # 184
A Machine Learning Engineer needs a continuous deployment pipeline for their models hosted on Databricks Model Serving. The deployment automation should execute after a model is trained and registered using MLflow. The goal of the automation is to deploy the latest version of the model from the MLflow Model Registry only if the model can meet the company's strict latency requirements (P95 < 300ms) while serving production traffic. How can the engineer validate that new models meet their latency requirements when served in production?
- A. Serve the latest model on Databricks Model Serving and use a load testing client to generate requests at the production request rate. Use the load testing client to calculate P95 latency and verify it is less than 300ms.
- B. A/B test the latest model with Databricks Model Serving so that the latest model receives 5% of production traffic and the current model receives the rest. Use inference tables to calculate P95 latency and verify it is less than 300ms.
- C. Use the MLflow Get Run API to retrieve the model metrics from MLflow Tracking and verify that the model_latency metric is less than 300ms.
- D. Use the MLflow Get Run API to retrieve the model metrics from MLflow Tracking and verify that the inference_latency metric is less than 300ms.
Answer: B
Explanation:
Validating latency requirements must be done under real production serving conditions. Routing a small percentage of live production traffic to the new model using Databricks Model Serving allows accurate measurement of end-to-end serving latency. Inference tables capture request latency metrics, enabling calculation of the P95 latency and ensuring it meets the strict production threshold before full rollout.
NEW QUESTION # 185
Which of the following is an obstacle related to streaming machine learning applications?
- A. None of these
- B. End-to-end fault tolerance
- C. Out-of-order data
- D. All of these
Answer: D
Explanation:
Streaming machine learning applications face multiple challenges, including end-to-end fault tolerance (ensuring recovery from failures without data loss) and out-of-order data (handling events that arrive late or out of sequence). Both are common obstacles in building reliable real- time ML systems.
NEW QUESTION # 186
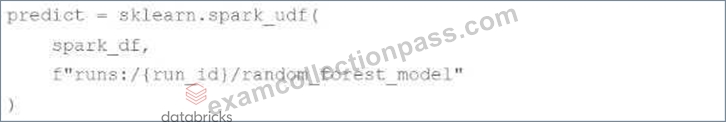
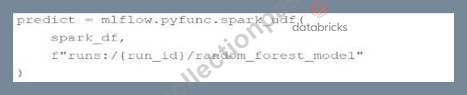
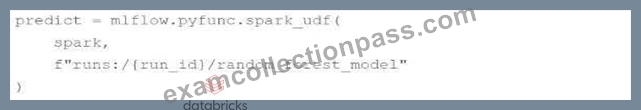
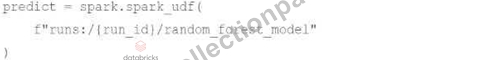
A machine learning engineer has developed a random forest model using scikit-learn, logged the model using MLflow as random_forest_model, and stored its run ID in the run_id Python variable.
They now want to deploy that model by performing batch inference on a Spark DataFrame spark_df. Which of the following code blocks can they use to create a function called predict that they can use to complete the task?
- A.
- B.
- C.
- D. It is not possible to deploy a scikit-learn model on a Spark DataFrame.
- E.
Answer: E
NEW QUESTION # 187
......
You will become accustomed to and familiar with the free demo for Databricks Databricks-Machine-Learning-Professional Exam Questions. Exam self-evaluation techniques in our Databricks-Machine-Learning-Professional desktop-based software include randomized questions and timed tests. These tools assist you in assessing your ability and identifying areas for improvement to pass the Databricks Databricks Certified Machine Learning Professional exam.
Latest Databricks-Machine-Learning-Professional Exam Objectives: https://www.examcollectionpass.com/Databricks/Databricks-Machine-Learning-Professional-practice-exam-dumps.html
- Customized Databricks-Machine-Learning-Professional Lab Simulation ➰ VCE Databricks-Machine-Learning-Professional Dumps 🦙 Databricks-Machine-Learning-Professional Test Dumps.zip 😿 Easily obtain free download of ➽ Databricks-Machine-Learning-Professional 🢪 by searching on ➤ www.pass4test.com ⮘ 🏛Databricks-Machine-Learning-Professional Pass4sure Exam Prep
- Reliable Databricks-Machine-Learning-Professional Exam Dumps 🤢 Databricks-Machine-Learning-Professional Test Torrent 🤢 Databricks-Machine-Learning-Professional New Practice Materials 🙄 Search for ( Databricks-Machine-Learning-Professional ) on ➥ www.pdfvce.com 🡄 immediately to obtain a free download 🥋Practice Databricks-Machine-Learning-Professional Mock
- New Databricks-Machine-Learning-Professional Exam Test 🐳 Databricks-Machine-Learning-Professional Pass4sure Exam Prep 🥗 Reliable Databricks-Machine-Learning-Professional Exam Dumps 📔 Open ➡ www.exam4labs.com ️⬅️ enter ( Databricks-Machine-Learning-Professional ) and obtain a free download ✅Databricks-Machine-Learning-Professional Valid Braindumps
- Get Real And Easy-to-Use Databricks Databricks-Machine-Learning-Professional Dumps PDF Format 🧎 Search for 【 Databricks-Machine-Learning-Professional 】 on ▛ www.pdfvce.com ▟ immediately to obtain a free download 🚔Reliable Databricks-Machine-Learning-Professional Exam Dumps
- Databricks-Machine-Learning-Professional 100% Exam Coverage 🍲 Free Databricks-Machine-Learning-Professional Test Questions 🅿 Test Databricks-Machine-Learning-Professional Guide Online 🤴 Open website 「 www.torrentvce.com 」 and search for ➠ Databricks-Machine-Learning-Professional 🠰 for free download 🎣Free Databricks-Machine-Learning-Professional Test Questions
- Get Real And Easy-to-Use Databricks Databricks-Machine-Learning-Professional Dumps PDF Format 😕 Easily obtain free download of ☀ Databricks-Machine-Learning-Professional ️☀️ by searching on ☀ www.pdfvce.com ️☀️ ❇Databricks-Machine-Learning-Professional 100% Exam Coverage
- Detailed Databricks-Machine-Learning-Professional Study Plan 🍬 New Databricks-Machine-Learning-Professional Exam Test 🚒 Databricks-Machine-Learning-Professional Book Free 🎮 Copy URL ➠ www.dumpsmaterials.com 🠰 open and search for [ Databricks-Machine-Learning-Professional ] to download for free ‼VCE Databricks-Machine-Learning-Professional Dumps
- Test Databricks-Machine-Learning-Professional Guide Online 🙊 Databricks-Machine-Learning-Professional Test Torrent 🌍 New Databricks-Machine-Learning-Professional Exam Test 🎻 Copy URL [ www.pdfvce.com ] open and search for ▷ Databricks-Machine-Learning-Professional ◁ to download for free 👞VCE Databricks-Machine-Learning-Professional Dumps
- Databricks-Machine-Learning-Professional Pass4sure Exam Prep 🧡 Databricks-Machine-Learning-Professional Reliable Exam Pattern 🗾 Databricks-Machine-Learning-Professional New Practice Materials ⛑ Open website { www.torrentvce.com } and search for ( Databricks-Machine-Learning-Professional ) for free download 👏VCE Databricks-Machine-Learning-Professional Dumps
- Pass-Sure New Databricks-Machine-Learning-Professional Test Tips – Pass Databricks-Machine-Learning-Professional First Attempt 🌾 Search for ➠ Databricks-Machine-Learning-Professional 🠰 and download exam materials for free through ➠ www.pdfvce.com 🠰 🖌Databricks-Machine-Learning-Professional Pass4sure Exam Prep
- Databricks-Machine-Learning-Professional Test Torrent 🏥 Databricks-Machine-Learning-Professional Test Torrent 🎲 VCE Databricks-Machine-Learning-Professional Dumps 🤽 Search for ⇛ Databricks-Machine-Learning-Professional ⇚ and easily obtain a free download on [ www.easy4engine.com ] 🧆Test Databricks-Machine-Learning-Professional Guide Online
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
What's more, part of that ExamcollectionPass Databricks-Machine-Learning-Professional dumps now are free: https://drive.google.com/open?id=15MmoIiHca5pEs8iIOIHXr9NjSqJhqVV7