Databricks Databricks-Certified-Data-Engineer-Professional絶対合格、Databricks-Certified-Data-Engineer-Professional合格体験談

P.S. CertJukenがGoogle Driveで共有している無料かつ新しいDatabricks-Certified-Data-Engineer-Professionalダンプ:https://drive.google.com/open?id=1_N1nTs55mc7TGTz8s04aRNoOA0aPyrCM
Databricks-Certified-Data-Engineer-Professional試験参考書を購入すると、完璧なアフターサービスと高品質なを楽しむことができます。だから、あなたは私たちのDatabricks-Certified-Data-Engineer-Professional試験参考書から、驚きを得ることができると信じています。また、あなたがDatabricks-Certified-Data-Engineer-Professional試験参考書の費用を支払う前にサービスを楽しむことができるだけでなく、購入後1年間無料でDatabricks-Certified-Data-Engineer-Professional試験参考書の更新版を楽しむこともできます。
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Data Modeling and Storage | 20% | - Storage Optimization
- File Formats
- Data Modeling
|
| Databricks Lakehouse Platform | 24% | - Delta Lake
- Data Management
- Unity Catalog
- Lakehouse Architecture
|
| Monitoring and Troubleshooting | 16% | - Troubleshooting
- Performance Optimization
- Monitoring
|
| Data Quality and Governance | 12% | - Data Lineage
- Governance
- Data Quality
|
| Data Processing | 28% | - Structured Streaming
- Spark SQL
- Data Transformation
- ETL Pipelines
|
>> Databricks Databricks-Certified-Data-Engineer-Professional絶対合格 <<
Databricks-Certified-Data-Engineer-Professional合格体験談、Databricks-Certified-Data-Engineer-Professional日本語版問題解説
質問と回答のみを提供するPDFバージョンの機能に満足できない場合は、Databricks-Certified-Data-Engineer-Professional試験の教材のAPPバージョンでさらに多くを提供できます。 APPバージョンは、実際のテストシーンをシミュレートするだけでなく、間違いを指摘し、何度も練習することに気付くことができます。 Databricks Databricks-Certified-Data-Engineer-Professional試験の教材のこのバージョンはかなり強力です。 あなたが喜んでいるなら、あなたは毎日あなたのパフォーマンスをマークし、比較的あなたの勉強と準備を調整することができます。 Databricks-Certified-Data-Engineer-Professional試験の教材は、お客様の要求を満たすために最善を尽くします。
Databricks Certified Data Engineer Professional Exam 認定 Databricks-Certified-Data-Engineer-Professional 試験問題 (Q24-Q29):
質問 # 24
A data engineer is reviewing the PySpark code to copy a part of the production dataset to the sandbox environment, and needs to be sure that no PII(Personally Identifiable Information) data is being copied. After checking the sales table, the data engineer notices that it has user emails as the only PII data included as well as being the only column to identify the user.
from pyspark.sql import functions as F
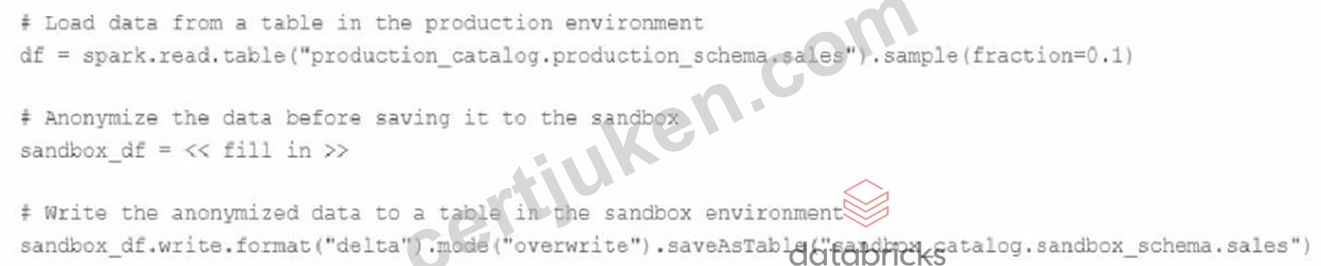
Which anonymised code should be used to achieve the required outcome?
- A. df.withColumn ("hashed_email", sha2 ("user_email"))
- B. df.withColumn ("user_email", F.regexp_replace ("user_eamail", "@*", "@anonymized.com"))
- C. df.withColumn ("user_email", F.sha2 ("user_email"))
- D. df.withColumn ("user_emai", F.expr("uuid()"))
正解:C
解説:
Hashing the email column replaces the original PII with a deterministic, irreversible value while preserving its role as a unique identifier. This ensures no actual email addresses are copied to the sandbox environment, while still allowing consistent joins or user-level analysis if needed.
質問 # 25
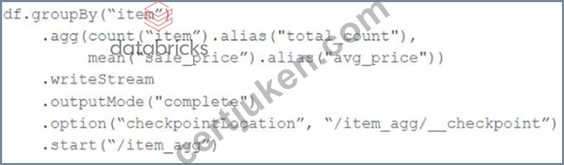
A data team's Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.
Original query:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
Proposed query:
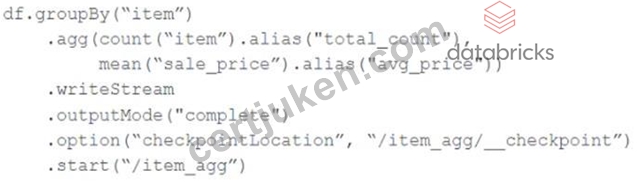
Proposed query:
.start("/item_agg")
Which step must also be completed to put the proposed query into production?
- A. Specify a new checkpointlocation
- B. Increase the shuffle partitions to account for additional aggregates
- C. Run REFRESH TABLE delta, /item_agg'
- D. Remove .option (mergeSchema', true') from the streaming write
- E. Register the data in the "/item_agg" directory to the Hive metastore
正解:A
解説:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
質問 # 26
An upstream source writes Parquet data as hourly batches to directories named with the current date. A nightly batch job runs the following code to ingest all data from the previous day as indicated by the date variable:
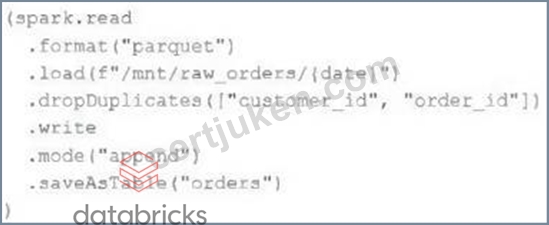
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order.
If the upstream system is known to occasionally produce duplicate entries for a single order hours apart, which statement is correct?
- A. Each write to the orders table will only contain unique records, but newly written records may have duplicates already present in the target table.
- B. Each write to the orders table will run deduplication over the union of new and existing records, ensuring no duplicate records are present.
- C. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, the operation will tail.
- D. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, these records will be overwritten.
- E. Each write to the orders table will only contain unique records, and only those records without duplicates in the target table will be written.
正解:A
解説:
This is the correct answer because the code uses the dropDuplicates method to remove any duplicate records within each batch of data before writing to the orders table. However, this method does not check for duplicates across different batches or in the target table, so it is possible that newly written records may have duplicates already present in the target table. To avoid this, a better approach would be to use Delta Lake and perform an upsert operation using mergeInto.
質問 # 27
A data engineer is using Auto Loader to read incoming JSON data as it arrives. They have configured Auto Loader to quarantine invalid JSON records but notice that over time, some records are being quarantined even though they are well-formed JSON.
The code snippet is:
df = (spark.readStream
.format("cloudFiles")
.option("cloudFiles.format", "json")
.option("badRecordsPath", "/tmp/somewhere/badRecordsPath")
.schema("a int, b int")
.load("/Volumes/catalog/schema/raw_data/"))
What is the cause of the missing data?
- A. The engineer forgot to set the option "cloudFiles.quarantineMode" = "rescue".
- B. The source data is valid JSON but does not conform to the defined schema in some way.
- C. At some point, the upstream data provider switched everything to multi-line JSON.
- D. The badRecordsPath location is accumulating many small files.
正解:B
解説:
Auto Loader quarantines records that cannot be parsed according to the specified schema, even if the JSON itself is well formed. If incoming records contain additional fields, missing fields, or incompatible data types compared to the declared schema, they are treated as invalid and routed to the bad records path.
質問 # 28
A company stores account transactions in a Delta Lake table. The company needs to apply frequent account-level correlations (e.g., UPDATE statements) but wants to avoid rewriting entire Parquet files for each change to reduce file churn and improve write performance. Which Delta Lake feature should they enable?
- A. Enable deletion vectors on the Delta table
- B. Enable automatic file compaction on writes
- C. Partition the Delta table by account_id
- D. Enable change data feed on the Delta table
正解:A
解説:
Deletion vectors allow Delta Lake to track row-level deletes and updates without rewriting entire Parquet files. By recording changes separately from the base files, this feature significantly reduces file churn and improves write performance for workloads with frequent row-level modifications such as account-level updates.
質問 # 29
......
CertJukenは成立以来、ますます完全的な体系、もっと豊富な問題集、より安全的な支払保障、よりよいサービスを持っています。現在提供するDatabricksのDatabricks-Certified-Data-Engineer-Professional試験の資料は多くのお客様に認可されました。ご購入のあとで我々はアフターサービスを提供します。あなたにDatabricksのDatabricks-Certified-Data-Engineer-Professional試験のソフトの更新情況を了解させます。あなたは不幸で試験に失敗したら、我々は全額で返金します。
Databricks-Certified-Data-Engineer-Professional合格体験談: https://www.certjuken.com/Databricks-Certified-Data-Engineer-Professional-exam.html
- 一番優秀なDatabricks-Certified-Data-Engineer-Professional絶対合格 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional合格体験談 | 検証するDatabricks-Certified-Data-Engineer-Professional日本語版問題解説 😯 ⮆ www.shikenpass.com ⮄を開き、【 Databricks-Certified-Data-Engineer-Professional 】を入力して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professionalウェブトレーニング
- Databricks-Certified-Data-Engineer-Professional最新知識 🦈 Databricks-Certified-Data-Engineer-Professional受験記対策 🔎 Databricks-Certified-Data-Engineer-Professional学習体験談 🟠 今すぐ➠ www.goshiken.com 🠰で▛ Databricks-Certified-Data-Engineer-Professional ▟を検索して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional試験関連赤本
- 素敵なDatabricks-Certified-Data-Engineer-Professional絶対合格 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional合格体験談 | 信頼的なDatabricks-Certified-Data-Engineer-Professional日本語版問題解説 🔺 [ www.topexam.jp ]を開き、[ Databricks-Certified-Data-Engineer-Professional ]を入力して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional受験方法
- Databricks-Certified-Data-Engineer-Professional受験資格 🎺 Databricks-Certified-Data-Engineer-Professional無料試験 😚 Databricks-Certified-Data-Engineer-Professionalテスト難易度 🚪 最新☀ Databricks-Certified-Data-Engineer-Professional ️☀️問題集ファイルは“ www.goshiken.com ”にて検索Databricks-Certified-Data-Engineer-Professional受験方法
- 認定するDatabricks-Certified-Data-Engineer-Professional絶対合格 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional合格体験談 | 更新するDatabricks-Certified-Data-Engineer-Professional日本語版問題解説 🙎 検索するだけで➡ www.shikenpass.com ️⬅️から“ Databricks-Certified-Data-Engineer-Professional ”を無料でダウンロードDatabricks-Certified-Data-Engineer-Professional受験資格
- 認定するDatabricks-Certified-Data-Engineer-Professional絶対合格 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional合格体験談 | 更新するDatabricks-Certified-Data-Engineer-Professional日本語版問題解説 🏬 ⮆ www.goshiken.com ⮄には無料の➽ Databricks-Certified-Data-Engineer-Professional 🢪問題集がありますDatabricks-Certified-Data-Engineer-Professional復習内容
- Databricks-Certified-Data-Engineer-Professional復習解答例 🌘 Databricks-Certified-Data-Engineer-Professional学習体験談 🌁 Databricks-Certified-Data-Engineer-Professional受験記対策 👩 ➡ www.topexam.jp ️⬅️を開いて“ Databricks-Certified-Data-Engineer-Professional ”を検索し、試験資料を無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional資格トレーニング
- 認定するDatabricks-Certified-Data-Engineer-Professional絶対合格 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional合格体験談 | 更新するDatabricks-Certified-Data-Engineer-Professional日本語版問題解説 🥽 時間限定無料で使える➠ Databricks-Certified-Data-Engineer-Professional 🠰の試験問題は▶ www.goshiken.com ◀サイトで検索Databricks-Certified-Data-Engineer-Professional無料試験
- Databricks-Certified-Data-Engineer-Professional認定デベロッパー 🕜 Databricks-Certified-Data-Engineer-Professional練習問題 🌮 Databricks-Certified-Data-Engineer-Professional赤本合格率 🧺 ⏩ www.mogiexam.com ⏪にて限定無料の《 Databricks-Certified-Data-Engineer-Professional 》問題集をダウンロードせよDatabricks-Certified-Data-Engineer-Professional受験方法
- 素晴らしいDatabricks-Certified-Data-Engineer-Professional絶対合格 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional合格体験談 | 実用的なDatabricks-Certified-Data-Engineer-Professional日本語版問題解説 🥚 ⏩ www.goshiken.com ⏪に移動し、[ Databricks-Certified-Data-Engineer-Professional ]を検索して、無料でダウンロード可能な試験資料を探しますDatabricks-Certified-Data-Engineer-Professional学習体験談
- Databricks-Certified-Data-Engineer-Professional最新知識 🎁 Databricks-Certified-Data-Engineer-Professional資格トレーニング 🥼 Databricks-Certified-Data-Engineer-Professional日本語版問題集 ☢ { www.mogiexam.com }を開いて⇛ Databricks-Certified-Data-Engineer-Professional ⇚を検索し、試験資料を無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional資格トレーニング
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
さらに、CertJuken Databricks-Certified-Data-Engineer-Professionalダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1_N1nTs55mc7TGTz8s04aRNoOA0aPyrCM