Microsoft的DP-750考試是IT行業之中既流行也非常重要的一個考試,我們準備了最優質的學習指南和最佳的線上服務,特意為IT專業人士提供捷徑,VCESoft Microsoft的DP-750考題涵蓋了所有你需要知道的考試內容和答案,如果你通過我們VCESoft的考題模擬,你就知道這才是你千方百計想得到的東西,並且認為這樣才真的是為考試做準備的
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Prepare and process data | 30-35% | - Data quality and validation
|
| Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
隨著21世紀資訊時代的洪流到來,人們不斷提高自己的知識來適應這個時代,但遠遠不夠,就IT行業來說,Microsoft的DP-750考試認證是IT行業必不可少的認證,想要通過這項考試培訓是必須的,因為這項考試是有所困難的,通過了它,就可以受到國際的認可及接受,你將有一個美好的前程及拿著受人矚目的高薪,VCESoft網站有全世界最可靠的IT認證培訓資料,有了它你就可以實現你美好的計畫,我們保證你100%通過認證,參加Microsoft的DP-750考試認證的考生們,你們還在猶豫什麼呢,趕緊行動吧!
問題 #20
Which tool is best for continuous ingestion of files landing in Azure Data Lake?
答案:B
解題說明:
Auto Loader is optimized for incremental and continuous ingestion from cloud storage. It detects new files automatically and scales efficiently. Databricks Jobs schedule tasks but do not handle file detection. Logic Apps are workflow tools. ADF is batch-oriented.
問題 #21
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1 You need to meet the following requirements:
* Records that violate rule! must NOT be written to Table1. but the pipeline must continue processing valid records.
* Data engineers must be able to review expectation metrics by using minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.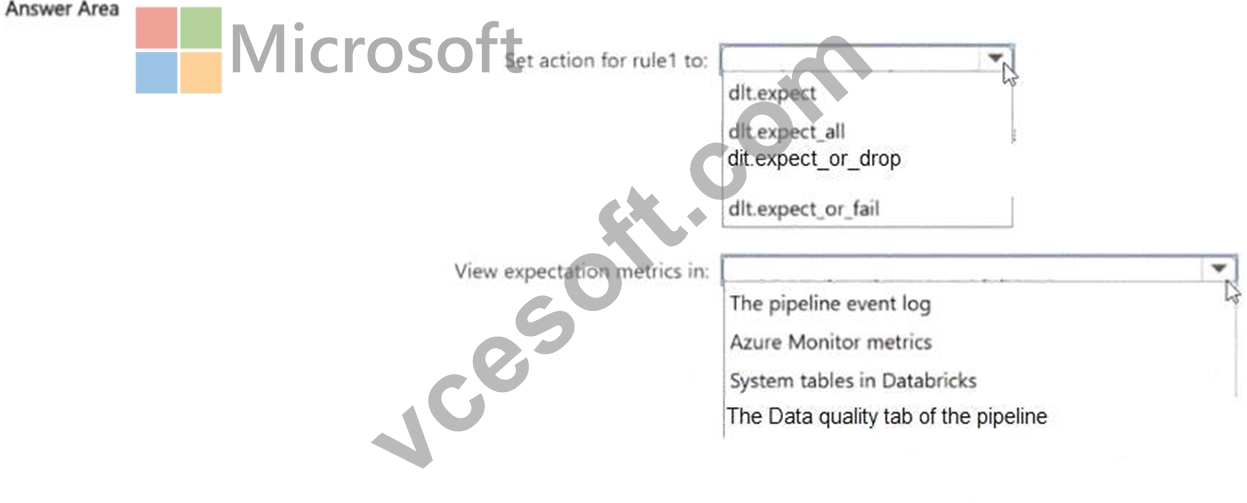
答案:
解題說明: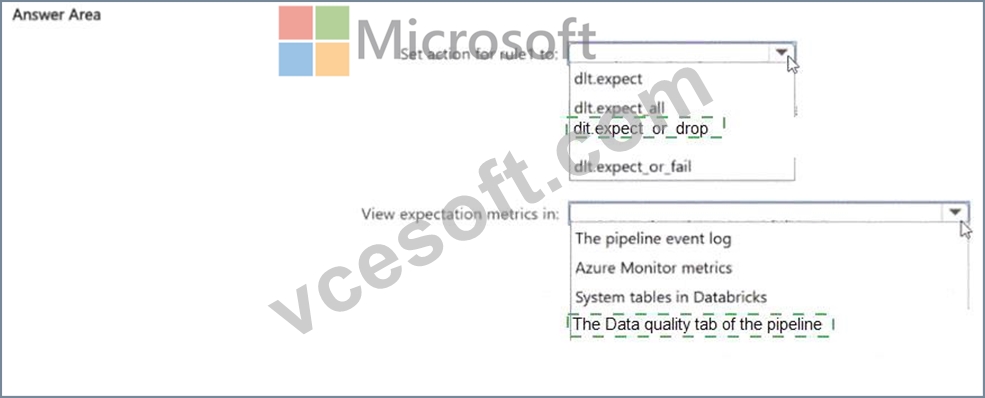
Explanation:
Two things are needed here:
For the rule enforcement: use @dlt.expect_or_drop. This drops any record that violates rule1 before it reaches Table1, while the pipeline continues processing all valid records. The table only ever receives clean data.
For reviewing metrics: the Lakeflow SDP Pipeline UI is the right tool - zero development effort required.
The pipeline graph shows expectation pass/fail counts directly on each table node, and the event log provides a detailed per-batch breakdown of how many records were dropped and why. Data engineers can inspect this at any time without writing additional monitoring queries or connecting external dashboards.
This combination is one of the strongest arguments for SDP over hand-coded Structured Streaming:
expectation observability is built in, not bolted on.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
問題 #22
You have an Azure Databricks workspace that contains multiple all-purpose clusters.
You discover that some clusters remain idle for long periods after users finish their work.
You need to reduce compute costs without affecting active workloads.
What should you do?
答案:D
解題說明:
To reduce compute costs from idle clusters without impacting active workloads, you must configure Auto-Termination and use Cluster Policies.
Core Remedies
*-> Auto-Termination: Set a strict inactivity timeout (e.g., 20-30 minutes) on all-purpose clusters to automatically shut them down when idle.
Cluster Policies: Enforce maximum auto-termination limits across the workspace so users cannot disable or set excessively long idle timeouts.
Single User Access Mode: Use this mode where possible, as it tracks idleness more accurately than Shared mode by monitoring the specific user's activity.
Reference:
https://medium.com/@sujathamudadla1213/databricks-lakehouse-platform-describe-how- clusters-are-terminated-and-the-impact-of-terminating-a-b6236689fd2e
問題 #23
You need to configure compute for the ingestion of telemetry data. The solution must meet the data ingestion and processing requirements.
What should you do?
答案:B
解題說明:
The correct answer is A. Photon is Azure Databricks ' native vectorized query engine, written in C++, designed to accelerate data ingestion and SQL-heavy workloads significantly over the standard Spark JVM path. Enabling it on a job compute cluster directly addresses Contoso ' s requirement for ' fast and consistent performance for BI workloads ' and ' production ingestion workloads that can scale automatically during telemetry spikes. ' Photon integrates transparently - no code changes are needed - and pairs well with autoscaling job clusters to handle the bursty 40,000-sensor telemetry load.
Option B contradicts the isolation requirement: Contoso explicitly needs production and development separated, not merged onto shared compute. Option C with a fixed large node gives peak capacity at all times, driving up costs even during quiet periods. Option D disabling autoscaling is the opposite of what ' s needed
- telemetry spikes require elastic scaling, not a locked node count.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/photon
問題 #24
You have an Azure Databricks account that contains workspaces enabled for Unity Catalog.
You need to implement audit logging to meet the following requirements:
* Capture audit logs for all the workspaces in the account.
* Retain the audit logs for 90 days.
* Minimize storage and ingestion costs.
The logs will be reviewed only during security investigations and will NOT be queried regularly.
To where should you send the audit logs?
答案:B
解題說明:
An Azure Storage account provides durable, comparatively low-cost retention for diagnostic and audit logs that are accessed infrequently. A lifecycle or retention policy can preserve the logs for 90 days and then remove them automatically. This matches an investigation-only access pattern without paying the ingestion and indexing charges associated with Log Analytics. Azure Monitor metrics stores numerical monitoring measurements, not the complete audit-event records required here. Azure Event Hubs is a streaming transport intended to forward events to consumers and is not the final long-term retention destination. Log Analytics is appropriate when teams need frequent querying, dashboards, and alerting, but those capabilities introduce unnecessary cost for logs reviewed only during occasional investigations. Storage therefore best satisfies centralized retention and cost requirements.
問題 #25
......
VCESoft的專家團隊為了滿足以大部分IT人士的需求,他們利用自己的經驗和知識努力地研究過去的幾年的Microsoft DP-750 認證考試題目,如此,VCESoft的最新的Microsoft DP-750 的模擬測試題和答案就問世了。 我們的Microsoft DP-750 模擬測試題及答案和真實考試的題目及答案有95%的相似性,通過VCESoft提供的測試題你可以100%通過考試。如果你沒有通過考試,VCESoft會全額退款給你。你也可以先在網上免費下載VCESoft提供的部分關於Microsoft DP-750 認證考試的練習題和答案作為嘗試,在你瞭解了我們的可靠性後,快將我們VCESoft提供的產品加入您的購物車吧。VCESoft將成就你的夢想。
DP-750認證資料: https://www.vcesoft.com/DP-750-pdf.html