You can practice all the difficulties and hurdles which could be faced in an actual Microsoft exam. It also assists you in boosting confidence and reducing problem-solving time. The Pass4future designs AI-200 desktop-based practice software for desktops, so you can install it from a website and then use it without an internet connection. You only need an internet connection to verify the license of the products. No other plugins are required to employ it.
| Section | Objectives |
|---|---|
| Implement Azure AI solutions | - Implement knowledge mining with Azure AI Search - Implement natural language processing solutions - Implement generative AI solutions using Azure OpenAI - Implement computer vision solutions |
| Plan and manage Azure AI solutions | - Plan security and compliance requirements - Select appropriate Azure AI services - Monitor and optimize AI solutions |
| Implement and monitor AI workloads | - Deploy AI models and services - Monitor performance and troubleshoot issues |
>> Valid AI-200 Test Preparation <<
You can learn our AI-200 test prep in the laptops or your cellphone and study easily and pleasantly as we have different types, or you can print our PDF version to prepare your exam which can be printed into papers and is convenient to make notes. Studying our AI-200 exam preparation doesn’t take you much time and if you stick to learning you will finally pass the exam successfully. Believe us because the AI-200 Test Prep are the most useful and efficient, and the AI-200 exam preparation will make you master the important information and the focus of the exam. We are sincerely hoping to help you pass the exam.
NEW QUESTION # 111
You are implementing the expiration requirement for AI-generated summaries in the Redis cache.
You need to purge the AI summaries five minutes after creation, regardless of how often they are accessed.
What should you do?
Answer: A
Explanation:
Configure a fixed expiration timeout on each Redis key when the summary is created , such as a five- minute TTL. Azure Managed Redis automatically removes a key when its configured timeout expires.
Critically, ordinary read operations do not extend that expiration period, so a summary created at time T will expire approximately five minutes later regardless of how frequently clients retrieve it.
This is the required absolute-expiration behavior. In Redis, applications can establish expiration when writing the value or by using expiration commands after creation. The important design property is that the expiration deadline is not refreshed whenever the key is read.
An allkeys-lru eviction policy addresses memory pressure , not deterministic five-minute expiration. It may evict less recently used keys when memory is constrained, but it does not guarantee removal exactly five minutes after creation. The PERSIST command is directly incorrect because it removes an existing timeout , potentially causing the summary to remain indefinitely. Sliding expiration is also unsuitable because it renews or resets the expiration window based on activity, allowing frequently accessed summaries to remain longer than five minutes.
Therefore, a per-key absolute five-minute expiration is the correct configuration.
Study Guide references: Azure Managed Redis # key expiration; TTL behavior; cache expiration versus eviction; fixed versus sliding expiration.
NEW QUESTION # 112
An AI application uses a database. The database credential rotates every 30 days.
The application currently requires a manual update each time the credential rotates.
You need to ensure that the application always uses the latest secret version without manual updates.
Which two actions should you perform? Each correct answer presents part of the solution. Choose two.
NOTE: Each correct selection is worth one point.
Answer: B,D
NEW QUESTION # 113
You have container source code stored in a Git repository.
The container registry must automatically build and store a new container image whenever a developer commits code to the Git repository.
You must minimize the use of an external build infrastructure.
You need to configure Azure Container Registry (ACR) to manage the build process natively and automatically.
Which two ACR components should you use? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,D
Explanation:
Azure Container Registry Tasks provides Azure-hosted container build capabilities, eliminating the need to maintain external Docker build servers or dedicated CI build infrastructure. A Quick task uses commands such as az acr build to send the build context to ACR-managed compute, where Azure builds the container image and, by default, pushes the successfully built image directly into the registry. Microsoft describes quick tasks as cloud-based, on-demand build-and-push operations that do not require a local Docker Engine.
For automatic execution after source-code changes, use a Source-triggered task . ACR Tasks can associate a task with a GitHub or Azure Repos repository and automatically execute the image build whenever code is committed to the configured branch. Microsoft documents that when a commit occurs, the source-control trigger causes ACR Tasks to build and push the resulting image.
A Webhook is not the required standalone ACR build component here. ACR Tasks creates and manages the necessary source-repository webhook as part of configuring the source trigger. An Artifact Cache rule caches upstream container artifacts and does not build application images from Git commits.
Study Guide references: Azure Container Registry Tasks # Quick tasks; Automatically triggered tasks; Source-code commit triggers; cloud-based image builds.
NEW QUESTION # 114
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Hotspot Question
You need to optimize secure database connectivity from the containerized Recommendation API.
How should you configure the application? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.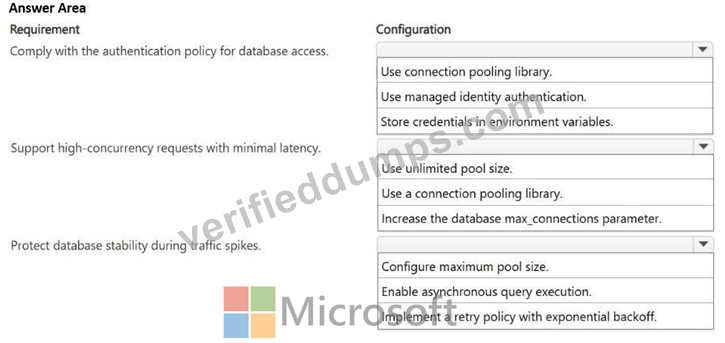
Answer:
Explanation: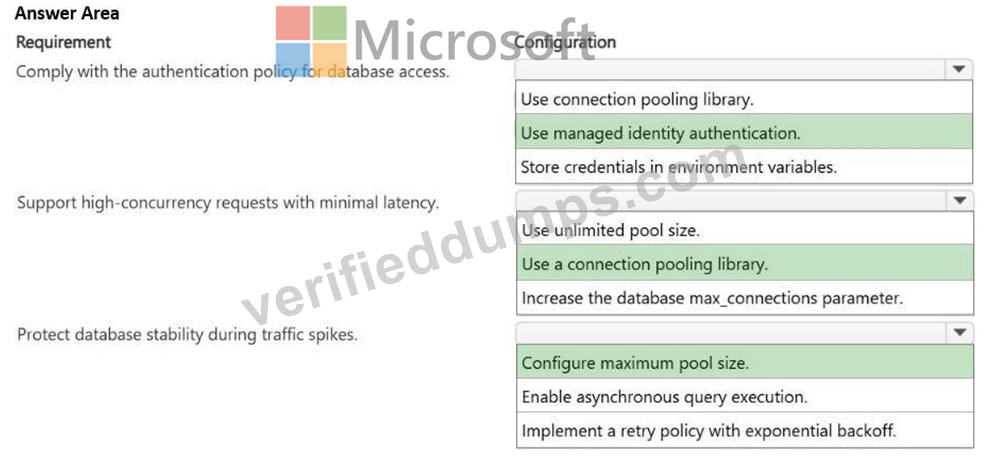
Explanation:
Box 1: Use managed identity authentication.
Scenario: Identity: Use managed identities for all service-to-service and service-to-database authentication. Plain-text credentials in configuration files are strictly prohibited.' Box 2: Use a connection pooling library Scenario: Environment: Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
To support high-concurrency requests with minimal latency on Azure Database for PostgreSQL, the best action is to use a connection pooling library (or leverage Azure's built-in PgBouncer feature).
Eliminates Connection Overhead:
PostgreSQL utilizes a process-per-connection model. Forking a new backend process for every incoming request introduces substantial CPU and memory overhead, severely degrading latency under high concurrency. A connection pool keeps a warm set of reusable database sessions active.
Optimized for Azure: Microsoft provides a built-in managed PgBouncer integration for Azure Database for PostgreSQL. Enabling it in transaction mode allows the database to accept thousands of concurrent client connections while keeping actual backend processes lean and stable Box 3: Configure a maximum pool size Configure a maximum pool size is the best action to directly protect database stability during sudden traffic spikes.
Prevents Resource Exhaustion: Traffic spikes naturally lead to a surge in connection requests.
Unchecked connections consume substantial RAM and CPU overhead, which can crash the database or trigger severe latency. Limiting the pool size stops the "thundering herd" problem Acts as a Shock Absorber: When the pool hits its maximum limit, extra client requests are safely queued at the application or connection pooling layer (like Azure's built-in PgBouncer proxy) rather than overwhelming the database backend Reference:
https://docs.azure.cn/en-us/postgresql/connectivity/concepts-pgbouncer
https://learn.microsoft.com/en-au/answers/questions/5884412/best-practise-azure-postgresql-flexible-server-max
NEW QUESTION # 115
You are developing an application that must extract structured field data (invoice number, total, vendor name) from scanned invoices in multiple layouts. You need a solution that requires no custom model training. What should you use?
Answer: A
Explanation:
The prebuilt invoice model in Azure AI Document Intelligence is trained to recognize common invoice fields (vendor, total, line items, invoice number) out of the box across varied layouts, requiring no training data or custom model.
NEW QUESTION # 116
......
According to our investigation, the test syllabus of the AI-200 exam is changing every year. Some new knowledge will be added into the annual real exam. Some old knowledge will be deleted. So you must have a clear understanding of the test syllabus of the AI-200 study engine. Now, you can directly refer to our AI-200 study materials. Because we have been in the field for over ten years and we are professional in this career. We can always offer the most updated information to our loyal customers.
Valid AI-200 Test Papers: https://www.verifieddumps.com/AI-200-valid-exam-braindumps.html