BONUS!!! Download part of Pass4sures Professional-Machine-Learning-Engineer dumps for free: https://drive.google.com/open?id=1JeenNpU2Z7Yd05Urutzf0GdGHXW96YkE
As long as you can form a positive outlook, which can aid you to realize your dreams through your constant efforts. Then our Professional-Machine-Learning-Engineer learning questions will aid you to regain confidence and courage. So you will never regret to choose our Professional-Machine-Learning-Engineer Study Materials. And we have help numerous of our customers achieved their dreams and live a better life. Just browser our websites and choose a suitable Professional-Machine-Learning-Engineer practice guide for you.
| Section | Objectives |
|---|---|
| Topic 1: Serving and scaling models | - Model optimization (Quantization, Distillation) - Online prediction (Vertex AI Prediction) - Hardware accelerators (GPU/TPU) in serving - Batch prediction |
| Topic 2: Collaborating within and across teams to manage data and models | - Version control and reproducibility (e.g., DVC, MLOps) - Data management and governance - Collaboration between Data Scientists, Data Engineers, and ML Engineers |
| Topic 3: Scaling prototypes into ML models | - Hyperparameter tuning - Training at scale (Distributed training, TPUs) - Frameworks (TensorFlow, PyTorch, JAX, Scikit-learn) |
| Topic 4: Monitoring ML solutions | - Logging and alerting (Cloud Monitoring) - Model retraining strategies - Performance monitoring and drift detection |
| Topic 5: Automating and orchestrating ML pipelines | - CI/CD for ML systems - Triggering and scheduling pipelines - Vertex AI Pipelines (Kubeflow Pipelines) |
| Topic 6: Architecting low-code ML solutions | - Implementing BigQuery ML for basic models - AutoML capabilities and implementation - Leveraging pre-built ML models as a service (e.g., Vision AI, Speech-to-Text, Recommendations AI) |
>> Valid Test Professional-Machine-Learning-Engineer Tutorial <<
With the advent of the era of big data, data information bringing convenience to our life at the same time, the problem of personal information leakage has become increasingly prominent. For preventing information leakage, our Professional-Machine-Learning-Engineer test torrent will provide the date protection for all customers. It is not necessary for you to be anxious about your information gained by the third party. At the same time, the versions of our Google Professional Machine Learning Engineer exam tool also have the ability to help you ward off network intrusion and attacks and protect users’ network security. If you choose our Professional-Machine-Learning-Engineer Study Materials, we can promise that we must enhance the safety guarantee and keep your information from revealing.
NEW QUESTION # 303
Your organization manages an online message board A few months ago, you discovered an increase in toxic language and bullying on the message board. You deployed an automated text classifier that flags certain comments as toxic or harmful. Now some users are reporting that benign comments referencing their religion are being misclassified as abusive Upon further inspection, you find that your classifier's false positive rate is higher for comments that reference certain underrepresented religious groups. Your team has a limited budget and is already overextended. What should you do?
Answer: C
Explanation:
The problem of the text classifier is that it has a high false positive rate for comments that reference certain underrepresented religious groups. This means that the classifier is not able to distinguish between toxic and non-toxic language when those groups are mentioned. One possible reason for this is that the training data does not have enough examples of non-toxic comments that reference those groups, leading to a biased model.
Therefore, a possible solution is to add synthetic training data where those phrases are used in non-toxic ways, which can help the model learn to generalize better and reduce the false positive rate. Synthetic data is artificially generated data that mimics the characteristics of real data, and can be used to augment the existing data when the real data is scarce or imbalanced. References:
* Preparing for Google Cloud Certification: Machine Learning Engineer, Course 5: Responsible AI, Week
3: Fairness
* Google Cloud Professional Machine Learning Engineer Exam Guide, Section 4: Ensuring solution quality, 4.4 Evaluating fairness and bias in ML models
* Official Google Cloud Certified Professional Machine Learning Engineer Study Guide, Chapter 9:
Responsible AI, Section 9.3: Fairness and Bias
NEW QUESTION # 304
You are an ML engineer at a large grocery retailer with stores in multiple regions. You have been asked to create an inventory prediction model. Your models features include region, location, historical demand, and seasonal popularity. You want the algorithm to learn from new inventory data on a daily basis. Which algorithms should you use to build the model?
Answer: D
Explanation:
"algorithm to learn from new inventory data on a daily basis" = time series model , best option to deal with time series is forsure RNN
https://builtin.com/data-science/recurrent-neural-networks-and-lstm
NEW QUESTION # 305
You trained a text classification model. You have the following SignatureDefs: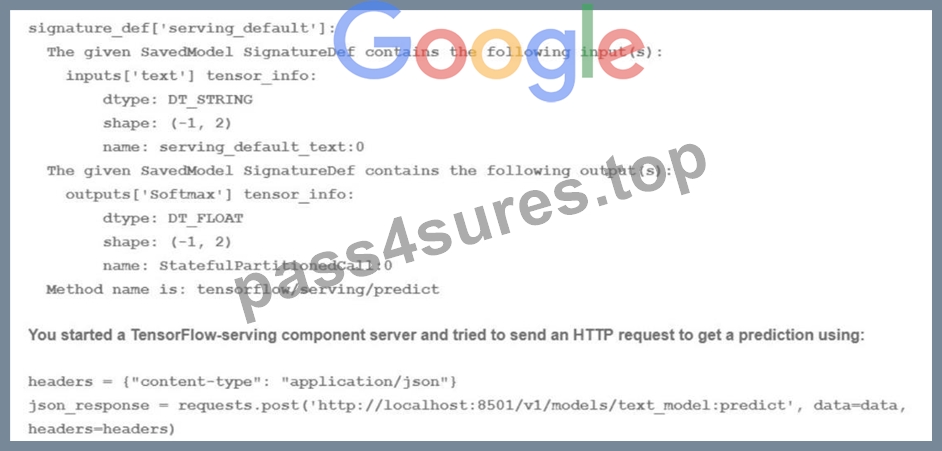
What is the correct way to write the predict request?
Answer: C
Explanation:
A predict request is a way to send data to a trained model and get predictions in return. A predict request can be written in different formats, such as JSON, protobuf, or gRPC, depending on the service and the platform that are used to host and serve the model. A predict request usually contains the following information:
* The signature name: This is the name of the signature that defines the inputs and outputs of the model.
A signature is a way to specify the expected format, type, and shape of the data that the model can accept and produce. A signature can be specified when exporting or saving the model, or it can be automatically inferred by the service or the platform. A model can have multiple signatures, but only one can be used for each predict request.
* The instances: This is the data that is sent to the model for prediction. The instances can be a single instance or a batch of instances, depending on the size and shape of the data. The instances should match the input specification of the signature, such as the number, name, and type of the input tensors.
For the use case of training a text classification model, the correct way to write the predict request is D. data = json.dumps({"signature_name": "serving_default", "instances": [['a', 'b'], ['c', 'd'] , ['e', 'f']]}) This option involves writing the predict request in JSON format, which is a common and convenient format for sending and receiving data over the web. JSON stands for JavaScript Object Notation, and it is a way to represent data as a collection of name-value pairs or an ordered list of values. JSON can be easily converted to and from Python objects using the json module.
This option also involves using the signature name "serving_default", which is the default signature name that is assigned to the model when it is saved or exported without specifying a custom signature name. The serving_default signature defines the input and output tensors of the model based on the SignatureDef that is shown in the image. According to the SignatureDef, the model expects an input tensor called "text" that has a shape of (-1, 2) and a type of DT_STRING, and produces an output tensor called "softmax" that has a shape of (-1, 2) and a type of DT_FLOAT. The -1 in the shape indicates that the dimension can vary depending on the number of instances, and the 2 indicates that the dimension is fixed at 2. The DT_STRING and DT_FLOAT indicate that the data type is string and float, respectively.
This option also involves sending a batch of three instances to the model for prediction. Each instance is a list of two strings, such as ['a', 'b'], ['c', 'd'] , or ['e', 'f']. These instances match the input specification of the signature, as they have a shape of (3, 2) and a type of string. The model will process these instances and produce a batch of three predictions, each with a softmax output that has a shape of (1, 2) and a type of float.
The softmax output is a probability distribution over the two possible classes that the model can predict, such as positive or negative sentiment.
Therefore, writing the predict request as data = json.dumps({"signature_name": "serving_default",
"instances": [['a', 'b'], ['c', 'd'] , ['e', 'f']]}) is the correct and valid way to send data to the text classification model and get predictions in return.
References:
[json - JSON encoder and decoder]
NEW QUESTION # 306
Your data science team is training a PyTorch model for image classification based on a pre-trained RestNet model. You need to perform hyperparameter tuning to optimize for several parameters. What should you do?
Answer: A
NEW QUESTION # 307
You have trained a DNN regressor with TensorFlow to predict housing prices using a set of predictive features. Your default precision is tf.float64, and you use a standard TensorFlow estimator; estimator = tf.estimator.DNNRegressor( feature_columns=[YOUR_LIST_OF_FEATURES], hidden_units-[1024, 512, 256], dropout=None) Your model performs well, but Just before deploying it to production, you discover that your current serving latency is 10ms @ 90 percentile and you currently serve on CPUs. Your production requirements expect a model latency of 8ms @ 90 percentile. You are willing to accept a small decrease in performance in order to reach the latency requirement Therefore your plan is to improve latency while evaluating how much the model ' s prediction decreases. What should you first try to quickly lower the serving latency?
Answer: B
Explanation:
* Qua ntization is a technique that reduces the numerical precision of the weights and activations of a neural network, which can improve the inference speed and reduce the memory footprint of the model 1
.
* Reducing the floating point precision from tf.float64 to tf.float16 can potentially halve the latency and memory usage of the model, while having minimal impact on the accuracy 2 .
* Increasing the dropout rate to 0.8 in either mode would not affect the latency, but would likely degrade the performance of the model significantly, as dropout is a regularization technique that randomly drops out units during training to prevent overfitti ng 3 .
* Switching from CPU to GPU serving may or may not improve the latency, depending on the hardware specifications and the model complexity, but it would also incur additional costs and complexity for deployment 4
NEW QUESTION # 308
......
Our Professional-Machine-Learning-Engineer training materials provide three different versions to the client and they include the PDF version, PC version, APP online version. Each version’s using method and functions are different but the questions and answers of our Professional-Machine-Learning-Engineer Study Materials is the same. The client can decide which version of our Professional-Machine-Learning-Engineer exam questions to choose according their hobbies and their practical conditions.
Professional-Machine-Learning-Engineer Exam Brain Dumps: https://www.pass4sures.top/Google-Cloud-Certified/Professional-Machine-Learning-Engineer-testking-braindumps.html
BONUS!!! Download part of Pass4sures Professional-Machine-Learning-Engineer dumps for free: https://drive.google.com/open?id=1JeenNpU2Z7Yd05Urutzf0GdGHXW96YkE