In the 21 Century, the DP-750 certification became more and more recognized in the society because it represented the certain ability of examinees. However, in order to obtain DP-750 certification, you have to spend a lot of time preparing for the DP-750 Exam. Many people gave up because of all kinds of difficulties before the examination, and finally lost the opportunity to enhance their self-worth. As a thriving multinational company, we are always committed to solving this problem.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Topic 2: Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Topic 3: Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Topic 4: Prepare and process data | 30-35% | - Data transformation and modeling
|
>> DP-750 Hottest Certification <<
For every candidats, practicing for the pass of the exam is an evitable process, since we can improve our ability. Our DP-750 Exam Torrent will provide you the practice. The pass rate is 98.88%, and if you fail to pass the test, money back guarantee. Besides, we also have online chat service stuff, if you have any questions, you can have a chat with them, or you can send emails to us, we will give you the reply as quickly as we can.
NEW QUESTION # 65
Hotspot Question
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 runs every hour.
Occasionally, the job run takes longer than one hour to complete. Overlapping runs must be prevented to avoid data corruption.
You need to configure the job scheduling behavior.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.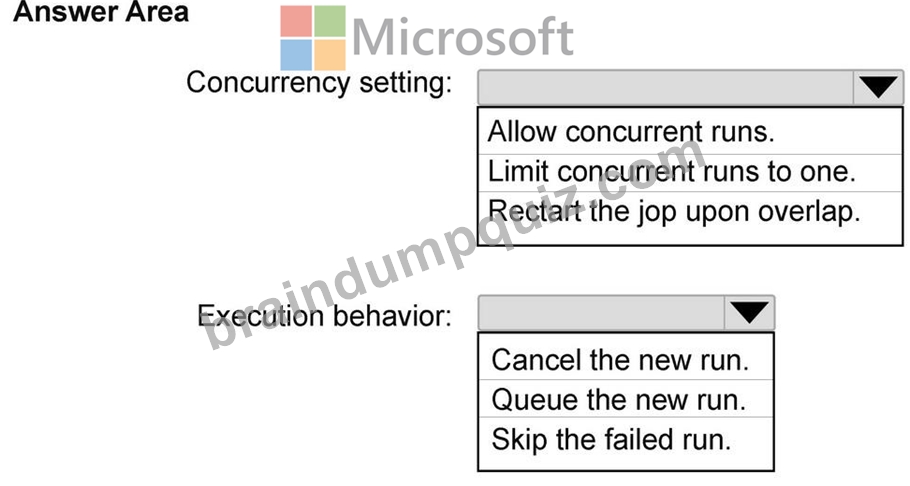
Answer:
Explanation: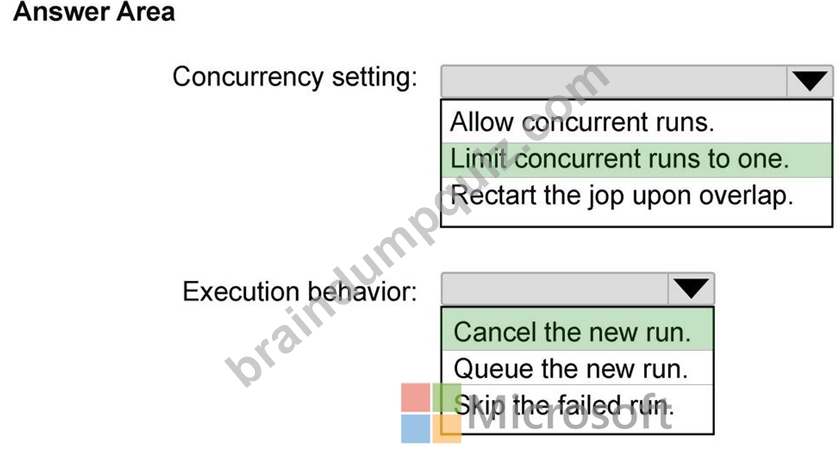
NEW QUESTION # 66
You have an Azure Databricks workspace that contains a Delta table named Table1.
Table1 has accumulated obsolete files.
You need to reduce storage costs. The solution must preserve 30 days of time travel history.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,C
Explanation:
To diminish storage costs while preserving 60 days of time travel history, you must perform the following two actions: Set the delta.deletedFileRetentionDuration table property to 60 days and Run the vacuum command on the table.
Set the delta.deletedFileRetentionDuration table property to 30 days
This property controls how long data files must be deleted before they become eligible for removal by a cleanup process. By default, it is set to 7 days. Increasing it to 60 days ensures that Delta Lake preserves the underlying parquet files required to query any historical snapshot within your 30-day time travel window.
Run the vacuum command on the tableChanging the retention property alone does not delete files or reduce costs. You must explicitly execute the VACUUM command. The command scans the table and permanently deletes uncommitted or deleted data files that are older than the 60- day threshold defined by your retention duration, thereby freeing up storage space.
Incorrect:
[Not C]
Set the delta.logRetentionDuration table property to 30 days
This property controls how long the transaction log (_delta_log) history is kept, which defaults to
30 days. While the transaction log is required for time travel, modifying this property alone does not delete the heavy data files causing high storage costs. Furthermore, it governs the logs rather than the actual deleted data files.
Reference:
https://www.cloudmatter.io/post/data-audit-with-databricks-delta-time-travel
NEW QUESTION # 67
You have an Azure Databricks workspace named Workspace1 that contains a cluster named Cluster1.
You need to enable a user named User1 to install a Maven package on all the nodes of Cluster1. The solution must follow the principle of least privilege.
What should you do?
Answer: A
Explanation:
Installing a Maven package on every node requires changing Cluster1's library configuration. The CAN MANAGE permission grants the cluster-level management capabilities required to add or remove libraries without giving User1 broader control over the entire workspace or Azure resource group. CAN RESTART allows a user to restart the cluster but does not provide sufficient authority to change its library configuration.
Assigning the Azure Contributor role would grant excessive control over the resource group and does not represent the appropriate Databricks object-level permission. Making User1 a workspace administrator would provide substantially more privileges than necessary. Granting CAN MANAGE directly on Cluster1 therefore satisfies the operational requirement while limiting User1's authority to the specific compute resource that must be modified.
NEW QUESTION # 68
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You plan to run the following PySpark code.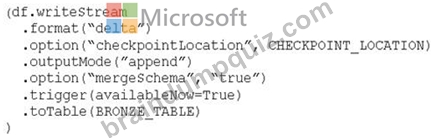
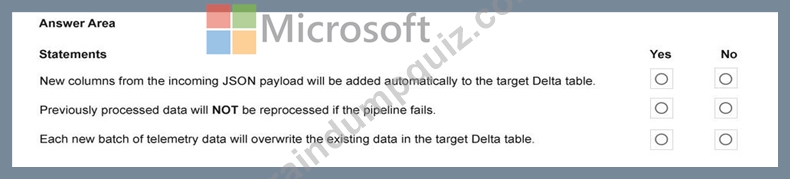
Answer:
Explanation: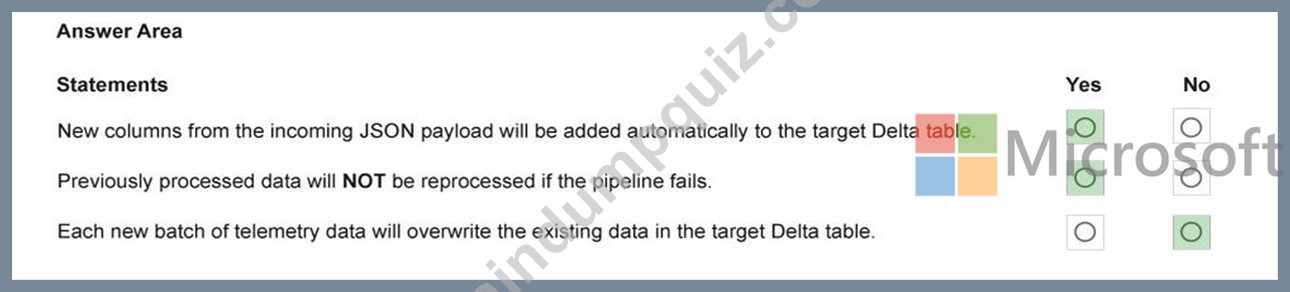
NEW QUESTION # 69
You need to recommend a compute type for the production ingestion workloads and BI workloads. The solution must meet the environment and compute requirements.
What should you recommend for each type of workload? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.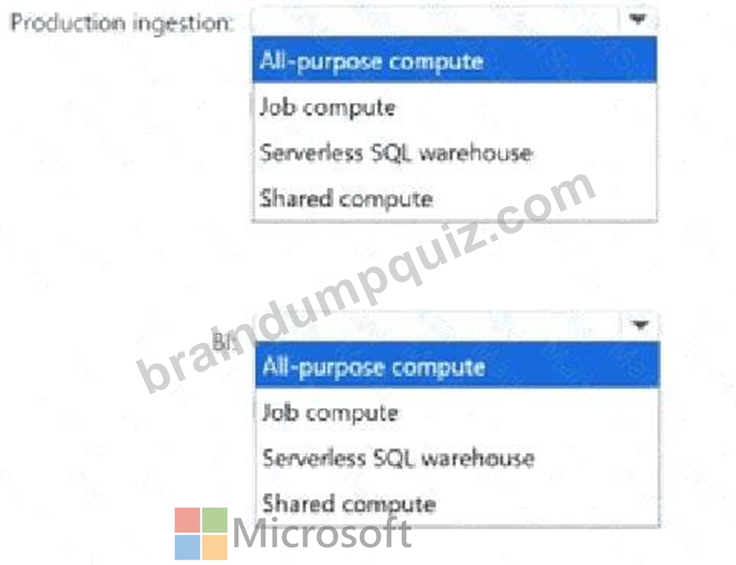
Answer:
Explanation: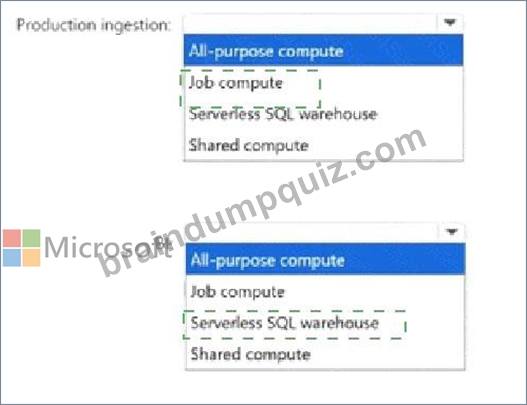
Explanation:
Production ingestion: Job compute
BI: Serverless SQL warehouse
Job compute is designed for automated production workloads executed through Lakeflow Jobs. Its lifecycle can be tied to the job run, providing workload isolation and avoiding the cost of maintaining an interactive all- purpose cluster continuously. It is therefore appropriate for scheduled ingestion and transformation processing. A serverless SQL warehouse is designed for BI and Databricks SQL workloads. It provides rapid startup, automatic infrastructure management, scaling, and optimized SQL-query execution for dashboards and reporting tools. All-purpose compute is intended primarily for interactive notebook development and exploration, while shared compute does not provide the same job-specific isolation or SQL-serving experience. Consequently, job compute should support production ingestion, and a serverless SQL warehouse should serve the BI workload.
NEW QUESTION # 70
......
If you are already an employee or busy in your routine, you can prepare Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam quickly with BraindumpQuiz pdf questions. DP-750 pdf exam questions help applicants study for the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam at any time from any location. With the pdf questions, it will be easy for you to complete the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam preparation in a short time.
Sure DP-750 Pass: https://www.braindumpquiz.com/DP-750-exam-material.html