P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by Prep4sures: https://drive.google.com/open?id=1EFN0mLSDd2K7Q5bTbUh1eZbMrDxownRI
Can you imagine that you only need to review twenty hours to successfully obtain the Snowflake certification? Can you imagine that you don’t have to stay up late to learn and get your boss’s favor? With SPS-C01 study materials, passing exams is no longer a dream. If you are an office worker, SPS-C01 Study Materials can help you make better use of the scattered time to review. Just a mobile phone can let you do questions at any time.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark Concepts | 15% | - Snowpark architecture and core concepts - Snowpark Sessions and connection management - Stored procedures and conditional logic - Transformations vs. Actions - Client-side vs. Server-side execution - Snowpark DataFrames and query plans |
| Topic 2: Performance Optimization and Best Practices | 20% | - Caching strategies - Warehouse sizing for Snowpark - Query pushdown and optimization - Debugging and explain plans - Vectorized UDFs - Minimizing data transfer |
| Topic 3: Data Transformations and DataFrame Operations | 35% | - Persisting transformed data - Using built-in functions - Window functions - Filtering, Aggregating, and Joining DataFrames - Complex data pipelines |
| Topic 4: Snowpark API for Python | 30% | - Working with Semi-structured data - DataFrame creation and manipulation - Reading and writing data - User-Defined Functions (UDFs) and Stored Procedures - Establishing connections and session management |
>> Online Snowflake SPS-C01 Training <<
What is your dream? Don't you want to make a career? The answer must be ok. Then, you need to upgrade and develop yourself. You worked in the IT industry, through what methods can you realize your dream? Taking IT certification exam and getting the certificate are the way to upgrade yourself. At present, Snowflake SPS-C01 Exam is very popular. Do you want to get Snowflake SPS-C01 certificate? If it is ok, don't hesitate to sign up for the exam. And don't worry about how to pass the test, Prep4sures certification training will be with you.
NEW QUESTION # 87
Consider the following Snowpark Python code snippet that defines and registers a User-Defined Table Function (UDTF):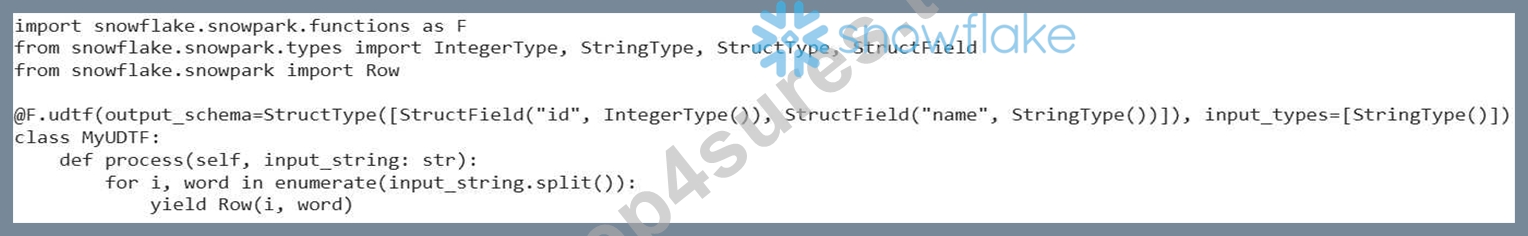
Which of the following statements is MOST accurate regarding the behavior and limitations of this UDTF when used in a Snowpark DataFrame transformation?
Answer: B
Explanation:
Option E is the most accurate. When a Snowpark UDTF receives NULL as input, it's passed as 'None' in Python. The provided code defines the 'output_schema' which describes the structure and types of the rows that the UDTF will return. Option A is incorrect because, while Snowflake distributes UDTF processing, the code itself doesn't guarantee parallelism within a single input string. Option B is incorrect; UDTFs can be used with any DataFrame, regardless of whether it's backed by a persistent table. Option C is incorrect because NULL values in the input DataFrame will be passed as 'None' to the 'process' method. Option D is incorrect; Snowpark distributes UDTF execution across worker nodes, not within the driver process.
NEW QUESTION # 88
You're tasked with loading data representing transactions from a legacy system into Snowflake using Snowpark. The legacy system exports the transaction data as a Python list of tuples, where each tuple contains transaction ID (integer), transaction amount (float), and transaction date (string in 'YYYY-MM-DD' format). The scale of data can be very high and need optimized way to load the data'. Your goal is to create a Snowpark DataFrame from this list of tuples, ensuring the date column is correctly interpreted as a Snowflake Date type. Which of the following approaches would be the most efficient and correct, minimizing data conversion overhead and maximizing Snowpark's capabilities?
Answer: E
Explanation:
Option C is the most efficient and correct way. Correctness : Option C explicitly defines the schema, including the 'DateType' for the transaction date. This ensures that Snowflake correctly interprets the date column without requiring any further casting or conversion. Avoids unnecessary string conversion. Efficiency : By defining the schema upfront, you avoid schema inference during dataframe creation, which can be costly for large datasets. This also avoids the cost of explicit casting after dataframe creation (as in Option A). Maximizing Snowpark Capabilities : Directly using Snowpark API to declare data types takes full advantage of Snowpark capabilities. Option A relies on implicit schema inference, which is not optimal in scenarios with specific data type requirements, and it requires an additional step which can be costly for large data. Option B introduces a dependency on Pandas and involves converting the data to a Pandas DataFrame, then to a Snowpark DataFrame, which creates unnecessary overhead and is not the most efficient approach. Option D, although correct, requires you to create a list of dictionaries, which adds an unneeded step in between and may not be optimized. Option E relies on implicit casting; However, this can lead to failure if date format is wrong.
NEW QUESTION # 89
You have a Snowflake stage containing image files. You need to write a Snowpark Python application that extracts metadata (e.g., image resolution, format) from these images and stores the metadata in a Snowflake table. You want to leverage a Python library, such as Pillow (PIL), for image processing. Which of the following steps are necessary to correctly and efficiently implement this?
Answer: B
Explanation:
Option B is the MOST correct. Using a Conda environment specification file ('environment.yml') and 'session.add_packages' is the recommended way to manage dependencies in Snowpark. It ensures that the correct version of Pillow is available and simplifies the deployment process. Option A is an older method and may not be as reliable. Option C involves UDFs which, while valid, can be less efficient than using native Snowpark functionalities directly. Option D is incorrect, Snowflake doesn't have built-in image processing functions. Option E again defeats the purpose of server-side processing.
NEW QUESTION # 90
You have configured your Snowpark application to use a '.env' file for storing connection parameters. The ' .env' file contains the following: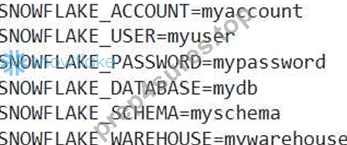
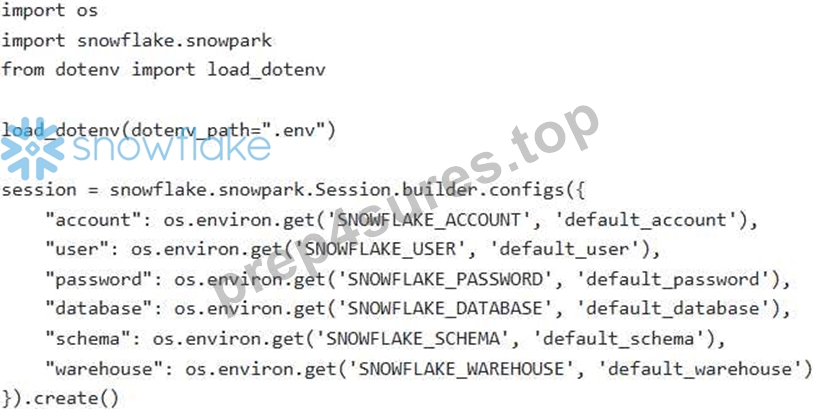
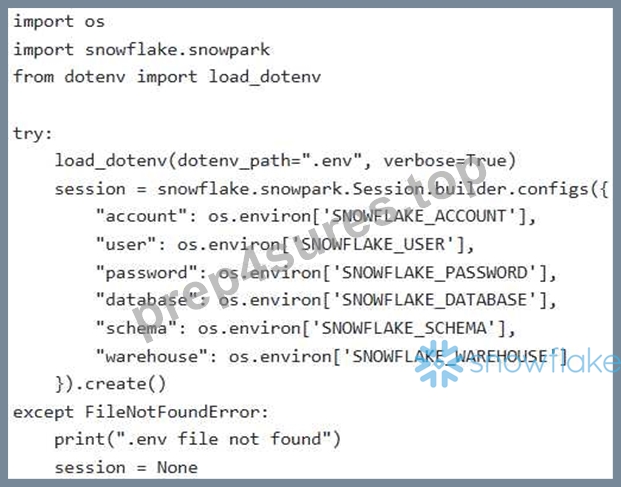
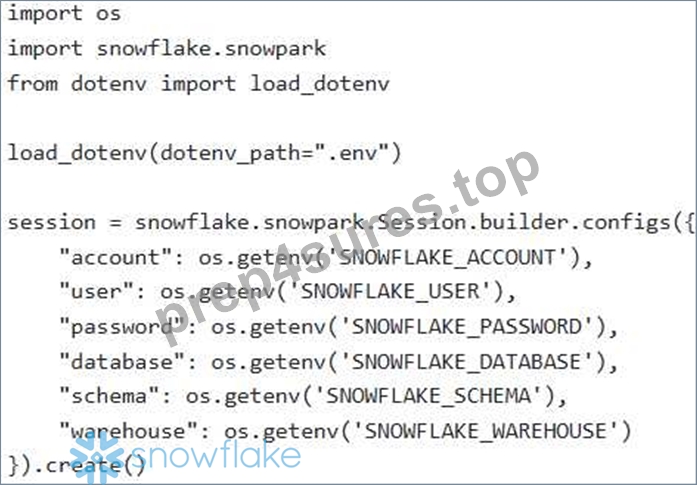
Which of the following code snippets demonstrates the most secure and recommended method for creating a Snowpark session using these environment variables and also ensuring the file exists?
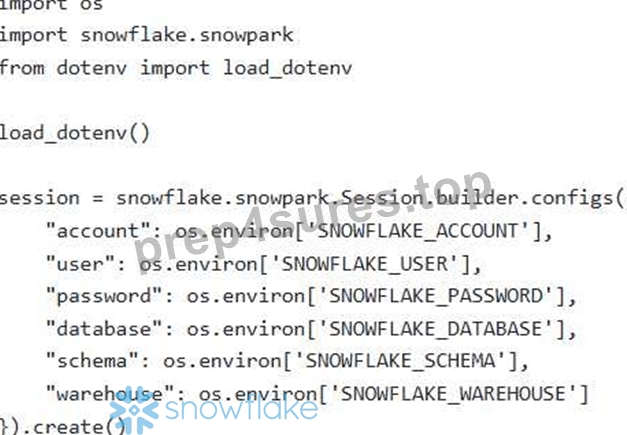
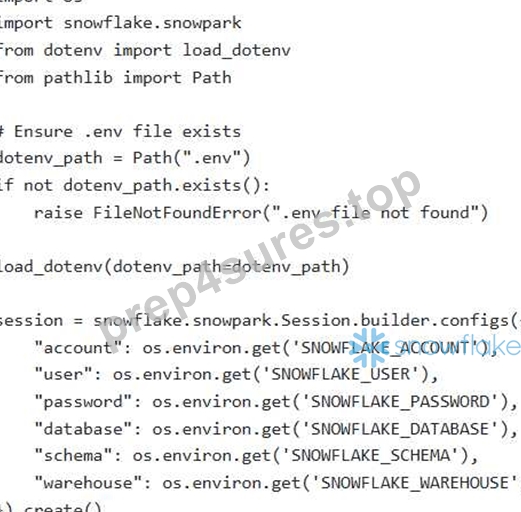
Answer: B
Explanation:
Option D is the most robust because it explicitly checks for the existence of the .env' file using 'pathlib' before attempting to load it, raising a FileNotFoundError' if it's missing, AND it utilizes 'os.environ.get()' which is safer than directly accessing 'os.environ[]" because it returns if the environment variable doesn't exist, preventing 'KeyError' exceptions, although in this case the .env' file not being present is detected. Options A, B, C and E don't proactively check for file existence prior to opening, and could thus potentially fail or crash the Snowpark session, or could inadvertently utilize invalid default values, which could lead to unexpected or incorrect behavior. Providing default values (Option E) might mask configuration errors.
NEW QUESTION # 91
You are tasked with optimizing a Snowpark application that processes sensor data'. The data includes timestamp, sensor ID, and sensor reading. Your initial implementation uses a regular Python UDF to calculate the moving average for each sensor. However, the processing time is significantly slow due to the large volume of data'. Which of the following strategies would be MOST effective in improving the performance of this calculation using vectorization?
Answer: E
Explanation:
Converting the Python UDF to a vectorized UDF allows it to process data in batches (as Pandas Series), which significantly reduces the overhead of transferring data between Snowflake and the UDE While increasing warehouse size (C) can provide some performance gain, vectorization (B) directly addresses the inefficiency of processing individual rows. Using built-in aggregation (D) is also a good option if feasible, but if a custom moving average calculation is required, vectorized UDF is the best fit. SQL UDFs aren't always faster and don't inherently vectorize. Java UDFs may provide some improvement but are more complex to implement than vectorized Python UDFs.
NEW QUESTION # 92
......
There is no doubt that the SPS-C01 certification in a popular exam in the industry. And, SPS-C01 is one of the most demanded certifications by the Cisco. We at Prep4sures, provide the money back guarantee on our SPS-C01 practice exam questions and training material. Our SPS-C01 certified professional team continuously works on updated exam content with Latest SPS-C01 Questions. If you want to clear the SPS-C01 exam in the best way, then you can utilize the best quality products and services provided by us. Our SPS-C01 PDF questions have all the updated question answers for SPS-C01 exams.
Practice SPS-C01 Test Online: https://www.prep4sures.top/SPS-C01-exam-dumps-torrent.html
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by Prep4sures: https://drive.google.com/open?id=1EFN0mLSDd2K7Q5bTbUh1eZbMrDxownRI