2026 Latest Prep4sures AI-300 PDF Dumps and AI-300 Exam Engine Free Share: https://drive.google.com/open?id=1jjH4ZTNz2aytO0EFIMVH6WZXhVzCWYXi
To get prepared for the Operationalizing Machine Learning and Generative AI Solutions (AI-300) certification exam, applicants face a lot of trouble if the study material is not updated. They are using outdated materials resulting in failure and loss of money and time. So to solve all these problems, Prep4sures offers actual AI-300 Questions to help candidates overcome all the obstacles and difficulties they face during AI-300 examination preparation.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement machine learning model lifecycle and operations | 25–30% | - Register, version, and package models
|
| Topic 2: Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
| Topic 3: Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
| Topic 4: Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Topic 5: Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
As you know, the low-quality latest AI-300 exam torrent may do harmful influence on you which may causes results past redemption. Whether you have experienced that problem or not was history by now. The exam will be vanquished smoothly this time by the help of valid latest AI-300 exam torrent. Written by meticulous and professional experts in this area, their quality has reached to the highest level compared with others’ similar AI-300 Test Prep and concord with the syllabus of the exam perfectly. Their questions points provide you with simulation environment to practice. In that case, when you sit in the real AI-300 exam room, you can deal with almost every question with ease.
NEW QUESTION # 37
Drag and Drop Question
An organization uses Microsoft Foundry to develop generative AI projects that access shared Azure resources such as storage accounts and vector databases.
The organization s security policy requires eliminating secret key-based authentication and enforcing least-privilege access.
You must configure identity and access so that:
Services authenticate without stored credentials.
Permissions are scoped appropriately across projects and shared resources.
You need to configure the appropriate identity or access mechanism for each requirement.
What should you configure in Microsoft Foundry to meet each requirement? To answer, move the appropriate configuration mechanisms to the correct requirements. You may use each configuration mechanism once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.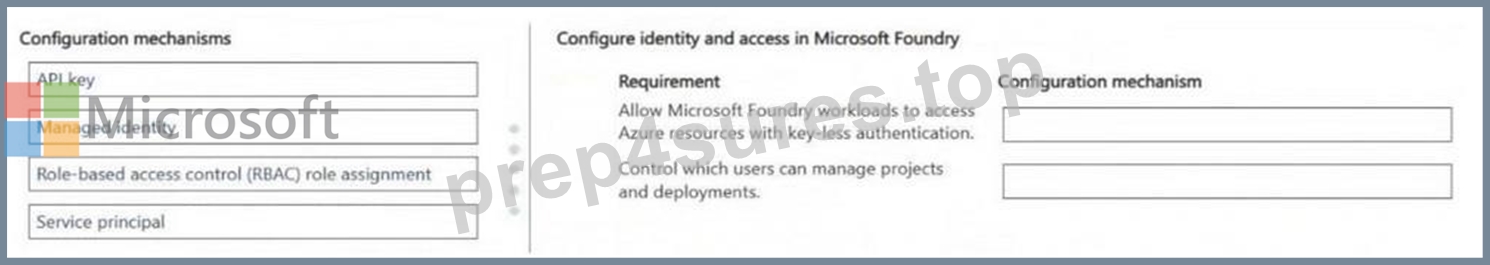
Answer:
Explanation: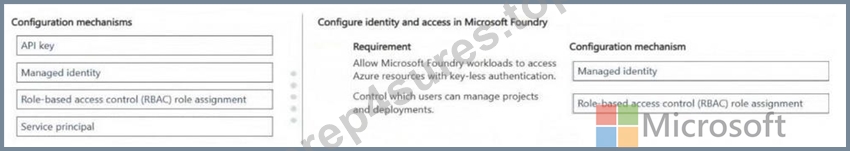
NEW QUESTION # 38
You create an Azure Machine Learning workspace named woricspace1. The workspace contains a Python SDK v2 notebook that uses MLflow to collect model training metrics and artifacts from your local computer.
You must reuse the notebook to run on Azure Machine Learning compute instance in workspace1.
You need to continue to log metrics and artifacts from your data science code.
What should you do?
Answer: A
NEW QUESTION # 39
Hotspot Question
You manage an Azure Machine Learning workspace. You create an experiment named experiment1 by using the Azure Machine Learning Python SDK v2 and MLflow.
You are reviewing the results of experiment1 by using the following code segment: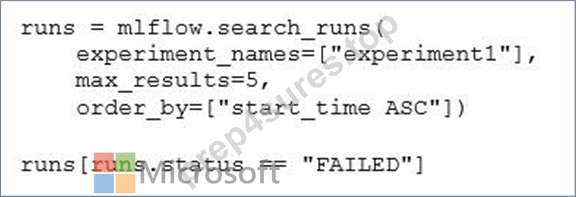
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: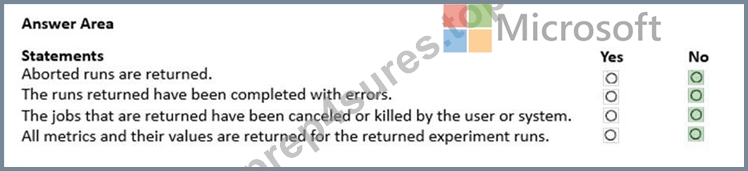
Explanation:
Box 1: No
Filter runs by status
You can also filter experiment by status. It becomes useful to find runs that are running, completed, canceled or failed.
Failed:The job/run has completed with errors.
KILLED: The job/run has been canceled or killed by the user/system.
The following example shows all the completed runs:
runs = mlflow.search_runs(experiment_ids=[ "1234-5678-90AB-CDEFG" ])
runs[runs.status == "FINISHED"]
Box 2: No
Ordering runs
By default, experiments are ordered descending by start_time, which is the time the experiment was queue in Azure Machine Learning.
However, here we have order_by=["start_time ASC"]. The five oldest experiments are returned.
Use the argument max_results from search_runs to limit the number of runs returned.
Box 3: No
Failed: The job/run has completed with errors.
KILLED: The job/run has been canceled or killed by the user/system.
Box 4: No
Getting metrics, parameters, artifacts and models
The method search_runs returns a Pandas Dataframe containing a limited amount of information by default. You can get Python objects if needed, which may be useful to get details about them.
Use the output_format parameter to control how output is returned:
runs = mlflow.search_runs(
experiment_ids=[ "1234-5678-90AB-CDEFG" ],
filter_string="params.num_boost_round='100'",
output_format="list",
)
Details can then be accessed from the info member. The following sample shows how to get the run_id:
last_run = runs[-1]
print("Last run ID:", last_run.info.run_id)
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-track-experiments-mlflow
NEW QUESTION # 40
Drag and Drop Question
A team deploys a classification model to production and monitors performance and data changes.
The team wants to ensure that significant drops in prediction accuracy automatically trigger the following:
- Stakeholders must be notified of the drops.
- Retraining must be initiated when thresholds are exceeded
You need to configure monitoring to meet the requirements.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.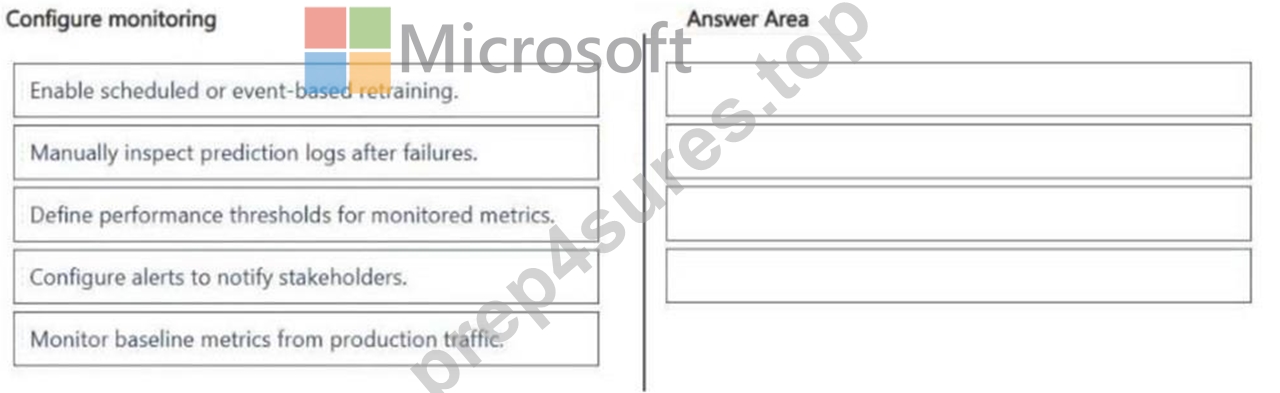
Answer:
Explanation: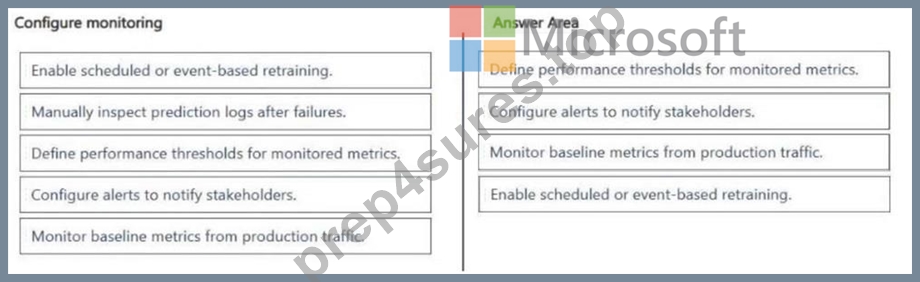
NEW QUESTION # 41
When comparing prompt variants, the team plans to assess whether the generated responses are grammatically correct.
You need to evaluate the quality of the language from the generated responses.
Which evaluator should you use?
Answer: D
Explanation:
In Microsoft Foundry ' s built-in evaluation framework, each evaluator measures a specific dimension of language quality. Fluency evaluates the grammatical correctness, sentence structure, and overall linguistic smoothness of generated text. A high fluency score means the response reads naturally, with proper grammar, punctuation, and sentence construction - regardless of factual accuracy or relevance to the topic. Coherence (option A) measures whether ideas flow logically from one sentence to the next - it is about logical structure, not grammar. Textual Similarity (option B) measures how closely the generated text matches a reference text using metrics like ROUGE or BLEU - it is a comparison metric, not a standalone quality dimension. Groundedness (option C) measures whether claims are supported by the provided context - it is a factual fidelity metric. For grammatical correctness specifically, Fluency is the correct evaluator.
Microsoft Learn Reference Topic: Built-in AI evaluators in Microsoft Foundry - Fluency, Coherence, Groundedness, and Similarity
NEW QUESTION # 42
......
Our experts have great familiarity with AI-300 real exam in this area. With passing rate up to 98 to 100 percent, we promise the profession of them and infallibility of our AI-300 practice materials. So you won’t be pestered with the difficulties of the exam any more. What is more, our AI-300 Exam Dumps can realize your potentiality greatly. Unlike some irresponsible companies who churn out some AI-300 study guide, we are looking forward to cooperate fervently.
AI-300 Reliable Test Book: https://www.prep4sures.top/AI-300-exam-dumps-torrent.html
BTW, DOWNLOAD part of Prep4sures AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1jjH4ZTNz2aytO0EFIMVH6WZXhVzCWYXi